How Do AI Agents Waste Your Money? The Systemic Structure of Token Waste
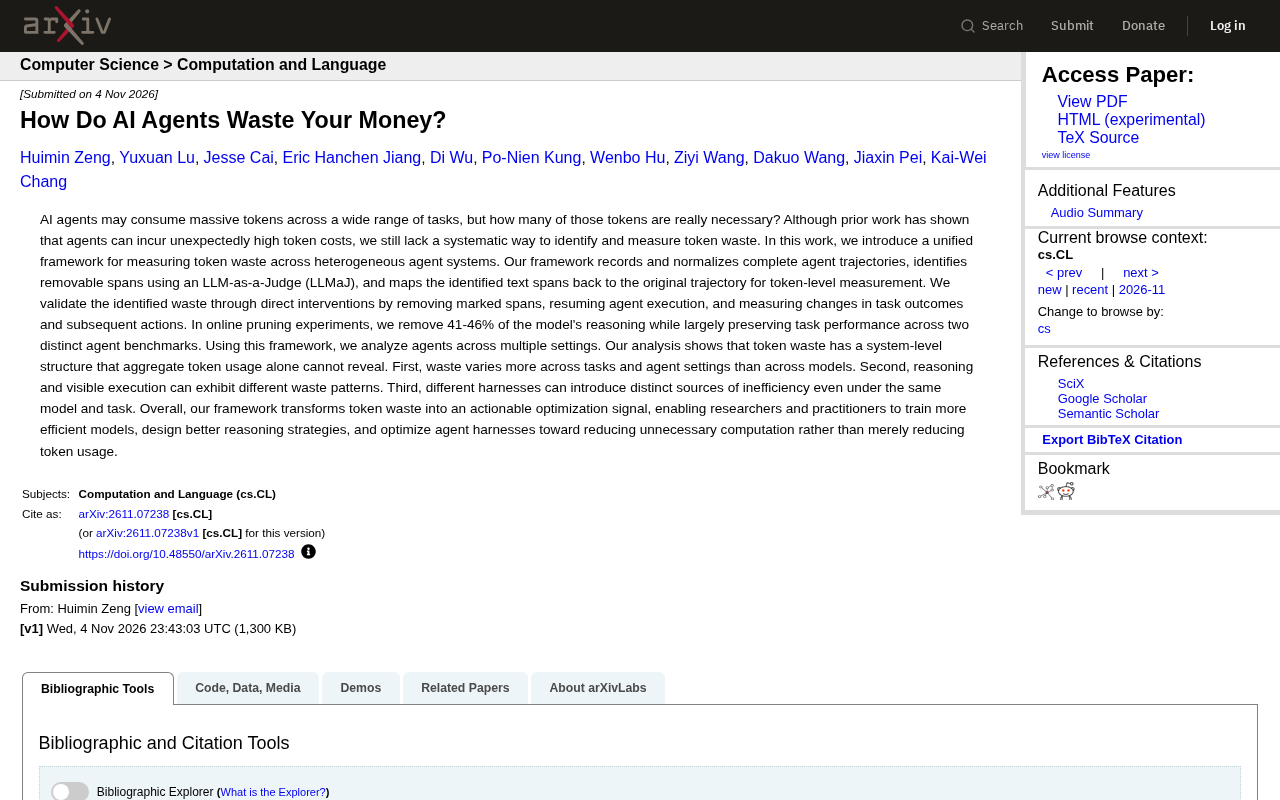
A unified framework measures AI agent token waste, revealing system-level structure and validating that online pruning removes nearly half of reasoning without hurting performance.
This study proposes a unified framework for measuring token waste in AI agents. It records and normalizes complete trajectories, uses LLM-as-a-Judge to identify removable segments, maps them back for token-level measurement, and validates via intervention. Online pruning removed 41–46% of reasoning content while preserving performance on two benchmarks. The researchers found waste has a system-level structure: task and setting differences exceed model differences; reasoning and execution waste patterns differ; and different Harnesses introduce unique inefficiencies. The framework turns token waste into an actionable optimization signal across task design, reasoning strategy, and Harness layers.
AI agents can consume massive amounts of tokens across various tasks, but how much of it is truly necessary? Although prior research has shown that agents can incur unexpectedly high token costs, we still lack a systematic way to identify and measure token waste. Recently, a study proposed a unified framework for measuring token waste across heterogeneous agent systems, revealing that waste is not randomly scattered but has a system-level structure.
Why We Need a Dedicated Framework for Measuring Token Waste
High token consumption does not equal waste. Some tokens are spent on necessary reasoning and execution, while others are purely redundant. The problem is that aggregate token usage alone cannot distinguish between the two. The study points out that we need a method capable of recording complete agent trajectories, identifying removable segments, and quantifying waste at the token level.
To this end, the researchers built a unified framework: it records and normalizes complete agent trajectories, uses LLM-as-a-Judge (LLMaJ) to identify removable text segments, and then maps the identified segments back to the original trajectories for token-level measurement. This "identify–map–measure" pipeline turns token waste from a vague impression into a quantifiable metric.
How the Framework Works: From Trajectory Recording to Intervention Validation
The core of the framework lies in two steps: first, LLMaJ judges which segments can be safely removed without affecting task completion; then, direct intervention validates whether the waste is real. The researchers remove the flagged segments, resume agent execution, and measure changes in task outcomes and subsequent actions. This interventional validation avoids the discrepancy between "the model thinks it can be removed" and "it actually can be removed."
In online pruning experiments, the researchers removed 41–46% of the model's reasoning content while essentially preserving task performance on two different agent benchmarks. This result shows that a substantial portion of reasoning tokens contributes nothing substantive to the final outcome, and removing them does not significantly harm agent performance.
LLM-as-a-Judge (LLMaJ) is a technical paradigm that uses large language models as evaluators. In this framework, LLMaJ does not directly judge task completion quality; instead, it is tasked with identifying "segments that can be safely removed": given a complete agent trajectory, the model must determine which text segments (such as redundant reasoning, repeated descriptions, or invalid attempts) can be deleted without affecting subsequent decisions and the final task outcome. The advantage of this approach is that LLMaJ can understand the semantics of natural-language trajectories, making it more flexible than rule-based or statistical heuristics; the risk, however, is that the model's judgment may diverge from actual removability, so the framework must introduce interventional validation—actually removing segments and re-executing the agent to calibrate LLMaJ's labels against real task outcomes. This "identify–intervene" loop is the key design that ensures the credibility of waste measurement.
The System-Level Structure of Token Waste: Three Key Findings
Using this framework, the researchers analyzed agents under various settings and found that token waste has a system-level structure that aggregate usage cannot reveal.
Waste Depends More on Tasks and Agent Settings Than on the Model Itself
The first finding: differences in waste across tasks and agent settings are larger than differences across models. This means the same model can exhibit vastly different waste levels under different tasks or configurations, and switching models may not solve the waste problem. Optimization efforts should focus on task design and agent configuration.
Reasoning and Visible Execution Exhibit Different Waste Patterns
The second finding: the reasoning process and the visible execution process may exhibit different waste patterns. Redundancy in reasoning and redundancy in execution cannot be lumped together; they need to be measured and optimized separately. This suggests that pruning strategies targeting reasoning may not apply to execution, and vice versa.
Reasoning tokens and visible execution tokens belong to different layers of an agent trajectory. Reasoning tokens refer to text produced by the model's internal chain-of-thought or implicit reasoning steps, usually not directly presented to the user but occupying a large share of the context; visible execution tokens include tool-call parameters, environment-interaction instructions, final replies, and other outputs that actually act on the external world. The two have different waste mechanisms: reasoning redundancy often manifests as repeated self-confirmation, circular argumentation, or re-derivation of already-settled conclusions; execution redundancy mostly manifests as invalid tool calls, parameter trial-and-error, or repeated queries. Because they occupy different positions and functions in the trajectory, pruning strategies must be designed separately—for reasoning, one can try compressing the chain of thought; for execution, one needs to optimize tool-call logic and caching mechanisms. The same set of rules cannot simply be applied to both.
Under the Same Model and Task, Different Harnesses Introduce Different Sources of Inefficiency
The third finding: even with the same model and task, different Harnesses (agent runtime frameworks) introduce different sources of inefficiency. Harness design choices—how prompts are organized, how context is managed, how tools are invoked—directly affect the degree and form of token waste. This provides clear optimization levers for engineering practice.
Harness (agent runtime framework) refers to the entire software scaffolding wrapped around the base model that drives agent behavior, typically including prompt template organization, context window management, tool-call interfaces, multi-turn dialogue state maintenance, output parsing, and retry logic. The same model performs significantly differently under different Harnesses, because the Harness determines "what the model sees" and "how it acts" each time it is invoked. For example, a Harness that concatenates the full history every turn introduces a large amount of repeated context tokens; a Harness lacking tool-call result caching may cause the model to repeatedly execute the same query. Therefore, Harness design choices are themselves one of the structural sources of token waste, and optimizing the Harness is often more direct than switching models in reducing ineffective consumption.
From Measurement to Action: Token Waste as an Optimization Signal
The value of this framework lies in turning token waste into an actionable optimization signal. The researchers point out that this can help researchers and practitioners train more efficient models, design better reasoning strategies, and optimize agent Harnesses to reduce unnecessary computation—not merely to reduce token usage.
Reducing token usage and reducing waste are two different goals. The former may come at the cost of task performance, while the latter seeks to eliminate redundancy while maintaining performance. Through interventional validation, the framework ensures that removed segments truly do not affect task outcomes, making optimization targeted.
Practical Implications: How to Reduce Token Waste in Agents
Based on these findings, practitioners can start from three levels. At the task level, identify high-waste task types and adjust task design; at the reasoning-strategy level, develop pruning or compression strategies separately for reasoning and execution; at the Harness level, examine sources of inefficiency in framework design, such as redundant context concatenation or unnecessary tool calls.
The study also reminds us that aggregate token usage is an overly coarse metric. To truly understand cost, one needs to go down to the trajectory level and identify which segments are removable and which are not. As agents take on increasingly complex tasks, this fine-grained waste measurement will become increasingly important.
Conclusion
Token waste in AI agents is not a random phenomenon but a system-level structure shaped jointly by tasks, settings, reasoning patterns, and Harnesses. The emergence of a unified measurement framework turns waste from a hidden cost into an optimizable target. For teams building agent applications, focusing on the structural sources of token waste may be more effective at controlling costs than simply pursuing cheaper models.
One-line Summary
A study proposes a unified framework for measuring token waste in AI agents, revealing its system-level structure and demonstrating that online pruning can remove nearly half of reasoning content without harming performance.
Paragraph Summary
Targeting the hard-to-distinguish necessary versus redundant portions of AI agent token consumption, this study proposes a unified measurement framework. The framework records and normalizes complete trajectories, uses LLM-as-a-Judge to identify removable segments, maps them back to trajectories for token-level measurement, and ensures accuracy through interventional validation. In online pruning experiments, removing 41–46% of reasoning content essentially preserved task performance on two benchmarks. Based on this framework, the researchers found that token waste has a system-level structure: differences across tasks and agent settings exceed differences across models; reasoning and visible execution exhibit different waste patterns; and different Harnesses introduce unique sources of inefficiency. The framework turns token waste into an actionable optimization signal, supporting waste reduction at the task-design, reasoning-strategy, and Harness levels rather than merely compressing token usage.
Related articles
Hermes Agent in Depth: From Deployment to Skills, MCP, and Hooks
A complete walkthrough of Hermes Agent based on a YouTube deep-dive: VPS deployment, soul.md and user.md memory layering, auto-generated skills, MCP and connectors for Notion, multiple profiles and sub-agent delegation, gateway and shell hooks, and voice call configuration essentials.
Codependency in Addiction: Let Go of the Rope So the Other Person Can Move Toward Recovery
Stanford addiction expert Dr. Anna Lembke explains how codependency sustains addiction: when families stop over-intervening, attend Al-Anon, and let go, addicted individuals are more likely to recover.
Where Does Autonomous Driving Training Data Come From? Cosmo 3 Uses Scene Graphs to Generate Multi-Sensor Data
Cosmo 3 offers a generative solution for autonomous driving training data: controlled generation via world scene graphs, synchronized RGB and LiDAR output, and continuous generation for closed-loop simulation, now open for developer trials.