Hugging Face Inference Routing Fully Moves to OpenRouter
Hugging Face moves inference routing to OpenRouter, with open-weight models at 81% of calls.
Hugging Face this week announced a partnership with OpenRouter, replacing its in-house inference router so requests are automatically routed to the best available provider. OpenRouter data shows open-weight models now handle 81% of requests, versus 78% for closed models a year ago. The onboarding follows existing Hub interactions: chat on the model page, view real-time metrics, grab Python/JS examples, and connect coding agents. Pro accounts get $2/month covering roughly 150M DeepSeek 4.1 Flash tokens (with caching), with no markup. Users can filter providers and set spending limits, though the integration creates new dependency on OpenRouter's routing policies.
Hugging Face announced this week a partnership with OpenRouter, migrating its in-house inference routing system to OpenRouter. This means that when users call models through Hugging Face, requests will be automatically routed by OpenRouter to the best available inference provider at any given moment. The change not only simplifies the underlying architecture but also reflects that open-source models have come to dominate real-world call volume. As someone who has long tracked AI infrastructure, I think this integration is worth breaking down across three dimensions: technology, ecosystem, and user experience.
Open-weight model calls overtake closed models as the ecosystem shifts
According to an official Hugging Face video, the model call mix on the OpenRouter platform has fundamentally flipped over the past year. This time last year, closed-weight models accounted for 78% of all requests; today, open-weight models handle 81% of requests. Eight of the ten most popular models on OpenRouter are open-weight models. This data aligns with the surge in open-source model popularity that Hugging Face has observed itself.
This shift is no accident. Open-source models are rapidly closing the performance gap with the closed-source frontier, while inference costs keep falling, making developers and enterprises more inclined to move workloads onto models they can control themselves. OpenRouter, as an aggregation and routing layer, happens to provide a unified interface and price-comparison capability for that migration.
Open-weight model refers to models whose parameter weights can be publicly downloaded and used, such as the Llama, Qwen, and DeepSeekAd series. Unlike fully closed models (e.g., GPT-4, Claude), open-weight models allow developers to deploy locally, fine-tune, or call them through third-party inference providers. The "share of requests for open-weight models" that OpenRouter tracks is based on API call volume for these models, not download counts. This metric more directly reflects actual usage preferences in production environments, because API calls usually correspond to real business workloads.
Calling OpenRouter directly on Hugging Face: get started in three steps
The entire onboarding flow follows the existing interaction patterns of the Hugging Face Hub, so there is virtually no new learning curve.
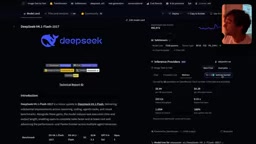
Step one: chat directly on the model page. Logged-in users can open any model page that supports inference (for example, the latest DeepSeek 4.1 Flash checkpoint demonstrated in the video) and see an embedded chat window. After entering a prompt, the request is routed directly through OpenRouter to an available inference provider. Click the provider list to see which backend the current request was dispatched to.
Step two: view real-time inference metrics. Click the metrics entry to see the price per million input/output tokens, tokens generated per second, time to first token, context window size, and the model's uptime on OpenRouter. These data points are critical for model selection and cost estimation.
Step three: integrate into your app or coding assistant. In the "Getting Started" section, users can directly grab Python or JavaScript call examples. At the same time, a Hugging Face account can be connected to coding agents such as Pi, OpenCode, Claude Code, and Codex, letting these tools call the model pool behind OpenRouter using Hugging Face credits.
Inference routing is a technique in which an aggregation layer dynamically distributes user requests to different inference backends based on current latency, price, availability, and other metrics. OpenRouter maintains real-time status for dozens of inference providers (such as Together, Fireworks, and DeepInfra), and when a provider fails or degrades in performance, the routing system automatically shifts traffic to backup nodes. This mechanism avoids single points of failure and spares users from manually comparing prices and switching API endpoints—essentially a load-balancing and failover solution for LLM inference.
Pro account: $2 per month in credits—how many tokens will that buy?
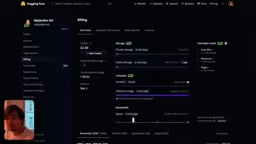
A Hugging Face Pro account comes with $2 in credits each month, usable across many services on the Hub, including private storage, public storage, ZeroGPU, and inference calls. The official video gives a reference point: that $2 is roughly enough to cover 150 million DeepSeek 4.1 Flash tokens, assuming typical conversation with prompt caching enabled—OpenRouter handles caching automatically.
More importantly, Hugging Face explicitly states that it does not mark up the displayed prices. The prices shown on the page are exactly the same as those published by OpenRouter, so users don't need to worry about a platform cut. For cost-sensitive teams, this transparent pricing reduces the complexity of cross-platform price comparison.
Provider filtering and spending controls
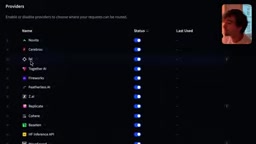
In the "Inference Providers" section of the settings page, users can view model usage analytics and manually turn off providers they don't want requests routed to. For example, the video demo mentions providers such as Novita, Cerebras, and FOUL; users can turn off Novita with one click, after which all requests will no longer go through that backend. This feature is especially important for teams with strict compliance requirements or preferences for specific providers.
At the same time, users can set spending limits on their accounts. Enterprise account administrators can manage this limit centrally for all members of the organization. This means teams can enjoy the convenience of OpenRouter routing while retaining budget control.
Prompt caching is a technique for optimizing inference costs: when multiple requests share the same prefix (such as a system prompt or a long document context), the inference provider can cache that portion of the computation and reuse it for subsequent requests, reducing redundant work. OpenRouter handles cache hits automatically, with no code changes required from users. For long-context conversations or agent workflows with fixed instructions, caching can significantly reduce token consumption—and this is an important premise behind the official estimate that "$2 covers 150 million tokens."
What this partnership means
From an architectural standpoint, replacing its in-house router with OpenRouter amounts to Hugging Face outsourcing the complex decision of "which inference backend to choose" to a specialized aggregation layer. OpenRouter already connects to a large number of inference providers and offers dynamic price comparison and failover. Hugging Face, meanwhile, focuses on model hosting, community, and accounts—the two parties complement each other.
For developers, the most direct change is a unified call path: whether through the Hugging Face website, the API, or coding agents, everything runs on the same OpenRouter routing underneath. Transparent pricing, filterable providers, and manageable credits—together these three capabilities reduce the operational burden of multi-model workflows.
It's worth noting that this aggregation model also introduces new dependencies. If OpenRouter's routing policies or available providers change, Hugging Face users will feel it directly. The provider filtering and spending limits offered officially are effective mitigations, but enterprises with strict SLA requirements still need to evaluate multi-provider redundancy strategies.
Overall, this partnership is a sign that the open-source model ecosystem is maturing: after the explosion in the number of models, integration and standardization at the call layer are becoming the focus of the next phase of competition.
Related articles
Hark Pro Hands-On Test: Three Tasks, Zero Input — Can AI Really Take Over Everyday Chores?
A YouTube creator tests Hark Pro on three everyday tasks: clearing an inbox with a billing sheet, a full DoorDash order, and a self-built dashboard. No keyboard, three wins — we analyze this operational AI's capabilities and concerns.
The Katseye Dilemma: How Long Can the Idol Industry's High-Speed Engine Keep Running?
Using Katseye's recent team struggles and One Direction members' reflections on grueling tour and promo schedules, this analysis examines the idol industry's structural 'tour—album—promo' cycle and what operational changes a group needs to turn things around.

Claude Code v2.1.329 Update Explained: Trust Dialog and Code Mode Enhancements
Claude Code v2.1.329 update analysis: new hook trust dialog and MCP server error prompts, Code Mode fixes memory leaks and tool call boundaries, /tasks consolidates session task view, and fixes multi-session login and file reading issues.