Identifying Characters from 'Time Difference 5 Hours 3' Posters: A Fun Observation Experiment
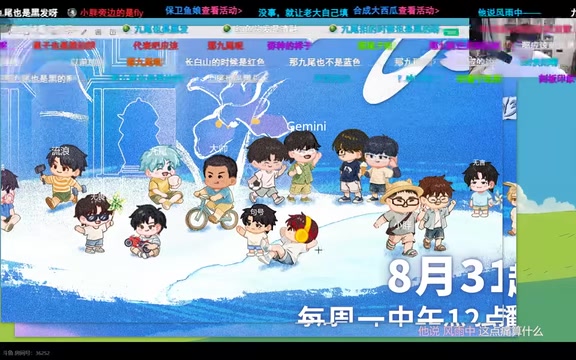
A viral poster-recognition fail reveals how humans identify characters when art styles flatten individual features.
Using a viral clip of a content creator struggling to identify characters — including himself — from Time Difference 5 Hours 3 promotional posters, this article explores how humans tackle high-similarity image recognition. When a unified art style compresses facial differences, people shift to props, hair color, and cross-image consistency as anchors, while using group-association memory and elimination to narrow candidates. The premiere is set for August 31st, Changbai Mountain arc first.
The upcoming premiere of Time Difference 5 Hours 3 has sparked an unexpected viral moment: a clip of a content creator trying to identify characters from the show's promotional posters — and failing to recognize even themselves. What looks like lighthearted entertainment is actually a revealing window into how humans struggle with high-similarity image recognition. When art styles are unified and individual features are flattened, even familiar faces become hard to place. This article uses that clip as a starting point to explore some observations about visual identification.
A Poster Recognition Game Where You Can't Even Spot Yourself
The scene is straightforward: a content creator goes through two sets of character posters, trying to match each illustrated figure to a real person. The funny part? He can't even identify himself — "I look like this, but if you weren't holding that baby bottle, I would have absolutely no idea that's me."
That throwaway complaint cuts right to the core of the problem. When a group of characters is rendered in a unified art style, individual facial differences get heavily compressed. People are forced to rely on external cues to tell figures apart: a baby bottle, distinct eyebrows, glasses, hair color, a wolf-tail hairstyle, Samoyed-like ears, a motorcycle prop, and so on. His repeated strategy of "start with the ones not wearing glasses" or "find the easy ones first" is essentially a search for the most discriminative feature markers.
This identification strategy mirrors the underlying logic of facial recognition systems — when core biometric features aren't distinctive enough, auxiliary attributes (accessories, posture, contextual associations) become the deciding factors.
Contextual Association: The "Connect the Dots" Approach to Recognition
One reasoning chain in the video is particularly worth examining. He notes: "In the previous image, Xiao Pang and Carter were together," and "Hua Hai was standing with me, Frei was with Ace, so the four of us should be in the same illustration."
Rather than relying purely on a single image's facial features, he draws on remembered spatial relationships to cross-reference identities. This is a textbook example of "contextual priors" in human cognition — using known groupings and positional patterns to infer unknowns. When he exclaims "See, I connected the dots!" he has just completed a logical loop built entirely from relational information.
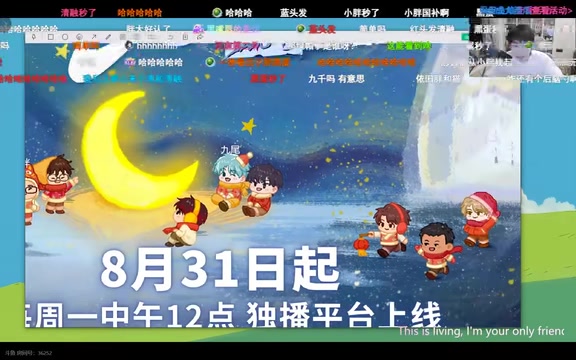
Process of elimination also appears constantly: "The top lane has Frei, Ace, Qingqing accounted for… so this spot must be Qingqing." When direct recognition fails, narrowing the candidate pool is a practical strategy for high-similarity identification tasks.
The "contextual prior" approach maps onto the Bayesian inference process of updating prior probabilities: the human brain doesn't process each image in isolation but continuously matches new perceptions against existing memory structures. When direct features fall short, spatial memory (who appears with whom), social relationships (a character's fixed partner), and even narrative logic (these two are always paired) all get recruited for identity judgment. This closely parallels the logic of Relation Networks or graph neural network node inference in computer vision — when a single node's attributes are ambiguous, neighboring node information can constrain it in reverse. Elimination corresponds to search-space pruning: with a finite candidate set, each confirmed identity removes one option, exponentially reducing the difficulty of resolving the remaining unknowns.
The Identification Challenge in Low-Distinctiveness Feature Spaces
Why are these posters so hard to read? He answers his own question: "Everyone has black eyes and black hair, then a few dots added — not completely the same, but just different enough to be confusing."
This perfectly describes a low-distinctiveness feature space. When all samples share a large number of identical attributes — the same art style, the same base hair color, similar face shapes — the information available for differentiation becomes sparse. In that context, even minor differences — a center part versus a side part, a green shirt, a single streak of unusual hair color — get amplified into critical discriminators.
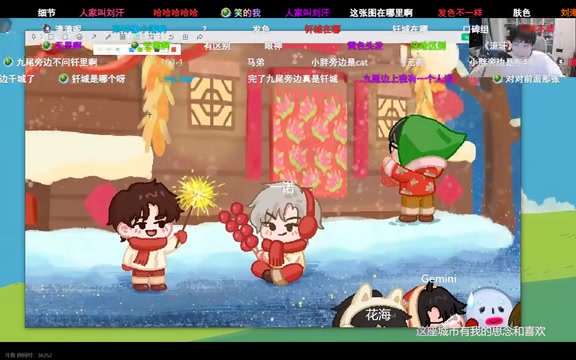
His reasoning about his own avatar near the end illustrates this clearly: "My hair isn't actually like that… but this one has green, and in the previous image I also had a green outfit, so I think I'm the one in the green outfit here." He abandons direct facial matching entirely and switches to "cross-image color consistency" — a sign that in weak-feature scenarios, people actively shift their identification strategy to a different dimension.
In facial recognition research, "low-distinctiveness feature spaces" correspond specifically to distributions with small intra-class variance and small inter-class variance. In plain terms: when all samples look similar to each other (small inter-class distance) and a single person's images are also highly consistent with one another (small intra-class distance), standard Euclidean or cosine similarity measures break down. This is precisely why the field has developed specialized loss function designs such as ArcFace and CosFace, whose core idea is to artificially increase inter-class angular margins while compressing intra-class distributions. The same-style illustration recognition problem is structurally identical: the artist's deliberate stylistic consistency artificially shrinks inter-class distance, rendering visual-distance-based recognition ineffective. Only by pivoting to semantic auxiliary attributes can discriminability be recovered.
The Observational Value Hidden in Entertainment Content
At its core, this is audience-engagement entertainment — the creator himself admitted "I literally can't keep it together" and "this illustration is too wild." But it inadvertently provides a vivid case study of human image-recognition behavior in action.
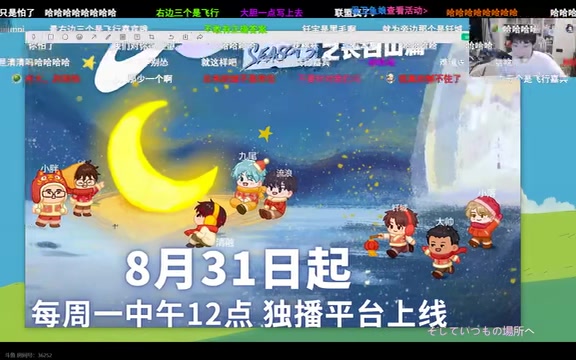
A few patterns worth noting:
- Prop dependency: A baby bottle, an ice cream cone, a motorcycle become more reliable recognition anchors than faces;
- Group association memory: Fixed character pairings are used to reverse-infer individual identities;
- Cross-image consistency reasoning: Costume and hair color from a previous version are used to inform judgment on a new one.
These strategies share structural similarities with feature engineering and contextual modeling in computer vision. That said, the source material is pure entertainment and involves no technical analysis — the observations above are purely an extended interpretive layer.
Premiere Information
According to the creator, Time Difference 5 Hours 3's Changbai Mountain arc will premiere on August 31st, with the Changbai Mountain episodes airing before the Paris arc. Due to platform rules, he cannot watch on the day of release and must wait 12 hours after the official upload before hosting a watch-along on Douyu — so he plans to post his reaction content every Tuesday evening. Viewers who can't wait are welcome to head to the official platform and watch ahead.
Overall, this is a relaxed, audience-oriented piece of content — more fun than informative, and a perfect warm-up for series fans ahead of the premiere.
Related articles
What Are APIs and API Keys? A 4-Minute Explainer Using DeepSeek's Docs
What are APIs and API Keys? Using DeepSeek's official docs and a live terminal demo, this guide explains the core concepts in 4 minutes with a simple door-and-key analogy.
AI Agent Beginner's Guide: How Agents Work, What They're Made Of, and Where They're Used
A beginner's guide to AI Agents: learn how agents differ from chatbots, the three core components (brain, memory, tools), and the three types of agents available today.
Beware of 'One-Click GPT-6 Deployment' Scams: Third-Party API Wrapper Traps Explained
Fact-checking viral 'free GPT-6 one-click deployment' tutorials: the GPT-6 X-TRAW model doesn't exist, and third-party token relays pose serious data and security risks.