Intelligence Should Be Measured by Cost: Unpacking OpenAI's New Model Evaluation Paradigm

Measuring AI intelligence as a function of cost is a more practical benchmark paradigm than raw scores alone.
This article explores an emerging approach to AI model evaluation: treating "intelligence" as a function of cost rather than a single benchmark score. Traditional evaluations ignore inference costs — a key factor in whether an application can scale. By presenting models on a Pareto frontier, developers can weigh performance against cost in one view, finding the optimal solution within their budget instead of blindly chasing leaderboard rankings. As leading vendors begin incorporating cost into official benchmarks, the industry is shifting from capability worship toward a rational focus on efficiency and real-world value.
A New Approach to Benchmarking: Balancing Performance and Cost
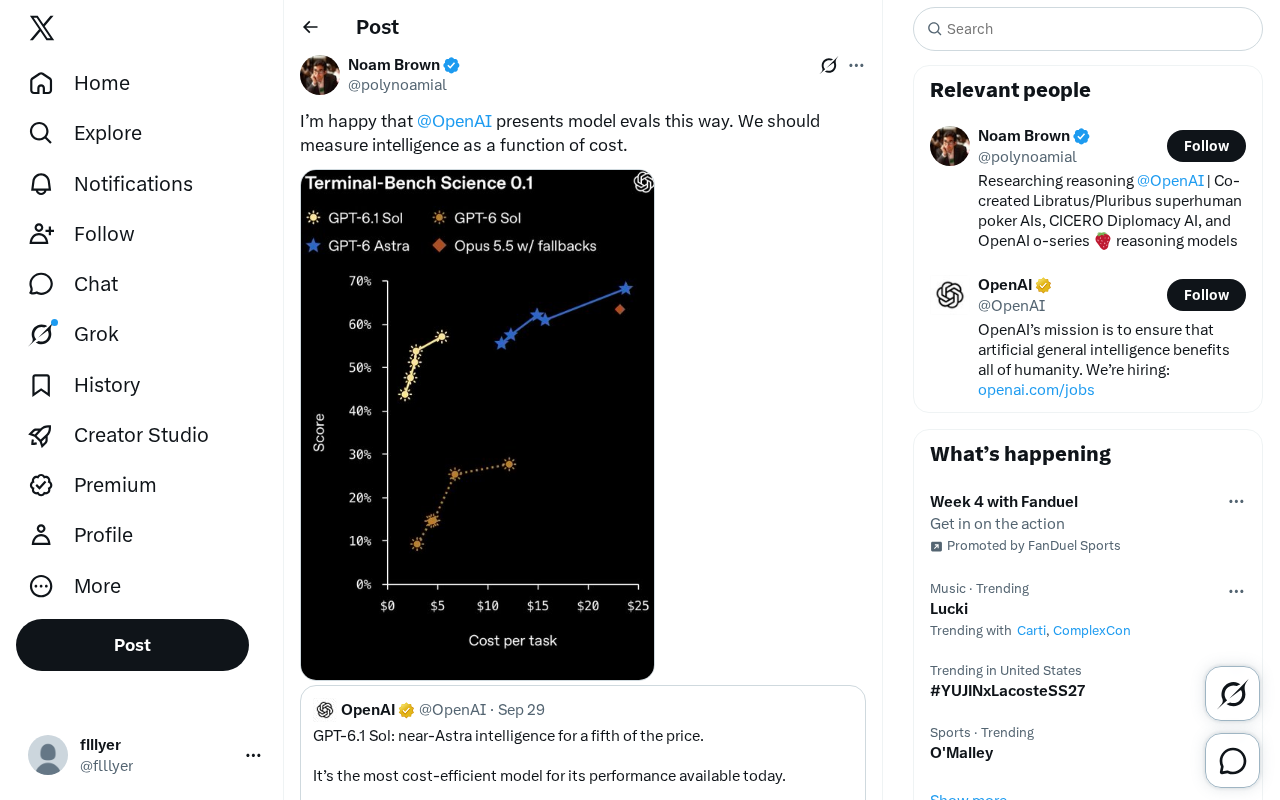
As competition in the AI model race intensifies, a perspective circulating in the tech community has sparked discussion: should we rethink how we measure a model's "intelligence"? One industry insider posted on Twitter that they'd love to see OpenAI present model benchmarks this way — specifically, to measure intelligence as a function of cost.
The idea sounds simple, but it touches on a dimension that has long been overlooked in large language model evaluation: chasing benchmark scores alone doesn't accurately reflect a model's real-world value.
Why Treat Intelligence as a Function of Cost
Traditional model evaluations tend to focus on a single capability metric — how high a model scores on a given benchmark, or how many questions it answers correctly. The problem with this approach is that it's completely divorced from the realities of deployment and usage. A model that performs brilliantly on tests but carries steep inference costs can have a radically different practical value than a slightly less capable model that costs far less — depending on the use case.
Expressing intelligence as a function of cost means presenting both "capability" and "price" on the same chart. Users can immediately see which model delivers the best intelligence for a given budget, or how much it costs to reach a certain capability threshold. This Pareto frontier-style presentation aligns far more closely with the real decision-making logic that engineers and enterprises use when selecting models.
What is the Pareto Frontier? The Pareto Frontier is a concept from multi-objective optimization. In a coordinate space defined by two competing metrics — such as performance and cost — the Pareto frontier represents the set of solutions where you cannot improve one metric without sacrificing the other. For model selection, a Pareto-optimal model means no other model achieves higher performance at the same cost, or lower cost at the same performance level. Models that fall outside the frontier have an obvious disadvantage: you can always find an alternative that is both cheaper and smarter. Visualizing model benchmarks as a Pareto curve immediately filters out options that are "expensive yet weak," letting developers focus their trade-offs among genuinely competitive candidates — rather than guessing whether a score difference on a one-dimensional leaderboard is worth the extra spend.
The Broader Industry Significance of This Paradigm Shift
As the number of available models explodes and pricing structures grow increasingly complex, "cost-effectiveness" is becoming an ever more critical factor in model selection. Inference cost directly determines whether an AI application can scale. For developers, knowing how "smart" a model is isn't enough — they also need to know how much each unit of intelligence costs.
When leading vendors begin incorporating cost dimensions into their official benchmarks, they are effectively nudging the entire industry toward more pragmatic evaluation standards. It encourages vendors to invest not only in raw capability, but also in efficiency and cost optimization — because the same level of intelligence only becomes truly competitive when it can be delivered at a lower price.
A note on inference costs: Inference costs are typically measured in dollars per million tokens, with separate pricing for input and output tokens. A token is the basic unit of text that large language models process — roughly four characters in English or one to two Chinese characters. A complex conversation or document-processing task can consume thousands or even tens of thousands of tokens. When an application scales to millions of calls per day, even a tiny per-call cost difference compounds into enormous bills. As a result, a model's "intelligence output per token" directly affects the commercial viability of an AI product. Techniques like Speculative Decoding and Mixture of Experts (MoE) architecture, which have emerged in recent years, represent exactly this kind of engineering effort — reducing inference costs without sacrificing capability. This is the technical backdrop against which cost has entered the official benchmarking conversation.
What This Means for Developers and Enterprise Users
For teams building AI products, this evaluation framework provides a far more actionable reference. In practice, rather than blindly chasing whichever model tops the leaderboard, teams should factor in their own call volumes, latency requirements, and budget constraints — then find the point on the performance-cost curve that best fits their needs.
High-performance models are well-suited for core tasks where quality demands are extremely high and call volume is modest. Cost-efficient models, on the other hand, are better for high-frequency, high-volume scenarios. Understanding the functional relationship between intelligence and cost helps teams make more rational technical decisions and avoid paying a premium for capabilities they'll never actually use.
Closing Thoughts
This brief community observation reflects a subtle but meaningful shift in AI benchmarking culture: a move away from pure capability worship, toward a rational focus on efficiency and practical value. When "intelligence" is measured on an axis of cost, the rules of the model race quietly change. For users, this is unquestionably a more accessible and more transparent direction.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.