Jev AI Implementation Guide: Guardrails First, Tool Selection Second
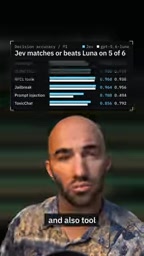
Jev AI can prioritize replacing guardrail components, while tool selection depends on whether generative text is required.
Based on an analysis video, the article discusses Jev AI's entry points in large model deployment. Guardrails and tool selection are the two major use cases, and these tasks mostly involve classification, judgment, routing, and matching—not necessarily requiring generative text—thus falling within Jev AI's strengths. The implementation order should be guardrails first, tool selection second: guardrail boundaries are clear with low validation costs, while tool selection is more complex, and any component requiring natural language output must still rely on large language models. The author emphasizes that strong performance is only a necessary condition for replacement, not a sufficient one—teams must first validate accuracy and stability on actual business data and adopt a progressive replacement strategy with large models as a fallback.
Why Start with Guardrails and Tool Selection for Jev AI
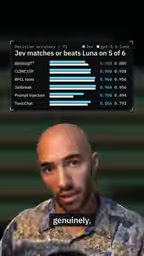
In the process of deploying large model applications, guardrails and tool selection are currently the two most central use cases. According to the perspective of a related analysis video on YouTube, Jev AI demonstrates strong performance in these two areas, and can therefore replace some of these components after testing and validation.
The key to this judgment is that not all tasks require generative text. Guardrail scenarios typically involve classification, judgment, and interception, while tool selection often involves routing and matching—these two types of tasks happen to fall within Jev AI's strengths.
Guardrails in the context of large model applications refer to rule constraint layers set on both the input and output sides of the model, used to intercept jailbreak prompts, harmful content, sensitive information leakage, or requests that deviate from business scope. They are typically implemented with classifiers, rule engines, or lightweight discriminative models, making rapid judgments on each interaction rather than generating complete responses.
Tool Selection is the routing component in Agent architectures: given user intent, select the most appropriate one or several from the available tool/API set. Its implementation falls into two categories—relying on large models for semantic reasoning and generative judgment, or relying on embeddings, keywords, and classification models for matching and routing. What the article repeatedly distinguishes is precisely the difference between these two implementation paths.
Guardrails: The Clearest Starting Point
The video author explicitly states that the clearest entry point is guardrails. The reason is not hard to understand: the core responsibility of guardrails is to judge whether input or output touches rule boundaries. Such tasks have low requirements for generation capability but high requirements for judgment stability and response speed. Jev AI's strong performance in this scenario means that teams can use it to take on some guardrail responsibilities, provided they conduct proper testing and validation.
It is important to note that replacement does not mean full takeover. The video emphasizes "replacing some components," which suggests that teams should retain the original large model as a fallback capability and use Jev AI for high-frequency, clearly-defined judgment paths, thereby gaining benefits in cost and latency.
Tool Selection: A More Nuanced Boundary
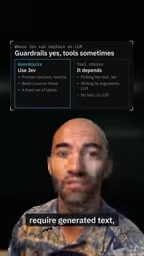
The situation with tool selection is more complex than guardrails. The video author points out that when tool selection requires reliance on generative text, Jev AI cannot handle it, and teams still need to use large language models.
But not all tool selection requires text generation. For routing and matching tasks that do not depend on generation capability, Jev AI can truly be put to use. The criterion here is practical: first check whether the component must produce natural language content. If not, there is room for replacement with Jev AI.
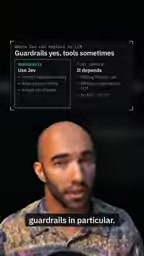
Whether a task "depends on generative text" can be inferred from the output format: if the final product of the component is a piece of natural language (such as explanations, rewrites, or multi-turn follow-ups), it must rely on large models; if the product is merely a label, score, ID, or boolean judgment, then discriminative or lightweight models can handle it. Many subtasks in tool selection fall into the latter category, such as intent classification, tool name matching, and parameter slot validation. Additionally, the trade-off between latency and cost should be considered—the routing component sits early in the request chain, and its response speed directly amplifies to the overall experience, which is precisely where the value of lightweight solutions lies.
Implementation Order and Validation Prerequisites
The path given in the video is clear: guardrails first, tool selection second. This order follows the logic of risk control—guardrail boundaries are relatively clear with lower validation costs; tool selection involves integration with downstream systems and requires more careful testing.
The author repeatedly emphasizes the prerequisite of "testing and validation." In other words, Jev AI's strong performance is a necessary condition for replacement, not a sufficient one. Teams need to validate its judgment accuracy and stability on actual business data before determining the scope of replacement.
Progressive replacement in engineering typically starts with shadow mode: the new model runs in parallel with the original pipeline, only recording its judgment results without affecting live traffic, then comparing accuracy and consistency rates between the two using offline labeling or manual sampling. Once the consistency rate reaches a threshold, a small proportion of low-risk traffic can be gradually rolled out, observing metrics before scaling up. In evaluation, beyond accuracy, attention should also be paid to the imbalanced costs of false interception versus missed interception—in guardrail scenarios, false interception directly harms user experience, and this type of error often needs to be controlled with higher priority than missed interception.
Implications for Teams
The value of this analysis lies in providing a pragmatic implementation roadmap rather than generic capability promotion. For teams currently evaluating Jev AI, they can proceed as follows: first review existing guardrail and tool selection components, identify subtasks that do not require generative text; then conduct small-scale testing on these tasks; after validation passes, gradually replace while retaining large models as a fallback.
This progressive replacement strategy both controls risk and allows teams to build understanding of Jev AI's boundaries in real scenarios. Guardrails first, tool selection following—this is a starting point worth considering.
One-line Summary
Jev AI can prioritize replacing guardrail components; tool selection depends on whether generative text is required.
Paragraph Summary
Based on the perspective of an analysis video, the article discusses Jev AI's entry points in large model application deployment. The core judgment is: guardrails and tool selection are the two major use cases, and these tasks mostly involve classification, judgment, routing, and matching—not necessarily requiring generative text—thus falling within Jev AI's strengths. The implementation order should be guardrails first, tool selection second, because guardrail boundaries are clear with low validation costs; tool selection is more complex, and any component requiring natural language output must still rely on large language models. The author repeatedly emphasizes that strong performance is only a necessary condition for replacement, not a sufficient one—teams must first validate accuracy and stability on actual business data and adopt a progressive replacement strategy that retains large models as a fallback.
Related articles

Why Git Is Essential in the AI Era: From Version Control to Agent Collaboration
What's the difference between Git and GitHub? How do you manage changes with Issues, branches, and Pull Requests after AI Agents write code? Based on NetworkChuck's Git tutorial, this article walks through the complete flow from git init to conflict resolution and analyzes why version control has become an essential skill in the AI era.
OpenAI 6.2 Astra Hands-On Review Gone Wrong: Impressive Benchmarks, But Developers Say It's Unusable
OpenAI 6.2 Astra leads benchmarks at lower cost, but early testers report frequent stalls in long tasks, unparseable output, and uncontrolled resource management. We examine the gap between real-world experience and official data, and what it means for developer adoption.
GTA VI Coffee System Details Revealed: Hot Coffee Can Be Splashed on People?
Vergecast podcast reveals GTA VI's coffee system: players can brew in apartments, buy from vending machines, order in restaurants, and even splash hot coffee on others. This detailed recreation of daily interactions continues Red Dead Redemption 2's immersive design and sparks discussion on game detail versus gameplay balance.