Jev AI Matches or Beats LLM on 5 of 6 Benchmarks: Significant Latency and Cost Advantages

Jev AI matches or beats the large model Luna on 5 of 6 benchmarks, with low latency and low cost.
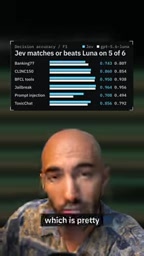
Based on a YouTube video analysis, Jev AI matches or exceeds the LLM Luna on five of six benchmarks, losing only on a banking intent classification benchmark where Luna scored 77. Jev leads on guardrail tests such as prompt injection and toxic check, indicating better safety and compliance for strict content control. It also has clear latency and cost advantages, making it more cost-effective for real-time and large-scale deployment. Jev offers a competitive alternative for specific scenarios and could expand its applicability as it is further optimized.
Small Model Challenges Big Model: Jev AI's Benchmark Performance
According to analysis of a YouTube video, Jev AI matches or exceeds the performance of an LLM (large language model) called Luna on five of six benchmarks. Given the significant differences in latency and cost between the two, this result is impressive.
The video notes that Jev either matches or beats Luna on most tests. Its only miss was a banking-focused intent classification benchmark (banking 77), where Luna performed better. On the remaining tests, Jev performed well, especially on guardrail-related benchmarks.
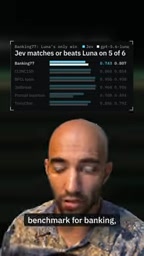
The Only Loss: Banking Intent Classification
The video explicitly states that the only benchmark Luna won was the banking intent classification task, with a score of 77. This test likely involves identifying the intent behind bank customer queries, a scenario where Luna showed an advantage. Apart from that, Jev was not outmatched on any of the other five benchmarks.
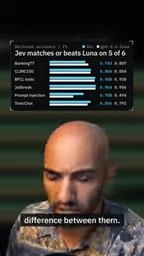
Intent classification is a fundamental task in natural language processing: given a user input, the model must determine which predefined category it belongs to, such as "check balance," "report a lost bank card," or "complain about fees." Banking scenarios place especially strict demands on intent classification because the category system is often fine-grained, terminology is highly specialized, and a single sentence may contain ambiguity or colloquial expressions. The "77" commonly seen in evaluations usually refers to a metric value such as accuracy or F1 score. Intent classification results directly determine whether subsequent dialogue routing leads to the correct business process, so a gap on this benchmark means small models may still lag behind large models on tasks requiring fine-grained domain knowledge.
Outstanding Performance on Guardrail Tests
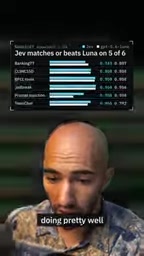
Jev performed particularly well on guardrail-related benchmarks. The video notes that on two tests—prompt injection and toxic check—Jev significantly outperformed Luna. This suggests that Jev has advantages in safety and compliance and may be more attractive for application scenarios requiring strict content control.
Prompt injection refers to an attacker embedding instructions in the input to try to override or bypass the system's preset behavioral constraints, such as making the model ignore safety rules, leak system prompts, or perform unauthorized operations. Toxic check requires the model to identify and block inappropriate content such as hate, harassment, and violence. Both fall under the category of "guardrails," the safety defenses deployed on both the input and output sides of the model. Models with strong guardrail capabilities are better suited to products open to end users, because they are less likely to fail when maliciously induced. If a small model can surpass a large model on these benchmarks, it often benefits from specialized training for safety alignment or more conservative refusal strategies.
Latency and Cost: Jev's Hidden Advantage
The video emphasizes that there are significant differences between Jev and Luna in latency and cost. Although no specific numbers are given, Jev can reduce latency and cost while maintaining performance, which may make it more cost-effective in real deployments. For scenarios requiring real-time responses or large-scale deployment, this advantage is especially critical.
Latency usually refers to the time from sending a request to receiving the first token or the complete response, directly determining whether the interactive experience is smooth; cost is often measured by the input/output price per million tokens, and the gap becomes more obvious at larger scale. Small models have fewer parameters and require less compute and memory for inference, so on the same hardware they can often achieve higher throughput and lower per-call cost. But there is usually a trade-off between performance and cost, and small models often suffer on complex reasoning. The significance of Jev is that it is not clearly dragged down by this trade-off on most benchmarks, making a cascaded architecture feasible: use smaller, faster models for most traffic and hand only difficult problems to large models.
Summary and Outlook
Jev AI matches or exceeds the LLM on most benchmarks, performs especially well on guardrail tests, and falls slightly short only on banking intent classification. Combined with its latency and cost advantages, Jev offers a competitive alternative for specific application scenarios. In the future, as the model is further optimized, its range of applications is expected to expand.
Background Note
It should be noted that benchmarks can only reflect performance under a specific task distribution and are not equivalent to real business results. The six benchmarks mentioned in the article cover dimensions such as intent classification and safety guardrails, but sample size, evaluation method, and prompt design all affect the conclusions; the latency and cost advantages also lack support from specific numbers. Therefore, a more cautious interpretation is: Jev can serve as a low-cost replacement for large models on tasks with clear boundaries such as "safety guardrails + routine classification," while scenarios requiring deep domain knowledge and fine-grained judgment (such as banking intent classification) should still retain large models or adopt a hybrid routing strategy, with pre-launch comparative evaluation using your own data.
One-line Summary
Jev AI matches or beats the large model Luna on five of six benchmarks, with low latency and low cost advantages.
Paragraph Summary
Based on analysis of a YouTube video, the article introduces the comparison between Jev AI and an LLM called Luna across six benchmarks: Jev matches or exceeds Luna on five of them, with its only loss on a banking intent classification benchmark where Luna scored 77. Jev's advantages are concentrated in guardrail tests, leading significantly on prompt injection and toxic check, indicating it is better suited to scenarios requiring strict content control in terms of safety and compliance. At the same time, Jev is clearly lower than Luna in latency and cost; although the original text gives no specific numbers, this makes it more cost-effective for real-time responses and large-scale deployment. The article concludes that Jev provides a competitive alternative for specific application scenarios, and as the model continues to be optimized, its scope of application is expected to expand further.
Related articles

Using and Topping Up Claude in China: Three Methods Compared and a Guide to Avoiding Account Bans
A guide to using and topping up Claude in China: compare direct overseas credit card payment, US Apple ID and Android Google Play in-app purchases, and self-service website top-up by barriers, cost, and suspension risk, plus five habits to reduce the chance of a ban.

From ChatGPT Content Restrictions to Eval, Observability, and Guardrail in Practice
Through a hands-on e-commerce order Agent, this article explains the engineering logic behind ChatGPT content restrictions and how Eval, Observability, and Guardrail work together to prevent same-name user data leaks and prompt injection risks.

DeepSeek Open-Sources Super-Agent: An Architecture Deep Dive into the Router and Worker Design of an Always-On Coding Assistant
DeepSeek open-sources the always-on coding agent dsh-superagent, using a separated Router-Worker architecture that balances continuous operation and permission control. This article analyzes its design approach, what the code actually delivers, and the safety debate surrounding autonomous coding assistants, helping developers decide whether it is worth learning from.