Jev: The New AI Model from a ChatGPT Inventor That's Thrilling Developers
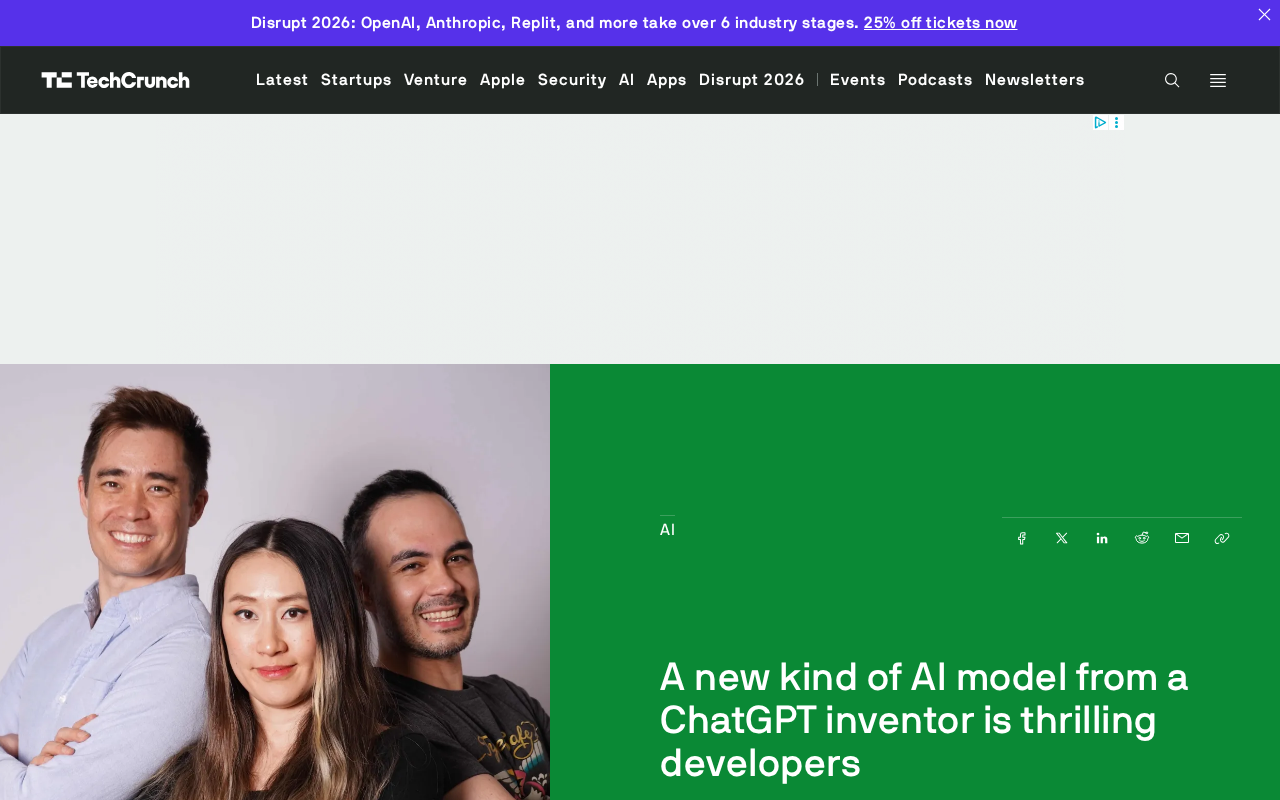
A ChatGPT co-creator's new model Jev targets lower cost and latency for software intelligence use cases.
Jev is a new AI model built by a core figure behind ChatGPT, positioned to deliver software intelligence at lower cost and with faster response times. In a landscape where high API fees and inference latency hinder real-world adoption, Jev aims to find a new balance between cost efficiency and capability. For agent systems, real-time code assistants, and other high-frequency use cases, speed and cost matter more than peak performance. That said, key details — parameter size, benchmarks, pricing — remain undisclosed, and its core claims await third-party validation.
A New Direction from a Key Figure Behind ChatGPT
According to overseas tech media reports, a new AI model called Jev is generating buzz in the developer community. The model comes from a core figure who was involved in building ChatGPT, and it leads with a sharp value proposition: offering a cheaper, faster path to software intelligence.
Against a backdrop where large models generally face steep compute costs and high inference expenses, Jev is trying to strike a new balance between cost and capability. That positioning alone is enough to excite developers who have long struggled with API call fees and response latency.
What Problem Is Jev Trying to Solve
Software intelligence refers to AI's ability to deeply engage with code comprehension, generation, debugging, and even system-level reasoning. This space has grown rapidly over the past two years, but it has also exposed two prominent pain points:
- High cost: Mainstream large models charge per token, and large-scale, high-frequency calls can quickly rack up staggering expenses — especially unfriendly to early-stage teams and individual developers.
- Slow speed: Complex reasoning often comes with significant response latency, which degrades the practical experience in interactive development workflows.
Jev is described as "a new kind of AI model," hinting that it may differ from conventional general-purpose large language models in architecture or training paradigm — and therefore achieve improvements on both dimensions. For developers embedding AI into real workflows, reductions in cost and latency are often more compelling than raw capability peaks.
The phrase "new kind of model" in the industry typically points to a few possible technical approaches: adopting a Mixture of Experts (MoE) architecture to reduce inference compute by dynamically routing to only a subset of parameters; applying Knowledge Distillation to compress a large model's capabilities into a smaller one; or conducting domain-specific training (e.g., focused on code) in exchange for moderate trade-offs in general capability. Any of these approaches, if well-designed, can significantly cut the compute required per inference while keeping the model useful for targeted tasks — reducing cost and shortening response time. Understanding this context helps in evaluating what engineering trade-offs underpin Jev's "cheaper and faster" claims.
Why Developers Are "Thrilled"
Developer excitement about new tools usually comes down to whether those tools can actually land in day-to-day work. A model that can both cut costs and improve response speed means more use cases — previously out of reach due to budget or performance constraints — suddenly become viable. Think real-time code assistants, bulk automation pipelines, and agent systems that require frequent model calls.
It's also worth noting that Jev's creator carries the credibility of a ChatGPT background. The industry pays attention to whether this technical figure has channeled their experience in large-scale model engineering into a leaner, more pragmatic product philosophy.
Agent systems are particularly sensitive to model latency and cost: a typical Agent task often requires multiple rounds of tool calls and reasoning, with the full chain potentially triggering dozens of model requests. If each call takes several seconds or carries significant cost, the agent's real-world utility suffers badly. That's precisely why "small but fast" models like Anthropic's Claude Haiku and OpenAI's GPT-4o mini have become favorites in agent scenarios — developers are willing to accept a slight dip in peak capability in exchange for lower latency and more predictable cost budgets. If Jev can carve out a similar position within the vertical of software intelligence, it would directly address this need.
Stay Cautious: Information Is Still Limited
To be transparent: the publicly available information about Jev is still quite limited. The original reporting approaches the story more from the angle of "trends" and "developer sentiment," without disclosing key details such as model parameter size, benchmark results, pricing, or degree of openness.
As a result, the core claim of "cheaper and faster" still needs validation from third-party evaluations and real-world usage feedback. In the AI space, there is often a gap between early excitement and actual engineering performance. Developers evaluating whether to adopt a new tool are best served by running small-scale trials in their own context, rather than drawing conclusions from marketing alone.
Summary
Jev represents an important direction in the current evolution of AI models: rather than purely chasing capability ceilings, the focus turns back to optimizing cost efficiency and response speed — the two metrics that ultimately determine whether a model works in production. With its creator's ChatGPT pedigree and its "new kind of model" positioning, Jev has already captured developers' attention. Whether it can deliver on its promises remains to be tested across real-world projects.
Related articles
Cloudflare Quick Tunnels: Expose Your Local Service to the Internet with One Command
Cloudflare Quick Tunnels lets developers expose local services to the internet with one cloudflared command — no account or domain needed, HTTPS included.
SCIM Logs Are Here: Finally Solving the Identity Provisioning Debugging Nightmare
SCIM directories now include a Logs tab showing every provisioning request, full JSON payloads, and human-readable failure explanations — making IdP debugging far easier.
AI vs. Human: Who Writes Better? Reflections on a New York Times Quiz
The NYT's AI vs. human writing quiz is going viral. We explore why AI text is harder to detect, what good writing really means, and what creators should do about it.