jev-tools: Letting AI Coding Agents Verify Their Work with Repository Evidence

jev-tools helps AI coding agents verify conclusions with repository evidence tools, reducing false confidence.
NomenAK's open-source jev-tools tackles AI coding agents confidently giving wrong conclusions by separating evidence gathering from semantic judgment. It offers six tools for Q&A, multi-file evaluation, file location, diff checks, and test selection, with MCP support and doc consistency checks. The authors note it cannot eliminate hallucinations—only structurally reduce uncertainty.
jev-tools: Letting AI Coding Agents Verify Their Work with Repository Evidence
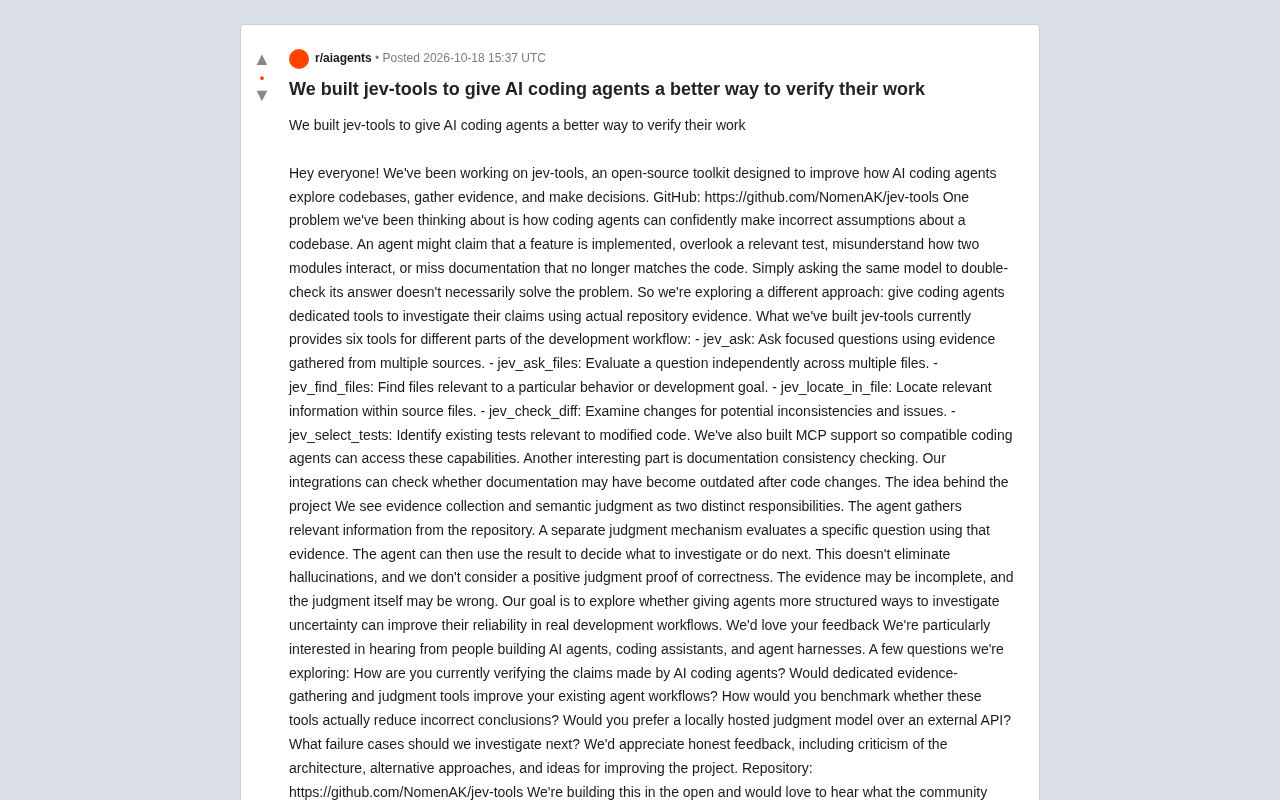
The most dangerous failure mode of AI coding agents isn't failing to write code—it's confidently producing wrong conclusions: claiming a feature is already implemented, missing related tests, misinterpreting module interactions, or citing outdated documentation. The developer team NomenAK has open-sourced jev-tools to tackle this problem at the engineering level: rather than having the same model "check again," give the agent a dedicated set of tools for gathering repository evidence.
The Problem: Why Self-Review Isn't Enough
In their post, the project authors point out a widely overlooked phenomenon: when coding agents make wrong assumptions about a codebase, they tend to sound just as certain. Simply asking the same model to double-check doesn't really address cognitive bias, because the review process still rests on the same context and reasoning path, lacking any external anchor.
jev-tools' approach is to separate "gathering evidence" from "judging." The agent collects evidence relevant to the question from the repository, a separate independent judgment mechanism answers specific questions based on that evidence, and the agent then decides on the next investigation step or action. This separation of responsibilities is the core design that distinguishes the project from ordinary "self-reflection" prompts.
Context refers to all the input information a model can "see" and use in a single inference, including system prompts, conversation history, tool return results, and so on. In self-review scenarios, when the same model re-examines its own output, the context available to it is nearly identical to the first inference, making it very difficult to spot the implicit wrong assumptions in the original reasoning. Cognitive bias here refers to the model's tendency to maintain its previously generated conclusions rather than actively falsifying them. Introducing external tools to obtain objective evidence from the repository is equivalent to providing the model with new, independent context anchors, thereby breaking this self-reinforcing loop.
Six Tools Covering the Development Workflow
jev-tools currently offers six tools, each corresponding to a different stage of the development process:
- jev_ask: Answers focused questions based on evidence gathered from multiple sources.
- jev_ask_files: Independently evaluates the same question across multiple files, avoiding misjudgments from a single-file perspective.
- jev_find_files: Locates relevant files based on a behavior or development goal.
- jev_locate_in_file: Precisely locates relevant information within a source file.
- jev_check_diff: Checks for potential inconsistencies and issues in changes.
- jev_select_tests: Identifies existing tests related to modified code.
Additionally, the project provides MCP (Model Context Protocol) support, allowing compatible coding agents to call these capabilities directly. Also worth noting is documentation consistency checking: once integrated, it can detect whether documentation has become outdated after code changes, which directly addresses the common blind spot mentioned earlier—"documentation and code no longer match."
Model Context Protocol (MCP) is an open protocol for standardizing how AI applications connect to external tools and data sources. In coding agent scenarios, MCP defines a unified interface that enables agents to discover and invoke external capabilities consistently, without needing to write separate integration code for each tool. jev-tools' MCP support means any coding agent that implements an MCP client—such as certain IDE plugins or command-line assistants—can directly call these six tools, lowering integration costs and decoupling the tools themselves from specific agent implementations.
Doesn't Eliminate Hallucinations, But Structurally Reduces Uncertainty
The authors are quite restrained in describing the boundaries of the capability: this toolset cannot eliminate hallucinations, and a positive judgment does not constitute proof of correctness—evidence may be incomplete, and the judgment itself may be wrong. The project's goal is simply to explore whether giving agents more structured ways to investigate uncertainty can improve reliability in real development workflows.
This honesty actually makes the architecture more credible. It shifts the problem from "make the model smarter" to "make the verification process more traceable"—a realist engineering approach rather than yet another marketing narrative claiming to solve hallucinations.
Hallucination in large language models refers to the model generating plausible-sounding but factually incorrect content, such as fabricating APIs, incorrectly referencing non-existent functions, or misjudging code behavior. In programming scenarios, hallucinations are especially dangerous because wrong conclusions are often presented in a confident tone, making developers prone to believing them. Common engineering approaches to reducing hallucinations include retrieval-augmented generation (RAG), tool calling, and external verification—all of which share the core idea of exposing the model to verifiable external information. jev-tools belongs to the external verification approach: it doesn't change the model itself but instead makes conclusions traceable through structured evidence gathering, thereby reducing unfounded assertions.
Open Questions Worth Watching
The project authors pose several questions to agent developers, coding assistant builders, and agent harness constructors that have yet to reach consensus: How do people currently verify the conclusions of AI coding agents? Can dedicated evidence-gathering and judgment tools improve existing workflows? How can benchmarks measure whether such tools actually reduce wrong conclusions? And is a locally deployed judgment model or an external API more widely accepted?
These questions themselves expose gaps in the current AI coding toolchain: the verification stage lacks recognized evaluation methods and best practices. jev-tools advances this in an open-source manner, and its value lies not only in the six tools themselves but in turning "how agents gather evidence" into an engineering topic that the community can discuss and examine.
One-line Summary
jev-tools helps AI coding agents verify conclusions with repository evidence tools, reducing false confidence.
Paragraph Summary
NomenAK's open-source jev-tools addresses the problem of AI coding agents confidently producing wrong conclusions by proposing an engineering solution that separates evidence gathering from semantic judgment. It provides six tools for focused Q&A, multi-file evaluation, locating relevant files, precise in-file location, checking code diffs, and selecting relevant tests, and supports MCP protocol integration. The project also integrates documentation consistency checking to detect outdated docs after code changes. The authors explicitly state that the tools do not eliminate hallucinations and that a positive judgment does not constitute proof of correctness—the goal is simply to reduce uncertainty in a structured way, and they have opened up community topics such as verification methods and benchmarking.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.