Kill Two Birds with One Stone: A Unified Skill-Augmented Generation Framework for Retrieval and Utilization

Skill-Uni jointly optimizes skill retrieval and utilization with a unified reinforcement learning framework, significantly boosting LLM task performance.
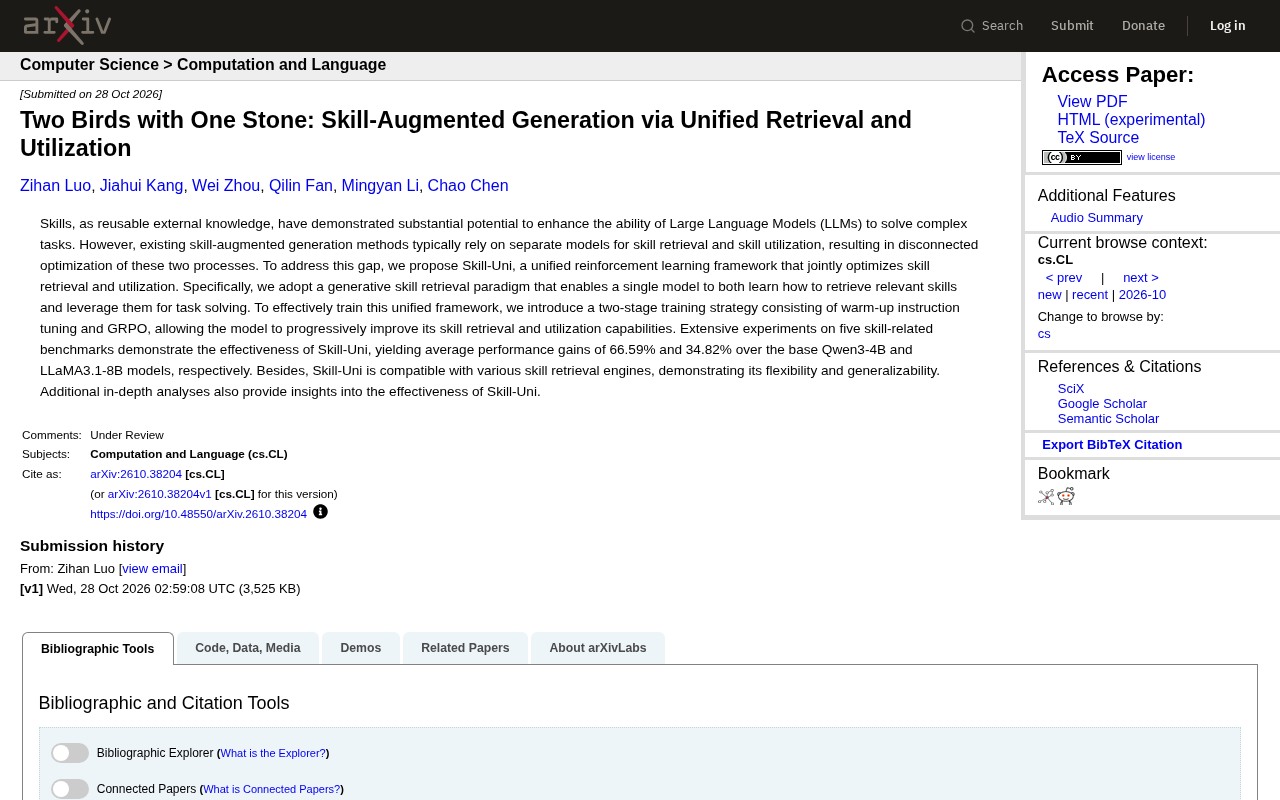
Skill-Uni is a unified reinforcement learning framework that addresses the separation of retrieval and utilization in skill-augmented generation. It uses a generative skill retrieval paradigm so a single model learns both to retrieve relevant skills and to use them for solving tasks, enabling end-to-end joint optimization. Training is two-stage: warm-up instruction tuning followed by GRPO reinforcement learning. On five skill-related benchmarks, Skill-Uni improves average performance by 66.59% over Qwen3-4B and 34.82% over LLaMA3.1-8B, and is compatible with multiple skill retrieval engines, showing strong flexibility and generality.
Large language models often need to leverage external knowledge to compensate for their own limitations when handling complex tasks. Skills, as a form of reusable external knowledge, have been shown to significantly enhance models' problem-solving capabilities. However, existing skill-augmented generation methods typically separate skill retrieval from skill utilization, processing them with independent models, which prevents the two processes from being optimized collaboratively. To address this pain point, researchers have proposed Skill-Uni—a unified reinforcement learning framework designed to jointly optimize skill retrieval and utilization, achieving a "kill two birds with one stone" effect.
Current State and Challenges of Skill-Augmented Generation
Currently, the mainstream approach to skill-augmented generation is a retrieval-utilization pipeline: first, a retrieval model finds relevant skills from a skill library, and then a generation model solves the problem based on these skills. Although this decoupled design is intuitive, it has obvious flaws. The retrieval model and the utilization model are trained independently, and the retrieval objective is not aligned with the final task objective—the retrieval model pursues recall relevance, while the generation model needs skills that are useful for the task. This misalignment of objectives limits overall performance, and the optimization of the two modules cannot mutually reinforce each other.
Skill-Uni was proposed precisely to break this separation. It adopts a generative skill retrieval paradigm, allowing a single model to simultaneously learn how to retrieve relevant skills and how to utilize skills to solve tasks. In this way, retrieval and utilization share the same set of parameters and can be jointly optimized end-to-end, fundamentally resolving the issue of inconsistent objectives.
Core Design of Skill-Uni: Unified Framework and Two-Stage Training
The core innovation of Skill-Uni lies in unifying skill retrieval and utilization into a single generative framework. The model no longer requires an independent retriever; instead, it directly generates skill identifiers or descriptions and then continues to generate the task answer based on them. This design naturally integrates the retrieval process into the generation flow, and the quality of retrieval is directly driven by the final task performance.
To effectively train this unified framework, the researchers designed a two-stage training strategy. The first stage is warm-up instruction tuning, which allows the model to initially familiarize itself with the basic patterns of skill retrieval and utilization; the second stage employs the GRPO (Group Relative Policy Optimization) reinforcement learning algorithm to further optimize the model's joint performance in retrieval and utilization. This progressive training enables the model to gradually improve its skill retrieval and utilization capabilities, avoiding the instability that direct reinforcement learning might introduce.
GRPO (Group Relative Policy Optimization) is a reinforcement learning algorithm proposed by the DeepSeekAd team, specifically designed for training large language models. Unlike traditional PPO (Proximal Policy Optimization), which requires training a separate value network (critic), GRPO estimates the advantage function through intra-group relative comparisons: it samples multiple responses for the same question and computes the relative advantage of each response using the group's average reward as a baseline, thereby eliminating the overhead of a value network. This design significantly reduces the computational cost and memory footprint of reinforcement learning while maintaining training stability. GRPO has been successfully applied in the training of reasoning models such as DeepSeek-R1, demonstrating good results on tasks like mathematical reasoning and code generation. Skill-Uni adopts GRPO for its second-stage training precisely because of its efficiency and stability in LLM scenarios.
Generative Retrieval is a retrieval paradigm fundamentally different from traditional dense vector retrieval. Traditional retrieval relies on dual-tower encoders to map queries and documents into vectors separately, and then uses approximate nearest neighbor search to find relevant documents; in contrast, generative retrieval treats document identifiers (such as DocID) or descriptions as target sequences, and the model directly generates retrieval results autoregressively. The advantages of this paradigm are: the retrieval process and the generation process share the same model and parameters, enabling end-to-end optimization; and the retrieval results directly serve downstream tasks, resulting in stronger objective consistency. Generative retrieval was first proposed in the document retrieval field (e.g., the DSI model) and has gradually expanded to scenarios such as multimodal retrieval and knowledge-augmented generation in recent years. Skill-Uni adopts this paradigm to naturally integrate skill retrieval into the generation flow, with retrieval quality driven by final task performance.
Experimental Results: Significant Performance Improvements and Broad Compatibility
The researchers conducted extensive experiments on five skill-related benchmarks. The results show that Skill-Uni achieves significant performance improvements over base models: an average improvement of 66.59% over Qwen3-4B and 34.82% over LLaMA3.1-8B. These numbers indicate that jointly optimizing retrieval and utilization indeed brings substantial benefits.
In addition to performance improvements, Skill-Uni also demonstrates good flexibility and generality. It is compatible with a variety of skill retrieval engines, meaning users can choose different retrieval backends according to their actual needs without being limited to a specific implementation. This compatibility lowers the deployment barrier and enhances the framework's practicality. Furthermore, the researchers conducted in-depth analyses that further reveal the sources of Skill-Uni's effectiveness, providing valuable references for future research.
Implications for the Field of Skill-Augmented Generation
The success of Skill-Uni validates an important idea: skill retrieval and skill utilization should not be treated as two separate steps but should be optimized as a whole. This unified perspective not only improves performance but also simplifies the system architecture—there is no longer a need to maintain multiple models, and both training and inference pipelines become more streamlined.
From a broader perspective, Skill-Uni represents a trend in the field of skill-augmented generation: moving from modular pipelines to end-to-end joint optimization. As LLM application scenarios become increasingly complex, how to efficiently leverage external knowledge will become a key competitive advantage. The unified reinforcement learning framework provided by Skill-Uni opens up new directions for future research and reminds us that sometimes "killing two birds with one stone" is not impossible—the key lies in finding the right way to integrate.
For developers, Skill-Uni's compatibility means it can be combined with existing skill libraries and retrieval engines and quickly integrated into practical applications. Although the paper does not disclose specific deployment details, its design philosophy is already clear enough: use a single model to unify retrieval and utilization, use two-stage training to ensure effectiveness, and use compatibility to ensure practical implementation. These three points constitute the core value of Skill-Uni and deserve close attention from practitioners in the field of skill-augmented generation.
One-line Summary
Skill-Uni jointly optimizes skill retrieval and utilization with a unified reinforcement learning framework, significantly improving LLM task performance.
Paragraph Summary
Skill-Uni is a unified reinforcement learning framework designed to address the separation of retrieval and utilization in skill-augmented generation. Traditional methods use decoupled pipelines where retrieval and generation models are trained independently, leading to inconsistent objectives and limited performance. Skill-Uni adopts a generative skill retrieval paradigm, enabling a single model to simultaneously learn to retrieve relevant skills and utilize them to solve tasks, achieving end-to-end joint optimization. Training uses a two-stage strategy: warm-up instruction tuning followed by the GRPO reinforcement learning algorithm to optimize joint performance. On five skill-related benchmarks, Skill-Uni achieves average improvements of 66.59% and 34.82% over Qwen3-4B and LLaMA3.1-8B, respectively, and is compatible with multiple skill retrieval engines, demonstrating strong flexibility and generality.
Related articles

Fifty Years Studying Power: Robert Caro's Writing and Insights on Power
Robert Caro reflects on 50 years studying power: Lyndon Johnson's persuasion and leverage, Robert Moses's transformation from idealist to ruthless builder, the dilemmas of large-scale construction, and his methods of compressing themes and solitary focus in biography writing.

Can a $20,000 Robot Do Your Chores? The Test Results Are Surprising
A YouTube test video shows how a $20,000 robot responds to commands like washing dishes, turning off lights, taking out trash, and feeding the dog. This article analyzes its real capability boundaries, the state of voice interaction technology, and how far household robots are from mainstream adoption.
The Complete Guide to Running AI Models Locally: Inference Engines and Tool Stack Explained
A systematic breakdown of the complete local LLM tool stack: from PyTorch and GGML compute libraries to llama.cpp, vLLM, SGLang inference engines and Ollama, LM Studio wrapper layers, with benchmark data on performance differences and selection logic.