Language Models Can Rewrite Their Own Weights: A New Paradigm for Self-Editing AI
A new paper enables language models to generate weight deltas during inference to directly modify their own parameters, achieving persistent knowledge updates.
The article introduces a new study: letting language models generate modifications to their own parameter matrices during inference, rather than relying on external fine-tuning or prompt engineering. The technical approach has two steps—the model receives a natural language instruction and generates low-rank or sparse weight deltas, relying on a meta-learning framework to map semantic intent to parameter changes. Unlike in-context learning, weight rewriting is persistent; unlike standard fine-tuning, the executor is the model itself. The Hacker News community focuses on reversibility, modification verification, and security boundaries. This direction may blur the boundary between training and inference and open a new path for continual learning, but it would reduce auditability. It is currently still in the controlled experimental stage, and there is still a distance from safe autonomous self-editing.
From "Parameter Tuning" to "Self-Modification": Models Gain the Ability to Edit Themselves
Traditionally, adjusting the behavior of large language models requires external intervention—fine-tuning, prompt engineering, or retraining via RLHF. But a new paper proposes a more ambitious direction: letting language models directly rewrite their own weights. This is not a metaphor—it refers to the model generating modifications to its own parameter matrices during inference, thereby accomplishing knowledge updates or behavior correction.
The work garnered 328 points and 106 comments on Hacker News, and the heated discussion shows the community's strong interest in the proposition of "model self-editing." The core question is no longer "can the model learn" but "can the model consciously modify itself."
Technical Approach: Weight Generation and Meta-Learning
The paper's core idea can be broken down into two steps. First, the model receives a natural language instruction describing the target modification, such as "learn this new fact" or "correct this erroneous tendency." Second, the model generates a set of weight deltas—not text output, but numerical updates applied directly to its own parameters. This requires the model to have a structured understanding of its own parameter space, not just forward inference capability.
In implementation, this relies on a meta-learning framework: during training, the model sees a large number of "instruction → weight modification" paired samples, thereby learning to map semantic intent to parameter changes. The key challenge is that weights are parameter vectors on the order of millions to billions, and the model must generate low-rank or sparse modifications to make computation feasible. The method adopted in the paper constrains weight deltas to a low-dimensional subspace.
Low-Rank and Sparse Modifications: The parameter count of weight matrices typically ranges from millions to billions. If the model directly outputs full weight deltas, both computation and storage costs become infeasible. Low-rank decomposition (such as LoRA) represents the delta as the product of two small matrices, compressing trainable parameters to a tiny fraction of the original matrix; sparse modification updates only a small number of non-zero elements. Both approaches keep computation feasible when the model generates modifications, while limiting the scope of impact of each edit and reducing the risk of catastrophic forgetting. The paper's constraint of weight deltas to a low-dimensional subspace is precisely an embodiment of this line of thinking.
Meta-Learning Framework: The core of meta-learning is "learning to learn," i.e., after training on a large number of tasks, the model gains the ability to quickly adapt to new tasks. In this work, the training phase provides a large number of "natural language instruction → weight modification" paired samples, from which the model learns to map semantic intent to parameter changes. This "instruction-to-weight" mapping capability is itself a product of meta-learning, enabling the model to generate reasonable weight deltas for new instructions during inference, rather than merely performing forward inference.
Essential Differences from Existing Approaches
This is fundamentally different from in-context learning. In-context learning places new information in the prompt; the model weights remain unchanged, and the model temporarily "references" this information during inference. Weight rewriting, by contrast, is persistent—once a modification is written, all subsequent inferences carry it, without the need to repeatedly provide instructions.
The difference from standard fine-tuning lies in the executor: fine-tuning is driven by an external training process, and the model is a passive object; weight rewriting is initiated by the model itself, making the model both the executor and the beneficiary. This "self-referential" property brings new security considerations and opens up new possibilities for continual learning.
In-Context Learning: In-context learning refers to the model completing new tasks solely through examples or information provided in the prompt, without updating weights. New information exists in the context during inference, and once the context is cleared, the information is lost. Weight rewriting, by contrast, persists modifications into the parameters, so subsequent inferences do not need to repeatedly provide instructions—this is the fundamental difference between the two in terms of information persistence.
RLHF: Reinforcement Learning from Human Feedback (RLHF) fine-tunes model behavior through external reward signals; the training process is externally driven, and the model is a passively adjusted object. Weight rewriting, by contrast, has the model itself generate parameter modifications, making the model both the executor and the beneficiary. This self-referential property brings new issues such as reversibility, verification, and security boundaries, and also distinguishes it from the passive mode of traditional fine-tuning.
Community Concerns and Potential Impact
The 106 comments on Hacker News reflect several concentrated concerns. First, reversibility: if a model can rewrite itself, can it equally cleanly roll back an erroneous modification? Second, the verification problem: how do you confirm that a weight modification actually achieves the intended semantic effect rather than introducing hidden bias? Third, security boundaries: could a self-editing model bypass external constraints to make unauthorized modifications?
On the positive side, this path points toward a truly continual learning system—when the model encounters new knowledge after deployment, it can update itself rather than waiting for the next round of training. But the cost is that the auditability of model behavior would significantly decrease.
Still Early, but the Direction Is Worth Tracking
The paper currently demonstrates weight editing capability under controlled conditions, and there is still a considerable distance from autonomously and safely modifying itself in open environments. However, it raises a question worth taking seriously: when a model can modify its own parameters, the boundary between "training" and "inference" is no longer clear. For AI researchers, this may be a key path toward adaptive systems; for safety researchers, this is a new attack surface that requires guardrails to be established in advance.
One-line Summary
A new paper lets language models generate weight deltas during inference to directly modify their own parameters, enabling persistent knowledge updates.
Paragraph Summary
The article introduces a new study: letting language models generate modifications to their own parameter matrices during inference, rather than relying on external fine-tuning or prompt engineering. The technical approach has two steps—the model receives a natural language instruction and generates low-rank or sparse weight deltas, relying on a meta-learning framework to map semantic intent to parameter changes. Unlike in-context learning, weight rewriting is persistent; unlike standard fine-tuning, the executor is the model itself. The Hacker News community focuses on three major issues: reversibility, modification verification, and security boundaries. This direction may blur the boundary between training and inference and open a new path for continual learning, but it would reduce auditability. It is currently still in the controlled experimental stage, and there is still a distance from safe autonomous self-editing.
Related articles
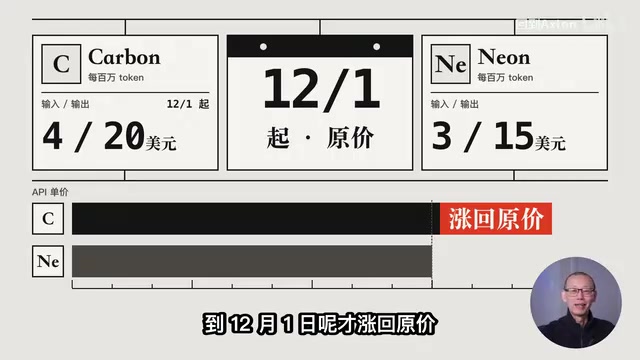
Deep Dive: Uncovering the Capabilities of the Entire Gemini 4 Model Family — Why Does the Default Tier Rank Last?
Double-blind testing of Gemini 4's four models — Argon, Carbon, Hydrogen, Neon — reveals why the default Neon High ranks last, how X High overtakes Carbon, and how Orchestrator sweeps 3-0, plus cost breakdown and four selection tips.
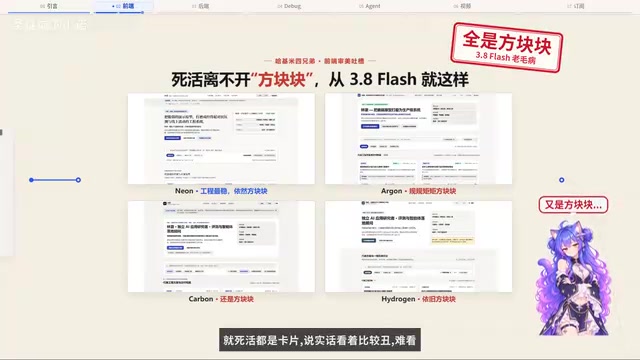
One Week with the Gemini 4 Family: Four Models Each Take a Crown on the Private Leaderboard, Carbon's Speed Polarizes
Bilibili creator tests the Gemini 4 family for a week: Neo, Argon, Carbon, and Hydrogen each top a private leaderboard, frontend aesthetics are weak, Carbon is strongest but slow.
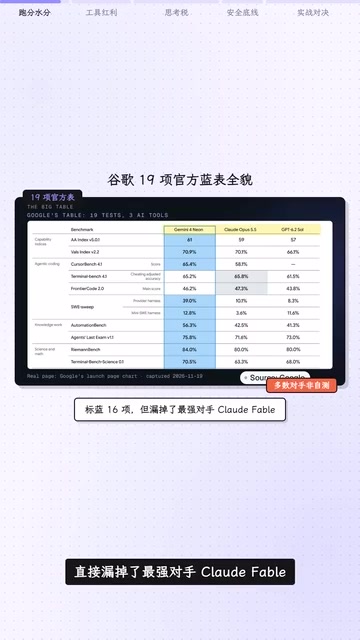
Is Gemini 4 Neon Really Better Than GPT-6.2 Sol? Breaking Down the Benchmarks
Google's Gemini 4 Neon won 16 of 19 official benchmarks, but independent testing and real-world bills reveal tool differences, thinking costs, and response speed that make GPT-6.2 Sol the better value.