Letting AI Build AI Tools: A 7-Day, 31-Commit Bootstrapping Post-Mortem

7 days, 31 commits: how an AI bootstrapping flywheel turns every failure into a permanent immunity gate.
An engineer built a fully autonomous AI development pipeline where AI selects topics, writes code, and validates against a 51-step regression gate daily — no human needed. Over 7 days and 31 commits, the bootstrapping success rate was just one in six. Yet the author calls it a win: 60+ pitfalls converged into 11 structural rules, all baked into automated checks that expanded the regression gate from 51 to 74 steps. Key lessons include treating measurement failures as evidence rather than halts, separating judgment from proof, and ensuring every AI instruction is verifiable.
What if you let one AI system autonomously develop another AI tool — no human in the loop? It sounds like science fiction, but one engineer actually made it work. Seven days. 31 commits. A bootstrapping success rate of one in six. Those numbers look grim, but the author's conclusion was: "totally worth it." The reason lies in how failures were handled: every pitfall the flywheel stumbled into became a permanent immunity record baked into the system itself.
What Is the AI-Builds-AI Bootstrapping Flywheel?
The engineer built a fully automated development pipeline: every morning at 7:30 AM, the system selects its own topic, drafts its own spec, writes its own code, then runs through a 51-step regression gate — all without human intervention. A task is only considered complete when every gate passes. And the system that built this pipeline? Another AI. Using AI to develop AI tooling — that's what "bootstrapping" means here.
The concept is elegant. The pitfalls are all in the details. On the very first morning at 7:30 AM, the flywheel was rejected before it even started — not by a hacker or a permissions issue, but by a dirty Git working directory the system had created the night before. Over seven days, the author hit 60+ issues, which ultimately converged into 11 structural rules.
A note on terms: The word "bootstrapping" comes from the compiler world: using an old version of a language's compiler to compile the new version, letting the language "pull itself up by its own bootstraps." In AI engineering, bootstrapping refers to using one AI system to build, test, or improve another, reducing direct human involvement in the development loop. A regression gate is a mandatory checkpoint in continuous integration: changes are only allowed to merge when all predefined tests pass. Combined, they act like a mechanical "integrity guarantee" for an unattended AI pipeline — the AI cannot bypass tests and lie to itself.
Five of the Most Typical Pitfalls
The Program Kills Itself
The most counterintuitive category: the flywheel writes daily run ledgers and scorecards, which are tracked by Git. Writing them dirties the working directory. The sandbox pre-check sees an unclean state and refuses to launch. This same trap appeared six times over seven days in different disguises — scorecards, clarification ledgers, impact accounts — all with the same root fuse.
The fix: add a pre-check that reports "dirty zone overflow" when the dirty area exceeds 50 lines, and move all runtime data out of Git tracking.
Measurement Itself Crashes the System
One day the system triggered a "circuit breaker shutdown" — twice, as false positives. Investigation revealed 103MB of build artifacts sitting in the working directory. The fingerprinting algorithm was using Git Diff's binary full-text mode, doing a full 103MB comparison plus per-file disk reads, re-reading 200+ files every window. The fix came in three cuts: change fingerprinting to list filenames only; for files over 1MB, only sample the size plus the first and last 4KB; and treat sensing failures as something other than zero progress.
Unbounded Feedback Blows Up the CLI
One checker produced 510KB of logs, which got stuffed wholesale into the next prompt. On Linux this would just be slow, but this was Windows — command-line arguments have a length limit. The dispatch crashed with "argument too long". The lesson is blunt: unbounded feedback is a crash bug, not just a minor inefficiency. Feedback is now compressed to 2.8KB, with an 8KB tail-truncation safety net and proper UTF-8 boundary handling.
The AI Doesn't Know When to Stop
The same login error burned through three context windows and three hours with nobody stopping it. The root cause was that failures weren't normalized, making cross-window comparison impossible.
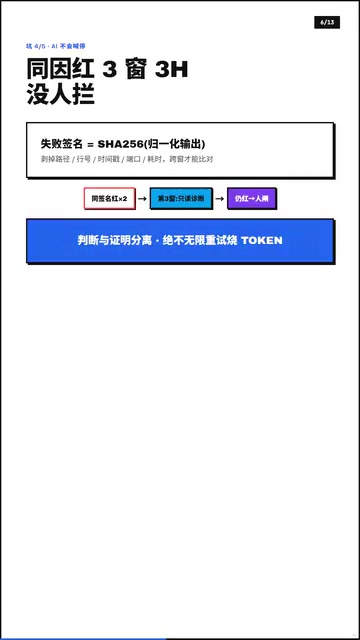
The fix: introduce a circuit breaker. Strip paths, line numbers, and timestamps from output, then bucket outputs into 256 failure signatures. If the same signature fires two windows in a row, the third window stops dispatching a code-writing AI and instead dispatches a read-only diagnostic agent to find the root cause. If the issue remains unresolved after diagnosis, it escalates to a human — no infinite retries burning tokens.
On Circuit Breakers: The Circuit Breaker pattern is borrowed from electrical engineering: when a circuit overloads, the physical breaker trips automatically to prevent wider damage. In software, Netflix's Hystrix library brought this concept to microservice fault tolerance — when a downstream service fails repeatedly past a threshold, the caller automatically falls back to degraded logic instead of retrying indefinitely and dragging down the whole chain. In AI agent contexts, circuit breakers matter even more: a single LLM call can consume thousands of tokens, and unbounded retries not only burn money but cause context window bloat that degrades model output quality in a negative feedback spiral. The approach described here — "switch to diagnostic mode after the same signature fires twice" — effectively replaces "HTTP response codes" with "semantic failure fingerprints" as the circuit breaker threshold.
Assertions Built on Pure Imagination
The most painful category: an AI-written end-to-end test failed four times in a row, burning an hour and a half, while the author fixed everything manually in ten minutes by just opening the page. A classic example: a button rendered with a space in the middle of its label text, and the AI's regex could never match it. The root cause was that expected values had no basis in reality — they were hallucinated. The fix: assertions must be generated from actual page renders; bare Chinese-character regexes are banned in favor of role-plus-name exact matching.
Three of the Most Valuable Structural Rules
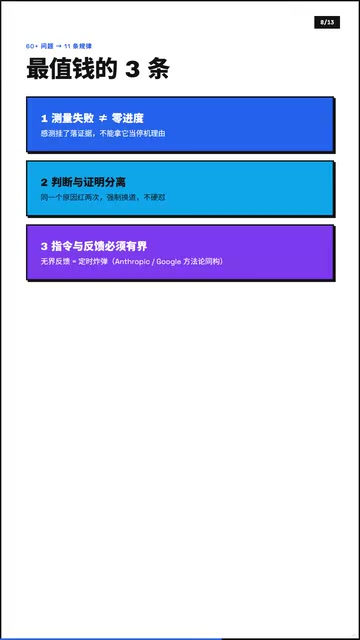
From 60+ issues, the author distilled 11 rules. Three stand out as most valuable:
- Measurement failure ≠ zero progress: When detection hangs, record the evidence — don't treat it as grounds to halt.
-
Judgment and proof must be separated: When the same root cause fires red twice in a row, forcibly switch to diagnostic mode.
-
Every instruction must be verifiable: Every instruction and every piece of feedback given to the AI must have a clear verification mechanism. No verification means a live bomb.
The author notes that all three of these rules have structurally equivalent counterparts in Anthropic's and Google's published methodologies — they're not unique findings.
AI Auditing AI: Nine Discrepancies Caught
Interestingly, this post-mortem itself went through a rigorous quality check. Three independent subagents performed adversarial re-verification, cross-checking 120 verifiable claims including 26 commit hashes and 40+ referenced line numbers. Result: zero fabrications confirmed, nine corrections made — all involving line number drift and unit conversion discrepancies. For example, the original text stated "bootstrapping passed the next day," but the audit ledger showed two consecutive days of silent failure. AI auditing AI can genuinely catch AI's own mistakes.
On Adversarial Multi-Agent Verification: Adversarial multi-agent verification is an emerging approach to improving LLM output reliability: multiple independent subagents each play the role of "proposer" and "challenger," cross-checking each other to reduce single-point hallucination. The theoretical basis is that different reasoning paths are far less likely to produce identical errors than a single path, so parallel multi-path verification significantly reduces systematic false positives. However, this mechanism has an important boundary: it excels at detecting anchored factual deviations (line numbers, timestamps, hash values), but is less effective against systematic biases at the logical reasoning level (when all subagents share the same training biases). The "zero fabrications, nine discrepancy corrections" result here falls squarely within the most effective operating range of this mechanism.
Why "Totally Worth It"
The key is the regression gate curve: it grew from 51 steps to 74 steps. Those extra 23 steps are automated checks earned through each day's failures — test isolation, failure signatures, circuit breakers, reality-anchored assertions, and boundary protections.
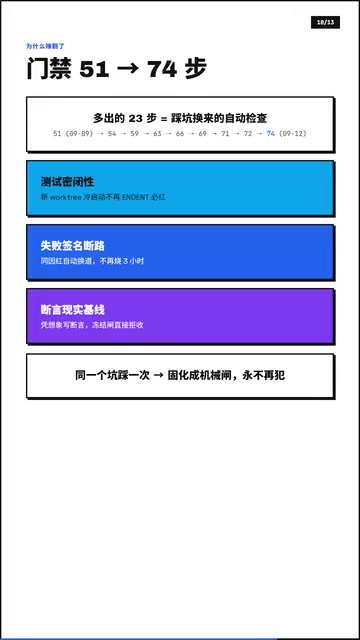
Every pitfall, once hit, gets hardened into a mechanical gate — the flywheel never makes the same mistake twice. That's the point of the bootstrapping flywheel: every error it makes becomes part of its own immune system. 31 commits = 31 immunity records.
The author offers three actions you can take the same day: First, move all runtime ledgers out of Git tracking. Second, add failure signatures to your automation — if the same error appears twice in a row, force a change in response strategy. Third, for AI-written test assertions, expected values must come from real page renders, never from imagination. None of these require a new framework. All are effective immediately.
Closing: The Intern and the Immune System
Is AI-driven development actually reliable? The author's answer is dialectically nuanced: looking at any single failure, it's as clueless as a first-day intern; but zoomed out across seven days, it converts every mistake into a permanent gate. Human engineers repeat the same mistakes. The flywheel doesn't. This may be the most underrated value of AI bootstrapped development — not the per-run success rate, but the accumulability of failure.
Related articles
Hierarchical RAG Architecture Research: How Independent Developers Can Break Into Academic Research
An indie developer on Reddit seeks IR professor guidance for hierarchical RAG research. This article explores the technical background and practical advice for independent AI researchers facing academic barriers.
Blind Entrepreneur Uses Claude to Build Accessible Product, Sells It for $1,700
A blind entrepreneur used Claude to build an accessible tool for a blind client and sold it for $1,700 — revealing why domain knowledge, not just AI, makes products truly usable.
Datamimic: Giving AI Coding Assistants a Controlled Test Data World
Datamimic is an open-source tool arguing against letting AI coding agents fabricate test data. This article examines the reliability risks of AI-generated test data and the value of controlled test data for development quality.