Lloyal: Package Open-Source LLMs into Downloadable Offline AI Apps

Lloyal packages open-source LLMs into offline, no-API-key AI apps via a TypeScript scaffold with multi-agent runtime.
Lloyal is an AI application framework for indie developers and small teams, designed to rapidly productize open-weight LLMs. It ships with a built-in inference engine and multi-agent runtime supporting local research, file access, document understanding, and specialist model composition — no agent scheduling logic needed from scratch. Offline-first and privacy-focused, it requires no API keys and keeps data on-device. Built on TypeScript, it deploys to desktop, web, or terminal from a single codebase. Key details like supported models, inference backend, and licensing terms are not yet fully public.
A Development Framework That Turns Open-Source Models into Desktop Apps
On Product Hunt, a developer tool called Lloyal recently climbed to #19 on the daily chart, earning 75 upvotes and a handful of discussions. Its positioning is straightforward: turn open-weight models into downloadable AI apps that anyone can use right away.
For developers, this tagline addresses a long-standing pain point — how to package a locally running LLM into polished software that doesn't rely on cloud APIs, doesn't require users to configure API keys, and works out of the box. Lloyal's answer is a TypeScript AI application scaffold with a built-in inference engine and multi-agent runtime, giving developers a working product prototype from the very first line of code.
Core Capabilities: Built-in Inference + Multi-Agent Runtime
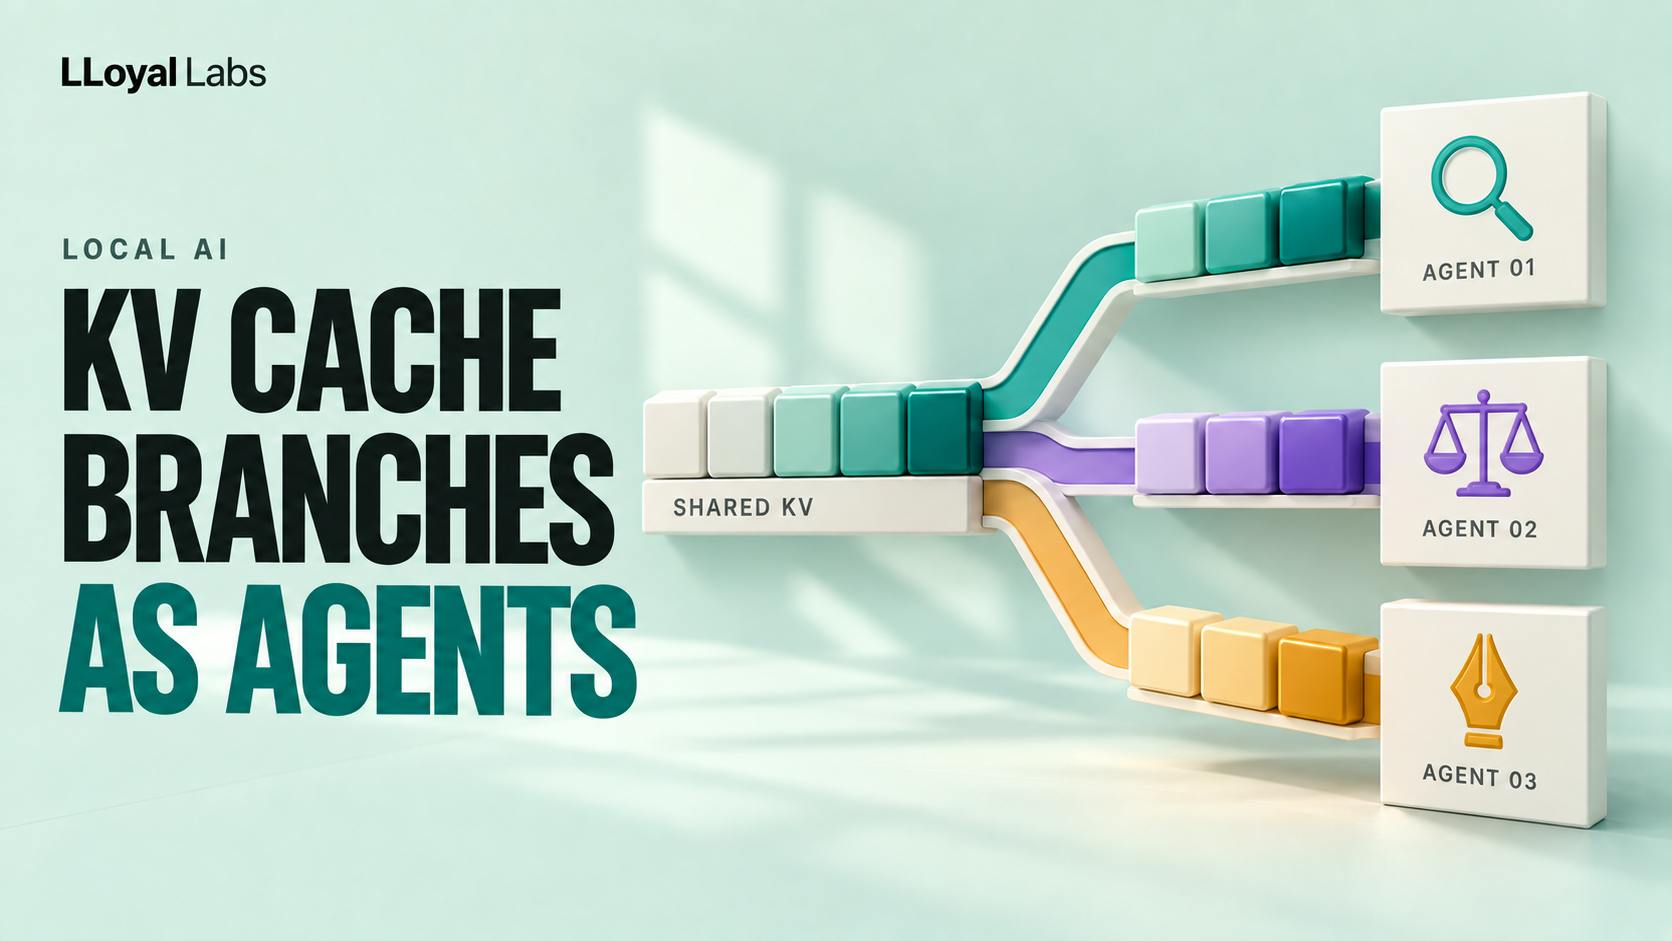
What makes Lloyal most noteworthy is that it ships with its own inference capabilities and multi-agent runtime — rather than simply wrapping a UI layer around existing tools.
According to the official description, the built-in agents can handle several types of tasks:
- Online or local research: Agents autonomously retrieve and organize information;
- Local file access: Directly read documents on the user's device without uploading to the cloud;
- Document understanding: Parse and answer questions about PDFs, text files, and similar content;
- Compose specialist models: Route different specialized models to collaborate on complex workflows.
This multi-agent architecture means developers don't have to build agent scheduling logic from scratch — they customize on top of an existing runtime framework. For teams looking to rapidly validate AI product ideas, this eliminates a significant amount of low-level infrastructure work.
Multi-agent Runtime represents an important paradigm shift in AI application development. In the traditional single-model invocation pattern, one request is handled independently by one model. A multi-agent architecture allows complex tasks to be broken down into subtasks, with agents of different capabilities or system prompts collaborating under a unified orchestrator. Frameworks like AutoGen, LangGraph, and CrewAI all adopt similar designs. The key advantages are composability and maintainability — each sub-agent can be optimized for a specific task. The challenges include inter-agent communication latency, error propagation risk, and debugging complexity. By embedding this runtime into the scaffold, Lloyal means developers don't need to implement task dispatch, state management, or result aggregation themselves — they can build directly on top of preconfigured collaboration patterns.
Offline-First and Privacy: No API Keys Required
It's no coincidence that Lloyal is listed under three Product Hunt categories: Software Engineering, Privacy, and Artificial Intelligence.
It emphasizes works offline, with no API keys and no complex configuration required on the user side. This stands in sharp contrast to the large number of AI apps today that depend on cloud APIs from OpenAI, Anthropic, and similar providers.
Running offline has an immediate privacy benefit: local files and documents never leave the user's device, and sensitive data doesn't pass through third-party servers. For compliance-sensitive domains like legal, healthcare, and enterprise environments, local inference is a compelling direction. Offline also means no per-call cloud costs — end users download the app once and can keep using it indefinitely.
Local inference relies on models and inference engines optimized for on-device execution. Current mainstream solutions include: llama.cpp (C++ implementation with CPU and Metal/CUDA acceleration), Ollama (which wraps llama.cpp as a local service), ONNX Runtime, and Apple's Core ML. These tools use quantization techniques (such as INT4 and INT8) to reduce model parameter precision, enabling large models that would otherwise require tens of gigabytes of VRAM to run on consumer hardware — at the cost of some accuracy. Today, quantized models in the 7B–13B parameter range run smoothly on modern laptops with 8–16 GB of RAM. Lloyal has not publicly disclosed the specific inference backend it uses under the hood, which is a key area developers should investigate before committing — the choice of inference backend directly determines which model families are supported, runtime performance, and hardware compatibility.
Multi-Platform Delivery: Desktop, Web, and Terminal
Beyond inference and privacy, Lloyal's other selling point is delivery flexibility. The team claims developers can customize and ship an app to desktop, web, or terminal in just a few minutes.
This write-once, deploy-anywhere approach lowers the barrier from prototype to finished product. The TypeScript stack also means that the large community of developers familiar with frontend and Node.js ecosystems can get up to speed quickly — without having to dive deep into Python ML toolchains.
Building cross-platform desktop apps on a TypeScript/JavaScript stack currently centers on two mainstream solutions: Electron (Chromium + Node.js, widely used by VS Code, Slack, and others) and Tauri (Rust backend + native system WebView, with smaller bundle sizes and lower memory usage). Both allow developers to write UIs with web frontend technologies while accessing native capabilities like the local filesystem and child processes through a backend process. For AI apps that need to bundle a local inference engine, packaging strategy is especially critical: inference backends (such as compiled llama.cpp binaries) and model weight files tend to be large, requiring tradeoffs between installer size, first-download experience, and offline availability. The technical choices and packaging strategies behind Lloyal's multi-platform delivery capabilities are worth scrutinizing closely.
Who It's For — and What Remains Unknown
Based on publicly available information, Lloyal targets independent developers and small teams who want to productize open-source models and deliver them as downloadable software to non-technical users. Its value proposition is clear: reduce the cost of developing and distributing local AI applications.
That said, the Product Hunt page still offers limited detail. Several key questions remain unanswered:
- Which open-source models are actually supported, and through what inference backend;
- Performance and resource usage on typical consumer hardware;
- The extensibility and customization freedom of the multi-agent runtime;
- The specifics of commercial licensing and the extent of open-source availability.
These will need to be verified through hands-on testing. But directionally, Lloyal is squarely aligned with two clear trends — the proliferation of open-weight models and the growing demand for local, privacy-first AI applications. As on-device model capabilities continue to improve, toolchains like this — ones that turn models into downloadable apps — could become a new distribution channel for AI applications.
Related articles

Python 3.15 New Feature: Is the sentinel Type Better Than None?
Python 3.15 adds the sentinel type, using named unique sentinel objects to replace None and bare object(), resolving confusion among missing values, explicit emptiness, and invalid input while avoiding type hint failures.

Deep Learning's Three Architectures and the Universal Approximation Theorem: A Complete Guide to MLPs, CNNs, and Transformers
Explaining the inductive bias differences among MLP, CNN, and Transformer, the existence meaning of the Universal Approximation Theorem (UAT), and the role of Taylor expansion in approximation analysis, while clearing up common misconceptions.

GitLab Emergency Patch Release: Analysis of Critical Security Fixes
GitLab releases critical patch 19.5.1, sparking 355 points of discussion on Hacker News. This article analyzes the background, upgrade steps for self-hosted instances, and verification points to help DevOps teams respond quickly to security updates.