Local AI Agent Reads arXiv So You Don't Have To: Only the Papers That Actually Matter

An open-source local AI agent that filters arXiv daily and pushes only papers relevant to your research.
Research Radar is an open-source local AI agent that runs daily to fetch, score, deep-read, and push arXiv papers truly relevant to your research. It runs fully offline via Ollama, vLLM, and other local backends, keeping data on your machine at zero cost, and adapts to any field with a single Markdown config file.
From Information Overload to Precise Filtering
For every researcher, the pile of papers waiting to be read only grows longer. One developer shared his solution on Reddit: he used to spend 30-60 minutes daily browsing X (Twitter) or arXiv listings, only to find that 95% of the content had nothing to do with his actual research. Traditional newsletters don't help either—they push what's "trending" rather than what's "relevant to your research."
arXiv, a free preprint server operated by Cornell University, has become the core platform for researchers in physics, mathematics, computer science, statistics, and other fields to publish papers since its founding in 1991. Hundreds to thousands of new papers are added daily; machine learning categories like cs.AI and cs.LG alone can generate over 200 new papers per day—which is precisely the root of the information overload problem.
To address this pain point, he built a local AI agent called Research Radar. It's a daily cron job that automatically fetches, scores, deep-reads, and pushes the new papers that truly matter to your personal research direction. After sticking with it for about a month, the author says it's "genuinely very useful within my own field."
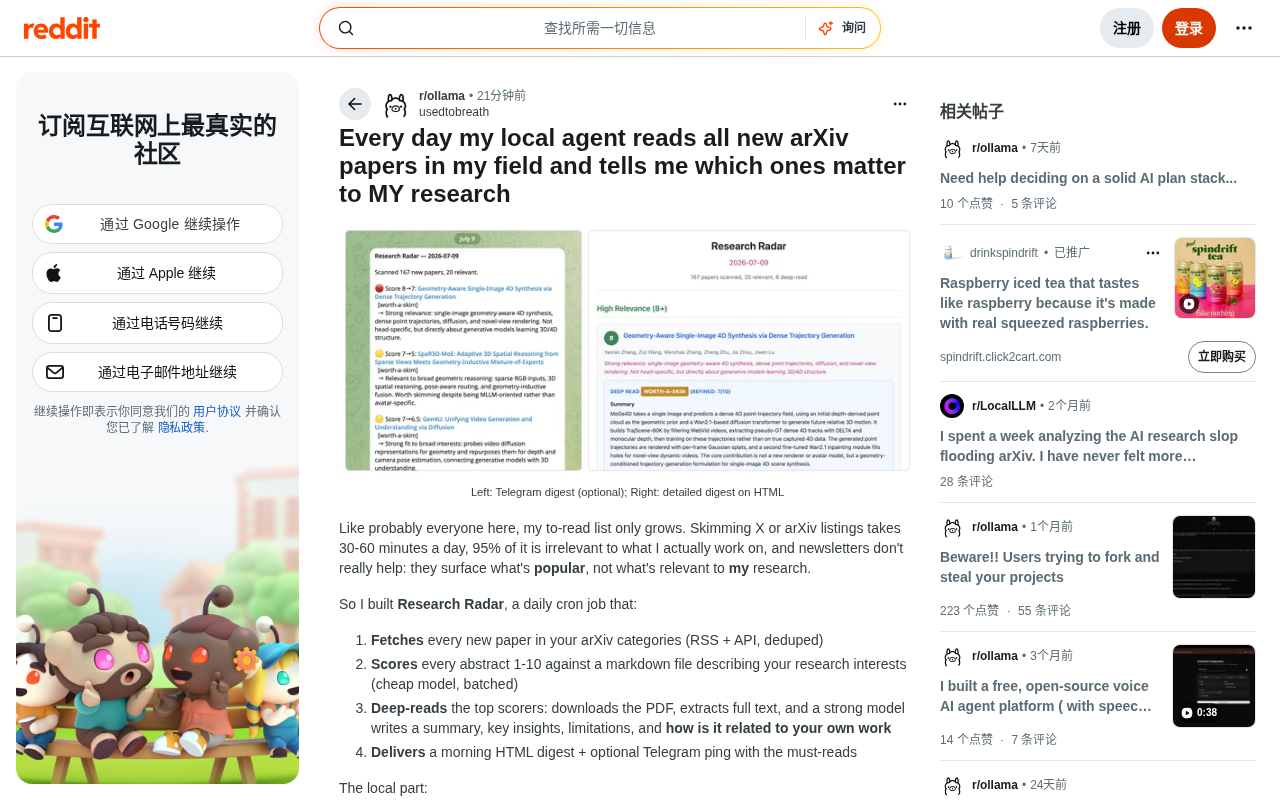
A Four-Step Pipeline: From Fetching to Deep Reading
The core of Research Radar is a clear automated pipeline that breaks the "needle in a haystack" process into four controllable steps.
1. Full Fetch and Deduplication
The system fetches all new papers under the arXiv categories you follow, via both RSS and API, and automatically deduplicates them. RSS (Really Simple Syndication) is a standardized XML-based data format that lets users subscribe to website content updates; arXiv provides an RSS feed for each subject category, making automated fetching of new papers possible. This step is deterministic, pure Python logic with no model inference involved, so it's efficient and runs reliably.
2. Batch Scoring with a Cheap Model
The system uses a lightweight small model to score each paper's abstract for relevance on a scale of 1-10. The scoring is based on a Markdown file the user writes themselves, describing their personal research interests. It processes about 10 abstracts per batch (roughly 18,000 tokens), quickly filtering out the vast majority of irrelevant content.
A token is the basic unit of text that a large language model processes, roughly corresponding to 3/4 of an English word or 1-2 Chinese characters. 18,000 tokens is about the text volume of a collection of standard academic paper abstracts, and a lightweight model can process it in batches quickly.
3. Deep Reading with a Powerful Model
For the top 5-10 highest-scoring papers, the system downloads the PDF, extracts the full text, and calls a more capable model to write a summary, distill key insights, point out limitations, and analyze its specific relevance to your own work. A single input can reach 40,000-70,000 tokens, requiring a model that supports long context.
"Long context" here is a key technical metric. A standard academic paper's full text typically contains 5,000 to 14,000 tokens, whereas early models (such as GPT-3) supported only a 4,096-token context window. Modern models like Claude 3.5 support 200K tokens and Gemini 1.5 Pro reaches 1 million tokens, making deep understanding of an entire paper truly possible.
4. Morning Push
The system generates an HTML-formatted morning digest and can optionally push "must-read" alerts via Telegram. On the left is Telegram's concise summary, on the right a more detailed HTML report—the two formats accommodate different scenarios.
Fully Local: Your Data Never Leaves Your Machine
The feature that most appeals to the developer community is its local-first design. Inference runs through a lightweight backend abstraction layer, supporting the standard OpenAI-compatible HTTP interface by default.
Simply point it at a locally running Ollama, vLLM, LM Studio, or llama.cpp server (e.g., base_url: http://localhost:11434/v1) to achieve fully offline, zero-cost operation with no data ever leaving your machine.
These four local inference backends each have their strengths: Ollama is known for its clean CLI and automatic model management, ideal for individual developers to get started quickly; vLLM, developed at UC Berkeley, focuses on server-side throughput optimization, suitable for scenarios requiring concurrent processing; LM Studio provides a graphical interface, ideal for users unfamiliar with the command line; llama.cpp, implemented in C++, has the lowest hardware requirements and can even run quantized small models on an ordinary laptop CPU. Notably, all four implement the OpenAI API-compatible HTTP interface standard, allowing the same codebase to switch backends seamlessly.
Even more flexibly, different stages can mix and match different backends: for example, using a local small model for batch scoring and a more powerful model for deep reading. The author also mentions that an alternative approach is to use the CLI subscription quota of Claude/Codex, which likewise requires no additional API key. Interestingly, only the scoring and deep-reading stages call models—fetching, deduplication, PDF extraction, and rendering are all deterministic Python code that incur no inference costs.
A Universal Architecture: One Markdown File to Reuse Across Fields
Research Radar's code contains no domain-specific hardcoded logic. Users only need to edit a Markdown config file describing their research interests, and the same pipeline works for machine learning, physics, biology, economics, or any other discipline.
The author admits this open-source version was generalized from his personal setup, and aside from his own field he hasn't deeply tested other disciplines—so he warmly welcomes community feedback and GitHub issues. The repository also provides benchmark data covering token usage, cost, latency, and quality ratings across different models, making it easy for users to assess the resources needed for local deployment.
The Key Challenge: The Sensitivity of Score Calibration
The author specifically pointed out a technical difficulty—score calibration. The model must be able to give plenty of low scores like "irrelevant, 3/10," rather than showing a tendency toward uniformly high scores. Once a model scores every paper highly, the entire filtering system becomes meaningless.
This problem is known in the AI field as sycophancy bias—large language models naturally tend to give positive, high-scoring evaluations rather than strictly distinguishing degrees of relevance. This bias is especially pronounced in small models, whose instruction-following capability is relatively weak, making it hard for them to strictly enforce the implicit requirement to "output plenty of low scores." Solutions typically include: providing specific scoring examples (few-shot examples) in the prompt, clearly defining the criteria for each score range, or forcing the score distribution to meet specific statistical characteristics in the system prompt.
This is also a core consideration in local model selection. The author says he hasn't yet completed systematic benchmarking of local models and looks forward to community recommendations of models suitable for the scoring stage—a task that demands both low cost and accurate judgment, placing high demands on a small model's instruction-following ability.
Conclusion
Research Radar represents a rising class of practical AI tools: rather than pursuing grand general-purpose capabilities, it uses large language models to solve specific, high-frequency pain points for researchers. It breaks "reading papers" down into an automatable pipeline while balancing privacy and cost control through local deployment.
For researchers drowning in the daily arXiv feed, this self-hostable, customizable, and mostly free tool may be exactly the pragmatic starting point for moving from "information overload" to "precise reading." The project is open source on GitHub (ramazan793/research-radar), and interested readers can deploy and try it themselves.
Key Takeaways
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.