MAGIC Attribution Method's Reliability Questioned: Accurate in Short Windows, Fails Globally

MAGIC attribution is reliable in short windows, but global attribution fails due to numerical overflow and low correlation.
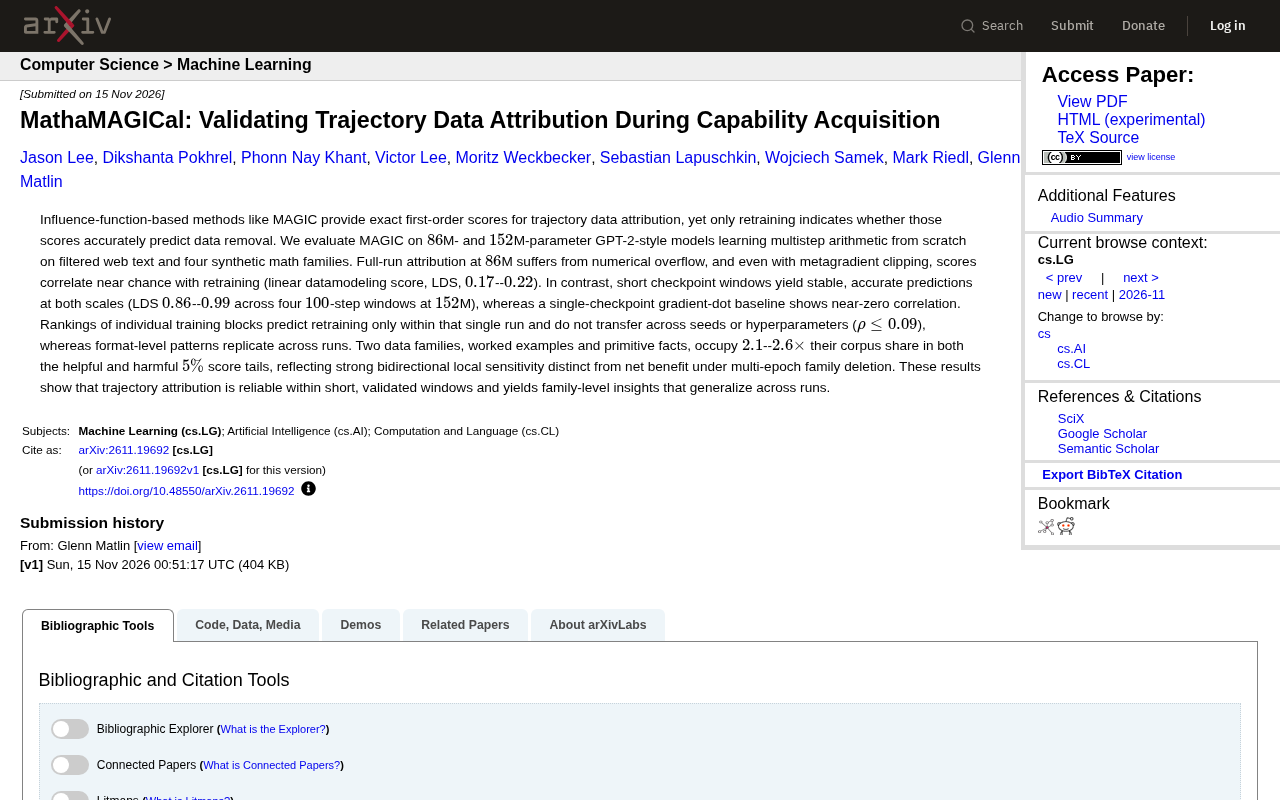
This paper systematically tests the reliability of the influence function method MAGIC when a language model learns multi-step arithmetic. On the 86M model, full-trajectory attribution overflows numerically, and even after metagradient clipping correlation with retraining is only 0.17–0.22, near random. In 100-step short checkpoint windows on the 152M model, LDS reaches 0.86–0.99 with high predictive accuracy, while the single-checkpoint gradient-dot baseline is near zero. Individual training-block attribution rankings do not transfer across seeds or hyperparameters (ρ≤0.09), but format-level patterns reproduce. Worked examples and primitive facts are overrepresented in both beneficial and harmful tails, showing two-way local sensitivity. The study recommends limiting attribution to short windows and focusing on family-level patterns.
Introduction
When training large language models, we often want to know: which training data contributes most to the model learning a certain capability? Influence function methods, such as MAGIC, promise to provide precise first-order attribution scores. However, can these scores really predict the effect of removing data? A study titled "MathaMAGICal: Validating Trajectory Data Attribution During Capability Acquisition" systematically tests the reliability of MAGIC through rigorous retraining experiments.
Influence functions originate from robust statistics and are used to estimate the first-order approximate effect of removing or perturbing a single training sample on model parameters or loss. In deep learning, common computation methods include TracIn based on gradient dot products, the Koh & Liang method based on Hessian inverse-vector products, and MAGIC (Model-Agnostic Gradient-based Influence Calculation), a meta-gradient method for long training trajectories. MAGIC attributes by accumulating gradient information along the training trajectory, and in theory can capture the cumulative effect of samples across multiple checkpoints. However, influence functions are essentially local linear approximations; when the training trajectory is long and parameters change drastically, higher-order terms and numerical instability may cause attribution scores to deviate from the true retraining effect. Therefore, validating influence functions usually requires correlation comparison with benchmarks such as "leave-one-out retraining" or "retraining after data deletion," commonly using Linear Datamodeling Score (LDS) or Spearman rank correlation as metrics.
Experimental Setup: Learning Multi-Step Arithmetic from Scratch
The research team evaluated MAGIC on 86M and 152M parameter GPT-2-style models. The training data included filtered web text and four synthetic math families, with the task of learning multi-step arithmetic from scratch. This setup simulates the process by which a model acquires mathematical reasoning ability and provides a controlled test environment for attribution methods.
Numerical Difficulties and Low Correlation in Global Attribution
When running full attribution on the 86M model, numerical overflow occurred. Even with metagradient clipping, the correlation between attribution scores and retraining results remained close to random—the Linear Datamodeling Score (LDS) was only 0.17–0.22. This means that attribution scores computed over long trajectories can hardly predict the true effect of data removal.
Metagradient clipping is an engineering technique used to stabilize influence function computation. In methods such as MAGIC, attribution scores are obtained by accumulating metagradients along the training trajectory, and the metagradient itself involves mixed partial derivatives of the validation loss with respect to training samples. Accumulation over long trajectories easily leads to gradient explosion or numerical overflow, manifesting as NaN or extremely large values in the scores. Clipping limits the norm of each metagradient vector to within a threshold, or truncates the accumulated scores, to mitigate overflow. But clipping introduces bias: it changes the direction or scale of the original gradients and may cause attribution scores to systematically deviate from the true influence. In addition, gradient directions at different checkpoints along a long trajectory may cancel each other out, reducing the signal-to-noise ratio of the final scores, which explains why correlation remains close to random even after clipping.
High-Accuracy Prediction Within Short Windows
In sharp contrast to the poor performance of global attribution, short checkpoint windows show stable and accurate predictive ability. On the 152M model, within four 100-step windows, LDS reached 0.86–0.99. This indicates that within short time windows, MAGIC scores can reliably reflect the effect of data removal. The single-checkpoint gradient-dot baseline, by contrast, showed near-zero correlation, further highlighting the advantage of the window method.
The Linear Datamodeling Score (LDS) is a standard metric for evaluating the quality of data attribution. Its procedure is: randomly sample several data subsets, retrain the model on each subset and record the target metric (such as validation loss), while using attribution scores to linearly predict the metric change on that subset; then compute the correlation coefficient (usually Pearson or Spearman) between predicted and actual values. The higher the LDS, the better the attribution scores can linearly explain the effect of removing data subsets. An LDS close to 1 indicates that attribution almost perfectly predicts retraining results, while close to 0 is no better than random guessing. The advantage of this metric is that it directly uses "retraining" as the gold standard, avoiding circular reasoning that only compares correlations among attribution scores. In this paper, short-window LDS reaching 0.86–0.99 means that within 100-step windows, attribution scores have high predictive power for the effect of data removal.
Individual Rankings Do Not Transfer, Format Patterns Generalize
The study also examined the transferability of attribution scores. Rankings for individual training blocks could predict retraining effects only within that run and could not transfer across random seeds or hyperparameters (Spearman correlation ρ≤0.09). However, format-level patterns could be reproduced across different runs. This indicates that fine-grained individual attribution is highly dependent on specific run conditions, while coarse-grained data category patterns have cross-run stability.
The Spearman rank correlation coefficient (ρ) measures the consistency between two sets of rankings, ranging from -1 to 1, with 0 indicating no relation. In attribution transferability evaluation, researchers typically compute ρ separately between attribution score rankings and retraining effect rankings for the same data block under different random seeds or hyperparameters. If ρ is very low (such as ≤0.09), it means that the ordering of "which training block is most important" in one run can hardly generalize to another run—that is, individual attribution is highly dependent on the specific initialization, data order, and optimization trajectory. In contrast, aggregate patterns at the format level (such as "step-by-step worked examples" versus "primitive facts") remain consistent across runs, because such coarse-grained categories reflect stable statistical regularities in the data distribution rather than accidental gradient interactions in a specific run. This distinction is crucial for practitioners: individual rankings do not transfer, but category-level insights can be reused across runs.
Distinguishing Two-Way Local Sensitivity from Net Benefit
An interesting finding is that two data families—worked examples and primitive facts—each occupied 2.1–2.6 times their corpus share in both the beneficial and harmful 5% score tails. This reflects strong two-way local sensitivity: these data can be attributed as either highly beneficial or highly harmful depending on context. This sensitivity is a different concept from net benefit under multi-round family deletion, reminding us to be cautious when interpreting attribution scores.
Implications and Limitations
This study sends a clear message: trajectory attribution methods are reliable within short, validated windows and can provide family-level insights that generalize across runs. But if used for global attribution over full-length training trajectories, they may fail due to numerical problems and low correlation. For practitioners, this means attribution analysis should be limited to short windows and should focus on data-family-level patterns rather than individual sample rankings.
It should be noted that this study only targets GPT-2-style models and synthetic math tasks, and whether the conclusions generalize to larger models and more complex tasks remains to be verified. In addition, MAGIC's numerical overflow problem also suggests that influence function methods still need to address stability challenges before practical deployment.
Conclusion
Influence function methods such as MAGIC are not a panacea. They can provide accurate attribution signals within short windows, but the reliability of global attribution is questionable. Researchers should make full use of short-window validation and family-level analysis, while being wary of the limitations of cross-run transfer of individual rankings. This study sets a benchmark for rigorous evaluation of data attribution and points out directions for future improvement.
One-line Summary
MAGIC attribution is reliable within short windows, but global attribution fails due to numerical overflow and low correlation.
Paragraph Summary
This paper systematically tests the reliability of the influence function method MAGIC when a language model learns multi-step arithmetic. On the 86M model, attribution over the full-length trajectory suffers from numerical overflow; even after metagradient clipping, correlation with retraining is only 0.17–0.22, close to random. In contrast, within 100-step short checkpoint windows on the 152M model, LDS reaches 0.86–0.99, showing high predictive accuracy, while the single-checkpoint gradient-dot baseline has near-zero correlation. Attribution rankings for individual training blocks do not transfer across random seeds or hyperparameters (ρ≤0.09), but format-level patterns are reproducible. The two data families worked examples and primitive facts are overrepresented in both beneficial and harmful tails, showing two-way local sensitivity. The study recommends limiting attribution to short windows and focusing on family-level patterns.
Related articles

The Birds of GTA 6: Audubon Explores Vice City's Wild Ecology
Audubon magazine publishes a GTA 6 bird field guide, comparing Vice City and Leonida's virtual ecology with real Florida avian communities. The article sparked discussion on Hacker News about ecological accuracy in game environment design and educational potential.

Major Tech Outages Are Becoming Routine: The Next Disruption Is Already on Its Way
FAA ground stop, multi-day Outlook outage, and JPMorgan failure strike in succession. DNI Jay Clayton warns more tech disruptions are coming as systemic risks mount.
@ai-sdk/langchain 2.0.344 Released: Another Update to the AI SDK and LangChain Adapter Layer
@ai-sdk/langchain releases patch version 2.0.344, syncing with ai@6.0.336. This article examines the adapter package's role in the AI SDK and LangChain ecosystems, its version maintenance cadence, and practical impact on developers.