Microsoft Email Service Suffers Massive Outage: July Fix Patch Introduced Software Defect
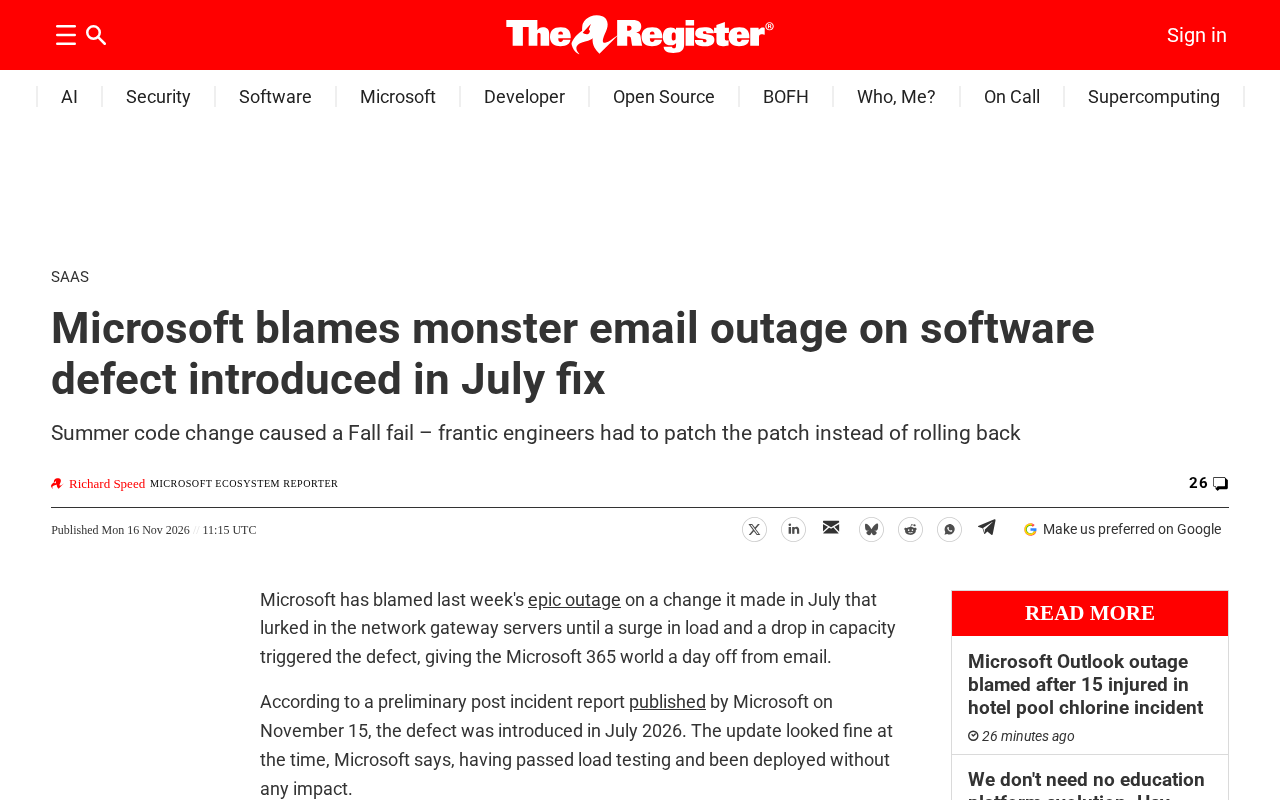
Microsoft email service suffered a massive outage due to a defect introduced in a July fix patch, highlighting cloud service change management challenges.
Microsoft's email service recently experienced a massive outage described by the Hacker News community as a "monster." Microsoft confirmed the root cause was a software defect introduced in a July fix patch, a typical "fix introducing new problems" pattern. The incident exposed change management and regression testing challenges in large cloud services: high update frequency and complex systems mean defects can bypass testing, enter production, and be amplified at scale. For users, it reminds them not to rely entirely on a single cloud service for critical business, but to have contingency plans and maintain data portability; for providers, it highlights the need for canary releases, automated rollback, and stricter testing. Community discussion focused on engineering culture, with future attention on whether Microsoft will publish a detailed postmortem and adjust its release strategy.
Microsoft recently experienced a severe email service outage, which the company attributed to a software defect introduced in a July fix patch. This incident has once again raised industry concerns about the stability of large-scale cloud services.
Incident Review: Massive Outage of Email Service
According to discussions in the Hacker News community, Microsoft's email service experienced a massive outage described as a "monster." Although the original report did not disclose the specific number of affected users or duration, the term "monster" suggests the severity and widespread impact of the failure. Microsoft subsequently confirmed that the root cause was a software defect.
Such failures typically affect enterprise email, Exchange Online, and related services, causing direct impact on enterprise users who rely on email communication. The incident received 19 upvotes and 13 comments on Hacker News, indicating that the technical community remains highly attentive to such infrastructure failures.
Root Cause Analysis: The Fix Patch Introduced New Problems
Microsoft blamed the failure on a "software defect introduced in a July fix." This means an update originally intended to fix a problem instead became the source of a new failure. This pattern of "fix introducing defect" is not uncommon in complex software systems, but at cloud service scale, its impact is dramatically amplified.
From an engineering perspective, this exposes challenges in change management and regression testing. Large cloud service providers deploy numerous updates daily, and how to ensure existing functionality is not broken while iterating rapidly is a persistent challenge. This incident shows that even giants like Microsoft can still have oversights in patch quality control.
Change Management is a set of process specifications in IT operations and software engineering aimed at ensuring that any modification to the production environment is evaluated, approved, tested, and documented. In cloud service scenarios, change management is particularly critical because a single deployment can affect millions of users simultaneously. Typical practices include change classification (e.g., treating emergency fixes differently from routine updates), change window control (avoiding business peak hours), and post-change monitoring and rollback plans. In this Microsoft incident, a July fix patch entered the production environment and caused a massive outage, indicating that the evaluation or testing phase of that change failed to fully cover potential risks. For hyperscale cloud service providers, change management is not just a process issue but also a technical one—automated tools are needed to enforce approval, validation, and rollback rather than relying on manual judgment.
Regression Testing refers to re-running existing test cases after software modifications to ensure that new changes have not broken existing functionality. It is the core means of preventing "fixes introducing new defects." However, in large cloud services, regression testing faces two major challenges: first, the system has numerous components and complex dependencies, making complete regression testing costly and time-consuming; second, real traffic patterns in the production environment are difficult to fully reproduce in the test environment, and some defects only surface under specific load or configuration combinations. Therefore, the industry typically combines unit testing, integration testing, contract testing, and online canary release to intercept problems at multiple layers. The fact that Microsoft's patch defect bypassed testing and entered production may mean there are blind spots in test coverage, or that the conditions triggering the defect were not simulated in the test environment.
Implications for Cloud Service Reliability
This outage incident serves as a wake-up call for both cloud service users and providers. For users, it reminds us that critical business functions such as email should not be entirely dependent on a single cloud service; having contingency plans and maintaining data portability remain important. For providers, it highlights the necessity of canary releases, automated rollback, and stricter testing processes.
Although cloud services generally have high reliability, such incidents demonstrate that the chain reaction of software defects can affect a large number of users in a short time. Microsoft's rapid attribution and fix are commendable, but how to prevent the cycle of "fixes introducing new defects" through process improvements remains an area requiring sustained investment.
Canary Release is a release strategy that pushes a new version to a small subset of users or servers first, observes its performance, and then gradually expands the scope. Its name originates from the典故 of "canaries warning of toxic gas in mines." In cloud services, canary releases are typically tied to automated monitoring metrics: if error rates, latency, or resource usage exceed preset thresholds, the system automatically pauses or rolls back the release. Canary releases can significantly reduce the impact scope of "fixes introducing new defects," but they are not a panacea—if a defect is only triggered in a specific region, specific tenant type, or specific time window, a small-scale canary may not detect it in time. Therefore, canary strategies require carefully designed traffic splitting dimensions and observation duration. If this Microsoft email service outage involved a global defect, it suggests either that the problem could not be reproduced during the canary phase, or that the canary step was skipped or shortened in the release process.
Automated Rollback refers to the process by which the system automatically restores the service to the last known good version when anomalies are detected after deployment. Together with canary releases and health checks, it forms the "safe release" loop of modern cloud services. The key to automated rollback lies in rapid detection—relying on fine-grained monitoring metrics (such as error rates, timeout rates, queue backlog) and clear rollback trigger conditions. Rollback itself can also introduce risks, such as database schema changes causing incompatibility with older versions, so supporting backward-compatible design and data migration strategies are needed. For stateful services like email, rollback also needs to consider the idempotency and consistency of already-processed messages. Leading cloud service providers compress rollback time targets (RTO) to the minute level to minimize user impact. Microsoft's repair speed in this incident is commendable, but what is more worth asking is: whether automated rollback was triggered at the first opportunity, and how long the trigger delay was.
Community Reaction and Follow-up Concerns
The discussion on Hacker News reflects the typical attitude of the technical community toward infrastructure failures: attention to both the technical details of the failure itself and the engineering culture issues behind it. Although 13 comments are not many, they are enough to show that this matter has prompted reflection among developers.
What is worth watching in the future is whether Microsoft will publish a more detailed postmortem report and whether it will adjust its update release strategy. For enterprise IT managers, this incident is also a reminder: while relying on cloud services, it is necessary to establish robust monitoring and disaster recovery mechanisms.
One-line Summary
Microsoft's email service suffered a massive outage due to a defect introduced in a July fix patch, highlighting cloud service change management challenges.
Paragraph Summary
Microsoft's email service recently experienced a massive outage described by the Hacker News community as a "monster." Microsoft confirmed that the root cause was a software defect introduced in a July fix patch, a typical pattern of "fix introducing new problems." The incident exposed the change management and regression testing challenges faced by large cloud services during rapid iteration: high update frequency and complex systems mean defects can bypass testing, enter production, and be amplified at scale. For users, this is a reminder not to rely entirely on a single cloud service for critical business, but to have contingency plans and maintain data portability; for providers, it highlights the necessity of canary releases, automated rollback, and stricter testing processes. Technical community discussions focused on engineering culture issues, and future attention will be on whether Microsoft publishes a detailed postmortem and adjusts its release strategy.
Related articles

Why Git Is Essential in the AI Era: From Version Control to Agent Collaboration
What's the difference between Git and GitHub? How do you manage changes with Issues, branches, and Pull Requests after AI Agents write code? Based on NetworkChuck's Git tutorial, this article walks through the complete flow from git init to conflict resolution and analyzes why version control has become an essential skill in the AI era.
OpenAI 6.2 Astra Hands-On Review Gone Wrong: Impressive Benchmarks, But Developers Say It's Unusable
OpenAI 6.2 Astra leads benchmarks at lower cost, but early testers report frequent stalls in long tasks, unparseable output, and uncontrolled resource management. We examine the gap between real-world experience and official data, and what it means for developer adoption.
GTA VI Coffee System Details Revealed: Hot Coffee Can Be Splashed on People?
Vergecast podcast reveals GTA VI's coffee system: players can brew in apartments, buy from vending machines, order in restaurants, and even splash hot coffee on others. This detailed recreation of daily interactions continues Red Dead Redemption 2's immersive design and sparks discussion on game detail versus gameplay balance.