Mistral Models Go to Space: AI Compute Moves from Ground to Orbit

Mistral models enter space orbit, extending AI inference from data centers to low Earth orbit and opening spatial competition in AI infrastructure.
Mistral AI announced that its models have entered space orbit, participating in the first AI satellite constellation project built by Orbitworks and Loft Orbital, with NVIDIA AI Infrastructure providing compute support. The article analyzes the motivations and impact of this event: the core value of in-orbit inference lies in reducing dependence on ground downlinks and compressing data processing from hours to minutes, making it suitable for time-sensitive scenarios such as disaster monitoring and maritime identification. At the engineering level, it faces three major challenges: power and heat dissipation, the radiation environment, and model updates, requiring coordinated optimization between the model side and the chip side. Mistral's efficiency-oriented approach naturally aligns with in-orbit power constraints. In the short term, orbital compute is a supplementary layer for edge inference, but its strategic significance lies in expanding AI infrastructure competition from ground scale to the dimension of spatial coverage.
AI models are breaking through the physical boundaries of the ground. Mistral AI recently announced on social media that its models have entered space orbit, participating in the first AI satellite constellation project built by Orbitworks and Loft Orbital, with NVIDIA AI Infrastructure also providing support for the project.
This news is brief, but it carries significant implications. It means that large model inference is moving from data centers to low Earth orbit, and the competitive dimensions of AI infrastructure may change as a result.
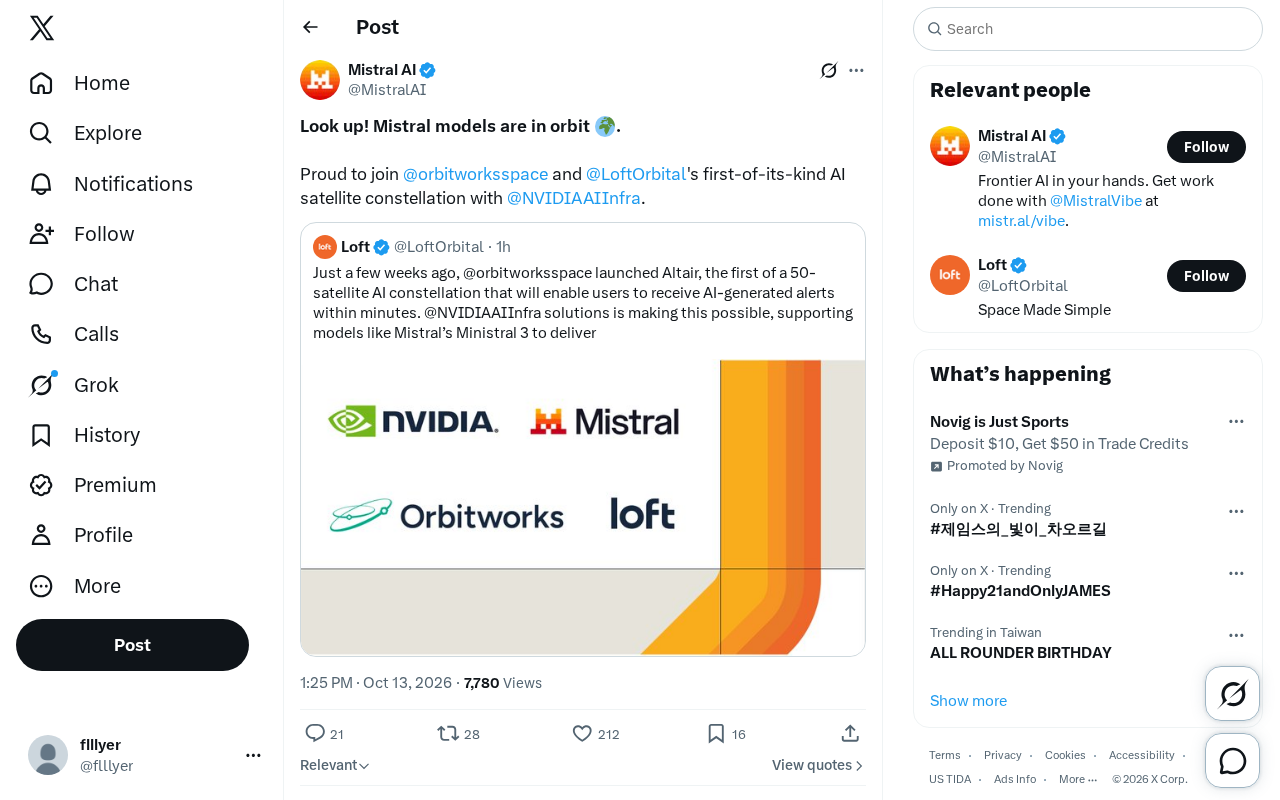
The Core Event: Who Is Doing What
According to Mistral AI's official tweet, the project involves three parties:
- Mistral AI: Provides large model capabilities, responsible for the model side of in-orbit inference
- Orbitworks: One of the lead promoters, positioned as a builder of AI satellite constellations
- Loft Orbital: Satellite platform and in-orbit infrastructure provider, responsible for sending payloads into orbit and operating them
- NVIDIA AI Infrastructure: Provides AI compute infrastructure support for the project
The tweet uses the phrase "first-of-its-kind AI satellite constellation," indicating that this is not a single experimental satellite, but a plan aimed at constellation-scale deployment.
Why Do AI Models Need to Go to Space
The most direct driving force for deploying large models on satellites is reducing dependence on ground links.
Traditional remote sensing satellites operate in the following mode: capture — downlink raw data — ground station processing — generate results. This chain is limited by downlink bandwidth and ground station coverage windows, with data latency ranging from several hours to several days. If models can complete inference in orbit, satellites only need to downlink conclusions rather than raw imagery, and both bandwidth requirements and response times will be greatly compressed.
For time-sensitive scenarios such as disaster monitoring, maritime identification, and agricultural yield estimation, the difference between minute-level and hour-level response may directly determine application value. The combination of Orbitworks and Loft Orbital covers both ends — "AI capability" and "in-orbit platform" — with the former responsible for onboard intelligence and the latter responsible for sending that intelligence into space and keeping it running.
NVIDIA's involvement points to the compute layer: in-orbit inference requires low-power, high-efficiency AI chips, which is precisely where NVIDIA AI Infrastructure excels.
Engineering Challenges of In-Orbit Inference
The difficulty of putting models into space goes far beyond "uploading the weight files."
Power consumption and heat dissipation are the primary constraints. A satellite's electricity comes from solar panels, and heat dissipation relies on radiation, with power budgets typically in the range of hundreds of watts. This means that models capable of going into space must undergo quantization, pruning, or distillation, and their parameter counts are not on the same scale as ground versions.
The radiation environment affects chip reliability. Cosmic rays can cause single-event upsets, and commercial GPUs cannot be directly adopted as-is; radiation-hardened designs or redundant verification mechanisms are needed.
In-orbit updates are also a problem. Model iteration speed is far faster than satellite lifespan, and how to complete hot updates of models under limited uplink bandwidth is a question that engineering deployment must answer.
Mistral's models are known for efficiency, and its Mixtral series adopts a sparse mixture-of-experts architecture, offering clear advantages in inference cost. This efficiency-oriented technical approach naturally aligns with the power constraints of in-orbit deployment.
Single Event Upset (SEU) is a foundational concept in the field of aerospace electronics, referring to the phenomenon in which high-energy cosmic rays or solar protons strike sensitive nodes in a chip, causing non-destructive flipping of the state of a memory cell or logic gate. It does not burn out the hardware, but it can change a single bit in a register from 0 to 1, thereby causing instruction errors or deviations in computation results. For ground-based commercial GPUs, the probability of such errors is extremely low; but in the orbital radiation environment, a satellite may encounter dozens of flips per day. Traditional aerospace chips use radiation-hardened processes, at the cost of older manufacturing nodes and weak compute power, creating a contradiction with the performance requirements of AI chips. Compromise solutions usually include: triple modular redundancy (TMR) voting, ECC memory verification, periodic state snapshots and rollback, and system-level fault detection and recovery mechanisms. For in-orbit large model inference, how to find a balance among compute, power, and fault tolerance is a more complex systems engineering problem than simply compressing the model.
Impact on the AI Infrastructure Landscape
The significance of this project goes beyond a single launch.
Over the past few years, AI compute competition has been concentrated in data centers: who has more GPUs, whose cluster is larger, who has lower electricity costs. The addition of orbital computing expands the competitive dimension from "ground scale" to "spatial coverage."
For scenarios that need to provide low-latency AI services globally — such as ocean shipping, polar research, and communications in remote areas — orbital inference nodes have a coverage advantage that ground data centers cannot replace.
Of course, in the short term, orbital compute cannot replace ground data centers. Its compute scale, cost structure, and operational complexity all determine that it is more suitable as a supplementary layer for edge inference, rather than a primary training facility.
A more realistic observation point is this: when core players in the ground AI ecosystem such as Mistral and NVIDIA begin to participate in orbital projects, it shows that in-orbit AI has moved from proof of concept into the engineering deployment stage. What deserves attention next is the constellation scale, per-satellite compute metrics, and feedback from actual application scenarios.
The boundary of AI compute is extending from the Earth's surface to low Earth orbit.
Edge inference refers to deploying models close to where data is generated to perform computation, rather than transmitting data back to a central cloud for processing. In ground scenarios, edge inference usually runs on base stations, factory gateways, or vehicular compute units, and its value lies in reducing transmission latency, cutting bandwidth consumption, and avoiding data privacy risks. Orbital inference can be seen as an extreme form of edge inference: the satellite itself is the data source, the inference node coincides with the collection node, and physical proximity is pushed to the limit. But unlike ground edge devices, orbital nodes face constraints such as limited power, difficult heat dissipation, and scarce maintenance windows, and the compute power of a single node is usually far lower than that of ground servers. Therefore, orbital inference is better suited to lightweight tasks such as preprocessing, filtering, and preliminary judgment, leaving truly high-precision analysis to be completed on the ground. This layered architecture of "space-based preliminary screening + ground-based precise analysis" is consistent with the multi-level coordination logic of ground edge computing, except that the physical boundary of each layer extends from the machine room to beyond the atmosphere.
One-line Summary
Mistral models enter space orbit, extending AI inference from data centers to low Earth orbit and opening a spatial competition in AI infrastructure.
Paragraph Summary
Mistral AI announced that its models have entered space orbit, participating in the first AI satellite constellation project built by Orbitworks and Loft Orbital, with NVIDIA AI Infrastructure providing compute support. The article analyzes the motivations and impact of this event: the core value of in-orbit inference lies in reducing dependence on ground downlinks and compressing data processing from hours to minutes, making it suitable for time-sensitive scenarios such as disaster monitoring and maritime identification. At the engineering level, it faces three major challenges: power and heat dissipation, the radiation environment, and model updates, requiring coordinated optimization between the model side and the chip side. Mistral's efficiency-oriented approach naturally aligns with in-orbit power constraints. In the short term, orbital compute is a supplementary layer for edge inference, but its strategic significance lies in expanding AI infrastructure competition from ground scale to the dimension of spatial coverage.
Related articles

Should U.S. College Fraternities Be Banned? A Researcher's Incisive Observations
Why not just ban U.S. college fraternities? A researcher finds the key resistance comes from decision-makers' own fraternity identities and schools' "willful ignorance."

Microsoft Discovery: Accelerating Scientific Discovery with AI Agents
Microsoft's Discovery platform runs specialized AI agents to help researchers screen and prioritize the most promising compounds and experimental paths, reducing experiments and accelerating scientific discovery.

Cambridge Heavy Industries Secretly Develops Desktop-Scale Nuclear Fusion Device
Cambridge Heavy Industries is secretly developing a desktop-scale laser-driven nuclear fusion device, targeting the equipment supply market for fusion power plants. This article analyzes its miniaturization technology path, commercialization logic, and unique positioning in the fusion startup wave.