Mistral Opens Up Trillion-Parameter Model, Microsoft Discloses $10B OpenAI Revenue

Mistral opens trillion-param MoE weights, Tencent previews vision model, Microsoft discloses OpenAI revenue, Claude mode to be removed.
This roundup covers six AI developments: Mistral opens weights for trillion-parameter MoE model Large 4, supporting image-text input and focused on coding and cybersecurity, but commercial use requires authorization; Tencent previews i4 and Hi4 Flash, adding visual understanding for the first time; Microsoft's earnings disclose about $10B in quarterly revenue from its OpenAI commercial arrangement, including revenue sharing but without breaking out cloud services; Claude Opus 4.8 fast mode will be removed on November 30, requiring migration to Opus 5.5; OpenAI updates its Model Spec and acknowledges the model does not yet fully meet it; NVIDIA open-sources Canary 3.5 Transcribe speech model with speaker diarization, requiring about 120GB VRAM for BF16 deployment. The article notes that many items are plans or previews, and open-source licensing, API compatibility, and hardware costs are variables developers need to check in advance.
Another Heavyweight Joins the Open Source Camp: Mistral Large 4 Opens Its Weights
On October 29, Mistral released a weight model called Large 4 (transliterated as "Maestro" in source material). It is a trillion-parameter-level mixture-of-experts (MoE) architecture model, and the company claims it activates only a portion of the expert networks when processing each token, balancing scale and efficiency. The model supports image-and-text input with text output, was trained from scratch on European infrastructure, focuses on coding and cybersecurity scenarios, and bills itself as "the strongest open-weight model for programming"—though this judgment comes from specific benchmarks, and developers still need to independently verify actual performance with their own coding tasks.
Note the licensing restrictions: the model uses a modified license, and enterprises need authorization before commercial use. So read the license terms carefully before downloading, then decide whether to self-deploy and fine-tune or choose a hosted service. Open weights do not equal unconditional commercial use—developers must pay attention to this red line.
Mixture of Experts (MoE) architecture: MoE is an architecture that splits a model into multiple "expert" subnetworks, where each token is computed by only a few experts selected by a routing mechanism. This allows the model's total parameter count to be extremely large, while the activated parameters and compute cost per inference are far lower than a dense model with the same total parameter count. Mistral Large 4's claimed trillion-parameter level relies on sparse activation to balance scale and inference cost. Note that "total parameters" and "parameters activated per inference" are two different concepts—the latter more directly determines inference memory and latency.
Open Weights: This means the parameter files of a trained model can be publicly downloaded, allowing developers to deploy, fine-tune, and even redistribute it themselves. It is not entirely equivalent to "open source"—training data, code, and training pipelines may not be public, and the license may impose commercial restrictions. That is why the article emphasizes that "open weights do not equal unconditional commercial use"; enterprises must check the license terms clause by clause before use.
Tencent Hunyuan Previews New Model: First Time Adding Visual Understanding
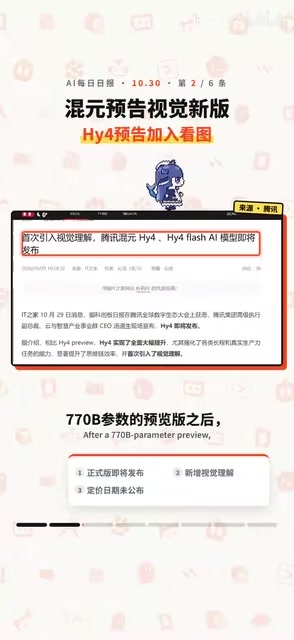
According to a report relayed by STAR Market Daily, Tencent previewed a new model, i4, at its developer conference. The company claims it strengthens long-horizon tasks and real-world productivity tasks and improves chain-of-thought efficiency. The so-called "first time adding visual understanding" is relative to the previous preview version and should not be overinterpreted to mean that none of Tencent's models ever had visual capabilities.
Also previewed at the same time was Hi4 Flash, focused on cost-effectiveness. The company says it will inherit visual and agent capabilities and follow a path of "designing models and products together with continuous iteration." However, neither report gave a specific release date, pricing method, or visual benchmark results. Currently, the capability improvements can only be relayed as official claims, and actual performance must wait for the official release to be verified.
OpenAI's Ledger in Microsoft's Earnings: About $10 Billion in Quarterly Revenue
On October 28, according to relevant financial media reports, Microsoft's earnings filing disclosed a set of figures: for the quarter ending September 30, Microsoft's commercial arrangement with OpenAI brought in about $10 billion in revenue, including revenue sharing. However, the filing did not break down how much came from revenue sharing versus cloud services, so this $10 billion cannot all be counted as cloud computing revenue.
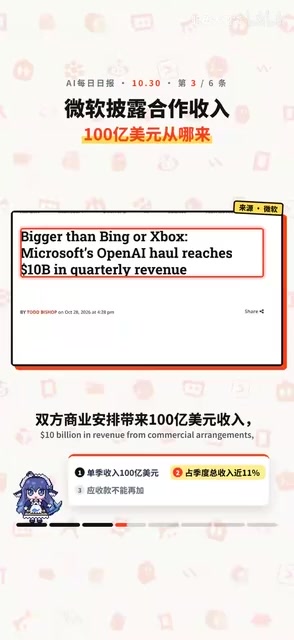
Another notable figure is receivables: $7.2 billion as of the end of September, up from $6 billion at the end of June. This is money from transactions that have occurred but have not yet been collected, and it cannot be counted again as new revenue. The filing also did not disclose the profit corresponding to these businesses, nor whether all receivables have been collected. When looking at this partnership's accounts, revenue, receivables, and business composition must be understood separately—the gaps in the filing are explicit uncertainties.
Claude Opus 4.8 Fast Mode to Be Removed on November 30
On September 30, the Cloud platform changelog published a deprecation schedule: starting November 30, requests targeting Claude Opus 4.8 fast mode will return errors. This means existing programs need to check model and speed parameters—not just whether the model name is spelled correctly. If the code still specifies this model and requests fast processing, it will receive an error. The official recommendation is to migrate to Claude Opus 5.5.
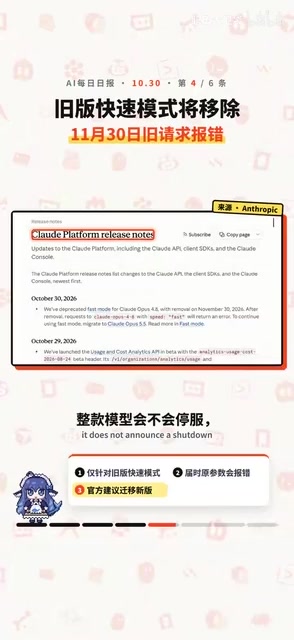
To clarify: what is being removed is "fast mode," not the entire model being discontinued. The official announcement did not declare that Opus 4.8 itself is being taken offline, and the original text does not further explain whether regular requests relying on that model will be affected. Refer to the official page for the latest information.
OpenAI Updates Model Spec: Acknowledges Model Does Not Yet Fully Meet It
On October 29, OpenAI published an article updating the Model Spec, which was reported by media on October 30. The company emphasizes that models should be faithful to human intent while reducing harm, maintaining honesty and transparency, and respecting human autonomy and care. Specific practices include understanding what users want to accomplish, making reasonable judgments based on context from the conversation and memory when instructions are incomplete, and strengthening explanations of the negative effects of actions.
One detail: the company removed previous stylistic guidance that was more structured and preachy, shifting to adapting to user preferences. But this does not mean all user requests must be followed—safety boundaries still exist. The company explicitly states that this spec describes the direction of effort, and the model does not yet fully comply with it. It can serve as a public yardstick for observing model behavior, not as proof that results have already been delivered.
Model Spec: This is a publicly released OpenAI document describing how models should understand instructions, handle conflicting priorities, and observe safety boundaries. It is similar to a "code of conduct" used to guide training and evaluation while providing the public with a yardstick for scrutinizing model behavior. The spec typically defines instruction hierarchy (e.g., platform rules take precedence over user instructions) and principles such as the trade-off between honesty and helpfulness. The company's acknowledgment that the model does not yet fully comply with the spec means this document is an aspirational goal rather than a guarantee of the status quo; readers should not treat it as proof that model capabilities have already been delivered.
NVIDIA Open-Sources Speech Transcription Model: Can Label Who Is Speaking
On October 28, NVIDIA released the open-source full-weight model Canary 3.5 Transcribe. The company says it can transcribe recordings up to one hour long, return timestamped results, support speaker diarization (labeling who is speaking), and switch output styles such as verbatim transcription, written cleanup, or translation as needed. The "30B" in the model name refers to a total parameter count of about 34 billion; combined with an audio encoder to process sound, it activates about 4.3 billion parameters per inference.
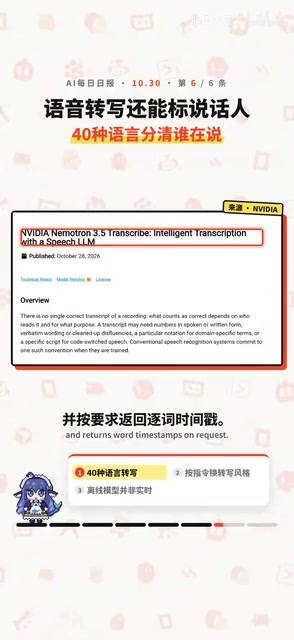
Hardware requirements need to be factored in: the company lists a BF16 deployment configuration requiring about 120 GB of VRAM. It also explicitly states this is an offline model, so one should not expect it to be "as fast as real time." Before using it for scenarios such as meeting subtitles, test noise, accents, speaker switching, and name recognition; final drafts should still be reviewed manually.
Speaker Diarization: This refers to the technology that automatically determines "who spoke when" in multi-speaker audio and labels the transcribed text by speaker segments. It is usually chained with automatic speech recognition (ASR): first detect voice activity, segment speaker turns, then transcribe separately and merge timestamps. Speaker diarization is especially critical for meeting minutes and interview transcription, but error rates rise noticeably when speakers overlap, accents differ greatly, or background noise is strong—hence the article's recommendation for manual review before finalizing.
Two Main Threads Across Six Items
These pieces of news can be grouped into two categories: one is open models and product previews, including Mistral Large 4, Tencent i4 and Hi4 Flash, and NVIDIA's speech model; the other is business and rule changes, including Microsoft's disclosed OpenAI-related revenue, the removal of Claude fast mode, and the OpenAI spec update. Many of these are "plans" or "previews" rather than official launches; refer to official pages for specifics. Commercial licensing of open models, API parameter compatibility, and hardware costs are the three variables developers most need to check in advance.
Related articles
 Tech Frontiers
Sherlock: An Open-Source Tool for Tracking Usernames Across Social Networks
Sherlock is an open-source Python tool that tracks social accounts across networks by username. This article covers its core features, why developers love it, typical use cases, and privacy compliance considerations.
 Tech Frontiers
GitHub Daily·Nov 07: Agent-Ready and Context Compression
GitHub Trending Nov 07: meta's agent-ready design system astryx, billion-context's 5x context compression, sherlock nearing 100k stars, plus local-first localthings and bare-metal GPU orchestration nvke.
 Tech Frontiers
Buoyant Open-Sources Kinference: An Inference Control Plane for vLLM on K8s
Buoyant open-sources Kinference, an inference control plane for vLLM on Kubernetes, with declarative routing, KV-cache-aware load balancing, and per-tenant metrics—claiming 95% lower median TTFT in official benchmarks.