Multi-Agent Collaboration Enables Autonomous Research in Quantum Spin Experiments

A multi-agent LLM system autonomously completes the research loop from question posing to verification in quantum spin experiments.
An arXiv study demonstrates how a multi-agent system based on large language models collaboratively completes a full research loop, with the research subject being a quantum spin ensemble in diamond. The core design is to have multiple LLM agents evaluate each other and possess the authority to halt or redirect research, in order to reduce overconfidence and hallucination risk of single models. Agents autonomously derive the minimum number of calibration settings required to predict microwave pulse responses and design experiments to distinguish competing predictions; upon detecting signal drift, they judge the results as uncertain and revise the measurement protocol without relaxing acceptance criteria. The study validates the potential of collaborative AI agents in controlled physical systems, but its applicable scope remains limited to scenarios with well-defined parameter spaces.
Artificial intelligence is evolving from an assistive tool into an active participant in the scientific research process. A study published on arXiv demonstrates how a multi-agent system based on large language models can collaboratively complete a full research loop—from posing questions and theoretical derivation to experimental verification—with the research subject being a quantum spin ensemble in diamond.
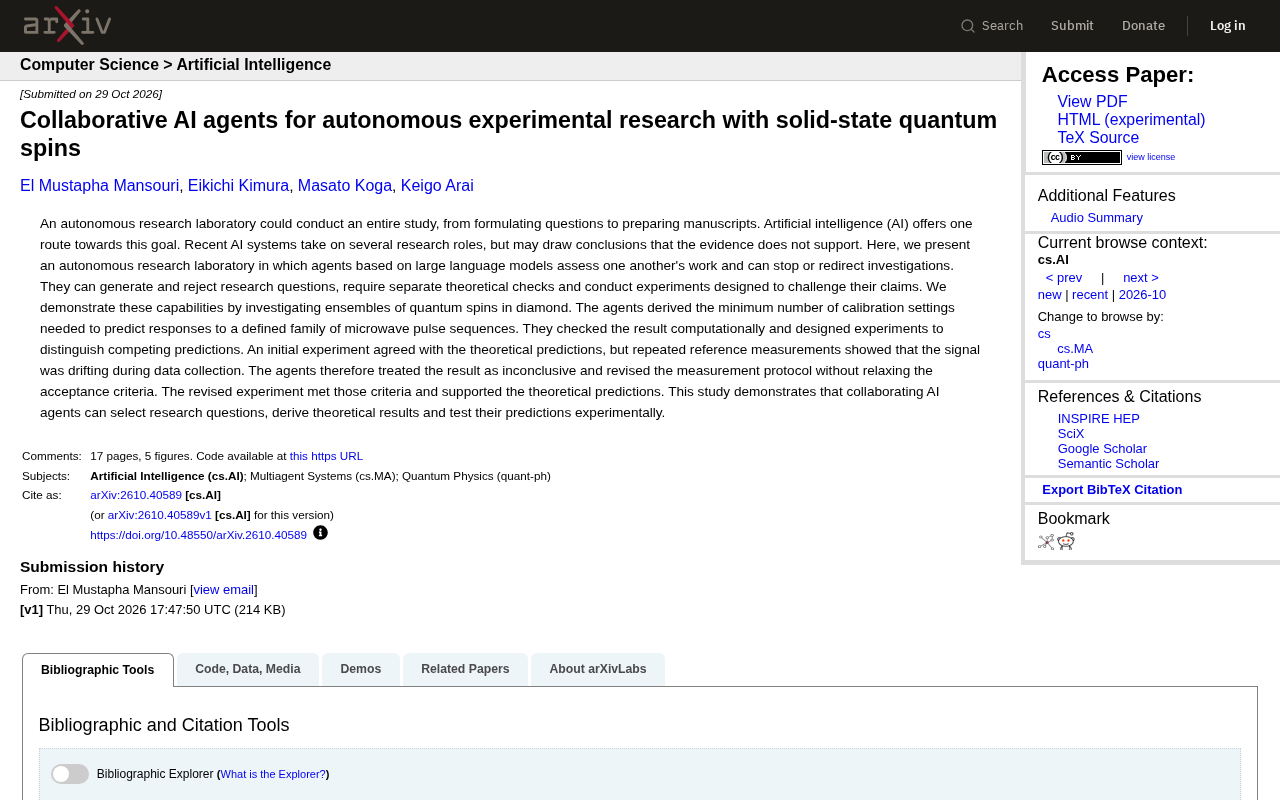
From "Going It Alone" to "Mutual Review": How Multi-Agent Systems Reduce AI Hallucination Risk
Most current AI research assistants complete tasks independently with a single model, making it easy to reach conclusions with insufficient evidence. The core design of this study is to have multiple LLM agents evaluate each other's work, with the authority to halt or redirect research.
This mechanism mimics the adversarial logic of peer review: agents can generate research questions and also veto them; they can demand independent theoretical verification and proactively design experiments aimed at challenging their own claims. According to the research team, when disagreements arise among agents, the system prioritizes theoretical cross-checking rather than hastily proceeding with experiments. This "self-doubt" design is precisely intended to address the overconfidence problem common in large language models.
Theoretical Derivation and Experimental Design in Quantum Spin Experiments
The study focuses on a quantum spin ensemble in diamond, where agents need to solve a specific problem: predicting the minimum number of calibration settings required for the response to a given family of microwave pulse sequences.
Agents first derive this minimum number, then verify the result through computational means, and design experimental protocols capable of distinguishing competing predictions. At first glance, this appears to be merely a parameter optimization problem, but the difficulty lies in the fact that agents must judge for themselves "what counts as sufficient theoretical grounding" rather than having human-preset standards.
Quantum spin ensemble refers to a collection of a large number of quantum particles with spin (such as nitrogen-vacancy centers in diamond). A single spin is a two-level quantum system that can be in a superposition state and is sensitive to microwave pulses; when a large number of spins are coupled to the same control field in the same manner, they collectively behave as a controllable macroscopic quantum system while still retaining quantum coherence. Such ensembles are commonly used as basic building blocks for quantum sensors, quantum memory, and quantum computing. "Predicting the response to a given family of microwave pulse sequences" essentially means characterizing how external microwave driving changes the phase and population of the ensemble; to accurately predict the response, one needs to know several calibration parameters (such as drive amplitude, detuning, coupling strength, etc.), and independent measurement of each parameter consumes experimental resources. Therefore, the "minimum number of calibration settings" directly relates to experimental efficiency and error accumulation.
Large language model hallucination refers to the model generating content that appears plausible but is factually incorrect and lacks evidential support. In research contexts, hallucinations may manifest as fabricating references, incorrectly deriving formulas, or overinterpreting experimental data. A single model often struggles to self-identify such errors because its outputs are not consistent with its internal confidence; having multiple agents question each other and demand verifiable reasoning chains or experimental evidence is a form of externalized error correction, similar to peer review in academia.
Autonomous Error Correction Revealed by a Failed Experiment
A compelling turning point emerged in the study. The initial experiment results were consistent with theoretical predictions, but during repeated reference measurements, the agents discovered that the signal had drifted during data acquisition. Faced with this anomaly, the agents judged the results as "uncertain" and revised the measurement protocol, while not lowering the acceptance criteria.
The revised experiment met the established criteria and ultimately supported the theoretical predictions. This process demonstrates a key capability of autonomous laboratories: not only can they advance research when things go smoothly, but more importantly, they can proactively brake when evidence is insufficient rather than forcing a conclusion.
Signal drift is a common source of systematic error in experimental physics, referring to the slow change of a measurement reference or response over time, which may be caused by temperature fluctuations, equipment aging, magnetic field instability, and other factors. In quantum spin experiments, drift makes reference measurements and subsequent data no longer comparable, thereby rendering superficially "consistent with theory" results meaningless. The agents' detection of this anomaly during repeated reference measurements indicates that they treated reference measurements as consistency checks rather than one-time calibration; judging the results as "uncertain" and revising the measurement protocol (such as increasing reference measurement frequency, shortening acquisition windows, or introducing real-time correction) while not relaxing acceptance criteria reflects the scientific norm of "pausing conclusions when evidence is insufficient."
Boundaries and Implications of Autonomous Laboratories
The study validates the research potential of collaborative AI agents in controlled physical systems, but also delineates clear boundaries. The experimental subject is a quantum spin ensemble with well-defined structure and limited parameter space, rather than open-ended biological or materials discovery scenarios. Whether mutual review among agents can extend to more ambiguous domains that rely more on tacit knowledge remains an open question.
What is noteworthy is how the system handles "acceptance criteria"—revising protocols without relaxing standards—which provides a design principle that AI research systems can借鉴: autonomy should not come at the cost of lowering the evidentiary threshold.
As large language models continue to improve in reasoning and tool-calling capabilities, multi-agent collaboration is expected to become one of the standard architectures for autonomous laboratories, but the real test is whether human researchers are willing to delegate the authority to "halt research" to machines.
One-line Summary
A multi-agent LLM system autonomously completes the research loop from question posing to verification in quantum spin experiments.
Paragraph Summary
An arXiv study demonstrates how a multi-agent system based on large language models collaboratively completes a full research loop, with the research subject being a quantum spin ensemble in diamond. The core design is to have multiple LLM agents evaluate each other and possess the authority to halt or redirect research, in order to reduce overconfidence and hallucination risk of single models. Agents autonomously derive the minimum number of calibration settings required to predict microwave pulse responses and design experiments to distinguish competing predictions; upon detecting signal drift, they judge the results as uncertain and revise the measurement protocol without relaxing acceptance criteria. The study validates the potential of collaborative AI agents in controlled physical systems, but its applicable scope remains limited to scenarios with well-defined parameter spaces.
Related articles

Medicare Spends $50,000 Treating a Heart Attack but Won't Spend $100 Preventing One: The Mismatch in Healthcare
Medicare pays ~$50,000 to treat a heart attack but won't spend $100 to prevent one. This article unpacks the MedPage Today opinion piece and Hacker News debate on why healthcare payment favors treatment over prevention and the deep causes of incentive misalignment.
Nvidia May Cosign Loan for Nscale's West Virginia AI Data Center
Nvidia is considering cosigning a loan for Nscale's West Virginia AI data center. This article analyzes the signal significance of chip vendors entering data center financing, the risk-sharing logic, and project uncertainties.

Claude Code v2.1.316 Update Analysis: Enterprise Gateway and Multiple Stability Fixes
Claude Code v2.1.316 released: new enterprise gateway pooled group budgets, layered policy mode, subagent effort control, dozens of Shell, network, and session recovery fixes, and Opus 4.8 fast mode deprecated.