New Gemini Model Coming Soon? Decoding Reddit Community Rumors with Rational Analysis

Analyzing Reddit rumors about an upcoming Gemini model with rational perspective on pricing and competition.
A Reddit post hinting at a new Google Gemini model release has sparked widespread community discussion about model naming, pricing strategies, and Google's competitive positioning. This article decodes the community signals, examines the shift from pure performance competition to cost-efficiency battles among LLM providers, and offers a rational framework for evaluating such rumors.
A Reddit Community Rumor Sparks Gemini Speculation
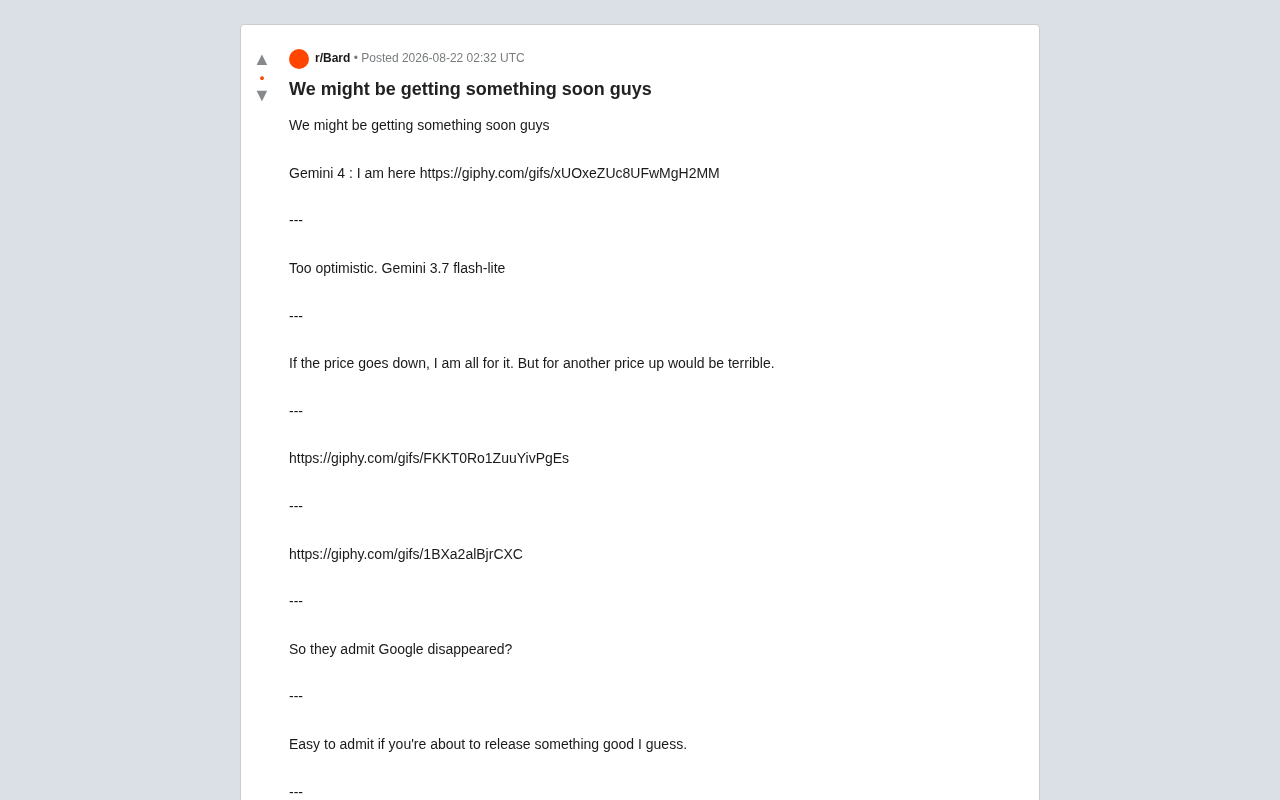
Recently, a post titled "We might be getting something soon guys" in a Reddit AI community sparked extensive discussion. While the post itself contained limited information, the community's reactions offer a window into users' high expectations and complex sentiments regarding Google's Gemini model iterations.
Google Gemini is a multimodal large language model series first released by Google DeepMind in December 2023, designed to unify understanding and generation capabilities across text, images, audio, video, and code. The Gemini family is divided into three tiers: Ultra (flagship), Pro (general-purpose), and Nano (on-device deployment), with the later addition of the Flash series focused on low latency and high cost-efficiency. Its technical architecture is based on the Transformer, but introduces significant innovations in training data scale, Mixture of Experts (MoE) architecture, and long context windows (up to 1 million or even 10 million tokens).
From the banter in the discussion thread, it's clear that users have all kinds of wild guesses about the next model's naming and positioning. Some optimistically proclaimed "Gemini 4: here I come," while others jokingly poured cold water: "That's way too optimistic — it'll be Gemini 3.7 flash-lite at best." It's worth explaining that the Flash series is Google's lightweight model line designed specifically for high-frequency, low-cost use cases, trading some reasoning depth for faster response times and lower API costs. The "lite" suffix suggests an even more stripped-down version. This naming convention is similar to OpenAI's GPT-4o-mini and Anthropic's Claude Haiku, reflecting the industry's evolution from single flagship models to multi-tiered product matrices. The gap between expectations of a "major flagship upgrade" versus "incremental iterations" precisely reflects users' real expectations about AI model update cadences.
Pricing Strategy: The Core Gemini Issue Users Care About Most
Among the many discussions, one comment hit the nail on the head: "If the price comes down, I'm all for it. But if it's another price hike, that would be terrible."
Behind this statement lies an inextricable tension in the current commercialization of large models. As model capabilities continue to grow, vendors' investments in compute and training costs rise accordingly, and these costs are ultimately passed on to API pricing and subscription fees. Specifically, LLM API pricing is primarily driven by three cost components: training costs (billions of dollars in GPU cluster investment, amortized over the model's lifecycle), inference costs (the compute consumed per user request, directly related to model parameter count and generated token count), and infrastructure maintenance costs. The industry-standard pricing model charges by input/output token count — for example, Gemini 1.5 Pro is priced at approximately $1.25/million input tokens and $5/million output tokens. Reducing inference costs depends on hardware iteration (such as Google's custom TPU v5), model distillation, quantization, and speculative decoding techniques.
For developers and power users, a model's "cost-efficiency" has become a key factor in platform selection, even surpassing raw performance metrics.
From Performance Competition to Cost-Efficiency Competition
Over the past few years, LLM competition has primarily revolved around "who's stronger" — longer context windows, better reasoning, more comprehensive multimodal capabilities. But now, the market is entering a new phase: simply stacking capabilities is no longer enough to win users over. "How much intelligence you get per dollar" is becoming the new battleground.
Since 2024, the LLM industry has experienced a notable price war. DeepSeekAd trained models with performance approaching GPT-4 at extremely low cost, OpenAI has repeatedly cut API prices, Anthropic launched the economical Claude Haiku, and Google responded with the Gemini Flash series. The underlying logic of this price competition is: as model capabilities converge toward homogeneity, differentiation shifts from pure benchmark scores to comprehensive cost-efficiency, reliability, and ecosystem experience. For enterprise users, a model that's 30% cheaper but performs comparably means saving millions of dollars annually in large-scale deployments.
If Google is indeed about to release a new Gemini model, its pricing strategy will be an important signal to watch. Whether it continues the high cost-efficiency approach of the Gemini Flash series, launches a more expensive but more powerful flagship, or does both, will directly influence users' migration decisions.
"Google Disappeared"? Community Sentiment Reflects Shifting Industry Dynamics
Another intriguing comment in the discussion: "So they're admitting Google disappeared?" Another user replied: "If you're about to release something good, it's easy to admit that."
While this exchange is tongue-in-cheek, it reflects a real piece of industry memory. To understand this sentiment, we need to revisit Google's unique position in AI. Google is actually one of the key architects of the modern AI revolution — the 2017 paper "Attention Is All You Need" by the Google Brain team introduced the Transformer architecture, directly giving rise to all mainstream large models including GPT and BERT. Google also possesses DeepMind (creators of AlphaGo/AlphaFold), leading TPU chips, and massive training datasets. However, the explosive growth of ChatGPT in late 2022 led to a widespread perception that Google had been outmaneuvered by OpenAI on the product front, reportedly triggering an internal "code red" status. Google subsequently accelerated the merger of Google Brain and DeepMind teams, going all-in on Gemini series development and commercial deployment.
For a considerable period after ChatGPT's emergence, Google — despite being an AI research pioneer — was perceived by public discourse as "behind," "slow to react," and even trapped in a "catch-up" narrative. As the Gemini series has continued to iterate and improve, Google is gradually reversing this impression.
The community sentiment of "admitting they fell behind because they're about to deliver something great" represents, to some degree, a segment of users' recognition and anticipation of Google returning to the forefront of AI competition.
How to Rationally Evaluate Gemini Model Release Rumors
It's important to emphasize that community posts like these are fundamentally speculation based on circumstantial evidence, not officially confirmed information. In the AI space, rumors about new model releases are endless, mixed with substantial amounts of unsubstantiated content. As rational observers, we should keep the following points in mind:
Distinguish Official Signals from Community Speculation
Truly reliable release signals typically come from official channels, changes in developer documentation, API endpoint update logs, or confirmed reports from credible media outlets. Community "feelings" and "maybes" are more of an atmospheric expectation with limited reference value.
Focus on Actual Model Capabilities Rather Than Naming
Whether it's called Gemini 4 or Gemini 3.x, the model's actual capabilities, pricing, and availability are what truly deserve attention. Naming is just marketing packaging — users will ultimately vote with their real-world experience and costs.
Conclusion: Expectations for New Gemini Models Should Remain Grounded
This Reddit post, though brief, serves as a mirror reflecting the collective mindset of today's AI community: full of anticipation for technological progress, yet vigilant about commercial pricing, while simultaneously witnessing the dynamic shifts in industry landscape.
For Google, if a new Gemini model is indeed on the way, the question it needs to answer isn't just "how capable is it" — it's "can it find a balance between performance and price that satisfies users." For us users, rather than being emotionally swayed by various rumors, it's better to stay rational, wait for the actual product to land, and judge based on real experience.
After all, in the ever-changing field of AI, the only certainty is that change is always on the way.
Related articles

RAG Getting Started in Practice: From Principles to Building an Enterprise Knowledge Base
Bilibili RAG course highlights: from retrieval-augmented generation principles, document chunking and vectorization, to five accuracy factors and enterprise knowledge base boundaries, with fine-tuning vs RAG selection advice.

AI Model Selection Guide: DeepSeek vs. Qwen3 in Practice
How should AI developers choose models? Based on a Bilibili tutorial, this article breaks down the Function Calling differences between DeepSeek V3 and R1, Qwen3's programmatic thinking mode switching and agent capabilities, and outlines a multi-model learning path and practical selection logic.

Anchoring, Loss Aversion, and Nudges: 5 Psychological Tactics Retailers Use to Make You Spend
Behavioral economics reveals how retailers use anchoring, framing, loss aversion, and nudge theory to manipulate your spending decisions. This article breaks down 5 common psychological tactics and offers counterstrategies like slowing down decisions and setting your own anchors to see through the pricing design behind discounts.