Obsidian 2026: MCP Connects AI Agents with Your Local Knowledge Base
In 2026, Obsidian uses MCP and local LLM plugins to become a knowledge work hub balancing privacy and AI.
The article outlines two main threads of Obsidian's AI integration in 2026. First, as a data source: through MCP and the Local REST API plugin, AI agents can locally read every file, folder, and Wikilinks graph in the vault, with mcp-obsidian as the representative project, offering no rate limits, millisecond retrieval, and data that never leaves the machine. Second, as a host: Smart Connections uses local embeddings for semantic search, Copilot for Obsidian handles conversation, together covering about 80% of typical use cases; Copilot V4 brings coding agents like opencode, Claude Code, and Codex into the vault with agent mode and custom instructions. The article concludes that privacy level depends on backend choice, with fundamental differences in data flow between local models and cloud APIs.
Obsidian has long been regarded as one of the most serious choices in personal knowledge management: local Markdown files, open data formats, and a vast plugin ecosystem. But by 2026, the focus of community discussion has shifted—no longer comparing whose interface looks better, but comparing who can better integrate with AI. The yardstick for this race is the Model Context Protocol (MCP), and Obsidian holds a dual identity in this matter: it can serve as a data source for AI agents, and it can also invite LLMs directly into the vault through plugins.
The Vault as a Data Source: How MCP Connects to Obsidian
MCP has established itself as the open standard for communication between AI applications and external systems. For Obsidian, multiple MCP servers allow AI assistants to directly access every Markdown file, every folder, and every link between notes in the vault. The most representative project is mcp-obsidian, which accesses the vault through the Local REST API community plugin and has gained around 4,500 stars on GitHub.
The core difference from cloud-based solutions like Notion lies in the architecture. The Obsidian MCP server runs as a local process on your own machine, reads files directly from the file system, and communicates with AI tools via stdio—no network access required, and no API key needed for the vault. A comparative analysis from April 2026 noted that this means there are no API rate limits, full-vault retrieval responses come back in milliseconds, and your notes never leave your computer.
What really excites Zettelkasten and Evergreen notes practitioners is the traceability of Wikilinks. AI agents can walk along the link graph—for example, answering questions like "which notes are connected to a certain concept." This capability is nearly impossible to achieve with cloud-based note tools at the same privacy cost.
What is the Model Context Protocol (MCP)
MCP is a protocol proposed and open-sourced by Anthropic at the end of 2024 to standardize how AI applications communicate with external data sources and tools. Think of it as "USB-C for the AI world": before MCP, every AI client that wanted to connect to a note-taking app or database needed a bespoke private integration; MCP abstracts this interaction into a standard message format between clients (AI applications) and servers (data/tool providers), typically based on JSON-RPC, with the transport layer supporting both local stdio and remote HTTP/SSE. MCP servers expose three types of capabilities: Resources (readable data, such as a note), Tools (callable operations, such as creating files or searching), and Prompts (preset prompt templates). Because it standardizes both "data sources" and "capabilities," the same Obsidian MCP server can be reused by Claude Desktop, Cursor, and various agent frameworks simultaneously, without having to adapt separately for each client.
The Role of the Local REST API Plugin
Local REST API is an Obsidian community plugin that starts an HTTPS service on your machine, wrapping the vault's file read/write, search, and command execution capabilities into HTTP interfaces. The MCP server itself does not directly parse Obsidian's metadata cache; instead, it accesses the vault indirectly through this local interface, so it can both read file contents and trigger Obsidian's internal operations. This is why most Obsidian MCP solutions require you to first install and enable Local REST API—without it, external processes can only treat the vault as an ordinary folder and cannot access structured information like links, tags, and frontmatter parsed by Obsidian.
Wikilinks and the Link Graph
[[bidirectional links]] are Obsidian's core syntax, making the relationships between notes a graph structure that can be traversed programmatically. Each link in the vault is both a reference and a queryable edge in reverse. For AI agents, this means retrieval doesn't have to rely solely on text similarity: it can start from a note and expand layer by layer along outlinks and backlinks, producing a set of semantically related, human-curated notes. This is exactly the capability that Zettelkasten (slip-box note-taking) and Evergreen Notes practitioners value—their note systems are themselves high-density link networks, and the link graph provides ready-made reasoning paths for agents.
Local LLM Combinations: Smart Connections and Copilot
Users who prefer not to call cloud APIs can run LLMs entirely locally. A guide from May 2026 recommended a combination of two plugins: Smart Connections uses local embeddings (e.g., running nomic-embed-text or mxbai-embed-large through Ollama) to achieve vault-wide semantic search; conversational functionality is handled by Copilot for Obsidian, pointed at the OpenAI-compatible Ollama endpoint http://localhost:11434/v1.
Together, these two plugins cover about 80% of typical "second brain" use cases—semantic search and Q&A over notes—while ensuring vault content never enters the cloud. One practical tip: the initial indexing of embedding vectors may take several minutes depending on vault size, so it's best to complete it before enabling other AI plugins. Mobile users can access Ollama through a home server on the local network or a mesh VPN like Tailscale.
How Embeddings and Semantic Search Work
Embedding is the process of mapping a piece of text to a high-dimensional vector, where semantically similar text lies closer together in vector space. Smart Connections first computes and caches embeddings for each note in the vault (usually chunked by paragraph or heading). When a user asks a question, the question is also converted into a vector, and cosine similarity is used to find the most relevant fragments to feed to the LLM. Therefore, initial indexing time depends on vault size—the more notes and the finer the chunking, the more computation required—but once indexing is done, daily retrieval is just vector comparison and is very fast. Switching embedding models invalidates the existing cache and requires re-indexing.
Why an OpenAI-Compatible Endpoint Is Needed
After Ollama starts locally, it exposes two categories of interfaces at http://localhost:11434, and the /v1 path deliberately mimics OpenAI's Chat Completions and Embeddings interface formats. This design allows any client originally written for OpenAI to seamlessly switch to a local model simply by changing the base URL to that address, without modifying code logic. Copilot for Obsidian leverages exactly this to support local models—users don't have to wait for the plugin to specifically adapt to Ollama, as long as the model itself has sufficient instruction-following and long-context capabilities. Note that local models are typically weaker than top-tier cloud models in reasoning quality, context window, and speed, so they suit privacy-sensitive, relatively simple tasks.
Tailscale and Mesh VPN
Built on WireGuard, Tailscale creates a point-to-point encrypted private network among your devices, giving each device a fixed internal IP regardless of whether they're on the same local network. For mobile users, this means Obsidian on a phone can directly access Ollama running on a home computer without exposing port 11434 to the public internet—avoiding security risks and bypassing carrier network NAT limitations. Similar mesh VPN solutions include ZeroTier; the core idea is to make dispersed devices appear to be on the same internal network without changing the existing network structure.
Copilot V4: Agents Move Directly into the Vault
The biggest change this year is the shift from a simple chat plugin to a true agent. Copilot V4 brings full coding agents into Obsidian through opencode, Claude Code, and Codex. The plugin is currently the most-used AI plugin, with over 2.4 million downloads, and won the "Best LLM Integration Award" from the Obsidian community in 2024; version 4.0.13 was updated in early October 2026.
Agent mode can inspect notes, create files, and execute tasks across multiple steps. Users can choose between their own API keys, local models, or hosted models; version 4 of the plugin also supports projects with custom instructions, reusable skills, and saved commands. This is essentially bringing the working style of coding agents into knowledge management—the note vault becomes a working directory the agent can read and write.
Where Coding Agents Meet Knowledge Management
Tools like opencode, Claude Code, and Codex were originally designed for code repositories, and they share common traits: the ability to read and write files, execute commands, and autonomously plan and call tools across multiple rounds of interaction until a task is complete. Connecting them to Obsidian essentially replaces the concept of a "code repository" with a "note vault"—the agent faces a directory full of Markdown files, links, and frontmatter rather than source code. This brings a key advantage: the agent doesn't need Obsidian-specific customization to perform cross-file lookups, batch renames, creating notes from templates, or organizing tags. The trade-off is that such agents typically have broad permissions and can modify or even delete files, making version control (e.g., managing the vault with Git) or regular backups even more important.
Agent Mode vs. Ordinary Chat
An ordinary chat plugin works in a "you ask, it answers" fashion, with model output staying in the chat window and requiring the user to manually move results into notes. Agent mode instead puts the model into an autonomous loop: first inspect relevant notes, then decide the next action (read file, write file, search), and continue based on results until the task is done. Users set a goal rather than step-by-step instructions, such as "categorize all unsorted meeting notes from this week by project and add tags." This also explains why Copilot V4 emphasizes custom instructions, reusable skills, and saved commands—they let users turn repetitive workflows into units the agent can execute.
Data Protection: Keep It Local, but Make a Conscious Choice
Obsidian itself stores notes privately on your device. With AI integrations added, the backend choice determines data flow: with local models, notes and prompts never leave your computer; with cloud APIs, messages and the note context being sent reach the respective provider. Copilot plugin developer Brevilabs emphasizes that when using the free version with its own backend, no data is transmitted to their servers; only hosted features process requests server-side.
Users handling sensitive notes need to make a conscious choice about this. The route of local MCP plus local LLM is currently the most thorough self-hosted solution for privacy, but the cost is hardware investment and configuration complexity.
The Cost and Trade-offs of Self-Hosting
"Local MCP plus local LLM" sounds like the privacy-optimal solution, but it isn't zero-cost. On the hardware side, running models in the 7B to 30B parameter range typically requires a GPU with sufficient VRAM, or relies on unified memory on Apple Silicon devices; CPU-only inference is feasible but often too slow to support interactive use. On the software side, users must maintain version compatibility among Ollama, embedding models, MCP servers, and plugins themselves, and any upgrade in one link can break the existing chain. Additionally, local models typically underperform cutting-edge cloud models on long-document summarization and complex reasoning, so in practice a common compromise is a tiered strategy: hand non-sensitive general Q&A to cloud APIs and keep privacy-related note retrieval and summarization local. Whichever route you choose, the key is to treat "where the data flows" as an explicit decision rather than sticking with default configurations.
Summary
By 2026, Obsidian has evolved from a note-taking app into a hub for AI-driven knowledge work: through MCP, the vault becomes a data source for external agents; through plugins like Smart Connections and Copilot, local, privacy-friendly assistants grow inside the vault. The combination of open file formats, local operation, and a vibrant plugin ecosystem makes Obsidian a foundation worth serious consideration—especially for users who want to connect their knowledge base to AI but are unwilling to give up data control. Where agent integration goes next, especially how coding agents collaborate with vaults, remains to be seen.
One-line Summary
In 2026, Obsidian becomes a knowledge work hub balancing privacy and AI capabilities through MCP and local LLM plugins.
Paragraph Summary
The article outlines two main threads of Obsidian's AI integration in 2026. The first is as a data source: through the Model Context Protocol and the Local REST API plugin, AI agents can locally read every file, folder, and Wikilinks link graph in the vault, with mcp-obsidian as the representative project, offering no rate limits, millisecond retrieval, and data that never leaves the machine. The second is as a host: Smart Connections uses local embeddings for semantic search, Copilot for Obsidian handles conversation, and the two together cover about 80% of typical use cases; Copilot V4 goes further by bringing coding agents like opencode, Claude Code, and Codex into the vault, supporting agent mode and custom instructions. The article concludes by emphasizing that privacy level depends on backend choice, with fundamental differences in data flow between local models and cloud APIs.
Related articles
Anthropic IPO Countdown: The Compute Cost Ledger Behind a $2 Trillion Valuation
Anthropic's IPO targets up to $2 trillion — double its Series H valuation. We break down the timeline, compute cost logic, and the key question investor day must answer.
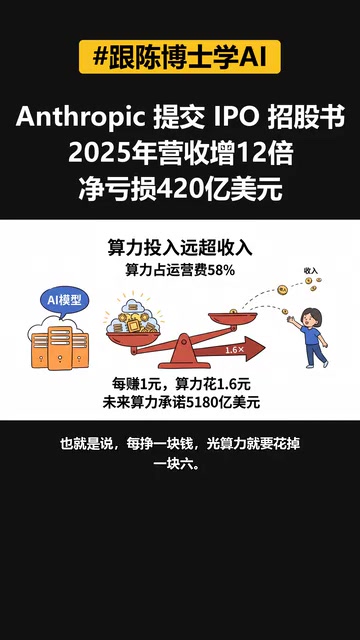
Anthropic IPO Prospectus Revealed: Behind 12x Revenue Growth, the Twin Tests of Compute Costs and Customer Concentration
Anthropic filed its IPO prospectus: 2025 revenue up 12x to $4.6B, net loss $42B including $34B non-cash. Breaking down compute costs, $2T valuation logic, customer concentration risks, and founder control.
Xteink X4 Pro Review: A Mini E-Reader That Fits in Your Pocket, Now More Affordable
Xteink X4 Pro is a 4.26-inch mini e-reader, smaller and thinner than a 6-inch Kindle, magnetically attachable to phones, and cheaper than ever. We analyze its screen, design, use cases, and value.