Open-Source Decision Model Laya: 420M Parameters, Runs Locally, Results in 33ms

Laya is a 420M-parameter open-source decision model that runs locally in 33ms at zero cost for Agent pipelines.
Laya is a newly open-sourced lightweight decision model — 421M parameters (English) or 322M (multilingual) — released under Apache 2.0. It abandons text generation entirely, handling only three task types: selecting from options (Trace), scoring a state (Score), and yes/no judgment. Its non-autoregressive architecture delivers 33ms per inference on a T4 GPU, dropping to 7.2ms in batch mode, at zero cost when run locally. English performance is solid (SNLI 0.86), multilingual is weaker but nearly doubles after fine-tuning. Positioned as a fine-tuning base for Agent decision layers, it lets large models focus on generation while small models handle high-frequency routing decisions.
A Small Model That Only Makes Decisions — No Text Generation
Agent systems are filled with constant judgment calls: "should I?" and "which one?" The traditional approach is to offload these questions to cloud-based large models — but at a real cost. Context has to leave the network, round-trips plus queue time easily add up to hundreds of milliseconds, and you're billed per token. The reality is that most decisions only need a single selection, a score, or a yes/no answer. Throwing a large model at that kind of work is overkill.
The newly open-sourced Laya offers a different path. Its scope is deliberately narrow: no chatting, no text generation — just decisions. Feed it a state description, run one forward pass, and get a structured result back. The English version has 421M parameters, the multilingual version 322M, with a maximum context of 8,192 tokens. Both are released under the Apache 2.0 license and can run directly on your own hardware.
Four Numbers That Tell the Speed Story
Laya's most compelling feature is its performance profile. On a single T4 GPU, it takes just 33ms per inference. In batch processing, that drops to 7.2ms per query — roughly 86 queries per second — at zero cost, since the model runs locally.
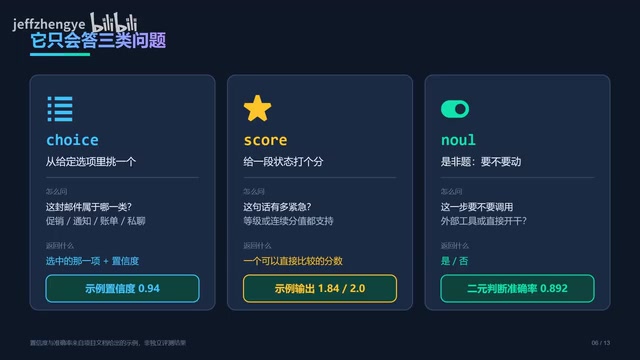
Why so fast? The key is its non-autoregressive architecture. Large language models generate text one token at a time, but Laya only runs a single forward pass: input state, declare the question, get the output fields — no sampling or decoding loop. This design trades generality for determinism and speed.
It answers exactly three types of questions:
- Trace: Pick one option from a list
- Score: Rate a given state (e.g., output 1.84)
- Yes/No: Binary judgment, accuracy 0.892
The core difference between non-autoregressive (NAR) and traditional autoregressive architectures lies in how they generate output. Autoregressive models like GPT depend on all previously generated tokens to produce the next one, advancing serially step by step — generating 100 words requires 100 forward passes. Non-autoregressive models break this serial dependency. Since Laya's tasks don't require sequence generation — only a classification label or a score — it's naturally suited to a "single forward pass, immediate result" architecture. The trade-off is the loss of sequence generation capability, but for decision-making tasks, that trade-off is entirely acceptable. The T4 GPU is NVIDIA's inference-oriented data center GPU with 16GB of VRAM and a solid price-to-performance ratio. Using it as a benchmark means Laya achieves these numbers on relatively common hardware.
Cost Comparison Across Three Approaches
Breaking down the decision-making layer, three approaches can be compared. Cloud API solutions require outbound network calls, incur fees, and face queuing delays. JAF (another decision framework) is faster but still an online service. Laya runs locally: 33ms, zero cost, open-source and commercially usable.
The trade-offs are real — deployment, GPU memory, and fine-tuning are all your responsibility. This isn't a plug-and-play product; it's a foundation that requires engineering investment.
Accuracy: Solid in English, Struggles Multilingually
Performance needs to be split in two. On English tasks, Laya performs well — reaching 0.86 on the SNLI dataset. But multilingual scenarios are clearly a struggle: on MASSIVE (covering 13 languages), it scores only 0.45, and Banking77 only 0.425, while JAF reports 0.87 on the same tasks.

The good news is that there's substantial room for fine-tuning. After fine-tuning, MASSIVE improves from 0.45 to 0.85, and another task goes from 0.362 to 0.766 — nearly doubling. This confirms the official positioning: Laya is a fine-tuning base, not a finished product.
The benchmark datasets mentioned each have a different focus. SNLI (Stanford Natural Language Inference) is a classic English NLI dataset where the task is to determine whether two sentences are entailment, contradiction, or neutral — moderate difficulty, with 0.86 representing a usable level. MASSIVE is Amazon's multilingual intent recognition dataset, covering 51 languages across 18 domains and 60 intent categories — significantly harder, especially challenging for models with limited non-English training data. Banking77 focuses on financial customer service with 77 fine-grained intent categories, demanding strong semantic understanding. Laya's low scores on the latter two (0.45 and 0.425) primarily reflect the limitations of its English-dominant pretraining data, not an architectural bottleneck — which is why fine-tuning yields such dramatic improvements.
Recommended Use: Add a Decision Layer to Your Agent
The best use case is embedding Laya inside an Agent's judgment layer. Let the expensive large model handle generation; let Laya handle each step's decision-making — dozens of high-frequency decisions per second, whether to execute code, which path to take. Reserve human review or large-model fallback for genuinely low-confidence cases. In short: expensive models generate, cheap models decide.
Getting started takes three steps: install via pip, load your checkpoint and warm it up on your chosen device, then call predict with all three question types together — it returns value and confidence so you can build your evaluation pipeline directly.
In Agent system architecture, decoupling "generation" from "judgment" is a design pattern gaining wide adoption. A typical Agent workflow involves perception, planning, and execution — each stage filled with routing decisions: which tool to call next, whether the current output meets quality standards, which branch matches user intent. These questions used to be handled entirely by the primary model (usually GPT-4 class), concentrating inference cost and making latency hard to optimize. Introducing a dedicated decision model means the large model is only called when actual content generation is needed, while high-frequency branching decisions are offloaded to a local small model. This division of labor is especially valuable in latency-sensitive applications (real-time chatbots, automated pipelines) and aligns with the engineering principle of using the right tool for the right job. Keeping the checkpoint warm in memory further eliminates per-call model loading overhead — standard practice in production deployments.
Five Cold Showers: Know These Pitfalls First
The authors are refreshingly candid about the model's limitations — five honest warnings against unrealistic expectations.

- Can classify, can't rank: Priority ordering across 8 items gets only 4 right
- Non-Latin scripts are basically unreadable: Multilingual capability has clear gaps
- Confidently wrong: Has reported 0.952 confidence on answers that scored 0
- Half the performance without fine-tuning: Using it out of the box degrades results significantly
- Drifts on long text and many options: Instability appears around 4,000 tokens and more than 20 options

It's a good fit for: data that can't leave the network, high-frequency decision-making, situations where you have labeled data, and adding a decision layer to an Agent. It's not a good fit for: tasks requiring explainability, simple coarse-grained classification, drop-in human replacement, or anything requiring text output.
Three Things to Remember
Three things worth keeping in mind about Laya: it only makes decisions, it doesn't generate text; 33ms, zero cost, Apache 2.0 license; it's a fine-tuning base, not a finished product.
As Agent architectures grow increasingly complex, decoupling judgment from generation and using small models for high-frequency decisions is a pragmatic path to cost reduction. It doesn't aim to do everything — it just aims to be fast and efficient at the one thing it does: delivering answers.
A question to leave you with: In your current workflow, where do you most need a model that only gives you answers?
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.