Open-Source Memory Plugin Dream Recall: Making AI Truly Remember You

Open-source plugin Dream Recall builds cross-window structured persistent memory and active organization for AI assistants.
The article introduces the DSH memory plugin "Dream Recall" v0.38.3, open-sourced by a Bilibili creator, addressing the pain point of AI assistants' limited context windows and session isolation causing "every new window to meet you for the first time." The plugin builds a structured memory board for each workspace, categorizing memories into skills, soul, user, project, topic, facts, lessons, and guidelines, proactively presenting key information when a window opens, with a "mind map" visual index. Its core is the "dream" mechanism: during idle time, spending two hours organizing scattered conversations, distilling casual remarks, pitfalls, and project progress into entries and pages respectively, so a new window opens with last time's experience. In forgetting design, faded memories are only marked "forgotten" rather than deleted, embodying the philosophy of "should fade but not disappear." The plugin is open source and easy to install.
Why AI Always "Meets You for the First Time"
Every time you open a new window in DSH, it's like meeting for the first time. Yesterday it remembered you don't eat cilantro, but today in a different window it asks who you are; it doesn't remember what annoys you, doesn't recall where you got stuck last time, and certainly doesn't remember the pitfalls it has stumbled into. This is a common problem with current AI assistants in long-conversation scenarios — limited context windows, session isolation, and memory that can't persist across windows.
The open-source memory plugin "Dream Recall" (梦境深忆) v0.38.3, released by a Bilibili creator, attempts to solve this problem at its root. Its approach isn't simply stacking context, but giving each workspace its own "little board" that structures and persists memory, proactively presenting it every time a window opens.
The context window is the upper limit of tokens an LLM can "see" in a single inference pass, including the system prompt, conversation history, and current input. It is not equivalent to long-term memory: once the window scrolls or the session closes, the excess no longer participates in subsequent generation. Session isolation means that different conversations don't share state by default, and each new window starts from a blank history. RAG (Retrieval-Augmented Generation) is a common remedy — chunking external documents into a vector store and retrieving them by similarity to splice into the prompt; but it retrieves static corpora and lacks proactive summarization of in-session experience like "user preferences" or "project progress." Dream Recall's approach is closer to "structured memory + proactive injection": first distilling conversations into entries, then presenting them on demand when a window opens, rather than passively waiting for retrieval hits.
Seven Memory Types and the "Mind Map" Index
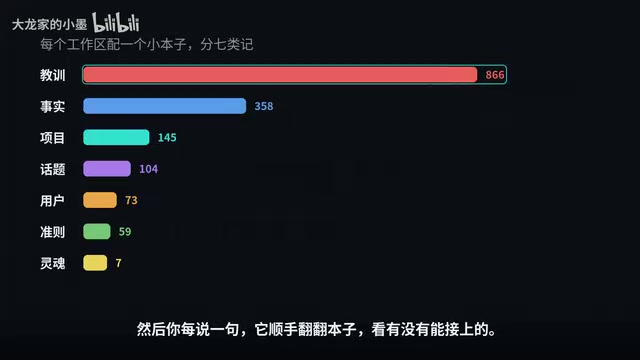
The plugin divides memory into seven categories: skills, soul, user, project, topic, facts, lessons, and guidelines. Each time a window opens, it first pulls out the important ones and places them up front; what you said is kept word-for-word, placed in its own entry right in front of you. Then with every sentence you say, it flips through the notebook to see if anything connects.
What do these memories look like? The creator drew a "mind map": in the center is "me," surrounded by over a hundred projects, each heart being one memory. Click on a heart and you can see when it was recorded and what was being discussed at the time. This visual index turns memory from a black box into a traceable, browsable knowledge network.
Memory classification isn't arbitrary — it corresponds to different invocation timings and lifecycles. "User" memories (preferences, taboos) should be loaded in almost every conversation; "project" memories are isolated by workspace and swapped when switching tasks; "lessons" and "guidelines" are high-priority behavioral constraints that often need to be injected into the prompt before generation to serve their purpose of "avoiding repeated mistakes"; "topics" and "facts" are short-cycle, easily decaying content suitable for recall only when related questions arise. The point of classification is to give retrieval clear priorities and trigger conditions, avoiding stuffing all memories into context at once — which wastes tokens and dilutes the truly critical constraint information.
"Dreams": Letting Scattered Conversations Settle into Experience
What truly distinguishes this plugin from ordinary chat logs is the "dream." During the day, conversations are messy — sentences barely pause, you jump from thought to thought, and before finishing one thing you run off to do another. When things quiet down, the plugin spends two hours going through everything said during that period, gathering up the scattered pieces: a casual remark becomes one entry, a pitfall stumbled into becomes one entry, a project becomes one page.
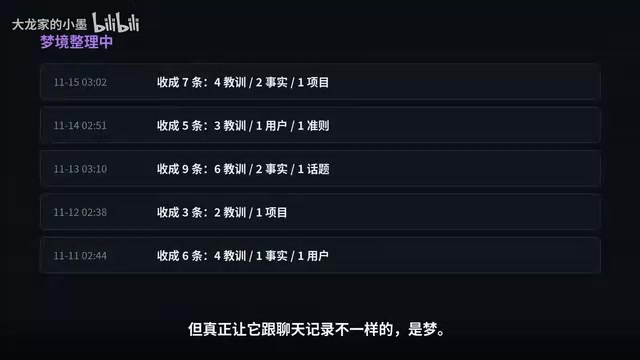
The next time you pick up where you left off, it's written right there. That's the value of the "dream" — it's not passive storage, but active organization, compression, and distillation.
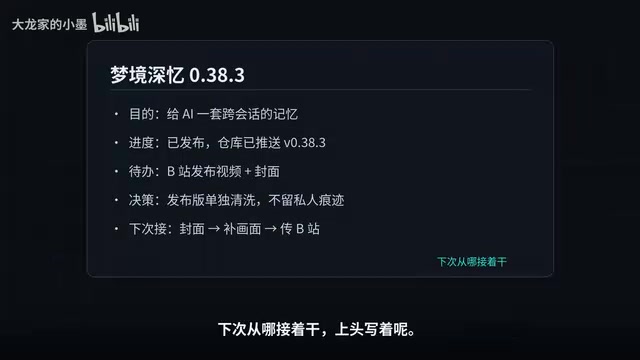
The "dream" here is essentially an offline batch-processing style of memory consolidation: during idle periods, another model instance summarizes, deduplicates, merges, and annotates historical conversations. It borrows from the mechanism of "memory replay" in human sleep — fragments encoded during the day are reactivated, compressed, and written into long-term storage during rest. In engineering terms, this is "background memory consolidation," complementary to online retrieval: the online phase only does lightweight writing and recall, leaving the heavy work for offline completion, so as not to slow down each conversation's response time. The cost is additional model invocation expenses and a scheduling strategy for determining "when to trigger consolidation."
From "Remembering" to "Opening with Experience"
What's the use of gathering it up? The use is that the next day when you open a new window, these are placed in front of it without you having to say a word. So it's not "remembering that such a thing happened," but opening with last time's experience.
The creator gave a real example: there used to be a bad habit — not verifying after making changes — which was mentioned once and recorded that time. Later, whenever a change was completed, that entry would pop up on its own — test before delivering. The same mistake is never made twice.
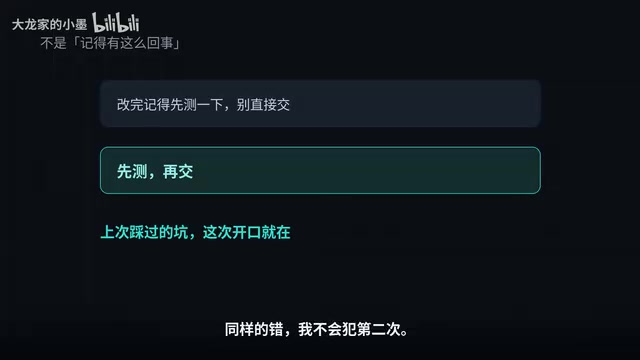
This mechanism transforms "lessons" into triggerable behavioral guidelines, rather than letting them sleep in history records.
Memories Should Fade, But Not Disappear
Data shows that over five weeks, 1,612 memories and 113 dreams accumulated, of which 11 have faded — not deleted, just marked as "forgotten," and still retrievable if you really look. The creator emphasizes: memories should naturally fade, but not disappear — this is intentional design.
This design philosophy is worth pondering. Human memory itself is a dynamic balance of forgetting and reinforcement. If AI memory only grows and never shrinks, it will eventually be drowned in noise; if deleted arbitrarily, key clues may be lost. Using "forgetting markers" instead of deletion is a more elegant compromise.
Open Source and Installation
This plugin is now open source. The creator posted it on GitHub, with installation instructions in the description. Just give the address to DSH and it installs itself. For users who use AI assistants for project development long-term, this cross-window persistent memory capability may change the user experience more directly than upgrading model parameters.
Related articles

Abnormal Error Rate Spike in Claude Mythos 5.2 and Fable 5.2
Claude Mythos 5.2 and Claude Fable 5.2 show an abnormal spike in request error rates, marked as investigating on the official status page. This article covers the incident overview, practical impact on developers, and recommended responses.

ReAct Runtime Context Trimming: Why Claude Code Acts at 70%
A deep dive into ReAct runtime context trimming: why Claude Code compresses at ~70% usage, why tool calls dominate, why messages must be dropped in pairs, and why codebases don't need RAG.

AI Agent vs LLM: How Cursor and Claude Code Actually Work
An in-depth analysis of the essential difference between AI Agents and LLMs: LLMs generate code suggestions, while Agents modify files and run tests via tool calls. Using a Spring Boot bug fix as an example, it breaks down the workflows, permission control, and verification mechanisms of Cursor and Claude Code.