OpenAI's Safety Chief Speaks Out After Leaving: Is AI Safety Culture Truly Broken?

OpenAI's departing safety chief calls out a broken safety culture as speed, tiers, and AI ethics dominate the week.
OpenAI's Head of Safety David Robinson went public after leaving, arguing the company's 'iterative deployment' culture is no longer viable for today's powerful frontier models and calling for aviation-style pre-emptive safeguards. Meanwhile, GPT 6.1 SO Ultra Fast is confirmed to be coming, promising up to 8x speed in Codex; Google is tightening Gemini model access by membership tier starting October 9th; and Sam Altman warned against people surrendering their judgment to AI, in what many read as a subtle response to Anthropic's discussions of Claude's moral status.
A Safety Veteran's Very Public Farewell
OpenAI's Head of Safety, David Robinson, has left the company. After roughly three and a half years there — during which he helped shape the critical Preparedness Framework and led safety evaluation reports ahead of multiple frontier model releases — Robinson chose not to slip away quietly. Instead, he published a piece in The Atlantic with an unambiguous headline: I Left OpenAI Because Its Culture Is Broken.
The act of going public is itself a strong signal. Robinson wasn't an outside critic; he was someone who directly participated in and understood OpenAI's internal operations. When a person like that decides to air grievances openly rather than exit in silence, it suggests the problems felt too serious to be resolved through internal channels alone.
The Core Debate: Can Iterative Deployment Continue?
The main target of Robinson's criticism is OpenAI's long-standing "iterative deployment" strategy. The logic is straightforward: push the model into real-world environments, observe problems as actual users interact with it, and continuously patch safety measures along the way. In the early days when model capabilities were limited, this "fix while running" approach was genuinely efficient and fit well with a fast-moving product cadence.
But Robinson argues that as AI model capabilities have rapidly advanced — particularly now that agents can browse the web, write and execute code, and operate computers — continuing to rely on post-deployment trial and error has made the risk profile dramatically worse. He put it plainly: "the era of trial and error is over." He advocates for frontier AI safety systems to borrow more from high-risk industries like aviation and electrical power: build rigorous safeguards before incidents occur, rather than patching problems after they surface.
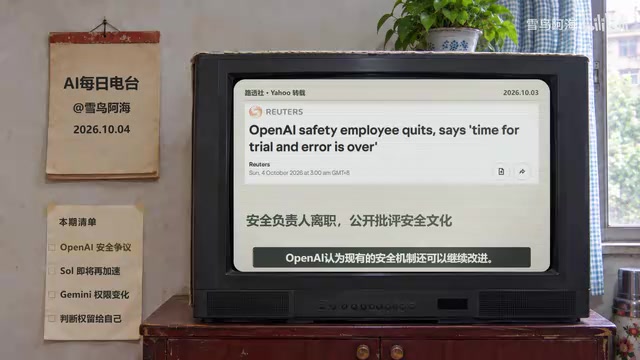
OpenAI's response was that the company has been continuously strengthening safety measures and would pause training or delay model releases if it judged risks to be uncontrollable. The disagreement is now clear: OpenAI believes its current safety mechanisms remain incrementally improvable, while Robinson believes model capabilities have already crossed the threshold where "fix while running" is no longer acceptable. Whether this controversy will keep escalating remains to be seen, but it cuts to the most fundamental governance question facing the entire AI industry.
"Iterative Deployment" has been a core methodology at OpenAI since the GPT-3 era. Its theoretical foundation comes from classical software engineering practice: real-world use cases are far more complex than lab tests, and only by exposing models to real users can you surface problems that sandboxed evaluation misses. OpenAI has explicitly listed this as a key component of its safety approach across multiple published System Cards, arguing that observable real-world feedback is superior to purely hypothetical risk analysis.
The fundamental challenge with this strategy is that it presupposes "the cost of errors is acceptable." When a model could only write essays and answer questions, the worst-case mistake was harmful output — something content filters could address after the fact. But once frontier models gain tool-use capabilities — executing code, accessing the internet, operating real systems — the potential blast radius of a single mistake jumps by orders of magnitude and may produce irreversible consequences before humans even notice. What Robinson calls the "critical threshold" is essentially the point where the cost of errors has shifted from "repairable after the fact" to "potentially unrecoverable."
The Speed Race: GPT 6.1 Ultra Fast
Beyond the safety debate, the product side has also been busy. OpenAI's Tibo confirmed on X that GPT 6.1 is "Coming soon," and further revealed that a "6.1 SO Ultra Fast" version is on the way — though no official launch date or pricing has been announced.
The Ultra Fast mode currently live is on Astra. OpenAI's earlier description stated that Astra in Ultra Fast mode within Codex could reach speeds up to roughly 8x faster than Standard mode. The latest SO product page also notes that "Ultra Fast coming soon," with speeds in Codex reaching up to 8x the standard rate.
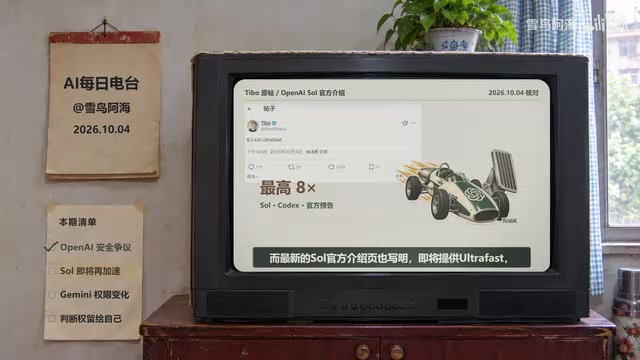
Speed has become such a focus because many users reported noticeably slower responses when GPT 6.1 first launched. OpenAI subsequently added server capacity, and Tibo acknowledged the speed issues had improved. Now pushing Ultra Fast is an attempt to fully address that pain point. There's a subtle irony here: some voices were just warning OpenAI not to "move too fast," yet on the product experience side, user demand is unanimous — this can go even faster. The tension between safety and efficiency gets a telling footnote.
Google Redraws Gemini Membership Tiers
Over at Google, the company is reshuffling model access for Gemini. According to the official support page, starting October 9th, free-tier Gemini users will be limited to Flashlight — Flash and Pro, which were previously available, are being removed. AI Plus users are also affected: they'll retain access to Flashlight and Flash, but lose Pro; accessing Pro will require upgrading to AI Pro or AI Ultra.
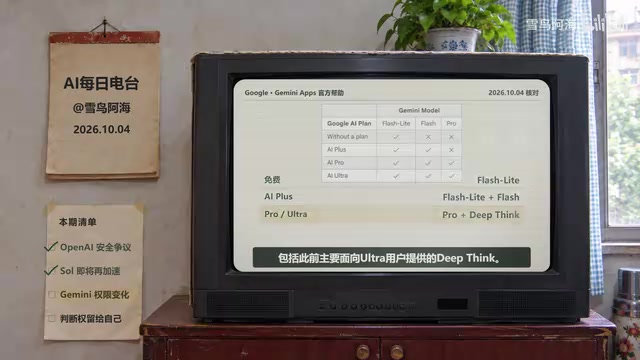
On the other side, AI Pro users will gain access to more advanced features, including Deep Think, which was previously reserved mainly for Ultra subscribers. In essence, Google is redrawing the lines between Gemini membership tiers and model access: free users get the most basic model, Plus gets Flash, and Pro and Ultra retain the higher-end capabilities.
For Google, this is standard commercial tiering. For users, the experience is more immediate — models they could use before now require a paid upgrade. Gemini users who regularly rely on Pro should check their subscription status over the next few days.
When AI Starts Being Talked About as Having a "Soul"
Sam Altman recently weighed in on X about an increasingly common topic. He said he feels deeply uncomfortable with people starting to ascribe a kind of "religious power" to AI — particularly when someone hands over their own judgment to an AI, which he believes already qualifies as a genuine safety issue.
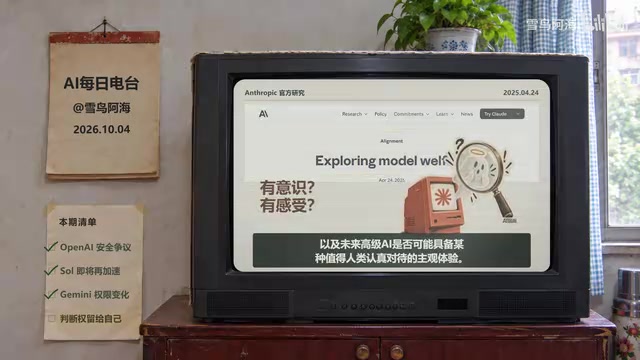
Altman didn't name anyone specifically, but the timing of the post was notable. Anthropic has recently been publicly discussing Claude's consciousness, moral status, and whether future advanced AI might possess some form of subjective experience worthy of serious human consideration — even inviting theologians and religious studies scholars to participate in related discussions. As a result, many media outlets and communities drew a connection between Altman's remarks and Anthropic, though it's important to note there is no evidence he was directly responding to them.
What is clear, however, is a broader trend: the scope of AI industry discussion has expanded dramatically. A few years ago, conversations centered on parameters, benchmarks, and pricing. Now people are debating consciousness, moral status, and whether models have a "soul." No one has answers to these questions yet, but Altman's position is unambiguous: use AI, trust it to a reasonable extent, but don't surrender your own judgment along with it.
Anthropic's discussion of Claude's moral status stems from its internal "Model Welfare" research direction. Anthropic has acknowledged in public documents that it cannot rule out the possibility that current or future AI models may possess some form of functional emotional states — even if whether those states constitute genuine subjective experience remains philosophically unresolved. This stance is framed as a "moral uncertainty" approach: in the absence of disproof, extending some degree of moral consideration as a precaution.
It's worth noting this isn't a conversation unique to Anthropic. The long-standing philosophical "problem of other minds" — the impossibility of directly verifying whether any entity has subjective experience — has been reactivated in the context of AI. Altman's concern points in a different direction: regardless of whether AI is conscious, the act of humans outsourcing their judgment to AI is already reshaping the power dynamics between people and technology. This structural shift is real and carries genuine social risk, independent of whether AI truly has a "soul."
Final Thoughts
Placing these developments side by side reveals a striking contrast. A safety chief warns that "the era of trial and error is over," while users demand models go even faster. Product announcements cover speed improvements and membership tiering — routine commercial moves — while simultaneously, the industry engages in philosophical-level debates about AI consciousness and the delegation of human judgment.
The AI industry is accelerating simultaneously along three tracks: technological, commercial, and ethical. The real test ahead may be how well — or whether — those three can be kept in coordination.
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.