OpenCode v2.2.7 Cache Warming Mechanism Explained: When Is It Worth Enabling

OpenCode v2.2.7 aligns cache warming with the model cache TTL—more precise, but costs must be weighed by usage pattern.
OpenCode v2.2.7 makes a key change to cache warming: pings are no longer sent at fixed intervals but aligned with the model cache TTL, triggering when the cache is about to expire to cut unnecessary requests. This shifts cache lifecycle management into the tool and lowers configuration complexity. But warming isn't free—each ping consumes API quota, and idle pings accumulate costs. Whether to enable it depends on your workflow: high-frequency, latency-sensitive use with intervals near the TTL benefits most; long idle periods or budget-sensitive projects should be cautious. Judge by the distribution of your call intervals.
What Is Cache Warming and Why It Matters
In the world of AI coding assistants, model response speed directly affects developer productivity. OpenCode, an open-source AI coding tool, introduced a seemingly minor but far-reaching change in v2.2.7: the timing logic for Cache Warming is now aligned with the model cache's TTL (Time To Live).
According to the RSS article "OpenCode Cache Warming: What v2.2.7 Changed and When to Turn It On," this change means OpenCode no longer sends warming requests at a fixed interval, but instead dynamically adjusts the frequency of pings based on the cache's actual expiration time.
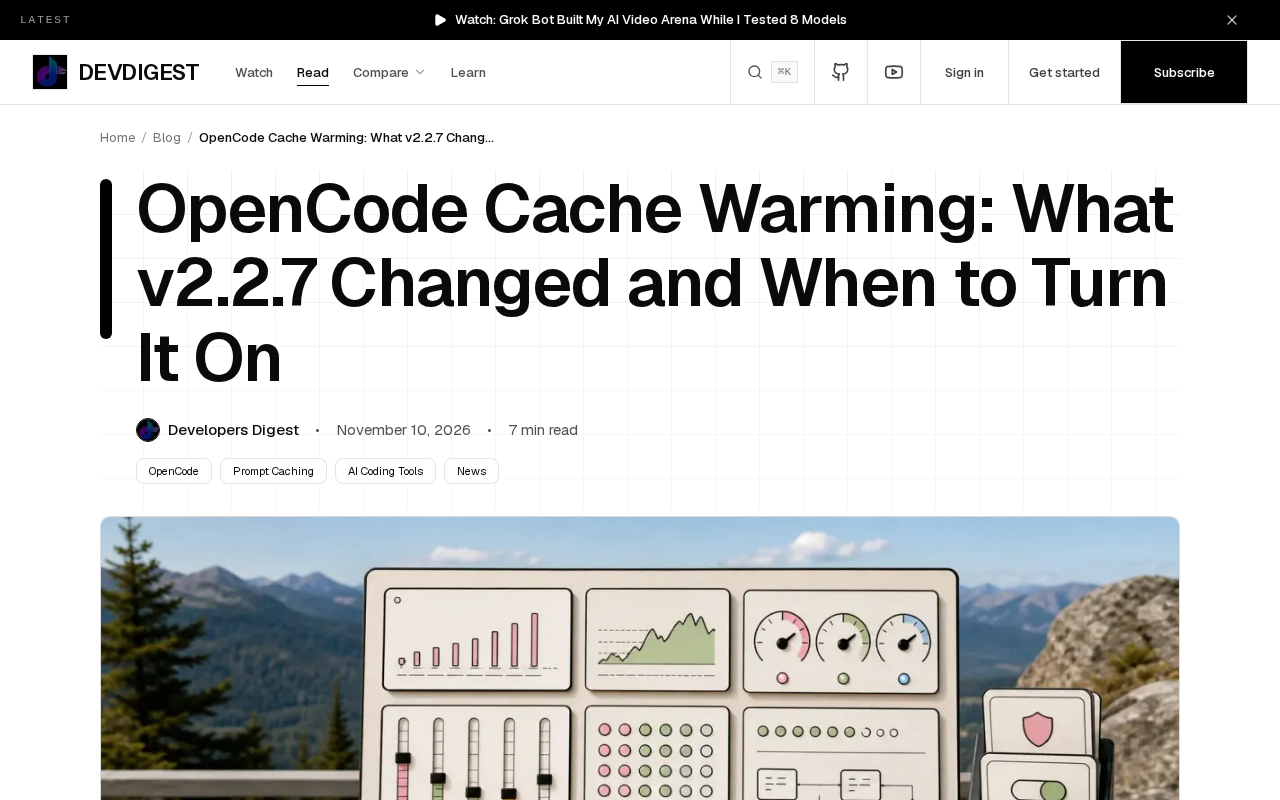
For users who rely on OpenCode for daily development, understanding this mechanism helps make more informed trade-offs between response speed and API cost.
Cache TTL is the key term for understanding this article. TTL (Time To Live) refers to the validity period set by the model server for a cache entry: starting from when the cache is created or last accessed, if that duration passes without a hit, the cache entry is cleared, and the next request must recompute and repopulate it. TTL varies widely across model providers and services—some are only a few minutes, others can be tens of minutes. TTL determines when a warming request must be sent to be meaningful—sending too early is wasteful, and sending too late means the cache has already expired and the warming effort is lost.
Cache Warming is essentially "exchanging one lightweight request for lower latency on subsequent calls." In AI inference scenarios, a complete request often includes prompt parsing, context construction, and model computation. A server-side cache hit can skip redundant computation and significantly reduce time-to-first-token. Warming means proactively sending a lightweight request (the ping mentioned in the article) to the server without generating a real business request—one sufficient to trigger a cache hit—keeping the cache "hot" and avoiding cold starts when users actually make calls.
The Core Change in v2.2.7: From Fixed Intervals to TTL Synchronization
Before v2.2.7, cache warming may have used a relatively fixed time interval to send requests, keeping the model-side cache active. But this approach has obvious flaws: if the cache TTL is long, a fixed interval may cause unnecessary pings; if the TTL is short, the cache may expire prematurely because the interval is too long.
v2.2.7 binds the timing of pings to the model cache's TTL, triggering warming requests when the cache is about to expire. The original article notes that this change makes warming behavior more precise and reduces unnecessary request overhead.
From an engineering perspective, this design approach is commendable: it shifts responsibility for managing the cache lifecycle from the user side to the tool's internals, reducing configuration complexity.
Configuration and the Cost of Idle Pings
The original article mentions configuration options and the cost issues brought by idle pings. Cache warming is not free—every ping consumes API call quota, even if the request itself is very lightweight.
When developers are thinking, reading code, or briefly away, OpenCode may still send warming requests at the TTL cadence, and this overhead is "idle cost." For token-billed model services, idle pings accumulated over time may not be negligible.
The original article suggests users evaluate based on their actual usage patterns: if sessions are frequently interrupted and resumed, warming can significantly reduce cold-start latency; but if the tool is idle most of the time, warming is instead a waste.
Understanding idle ping cost requires first clarifying the basic unit of API billing. Mainstream large-model services typically price input tokens and output tokens separately. Even if the warming request content is extremely short (such as a single character or a fixed probe), each call still generates a billing event and may trigger rate limits (RPM/TPM quotas). Therefore, the cost of idle pings is not only monetary but also quota consumption: when quotas are tight, warming requests may crowd out quota for real business requests.
In addition, cache hits can usually reduce billing (some providers offer discounts on input tokens for cache hits), but if the warming request itself misses or the probe is too short, the discount may not apply. When evaluating idle cost, you should compare "cost per ping × pings per day" with "time lost to cold starts × frequency of occurrence," rather than looking only at unit price. This is also why the original article emphasizes judging based on the distribution of personal call intervals.
When Enabling Cache Warming Is Worthwhile
Based on the original article's views, the following scenarios are suitable for enabling cache warming:
- High-frequency interactive development sessions: When coding continuously and frequently calling the model for completions or Q&A, keeping the cache active delivers a smoother experience.
- Latency-sensitive workflows: For example, code review or debugging scenarios that require instant feedback, where cold-start waiting time disrupts rhythm.
- Cases where the model TTL is short and call intervals are close to the TTL: This is where warming yields the greatest benefit, because the cache easily expires naturally.
Conversely, in the following situations you should enable warming cautiously or turn it off:
- Long idle periods: If OpenCode is only used occasionally, the cost of idle pings may exceed the inconvenience of cold starts.
- Budget-sensitive projects: When API call costs need strict control, additional warming requests should be taken into account.
Cold Start Latency is another core factor in the trade-off. When the cache expires, the server must reload the model context, rebuild the KV cache, or perform full forward computation, and the time-to-first-packet may be several times or even an order of magnitude higher than with a cache hit. For interactions that require "instant feedback," such as code completion and inline Q&A, the pause caused by a cold start interrupts the developer's flow, and the perceived cost is far higher than the token cost of the request itself.
Therefore, deciding whether to enable warming is essentially finding a balance between two costs: the deterministic API spending brought by warming, and the unpredictable time loss brought by cold starts. When the workflow is latency-sensitive and cold starts occur frequently, the former clearly offers better value; otherwise, saving API overhead should take priority.
How to Weigh It: A Practical Decision Framework
The original article does not give a one-size-fits-all answer, but emphasizes that "when to enable" depends on individual usage patterns. A simple way to judge is to observe the distribution of your model call intervals throughout the day. If most call intervals are shorter than the cache TTL, warming is almost imperceptible; if intervals often far exceed the TTL, warming is paying for cold starts that rarely happen.
At least the TTL alignment mechanism in v2.2.7 makes this trade-off more transparent—pings are no longer sent blindly but follow the cache lifecycle in rhythm. For developers pursuing maximum efficiency, understanding this mechanism allows them to adjust configuration with more justification rather than toggling it on and off by feel.
Summary
The cache warming improvements in OpenCode v2.2.7 reflect the tool's thinking on balancing cost and performance. TTL synchronization makes warming smarter, but whether to enable it still requires judgment based on personal workflows. In an era where AI coding tools are increasingly widespread, such detailed optimizations often determine the total cost of ownership over long-term use.
One-line Summary
OpenCode v2.2.7 aligns cache warming with the model cache TTL, making it more precise but requiring cost trade-offs based on usage patterns.
Paragraph Summary
OpenCode v2.2.7 makes a key adjustment to its cache warming mechanism: the timing of warming pings is no longer at a fixed interval but aligned with the model cache's TTL (Time To Live), triggering when the cache is about to expire to reduce unnecessary requests. This change shifts cache lifecycle management from the user side to the tool's internals, reducing configuration complexity. But cache warming is not free—every ping consumes API call quota, and "idle pings" generated while developers think or are away accumulate costs over time. The article notes that whether to enable warming depends on personal workflows: scenarios with high-frequency interaction, latency sensitivity, and call intervals close to the TTL benefit most; long idle periods or budget-sensitive projects should be cautious. The way to judge is to observe the distribution of model call intervals throughout the day.
Related articles
Why Rockets Don't Land Horizontally Like Airplanes: A Physics and Engineering Trade-off
Why don't rockets land horizontally like airplanes with wings? This article explains the engineering trade-offs behind Shuttle-style landings and Falcon 9 vertical landings from three angles: wing lift conditions, orbital velocity costs, and reusable booster structural reuse.

Can AI Governance Tools Block Agent and API Calls?
A Reddit developer questions whether AI governance tools only flag Agent calls rather than block them. We analyze the flagging vs. real-time blocking capability gap, vendor demo mismatches, and key questions to ask when buying.
Perplexity's New Default Setting: The Experience and the Logic Behind It
Exploring the significance and impact of Perplexity's default setting change, analyzing how defaults guide user experience and speculating on model, search scope, or answer style adjustments.