Perplexity Decision API Cuts Prices 50%: Input Tokens Now Just $0.02 per Million

Perplexity halves Decision API input pricing to $0.02/million tokens, intensifying the AI API price war.
Perplexity has cut its Decision API input token price in half again, down to just $0.02 per million tokens. While purely a pricing change with no feature updates, it reflects a clear industry trend of vendors slashing inference costs to win developer adoption. The Decision API's built-in RAG pipeline amplifies input token consumption, making this price cut especially impactful for retrieval-augmented and high-frequency use cases. Developers should note that only input pricing was announced — output pricing and rate limits still require a check of the official pricing page.
Perplexity Cuts Decision API Prices Again
Perplexity has announced another round of price cuts for its Decision API, slashing the previous rate in half. Input token costs now stand at just 2 cents per million input tokens. This adjustment directly lowers the cost for developers calling the API, making it especially attractive for applications that require high-frequency, large-scale usage.
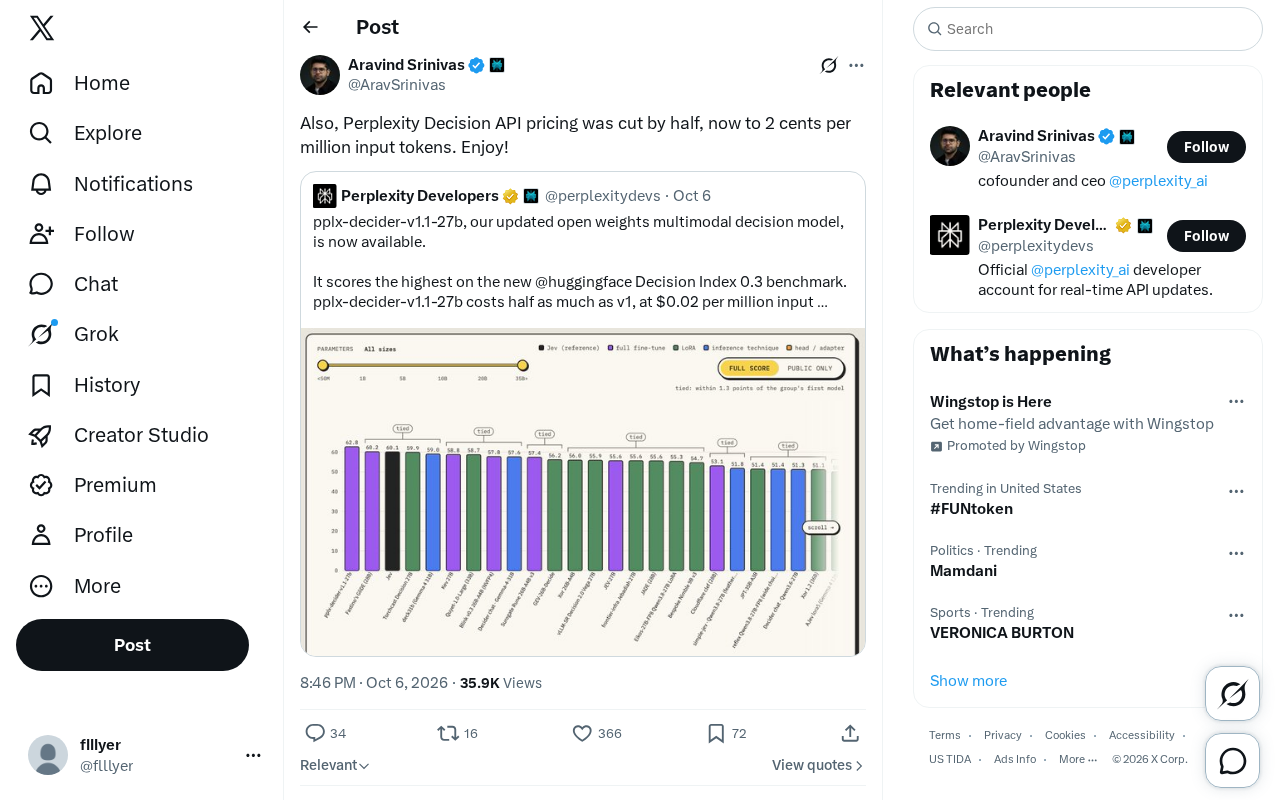
On its surface, this is a straightforward pricing change rather than a feature upgrade. But against the backdrop of an increasingly fierce AI API price war, the move sends a clear signal: vendors are aggressively cutting inference and usage costs to compete for developer mindshare.
The Industry Logic Behind the Price Drop
Dropping input token pricing to $0.02 per million further compresses the marginal cost of processing large volumes of text. For teams building decision-support or retrieval-augmented applications, these kinds of cost optimizations have a direct impact on gross margin structure and scalability.
Over the past year, major AI service providers have broadly moved into a price-cutting cycle — whether for foundational LLM APIs or specialized interfaces built around search, decision-making, and retrieval capabilities. Perplexity's strength lies in search and real-time information retrieval, and its Decision API targets applications that need to make judgments based on up-to-the-minute data. Halving the price lowers the barrier for small and mid-sized developers and early-stage startups to incorporate it into their tech stacks.
The Decision API is a specialized interface from Perplexity designed to deliver structured judgments or recommendations based on real-time web retrieval — rather than simply returning raw search results. Unlike general-purpose LLM APIs, the Decision API has a built-in retrieval-augmented generation (RAG) pipeline: it first fetches the latest information from the internet or designated data sources, then combines that with language model reasoning to produce a decision-ready conclusion that applications can consume directly. This makes it particularly well-suited for use cases like price comparison, product recommendations, competitive analysis, and real-time sentiment evaluation — scenarios that require both "current information" and "reasoning." Input token charges typically cover the user's prompt along with retrieved content, while output tokens correspond to the model's final response. Both together make up the full cost of a call.
What This Means for Developers
For developers already using the Decision API, the most immediate benefit is a cost reduction of 50%. Workloads previously constrained by budget can now run at double the volume for the same spend, opening up more room for product iteration and large-scale testing.
It's worth noting that the official announcement only addresses input token pricing. Output token pricing, rate limits, and other billing details were not specified in this update. Developers doing cost projections should still refer to Perplexity's official pricing page for complete information and factor in both input and output costs when estimating real-world expenses.
Retrieval-Augmented Generation (RAG) is one of the dominant architectures in modern AI application development. The core idea is straightforward: before the model generates a response, a retrieval system fetches external documents or real-time data relevant to the query, and that content is injected into the prompt as context — helping the model produce more accurate, timely answers. The advantage of this approach is that new knowledge can be introduced without retraining the model, but the trade-off is that prompt length (and therefore input token count) grows significantly as more retrieved content is added. This makes input token pricing especially impactful for RAG-based applications — and Perplexity's price cut will often deliver more meaningful cost savings for these workloads than for simple question-answering use cases.
Takeaway
Perplexity's Decision API input pricing dropping to $0.02 per million tokens is another data point in the ongoing AI API price competition. For cost-conscious teams, it's a meaningful development worth watching — though a complete value assessment still requires factoring in output pricing and your actual usage patterns.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.