Ponytail: 176K Stars — Teaching AI Coding Assistants to Be Lazy and Halve the Code

Ponytail's seven-rung ladder makes AI first ask "can we not write this?" — halving code while test coverage rises.
Ponytail is an open-source project with over 176K GitHub stars that aims to correct AI coding assistants' "do-everything" tendency. Through a "seven-rung ladder" decision process, it requires AI to ask before writing code: does the feature need to exist, is there a ready implementation in the repo, can the standard library or platform cover it, can existing dependencies be reused, can one line do it — and only when all fail does it write minimum viable code. Its "laziness" applies only to solution selection; input validation, error handling, security, and accessibility are not cut. Official benchmarks show 53% less code, 41% less time, 26% lower cost, and high-risk logic test coverage rising from 68% to 98%. It also offers review and audit commands, installable in two commands within Claude Code.
An Open-Source Project That Gets AI to Write Less Code
AI coding assistants tend to go for the "do-everything" approach — ask it to add a date picker, and it might install a third-party library or hand-write an entire calendar component, easily ballooning past hundreds of lines of code. The Ponytail project, showcased on Bilibili, tries to reverse this tendency: it gets AI to think like the laziest senior developer on the team, aiming to solve problems with the least amount of code. The project has already racked up over 176,000 stars on GitHub, bookmarked by 176,000 people, making it a highly discussed "laziness tool" in the developer community.
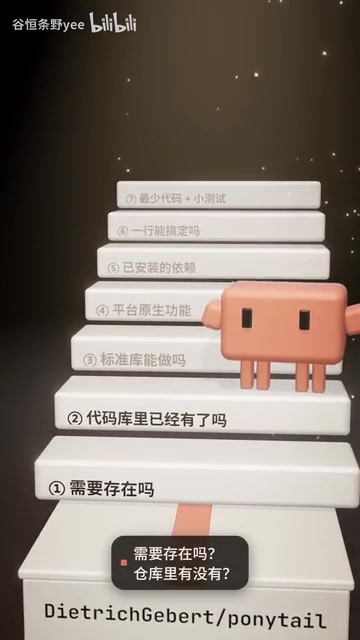
Ponytail's core idea is simple: before writing any code, ask a few questions — write less if you can. It turns this "laziness" into an executable decision process, rather than simply letting AI cut corners.
The Seven-Rung Ladder: From "Does This Need to Exist?" to "Minimum Viable Code"
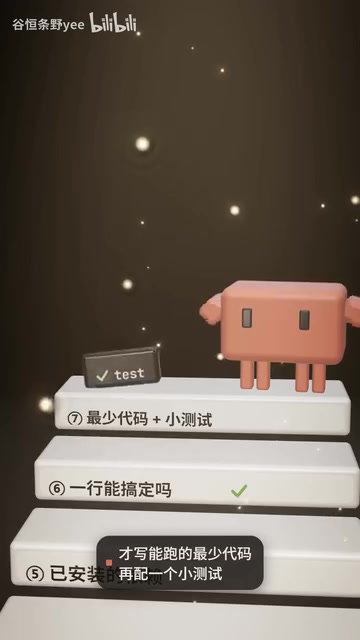
Ponytail's secret is a "seven-rung ladder." Before writing code, the AI must climb from the first rung upward, asking at each step: Does this feature need to exist? Is there an existing implementation in the repo? Can the standard library do it? Can the platform's native capabilities cover it? Can an existing dependency be reused? Can one line of code do the job? Only when every lower-level option fails does it reach the final rung — writing the minimum code that runs.
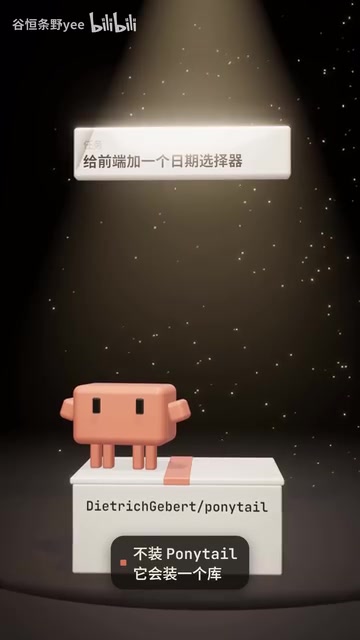
Take adding a date picker as an example: without Ponytail, the AI might install a library or just hand-write an entire calendar, reaching 335 lines of code. With Ponytail, it first checks whether the repo already has an input field, then directly leverages the browser's built-in date selection capability — a few lines of code and it's done. This "find the existing solution first" path avoids reinventing the wheel and dramatically shrinks code size.
Browser-native date selection refers to the HTML standard element <input type="date"> and its companion showPicker() method. Modern browsers (Chrome, Edge, Safari, Firefox) all have a built-in date picker UI — clicking the input pops up a month-calendar overlay, with no need to import any JavaScript library or hand-write a calendar component. The element returns a YYYY-MM-DD formatted string, can constrain the selectable range via the min, max, and step attributes, and natively supports keyboard operation and accessibility semantics. Ponytail leverages exactly this platform capability to compress a calendar component that would otherwise need hundreds of lines into a few lines of declarative HTML, while automatically gaining cross-browser compatibility and accessibility guarantees.
"Minimum viable code" borrows from the idea of a "minimum viable product" (MVP): given that functional requirements are met, write only the absolutely necessary code, avoiding any speculative abstractions, configuration options, or extension points. It requires the developer (or AI) to first deliver a minimal implementation that runs and validates assumptions, then decide whether to extend based on real feedback. Ponytail's seven-rung ladder engineers this principle: each rung tries to satisfy the need with less code, and only when the current rung genuinely cannot cover it is moving to the next rung allowed. This effectively curbs AI's common tendency toward "over-engineering" — for example, pre-designing a plugin architecture or generic configuration system for a single scenario.
Laziness Has Boundaries: Security and Error Handling Are Never Cut
It's worth emphasizing that Ponytail's "laziness" applies only to solution selection, not to lowering code quality. It explicitly requires that input validation, error handling, security, and accessibility support must not be cut. In other words, what it cuts is redundant implementation approaches, not necessary robustness guarantees.
This design philosophy addresses a common pain point: AI-generated code often piles up large amounts of unnecessary logic just to "look complete," which actually increases maintenance cost and the probability of errors. By constraining the AI's decision path, Ponytail makes its output closer to a senior developer's habits — satisfying requirements in the simplest way while holding the quality line.
Measured Results: Half the Code, Yet Higher Test Coverage
Ponytail's official benchmark provides a direct comparison: code volume reduced by 53%, time reduced by 41%, and cost reduced by 26%. More counterintuitively, the share of high-risk logic with tests rose from 68% to 98%.
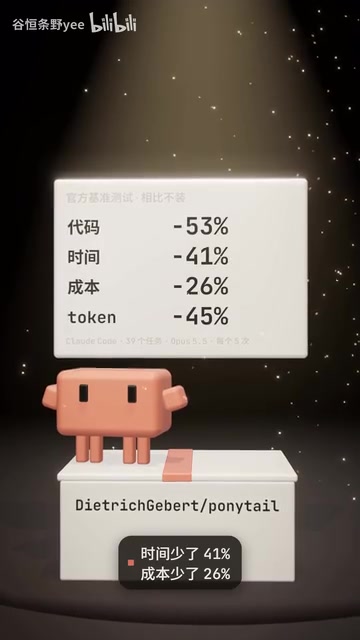
This result shows that "laziness" does not sacrifice reliability. Less code means the logic needing tests is more concentrated, making it easier for the AI to add tests for critical paths. For team collaboration, a smaller code diff also means a lower review burden and higher merge efficiency.
High-risk logic typically refers to critical code paths involving financial transactions, permission checks, data persistence, external input handling, or security boundaries. Errors in such logic have serious consequences and are hard to fully rule out through manual review, so the industry generally requires high test coverage for it. In Ponytail's benchmark, this ratio rose from 68% to 98%, indicating that after code volume shrinks, the AI's attention is more focused and it is more willing to add test cases for critical branches. This also corroborates an engineering lesson: the less code there is and the more single-purpose the responsibilities, the easier it is to achieve thorough test coverage.
Two Commands: review and audit
Beyond the ladder strategy used during code generation, Ponytail also provides two practical commands: review for reviewing the current change, and audit for scanning the entire repository and ranking fixes by priority. In the Claude Code environment, installation takes just two commands. This lightweight integration lowers the barrier to entry and lets Ponytail fit into existing AI coding workflows, rather than requiring developers to switch toolchains.
From a broader perspective, Ponytail represents a new expectation for AI coding assistants: not generating more code, but generating less yet more accurate code. When AI can judge "what not to write" like a senior developer, code quality and development efficiency can truly improve at the same time.
Claude Code is a command-line AI coding tool launched by Anthropic that allows developers to interact directly with the Claude model in the terminal, performing tasks such as code generation, file editing, and command execution, and supports extending its capabilities through custom commands. Ponytail integrates in a "two commands to install" manner, meaning it does not require developers to switch IDEs or workflows but exists as a skill pack or command extension for Claude Code, lowering adoption cost. This lightweight integration model also reflects a trend in the AI coding tool ecosystem: capabilities embedded into existing workflows as composable plugins, rather than starting from scratch.
One-line Summary
Ponytail uses a seven-rung ladder to make AI first ask "can we not write this?" — halving code while test coverage rises.
Related articles

Claude Code + Agent: Building a Fully Automated AI Testing Loop
Bilibili course breakdown: how test developers can use Claude Code terminal-based Agents to build a fully automated AI testing loop. Compares permission boundaries of terminal vs. device Agents, explains why enterprise projects choose Claude Code over Open Claude-type tools, and outlines the Node.js environment setup and DeepSeek model integration path.

Working with AI Agents Requires Nerves of Steel
The more autonomous AI agents become, the heavier the user's psychological burden. Drawing from a Hacker News discussion, this article analyzes black-box anxiety, behavior drift, and monitoring fatigue in agent collaboration, and offers practical approaches like sandbox isolation, permission control, and task granularity management to reduce cognitive load.

To Replace Adobe Acrobat, I Built My Own Open-Source PDF Reader Folio
A developer unhappy with Adobe Acrobat's bloat built Folio, a lightweight open-source PDF reader. Learn the design philosophy and use cases of this alternative.