Private Evolution: When Differentially Private Synthetic Data Meets Learning-Augmented Clustering

New research reframes Private Evolution as generative model-augmented Wasserstein learning, showing low-dimensional structure captured by generative models tightens privacy bounds.
The differentially private synthetic data algorithm Private Evolution (PE) outperforms worst-case Wasserstein bounds in practice. A recent RSS study attributes this to generative models providing prior knowledge, reframing PE as learning-augmented clustering where the model proposes candidates and the privacy mechanism evaluates them. This perspective explains PE's empirical advantages and offers guidance for model selection and privacy budget allocation.
Differentially private synthetic data generation has long faced an awkward reality: theoretical worst-case guarantees often diverge dramatically from empirical performance. Private Evolution (PE), a differentially private synthetic data algorithm, performs far better in practice than the lower bounds predicted by Wasserstein distance analysis. A recent study from RSS attempts to explain this phenomenon by reframing PE as "generative model-augmented Wasserstein learning" and proving that performance bounds can be substantially tightened when the generative model captures partial structure of the true distribution.
From Wasserstein Learning to Generative Model Augmentation
Traditional analysis treats PE as a Wasserstein learning algorithm, focusing on the Wasserstein distance between the synthetic data distribution and the true distribution. The limitation of this perspective is that it assumes no prior knowledge is available during the generation process, and therefore can only provide worst-case convergence rates. But PE does not actually start from scratch—it relies on a generative model to produce candidate samples, which are then filtered and iterated upon by a differential privacy mechanism.
The researchers point out that if the generative model can capture the low-dimensional structure of the true distribution (e.g., samples lie in the same low-dimensional space), then the error upper bound of PE can be significantly better than what pure Wasserstein analysis yields. In other words, PE's performance advantage stems partly from the "learning augmentation" provided by the generative model, rather than from the algorithm's own Wasserstein optimization process.
Wasserstein distance (also known as earth mover's distance) is a measure of the difference between two probability distributions, intuitively understood as the minimum cost of moving the "pile of earth" of one distribution to match another. In differentially private synthetic data, Wasserstein distance is commonly used to bound the error between the synthetic and true distributions. However, convergence analysis based on Wasserstein distance typically assumes the algorithm has no prior knowledge of the true distribution, yielding worst-case rates that tend to be conservative. This explains why PE performs far better in experiments than the theoretical lower bound—because the analysis does not exploit the distributional structure information provided by the generative model.
Theoretical Framework of Learning-Augmented Clustering
Reframing PE as learning-augmented clustering is the core conceptual leap of this work. From the clustering perspective, PE's iterative process can be understood as follows: the generative model proposes candidate cluster centers or samples, and the differential privacy mechanism evaluates how well these candidates match the real data while protecting individual privacy. The quality of the generative model determines how well the candidate set aligns with the true distribution, thereby affecting the utility of the final synthetic data.
The theoretical contribution lies in the authors providing performance bounds when the generative model has a certain capacity to capture the distribution. These bounds are not only tighter but also explain why PE can exceed the predictions of worst-case Wasserstein analysis in experiments. For the field of differentially private synthetic data, this means algorithm design can more actively leverage the prior knowledge of generative models rather than treating them as black-box components.
The core of a differential privacy mechanism is to ensure that the algorithm's output is insensitive to changes in any single data point, typically achieved by adding calibrated noise (such as the Gaussian mechanism or Laplace mechanism). In PE's clustering perspective, when the differential privacy mechanism is used to evaluate how well candidate samples match real data, it must ensure that the evaluation process does not leak individual information. Common approaches include adding noise to matching scores or using the exponential mechanism to select candidates. The design of this mechanism directly affects clustering quality and the allocation of privacy budget, and is a key link connecting generative model proposals to the utility of the final synthetic data.
Implications for Differentially Private Synthetic Data Practice
This analysis offers several direct insights for practitioners. First, when selecting or training a generative model, one should focus on whether it can capture the low-dimensional structure of the data, rather than merely pursuing diversity of generated samples. Second, PE's number of iterations and privacy budget allocation can be adjusted in conjunction with the quality of the generative model—the stronger the generative model, the lower the privacy budget may need to be to achieve the same utility. Third, the improved theoretical bounds provide more reliable expectations for evaluating PE's performance on different datasets, reducing the gap between "conservative theory and surprising experiments."
Of course, the theoretical assumptions of this work still need to be validated across broader data types and privacy parameters. The condition that the generative model "captures the true distribution" is difficult to quantify in practice, and how to translate it into actionable design guidelines is a question that future research needs to answer. But at the very least, understanding PE as learning-augmented clustering provides a more explanatory analytical perspective for differentially private synthetic data generation.
One-line Summary
A new study reframes Private Evolution as generative model-augmented Wasserstein learning, proving that leveraging low-dimensional structure captured by generative models can substantially tighten performance bounds for differentially private synthetic data.
Paragraph Summary
The differentially private synthetic data algorithm Private Evolution (PE) performs far better in practice than the worst-case lower bounds predicted by Wasserstein distance analysis. A recent RSS study points out that traditional analysis ignores the prior knowledge provided by generative models, and reframes PE as "generative model-augmented Wasserstein learning." When the generative model can capture the low-dimensional structure of the true distribution, PE's error upper bound can be significantly better than pure Wasserstein analysis. The researchers further interpret PE as learning-augmented clustering: the generative model proposes candidate samples, and the differential privacy mechanism evaluates match quality. This perspective not only explains PE's empirical advantages but also provides theoretical grounding for generative model selection and privacy budget allocation.
Related articles
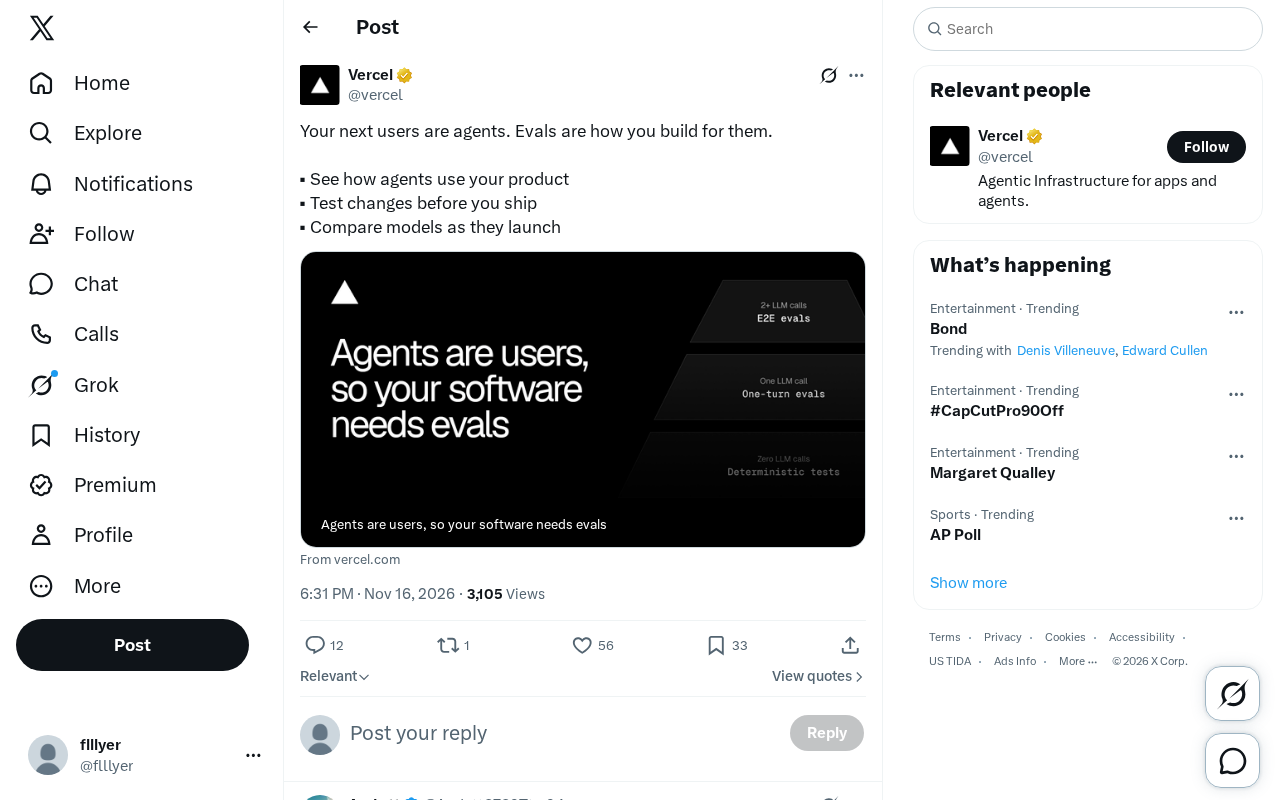
The AI Agent Era: Building a New Product Paradigm with Evals
AI Agents are becoming the next users of products. This article explains how to use Evals to observe Agent usage behavior, test changes before launch, and compare new model performance, helping product teams establish a development methodology for the Agent era.
Microsoft Global Email Outage Leads to Chlorine Leak at German Hotel, Injuring 15
A Microsoft 365 and Outlook global outage prevented a chlorine safety alert from reaching a German Phantasialand hotel, injuring 15 guests and exposing the fragility of cloud-dependent safety systems.
iPhone Duo to Support Face Unlock Using Only the Front Camera
Apple is developing front-camera-only face unlock for the iPhone Duo, now testing in the iOS 27.3 beta. We analyze the technical approach, user experience, and security trade-offs.