Progressive Disclosure Makes Agents 2.3x Faster: A New Approach to Context Engineering

Progressive disclosure speeds up agents by 2.3x through on-demand, layered context loading.
Starting from a Hacker News discussion, this article explains how "progressive disclosure," a strategy from interaction design, has been transplanted into AI agent development. Many agent frameworks stuff all tool schemas, reference documents, and lengthy history into the system prompt, keeping input tokens high every reasoning round. The article analyzes three ways context bloat slows agents: inference latency growing linearly with tokens, attention dilution and the "lost in the middle" phenomenon in long contexts, and interference and mis-calls caused by irrelevant tool descriptions. Corresponding practices include layered tool catalogs, on-demand document retrieval, history compression and summarization, and staged system prompts—essentially changing one-time full loading into on-demand progressive loading. The author is cautious about the 2.3x speedup, viewing it as scenario-limited, but notes that context optimization gains can rival switching to a faster model, and warns of added decision overhead and information omission risks in implementation.
In AI Agent development, a frequently overlooked performance bottleneck is coming to the surface: context management. A discussion on Hacker News points out that a "Progressive Disclosure" strategy can make agents run 2.3x faster. Behind this number lies a methodology that is taking shape: Context Engineering.
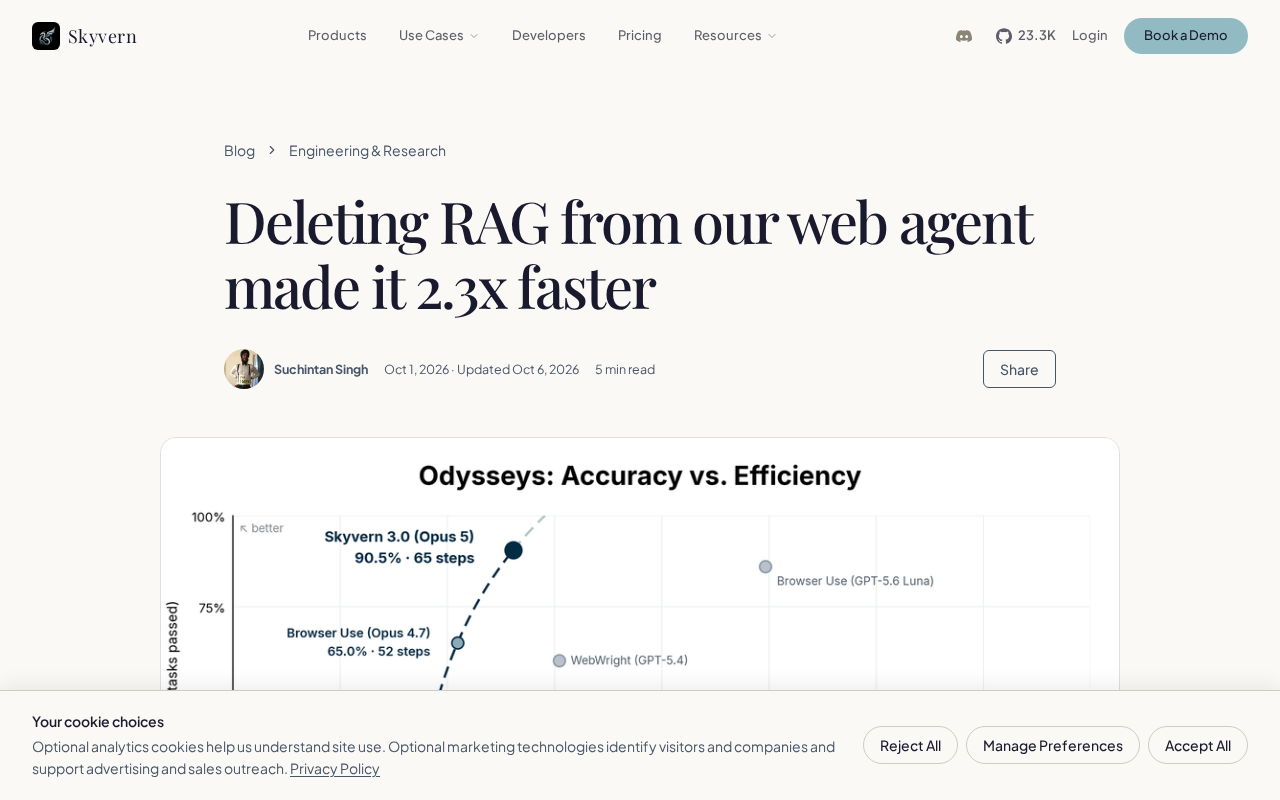
What Is Progressive Disclosure?
Progressive disclosure is not a new concept in AI—it originated in interaction design, referring to interfaces that reveal information gradually only when users need it, avoiding dumping all options at once. Transplanted into the agent context, the core idea becomes: don't burden the agent with the full set of tool descriptions, document content, and history on every reasoning round; instead, load information on demand, in layers, and in stages.
This stands in sharp contrast to current mainstream practice. Many agent frameworks habitually stuff the complete schemas of all available tools, all reference documents, and lengthy conversation history into the system prompt, keeping input token counts high on every LLM call. The longer the context, the higher the inference latency, and the more the model's attention to key information gets diluted.
Why Context Bloat Slows Agents Down
Agent performance losses come mainly from three dimensions.
Linear Growth of Inference Latency
LLM inference time is roughly positively correlated with the number of input tokens. When the number of tools grows from 5 to 50, tool descriptions alone can occupy thousands of tokens. Every ReAct loop round re-transmits this "static burden," so latency naturally rises.
The ReAct loop is the most classic reasoning-acting paradigm in the agent field, alternating between Reasoning and Acting: the model first outputs a thought, decides which tool to call and with what parameters, gets an observation after execution, and then enters the next round of thinking. Every loop round requires re-sending "system prompt + history trajectory + new observation" to the model as a whole, so the static portion of the context is repeatedly billed and repeatedly reasoned over. This is why fixed content like tool schemas has a multiplier effect on latency—it isn't transmitted just once, but accumulates linearly with the number of loop rounds. Understanding this makes it clear why compressing static context can yield speedups far beyond expectations.
Attention Dilution and Degraded Decision Quality
A more insidious problem is that overly long contexts make it hard for the model to focus on truly relevant information. The industry's commonly cited "lost in the middle" phenomenon shows that models utilize content in the middle of the context noticeably less. When tool lists and documents fill the prompt, the agent's accuracy in selecting the right tool and citing the right passage drops, triggering more trial-and-error loops—which is itself a huge time cost.
Lost in the middle is an empirical finding proposed by Stanford and other institutions in 2023: when key information is placed at different positions in a long context, the model's recall for the beginning and end is noticeably higher than for the middle, forming a U-shaped curve. This means that even if a model claims to support an ultra-long context window, it doesn't mean it can evenly utilize every piece of information within it. For agents, tool schemas and documents are often piled in the middle of the prompt, exactly in the least-utilized range. Mitigation approaches include placing the most critical instructions at the front or back, explicitly numbering and summarizing injected content, and shortening the span of the "middle" by reducing total volume.
Interference from Irrelevant Tools
An agent with dozens of tools often needs only two or three of them for a specific task. Descriptions of the remaining tools not only waste tokens but may also induce the model to call irrelevant tools, generating extra round trips.
Practical Approaches to Progressive Disclosure
According to the thinking in the Hacker News discussion, progressive disclosure can be implemented from several directions.
Layered tool catalog. First expose tool categories and brief descriptions to the agent, and only after the agent expresses a certain type of intent, load the full schemas of the specific tools under that category. This resembles how humans use documentation: first look at the table of contents, then turn to specific chapters.
On-demand document retrieval. Instead of stuffing the entire knowledge base into the prompt, let the agent actively retrieve passages through a retrieval tool and inject only the relevant matched content into context. RAG itself embodies this idea, but progressive disclosure emphasizes dynamically controlling the injection volume at every decision step of the agent.
History compression and summarization. In long conversations, details of early interactions can be compressed into summaries and expanded back to the original text only when retrospection is needed. This can significantly control the growth curve of context.
Staged system prompts. Split the system prompt into base instructions and task-related instructions, with the latter dynamically mounted according to the current task stage.
What these approaches share is changing "one-time full loading" into "on-demand progressive loading"—essentially finer-grained scheduling of context as a scarce resource.
What Does a 2.3x Speedup Mean?
The 2.3x speedup figure should be treated with caution—it very likely comes from measurements under specific tasks and specific model configurations and may not transfer directly to all scenarios. But this magnitude suggests that the gains from context optimization may be no less than switching to a faster model or adding hardware.
For developers, this means that while chasing larger context windows, thinking in reverse about "how to use less context" is equally valuable. Larger context windows solve the question of "can it fit," while progressive disclosure solves the question of "should it be loaded." The two are not contradictory but complementary: no matter how large the window, unrestrained filling will sacrifice speed and accuracy.
From a cost perspective, reducing input tokens directly lowers API call costs and also reduces inference energy consumption. For high-frequency production agents, this optimization compounds over time.
Considerations for Implementation
Progressive disclosure is not without costs. Layered loading introduces additional decision steps—the agent must first judge "what kind of information do I need," which itself consumes a reasoning round. If the layering is designed too complexly, the tokens saved may not offset the added round-trip overhead.
Another risk is information omission: if catalog descriptions are not accurate enough, the agent may fail to realize that a useful tool exists and thus take detours. Therefore, the naming and summary quality of the layered catalog is crucial—it effectively takes on the role of "information routing."
A prudent approach in practice is to start small: first tally the hit rates of each tool in the agent's actual calls, identify high-frequency tools and long-tail tools, and apply lazy loading to the long-tail portion. Using real call data to drive layered design is more reliable than dividing categories by intuition.
Conclusion
Progressive disclosure brings the classic principles of interaction design into agent engineering, reminding us that context is a resource that requires careful budgeting. The 2.3x speedup figure may have scenario limitations, but the direction behind it deserves serious attention from every agent developer: putting a little less in the prompt and asking one more question at the right moment is often more effective than piling on more information.
Background Notes
Tool schemas are usually described in JSON Schema format, containing fields such as tool name, function description, and each parameter's name, type, whether it is required, enum values, and description. A moderately complex tool's full schema is often between 100 and 300 tokens, and enterprise-grade tools with many parameters and detailed descriptions can even exceed 500 tokens. When an agent mounts dozens of tools, this part alone can consume tens of thousands of tokens and is re-transmitted every loop round. Progressive disclosure first exposes only the tool name and a one-sentence description (which can be compressed to a dozen or so tokens), and loads the full schema only after the intent is clear, thereby deferring most token consumption until it is truly needed.
RAG (Retrieval-Augmented Generation) in its conventional form retrieves Top-K passages once after the user's question and concatenates them all into the prompt; the retrieval granularity and injection volume are fixed before the call. Progressive disclosure turns retrieval into a tool that the agent can actively call: the model first forms a query, observes the returned titles or summaries, and then decides whether to drill into a particular entry. The difference lies in where control resides—the former statically decides what to inject through an external pipeline, while the latter is dynamically decided by the model during reasoning. This also means the retrieval interface needs to return layered results (such as three levels: title list, passage summary, full original text) to support a step-by-step drill-down interaction pattern.
Related articles

Zero-Code AI God Sandbox: Is This Reddit User's Wild Idea Feasible?
A Reddit user wants 3-4 AI agents to play gods in a sandbox world for friends to interact with. Is this zero-code idea technically feasible? We break down the barriers.
Is Claude the AI That Refuses to Be a "Yes-Man"? A Reddit Discussion
Reddit discusses whether Claude is the least "yes-man" LLM. This article analyzes Claude's honesty design, comparisons with other models, and users' real attitudes toward AI people-pleasing.
What Security Teams Need to Know: Risks of Abliterated Models in Agents
Abliterated models strip alignment constraints at the weight level. When used in AI Agents with tool-calling capabilities, risk escalates from content to operations. This article offers security teams four directions: model provenance auditing, behavioral baseline detection, runtime protection, and supply chain admission.