Reflection to Open-Source 501B-Parameter MoE Model Beam
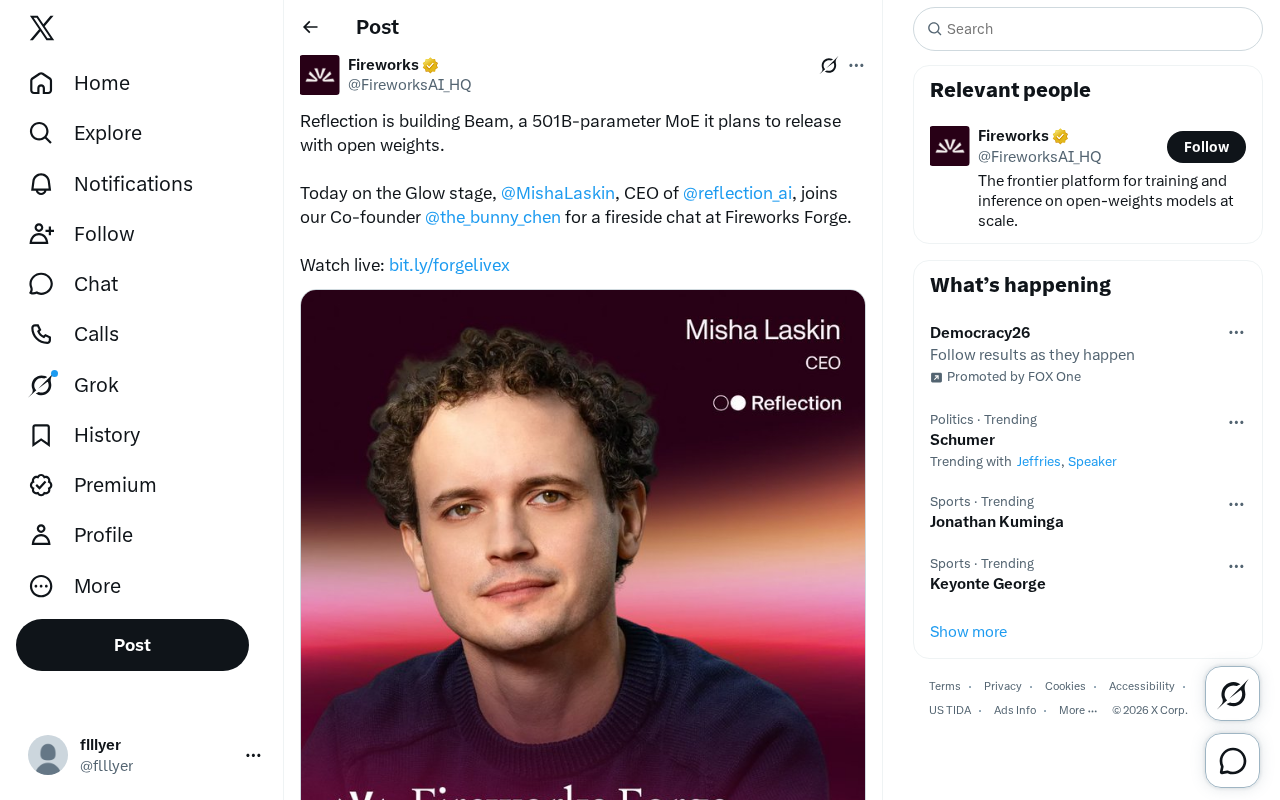
Reflection is reported to be building Beam, a 501B-parameter MoE model, planned for open-weight release.
According to Twitter, Reflection is building a mixture-of-experts model called Beam with 501B parameters, planned for open-weight release. The news was announced during a fireside chat on the Glow stage at the Fireworks Forge event by Reflection's CEO and Fireworks' co-founder. 501B is at the frontier for open-source models, and the MoE architecture controls inference costs through sparse activation. Open weights mean researchers and developers can download the weights for local deployment or secondary development. However, a model of this scale has a high deployment threshold, requiring considerable memory and distributed inference infrastructure. Currently, training data, architecture details, license, and release timing have not been disclosed; its commercial use license and documentation completeness will affect developer ecosystem recognition.
Model Specifications and Open-Source Strategy
According to Twitter, Reflection is building a mixture-of-experts (MoE) model called Beam with 501B parameters, and plans to release it with open weights. The news was announced on the Glow stage at the Fireworks Forge event, during a fireside chat between Reflection CEO @MishaLaskin and Fireworks co-founder @the_bunny_chen.
A 501B parameter scale is at the frontier for open-source models. The MoE architecture uses sparse activation, calling only a subset of parameters during inference, thereby scaling model capacity while controlling computational cost. Reflection's choice of open weights means researchers and developers can download the model weights for local deployment or secondary development, contrasting with earlier closed-source strategies that offered only API access.
Mixture-of-Experts (MoE) architecture is a sparse activation design that splits a model into multiple "expert" subnetworks. Each input token is selectively routed through a router network to activate a small number of experts (e.g., 2 out of 8), so the number of parameters actually involved in computation during inference is far smaller than the total. If only about 5%-10% of the 501B total parameters are activated each time, the actual computation can approach that of a dense model with tens of billions of parameters, but with broader model capacity and knowledge coverage. The challenges of MoE lie in routing load balancing, training stability, and memory footprint—all expert parameters still need to reside in memory, so the total parameter count determines the hardware threshold for deployment.
Open weights refers to publicly releasing trained model parameter files, allowing others to download, run locally, fine-tune, or redistribute them. It is not entirely equivalent to "open source": open source typically also requires public training code, data, and complete reproduction methods, whereas open weights may only provide weights and inference code, and the license may restrict commercial use. The core value of open weights is freeing researchers and enterprises from API dependence, enabling private deployment with controllable data privacy, and supporting domain-specific fine-tuning. However, license terms (such as whether commercial use is allowed and whether derivative models must also be open) determine the actual degree of openness.
Industry Context and Potential Impact
If Reflection's Beam model is open-sourced as planned, it will join the growing camp of open-weight MoE models. The open-source community's interest in large-scale MoE models continues to heat up, as such models can deliver performance close to dense models while maintaining inference efficiency. The 501B total parameter count combined with MoE routing is expected to show competitiveness on multiple benchmarks.
However, open weights also bring deployment threshold challenges. A model of this scale requires considerable memory and distributed inference infrastructure, making it difficult for ordinary developers to run directly. Reflection may lower the barrier through quantized versions or inference optimization tools, but specific plans have not yet been disclosed.
Memory and distributed inference: The memory required for model inference is roughly determined by parameter count, precision, and KV cache. For example, with 501B parameters, at FP16 precision the weights alone require about 1TB of memory, far exceeding single-GPU capacity, necessitating multi-GPU tensor parallelism or pipeline parallelism. Even with INT8/INT4 quantization, hundreds of GB of memory are still required. Therefore, local deployment of large-scale MoE typically relies on multiple GPU servers or cloud instances. Ordinary developers are more likely to run heavily compressed models on consumer hardware through quantized versions (such as GGUF format), but with some performance degradation.
Release Cadence and Open Questions
Currently, Reflection has only announced the model name, parameter scale, and open-source intention, without disclosing training data, architecture details, license type, or specific release timing. Whether these topics were covered in the fireside chat cannot be confirmed from available information. For the open-source AI community, Beam's subsequent progress is worth tracking, especially whether its weight license permits commercial use and whether Reflection will simultaneously provide inference code and a model card.
From a competitive landscape perspective, the open-source release of a 501B MoE will directly benchmark against other large-scale open-weight models and may drive a new round of open-source model capability competition. As a relatively low-profile player, whether Reflection can gain developer ecosystem recognition with Beam depends on the actual performance and documentation completeness at release.
One-line Summary
Reflection is reported to be building Beam, a 501B-parameter MoE model, planned for release with open weights.
Paragraph Summary
According to Twitter, Reflection is building a mixture-of-experts model called Beam with 501B parameters, planned for release with open weights. The news was announced during a fireside chat on the Glow stage at the Fireworks Forge event by Reflection's CEO and Fireworks' co-founder. 501B is at the frontier for open-source models, and the MoE architecture controls inference costs through sparse activation. Open weights mean researchers and developers can download the weights for local deployment or secondary development. However, a model of this scale has a high deployment threshold, requiring considerable memory and distributed inference infrastructure. Currently, training data, architecture details, license, and release timing have not been disclosed; its commercial use license and documentation completeness will affect developer ecosystem recognition.
Related articles

Glasshand: Giving AI Agents a Real iPhone and Mac
Glasshand lets AI agents rent real iPhones and Macs, supporting Claude Code, Codex, and more to post, book services, and test iOS apps on real devices. This article explains how it works, its use cases, and potential boundaries.

ChatGPT Images 2.6 Released: GIF Generation, Reference Image Reuse, and 50% Speed Boost
ChatGPT Images 2.6 released: prompt-to-GIF animation with frame-by-frame editing, reusable reference images for yourself, pets, or characters, 50% faster generation, plus Flare and Sunburst API model variants and SVG export for developers.

Rerun: Turn Your AI Subscription into an AI Coworker Team
Rerun, #3 on Product Hunt, turns your ChatGPT or Claude subscription into a team of AI coworkers that run on schedules or triggers, each with tools, a computer, and a shared workspace. It asks before risky actions, is open source (AGPL v3), and supports self-hosting.