Running Hermes with Qwen3-8B Local Deployment: Automated Workflows on Low-Spec Hardware
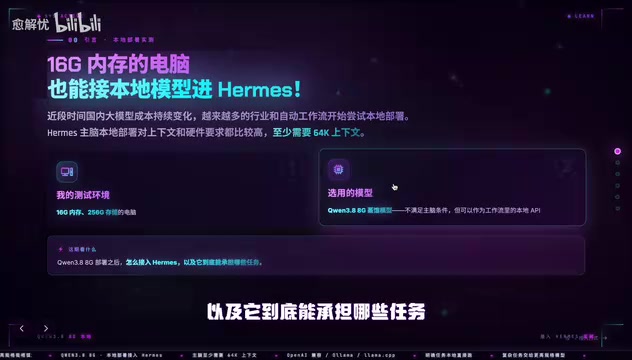
Run Hermes automation workflows on a 16GB RAM PC using Qwen3-8B distilled model as a local execution unit.
This article documents hands-on testing of integrating the Qwen3-8B distilled model into a Hermes Agent workflow on a 16GB RAM machine. Since Hermes requires at least 64K context as the main orchestrator, a layered approach is used: Hermes handles planning and scheduling while the local Qwen3-8B model serves as a local API executor for tasks like content extraction and format conversion. Three integration methods are covered — OpenAI-compatible APIs, Ollama, and llama.cpp — with emphasis on service stability as the real deployment challenge.
As the cost of using large language models continues to shift, more industries and automation workflows are exploring local deployment options. Hermes Agent (referred to as Hermes) — as the central task orchestrator — demands significant hardware resources and context window support, with a minimum requirement of 64K context. For developers working with limited hardware, figuring out how to integrate local models into this ecosystem has become a pressing challenge.
This article is based on hands-on testing by a Bilibili content creator on a machine with 16GB RAM and 256GB storage, exploring how to deploy the Qwen3-8B distilled model locally and integrate it into a Hermes workflow for real task execution.
Why Choose the Qwen3-8B Distilled Model
Hermes's context and hardware requirements mean it's simply not suited to run directly on low-spec devices. As an alternative, you can use a lightweight local model as a local API within the Hermes workflow, dedicated to handling specific execution-layer tasks.
The test machine — with 16GB RAM and 256GB storage — clearly falls short of what Hermes needs to run as the main orchestrator. That's why the creator chose the Qwen3-8B distilled model. While it can't serve as the orchestrator, it's more than capable of acting as an execution unit within the workflow. This "orchestrator + executor" division of labor is the key insight for making local deployment work on constrained hardware.
A distilled model is one produced through knowledge distillation — a technique that compresses and transfers the capabilities of a large "teacher model" into a smaller "student model." Rather than learning only from raw labeled data, the student model is trained to mimic the output distribution of the teacher, preserving as much of its reasoning ability as possible despite a dramatic reduction in parameter count. Qwen3-8B distilled was trained with a larger Qwen3 model as the teacher, and typically outperforms base models of the same size in instruction-following and reasoning quality. This is precisely why distilled models are often the better choice on low-spec hardware — more capability per parameter than their non-distilled counterparts.
Three Ways to Integrate the Local Model
Getting the model running is just the first step. There are currently three main approaches for local model deployment: running via an OpenAI-compatible API, using Ollama, or serving with llama.cpp directly. The methods differ, but the end goal is the same — enabling Hermes to reliably call the local model.
One commonly overlooked pitfall: if you launch the model but skip platform registration and API configuration, you'll likely run into connection drops, missing model errors, or failed calls. In other words, the core challenge of local deployment isn't just "getting the model running" — it's making sure it can be reliably called by upstream applications.
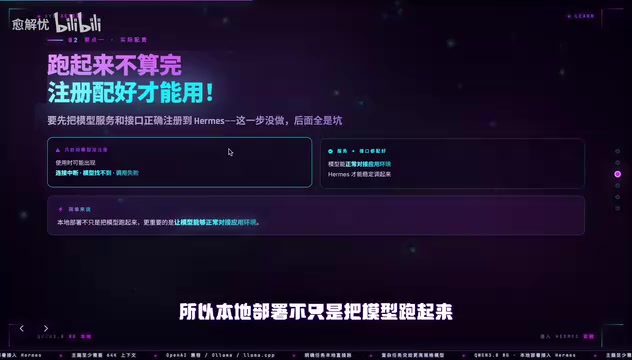
Each approach has its strengths: OpenAI-compatible APIs are HTTP endpoints exposed by local inference frameworks (such as vLLM or LM Studio) that follow the OpenAI API spec, allowing upstream applications to switch to local models without changing any code — the most broadly compatible option. Ollama is an all-in-one management tool designed specifically for local LLMs, offering a unified interface for model downloads, version management, and service startup — the most beginner-friendly option, with a built-in /api/chat endpoint supported by most major clients. llama.cpp is a high-efficiency inference engine written in C++, optimized for running quantized models (e.g., in GGUF format) on CPU-only or low-VRAM environments — the lowest resource overhead, though configuration is more low-level. All three can expose an API for Hermes to call; the choice comes down to your hardware constraints and how much operational complexity you're comfortable with.
What Tasks Can an 8B Model Handle?
After completing the integration, the creator ran practical capability tests across text generation, content organization, information extraction, basic analysis, and code generation.
The conclusions were fairly clear: as long as the task objective is well-defined, a model of this size can generally get the job done. It performs especially well on high-repetition, rule-based tasks. Content extraction, text cleanup, classification, format conversion, simple data processing, and basic coding tasks can all be handed off to it directly.
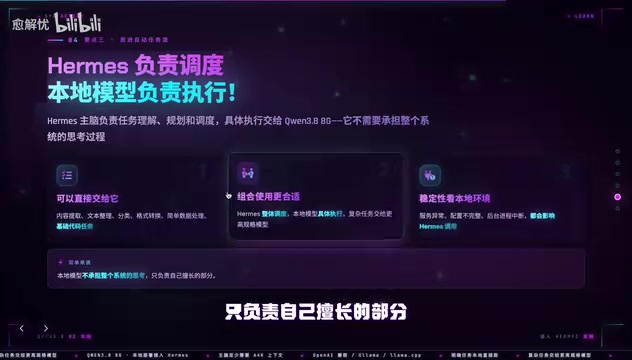
Looked at from another angle, what these tasks share is that they don't require long chains of reasoning. Local models aren't great at complex multi-step thinking, but they handle clearly scoped execution tasks with ease — and that's what makes them useful in this division-of-labor setup.
The Hermes + Local Model Division of Labor
The real value becomes apparent once the local model is embedded in Hermes's automated task pipeline. The overall logic is: Hermes handles task understanding, planning, and orchestration, then dispatches specific execution tasks to the Qwen3-8B distilled model.
This means the local model never has to carry the entire system's reasoning load — it only needs to handle what it's good at. In practice, this combination proves quite useful:
- Hermes handles overall orchestration: task decomposition, workflow planning, and deciding which tasks go where;
- The local model handles specific execution: content extraction, text cleanup, format conversion, and other clearly defined tasks;
- More capable models handle complex steps: long-context processing, complex reasoning, and multi-step tasks still need to go to stronger models.
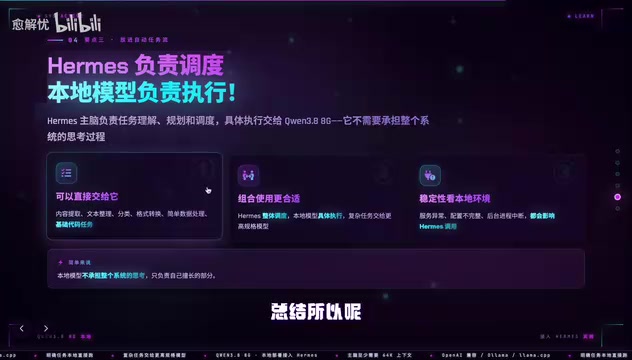
This layered scheduling controls cost while maintaining quality on complex tasks — a practical compromise for local deployment in the real world.
Hermes Agent, as the task orchestrator, operates similarly to the ReAct (Reasoning + Acting) framework: it first creates an overall plan for the user's goal, breaks the complex objective into a sequence of subtasks, then selects the appropriate tool or downstream model for each subtask based on its characteristics, and finally aggregates the results to complete the overall goal. This "plan → schedule → execute" layered architecture means the orchestrator doesn't need to personally carry out every fine-grained operation — it just maintains the global context and decision logic. That's precisely why Hermes requires a large context window (minimum 64K) and strong reasoning capabilities, while downstream execution units only need to handle single-turn tasks with limited context. An 8B local model is perfectly adequate at that layer.
Stability Is the Real Challenge of Local Deployment
One important caveat: the stability of local applications is highly dependent on the local environment. Whether you're using an OpenAI-compatible API, Ollama, or llama.cpp, any service failure, incomplete configuration, or background process interruption will directly break Hermes's call chain.
This reinforces the earlier point: the core challenge of local deployment isn't "can you start the model" — it's "once it's running, can it be called reliably and consistently." For scenarios where local models need to plug into automated workflows, ensuring service reliability deserves at least as much attention as the model's raw capabilities.
Conclusion
This hands-on test shows that while the Qwen3-8B distilled model isn't suitable as a Hermes orchestrator, it can already be put to practical use as a local execution model in certain scenarios. The right way to use it: delegate simple, repetitive, well-scoped tasks to the local model; send long-context, complex reasoning, and multi-step tasks to more capable models.
Only with this kind of division of labor can a local model truly become a valuable supporting component in an automated task pipeline, rather than a struggling stand-in pushed beyond its capabilities. For users looking to experiment with local deployment on low-spec hardware, this "orchestrator scheduling + local execution" approach is well worth considering.
Related articles
Cursor 3.0 Complete Beginner's Guide: Getting Started with AI-Powered IDE Development
Cursor 3.0 beginner's guide: from download and setup to parallel sub-agents, cloud development, skills, and automations. Master model selection, design mode, and Git with this complete AI IDE walkthrough.
Codex + Playwright as a Skill: UI Automation Without Manual Commands
Wrap Playwright as a Codex Skill so AI agents run UI automation tests via natural language. Covers install, Sauce Demo walkthrough, PO pattern, and MCP vs CLI+Skill tradeoffs.
Replicate the $400/Year 'Dedao Brain' With Obsidian + AI Agents — For Free
How to replicate Dedao Brain Expert Edition (¥2,999/year) using free Obsidian + AI agents. A breakdown of Germinate, Polish, Challenge, Style Coach, and more as reusable prompt skills.