Same AI, Two Developers: Where Does the Website Speed Gap Come From?

After swapping AI models, the website speed ranking remained unchanged, showing the performance gap stems from engineering configuration, not the model itself.
The article describes a controlled experiment: two developers built websites using Claude and Codex models respectively, and the Claude side's website was noticeably faster. To rule out the model factor, they swapped models and rebuilt, but the speed ranking did not reverse—the original developer's website was still faster. This shows the bottleneck in website performance isn't at the AI model layer, but in engineering aspects such as caching strategy, build artifact optimization, server configuration, and static asset handling. The author proposes a reusable checklist: enable server-side caching, run Lighthouse audits, and fix items one by one based on the report. The core conclusion is that embedding performance checks into the development process brings more real speed improvements than repeatedly switching models.
Two developers used the same AI to write code—one used the Claude model, the other used Codex. After testing, the Claude side's website was noticeably faster. But when they swapped models, the result was the same: the original developer's website was still faster. The difference wasn't in the model, but in a few engineering details.
After Swapping Models, the Speed Gap Persists
In the video, they ran a controlled experiment: Developer A used the Claude model, Developer B used Codex, and each built their own website. In the first round of testing, A's website loaded noticeably faster than B's.
To rule out the influence of the model itself, the two swapped models—A switched to Codex, B switched to Claude, and they rebuilt. Logically, if the speed difference came from the model, the result should have reversed.
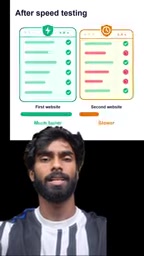
But the test results showed that A's website was still faster. In other words, switching models did not change the performance ranking.
The Real Gap Isn't in the AI, but in Engineering Configuration
This result points to an easily overlooked fact: while there are differences in the quality of code generated by AI models, the bottleneck in website performance often isn't at the model layer, but in the deployment and optimization stages.
The two developers used the same model and the same task, but the websites they delivered differed in speed. This shows that what determines performance is something beyond the code—caching strategy, the degree of build artifact optimization, server configuration, static asset handling, and so on. AI can write functionally correct code, but it won't automatically do performance tuning for you.
A common misconception is that "switching to a stronger model will produce a faster website." This experiment disproves exactly that: the same model given to different people can produce performance that differs by a wide margin.
Server-side caching is one of the most direct ways to improve response speed. The basic idea is: on the first request, the server completes rendering or data querying, stores the generated HTML or API results in memory (such as Redis) or on disk, and subsequent identical requests hit the cache directly, skipping the full rendering process. Common strategies include setting a reasonable TTL (time-to-live), generating cache keys based on URL or query parameters, and actively invalidating the cache when content is updated. For static sites, you can also combine with a CDN for edge caching, so requests are answered at nodes closer to the user. The risk of improper cache configuration is returning stale content, so you need to distinguish which pages can be cached long-term and which must be generated in real time.
A Reusable Performance Checklist
In the conclusion, the video's author provides a checklist for diagnosing and improving website performance:
- Enable server-side caching: So that repeated requests don't have to go through the full rendering process every time, reducing response time.
- Run a LighthouseAd audit: Use Lighthouse to systematically check pages, identify issues in performance, accessibility, and other areas, then fix them one by one according to the report.
- Follow up on fixes based on audit results: After getting Lighthouse scores and recommendations, address high-priority items specifically, rather than optimizing by gut feeling.
These three steps don't depend on any particular AI model and are general engineering practices. Whether you use Claude or Codex, a website that has these configurations in place will be faster.
Lighthouse is an open-source automated web quality auditing tool from Google, integrated into Chrome DevTools and also runnable via command line or in CI environments. It scores a single page across dimensions such as performance, accessibility, best practices, and SEO. The performance score is calculated as a weighted combination of Core Web Vitals metrics including First Contentful Paint, Largest Contentful Paint, Total Blocking Time, and Cumulative Layout Shift. The report lists specific items that can be optimized, such as uncompressed images, render-blocking scripts, and unused CSS. Note that Lighthouse scores in a local simulated environment differ from real user data, so it's better suited as a starting point for identifying problems rather than the sole performance standard.
Implications for AI-Assisted Development
The value of this experiment lies in separating "AI writes code" from "website performance." The model is responsible for generating logic; performance depends on engineering decisions. If developers focus only on prompts and model selection, they may discover slow page loads only after functionality is complete—and the root cause is often that caching was never configured and audits were never run from the start.
Building performance checks into the development process—for example, always running Lighthouse before deployment and enabling server-side caching by default—brings more real speed improvements than repeatedly switching models. The video's author also provides the full prompt in the description, which interested readers can use themselves.
Build artifact optimization is another main line of front-end performance. Modern frameworks generate a large number of JS/CSS files during build; if left unhandled, the resources that need to be downloaded and parsed for the first screen will significantly slow loading. Common practices include: code splitting (splitting by route or component, loading only necessary code for the first screen), tree shaking (removing unreferenced exports), minification and obfuscation (reducing file size), and using asset fingerprinting with long-term cache headers. In addition, images should be converted to modern formats such as WebP/AVIF and sized appropriately, and fonts can be subsetted or loading behavior controlled with font-display. Most of these steps can be configured once in the build toolchain—an engineering investment that pays off long-term.
One-line Summary
After swapping AI models, the website speed ranking didn't change, showing that the performance gap stems from engineering configuration rather than the model itself.
Paragraph Summary
The article describes a controlled experiment: two developers built websites using the Claude and Codex models respectively, and the Claude side's website was noticeably faster. To rule out the model factor, the two swapped models and rebuilt, but the speed ranking did not reverse—the original developer's website was still faster. This shows that the bottleneck in website performance isn't at the AI model layer, but in engineering aspects such as caching strategy, build artifact optimization, server configuration, and static asset handling. Based on this, the author proposes a reusable checklist: enable server-side caching, run Lighthouse audits, and fix items one by one according to the report. The core conclusion is that embedding performance checks into the development process brings more real speed improvements than repeatedly switching models.
Related articles
 Tech Frontiers
Coldframe: A Honeypot Disguised as a Supermarket Freezer Controller
Coldframe is a honeypot disguised as Danfoss AK-SM 800A and Dixell XWEB freezer controllers, built as a single Python file that detects CVE-2025-41450 attempts and is identified as real devices on Shodan.
 Tech Frontiers
GRFNet: A Lightweight PyTorch Model Designed for Multichannel Time-Series Classification
GRFNet is a lightweight PyTorch model for multichannel time-series classification, originating from EEG decoding research. With only 3,847 parameters, it is based on the ROCKET architecture, combining random convolution kernels with learnable spatial filters, supports arbitrary input lengths, and will soon be evaluated on the PhysioNet dataset.
 Tech Frontiers
CUDA-Accelerated Rocket League Simulator: A Player-Made Hardcore Experiment
A Reddit post shows a "100% Accurate" Rocket League simulator accelerated with CUDA. We analyze its technical context, CUDA's value in game physics simulation, and the significance and limitations of such community projects.