SketchAgentBench: Evaluating LLM 3D Spatial Reasoning with Sketches

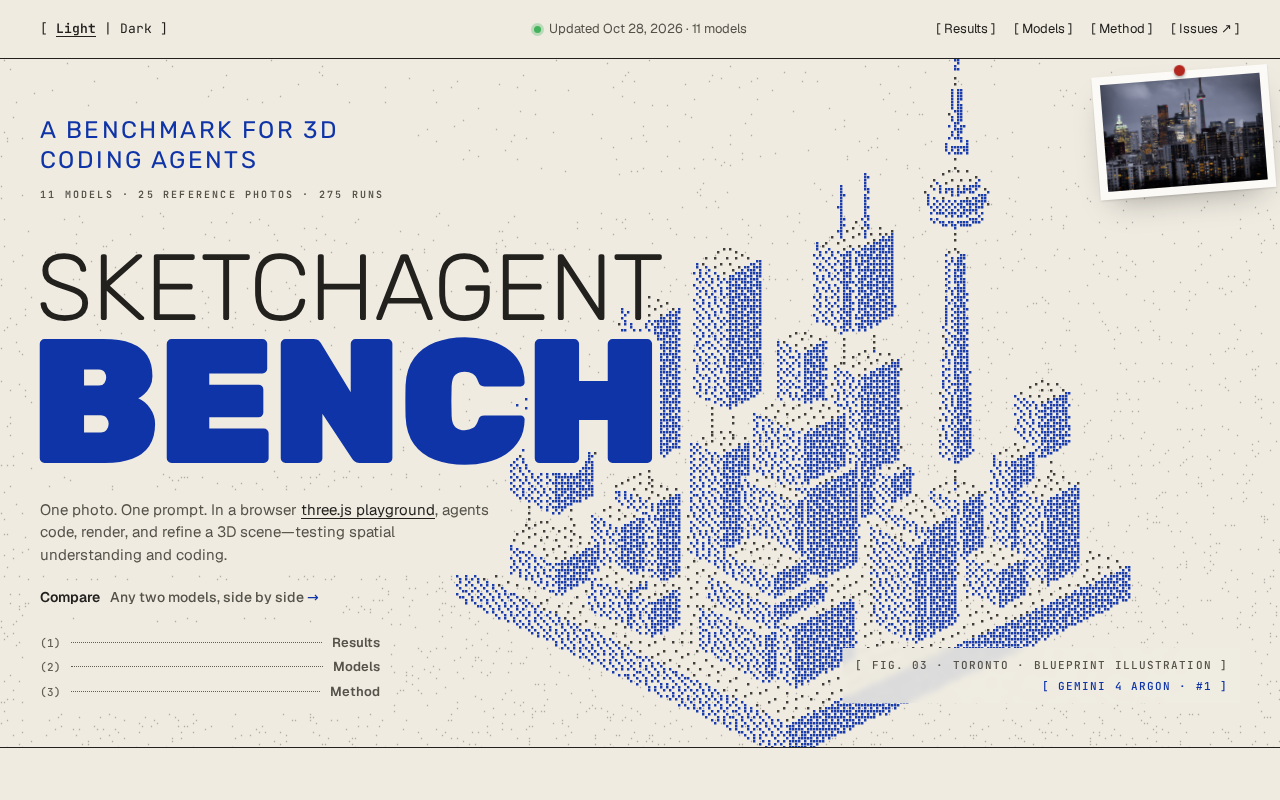
SketchAgentBench evaluates LLM 3D spatial reasoning through sketch tasks, filling a benchmark gap.
The article introduces SketchAgentBench, a benchmark suite seen on Hacker News that uses sketch tasks to assess large language models' 3D spatial reasoning. Existing benchmarks mostly focus on language or 2D vision tasks and lack systematic examination of the cognitive process from sketch to 3D structure. SketchAgentBench leverages spatial cues inherent in sketches, such as viewpoint, occlusion, and proportion, to distinguish genuine geometric understanding from language pattern matching. The article infers possible evaluation dimensions including 2D-to-3D inference, spatial relationship judgment, and sketch generation or modification, and emphasizes the foundational role of spatial reasoning in embodied intelligence and robot navigation. It also cautions that task design and scoring criteria have not yet been disclosed, so conclusions should be interpreted carefully.
Why do we need a dedicated benchmark for LLM 3D spatial reasoning?
Large language models perform impressively on tasks like text understanding and code generation, but their capability boundaries remain unclear when it comes to 3D spatial imagination and reasoning. Existing benchmarks mostly focus on language or 2D vision tasks and lack a systematic examination of the cognitive process of "going from sketch to 3D structure."
SketchAgentBench, which appeared on Hacker News, targets exactly this gap: it evaluates LLMs' 3D spatial reasoning through sketch tasks, offering researchers a reproducible evaluation perspective.
What is SketchAgentBench?
Based on the project name and release information, SketchAgentBench is a benchmark suite for LLMs. Its core idea is to have models handle sketch-related spatial tasks, thereby testing whether they truly understand 3D geometric relationships rather than merely relying on language pattern matching.
As a low-barrier, information-dense form of expression, sketches naturally contain spatial cues such as viewpoint, occlusion, and proportion. Requiring models to reason from sketches can expose their weaknesses in spatial representation.
Possible evaluation dimensions
Although the original material does not detail the specific task design, the keyword "3D spatial reasoning" suggests that the evaluation may involve inferring 3D structure from 2D sketches, judging spatial relationships between objects, and generating or modifying sketches from descriptions. Together, these tasks point to one goal: distinguishing "seems to understand" from "actually understands."
Common evaluation paradigms for spatial reasoning benchmarks
In 3D spatial reasoning benchmarks, task design usually revolves around several classic paradigms. The first is mental rotation, in which the model judges which option matches a 3D object after rotation, testing its ability to perform mental operations on geometric transformations. The second is spatial relationship judgment, which asks the model questions such as "is A to the left of/above/behind B," often involving the selection and transformation of reference frames. The third is occlusion and visibility reasoning, which requires judging from a specific viewpoint which parts are visible and which are occluded, demanding that the model build viewpoint-dependent scene representations. The fourth is 2D-to-3D mapping, such as inferring an object's 3D structure from multi-view sketches or a single line drawing. Together, these paradigms form a multidimensional evaluation framework for spatial cognition, and they also explain why sketches are a suitable test medium: sketches naturally carry viewpoint and proportion information and can elicit these kinds of reasoning at low cost.
Significance for the AI research community
Spatial reasoning is a foundational capability for applications such as embodied intelligence, robot navigation, and 3D content generation. A benchmark focused on this area can help researchers compare different models and drive targeted improvements in spatial understanding.
Although the discussion on Hacker News is still early (Points: 5), the emergence of such a benchmark itself sends a signal: the community is beginning to value evaluating LLMs on non-linguistic dimensions.
The relationship between embodied intelligence and spatial reasoning
Embodied AI emphasizes agents that learn and make decisions through interaction with the physical environment, and one of its core challenges is spatial understanding. Robots need to localize themselves in 3D space, plan paths, and estimate object distances and affordances, all of which rely on robust spatial reasoning. Current mainstream large language models are essentially processors of symbols and textual patterns and lack direct perception of and operational experience in physical space. Therefore, using benchmarks to quantify LLM performance on spatial tasks is effectively probing the feasibility boundary of transferring from "language intelligence" to "embodied intelligence." If a model can make correct spatial judgments on sketches based solely on language priors, it suggests that some transferable spatial representation may have formed internally; if not, it indicates that dedicated 3D perception modules or multimodal training may be needed. Such benchmarks therefore become important diagnostic tools connecting pure language model research with embodied applications.
Limitations and open questions
Public information is currently limited, and details such as the number of specific tasks, scoring criteria, and the list of evaluated models have not yet been disclosed. This means interpretations of its conclusions should remain cautious. Points worth watching include whether the tasks cover spatial relationships of varying difficulty, whether evaluation results correlate with real-world application performance, and whether the benchmark is open source and reproducible.
Reproducibility and validity issues in benchmark evaluation
For a newly released benchmark, beyond the number of tasks and scoring criteria, two methodological issues deserve attention. The first is reproducibility: whether the benchmark is open source, whether evaluation scripts are public, and whether random seeds and data splits are clearly specified determine whether other researchers can independently verify the conclusions. The second is construct validity: whether the scores measured by the benchmark truly correspond to the target capability of "3D spatial reasoning," rather than the model overfitting to task formats or linguistic cues. For example, if the textual description of a sketch already contains enough information, the model may bypass visual spatial reasoning and score well through language reasoning alone. In addition, the correlation between benchmark performance and real-world application performance needs to be cross-validated through downstream tasks such as robot navigation success rates. Until the details are disclosed, conclusions from any single benchmark should be treated with caution.
Conclusion
SketchAgentBench uses "sketches" as a probe to enter the relatively unexplored evaluation area of LLM 3D spatial reasoning. Its value lies not in providing final answers, but in raising a question worth following up on: how far are language models from true spatial intelligence?
Related articles
 Tech Frontiers
Sherlock: An Open-Source Tool for Tracking Usernames Across Social Networks
Sherlock is an open-source Python tool that tracks social accounts across networks by username. This article covers its core features, why developers love it, typical use cases, and privacy compliance considerations.
 Tech Frontiers
GitHub Daily·Nov 07: Agent-Ready and Context Compression
GitHub Trending Nov 07: meta's agent-ready design system astryx, billion-context's 5x context compression, sherlock nearing 100k stars, plus local-first localthings and bare-metal GPU orchestration nvke.
 Tech Frontiers
Buoyant Open-Sources Kinference: An Inference Control Plane for vLLM on K8s
Buoyant open-sources Kinference, an inference control plane for vLLM on Kubernetes, with declarative routing, KV-cache-aware load balancing, and per-tenant metrics—claiming 95% lower median TTFT in official benchmarks.