Small Models Fail at Structured Output: Why They Copy Prompt Labels Instead of Schema Enum Values

Small models in structured output tend to copy prompt labels instead of enum values, requiring real-call testing and fault-tolerant design.
The article describes a typical problem a developer encountered when using cheap small models (such as Gemini Flash) for structured output: the model directly copied the natural language label "At risk" from the prompt as output instead of following the enum value `risk` defined in the Schema, causing the strict parser to discard the entire response. Unit tests all passed because they used manually compliant inputs, exposing a testing blind spot. The author analyzes why small models' attention mechanisms are easily drawn to prominent labels and proposes three solutions: placing enum values adjacent to labels in the prompt, normalizing synonyms in the parser, and running real-model boundary tests after changes. Community discussion further suggests using format examples or mechanisms such as function calling, emphasizing that small models require extra engineering effort to compensate for format control limitations.
The Problem Emerges: A "small" mistake that cost a developer a day
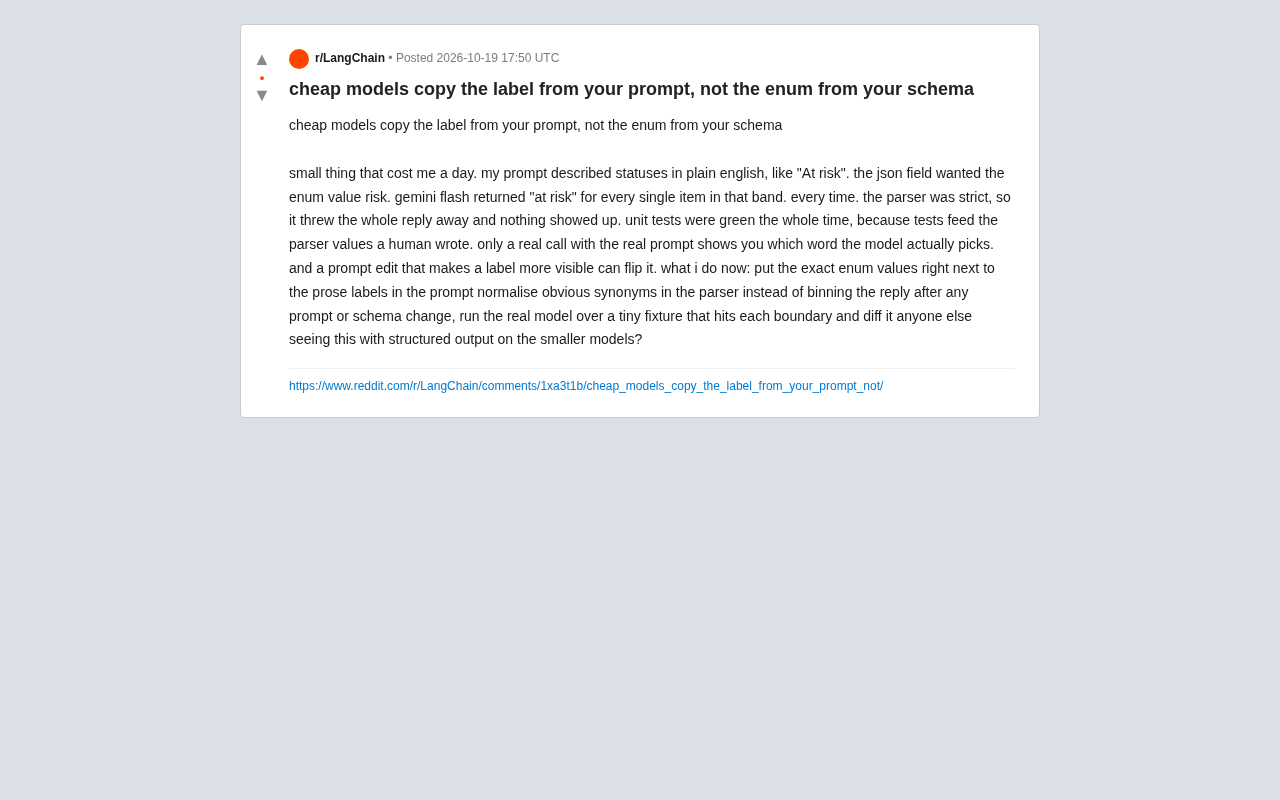
Recently on Reddit, a developer shared a pitfall they encountered while using cheap small models (like Gemini Flash) for structured output: the prompt described the status in natural language as "At risk," but the JSON field required the enum value risk. As a result, the model returned "at risk" for every entry, causing the strict parser to discard the entire response and leaving the page blank. More frustratingly, the unit tests always passed because the test parser input was human-written compliant values. Only by calling the real model with the real prompt could it be exposed which word the model actually chose.
This case is not an isolated incident. Many developers relying on small models for structured data extraction have encountered similar issues: the model tends to copy the prominent text labels in the prompt rather than following the enum values defined in the Schema. This reflects the inherent limitations of small models in instruction following and format control.
Why Do Small Models "Copy Labels" Instead of "Using Enums"?
When generating structured output, large language models need to handle both semantic understanding and format constraints simultaneously. For models with fewer parameters, their attention mechanism is more easily drawn to natural language labels that are repeated or prominently positioned in the prompt, while relatively ignoring the cold enum definitions in the Schema.
The developer pointed out that prompt editing also affects model choice—if a label is more prominent in the prompt, the model may flip to that word. This explains why simply adjusting prompt wording leads to unstable output. Small models lack strong robustness and struggle to maintain consistency under multiple constraints.
Testing Blind Spot: Why Did All Unit Tests Pass?
Traditional unit tests typically use manually constructed compliant inputs to verify parser logic, but never test the model's actual output. This creates a blind spot: the parser works fine for human input but may completely fail for model output. Only end-to-end real calls can reveal the problem.
Structured Output refers to having large language models generate data according to a predefined schema (such as JSON Schema) rather than free text. Common implementations include prompt constraints, function calling, and dedicated output parsers (such as LangChain's Pydantic parser). The core challenge is that the model needs to satisfy both semantic correctness and format compliance during generation, and small models, due to limited parameter capacity, have weaker instruction-following ability under multiple constraints and tend to "take shortcuts"—directly copying high-frequency text from the prompt rather than strictly looking up enum definitions in the Schema.
Enum values in JSON Schema are used to restrict a field to a predefined set of values, for example {"risk": ["low", "medium", "high"]}. Strict parsers validate enum values during deserialization and throw an error or discard the entire response if there is a mismatch. This design is intended to ensure data quality, but in small model scenarios it amplifies the consequences of format deviations.
End-to-End Testing is crucial in such scenarios because it covers the complete chain from prompt construction and model invocation to parser processing. Traditional unit tests only verify the parser's response to manually constructed compliant inputs, which is "component testing" and cannot reflect what the model actually generates. For systems relying on non-deterministic model output, it is recommended to adopt a "contract testing" approach: use real model calls to generate a batch of samples, then verify whether the parser can correctly handle these samples and compare the results with expected enum values. This can effectively detect model behavior drift and prompt sensitivity.
Practical Solutions: Three Ways to Avoid Enum Failures
Based on community discussion and their own experience, the developer summarized three effective measures worth adopting.
1. Place Exact Enum Values Adjacent to Natural Language Labels in the Prompt
Don't just define enums in the Schema; also provide the enum value when describing the status in the prompt. For example: "Status: At risk (corresponding enum value: risk)." This way, when the model copies the label, it also has a chance to see the correct enum value.
The "proximity principle" in prompt engineering: During generation, models tend to reference context closer to the current generation position. Placing enum values adjacent to natural language labels can reduce the probability of the model "hesitating" between the two. In addition, using explicit format markers (such as [enum value: risk]) or structured prompts (such as XML tags) can further reinforce constraints. However, note that excessively piling up enum values may increase prompt length and put pressure on the small model's context window and attention allocation, so this technique should be prioritized for key fields.
2. Normalize Obvious Synonyms in the Parser Rather Than Discarding Directly
Rather than having the parser strictly reject any non-enum value, it is better to add a normalization layer that maps common variants such as "at risk" and "At Risk" to risk. This improves fault tolerance and prevents the entire response from being discarded due to minor model deviations. Of course, normalization rules need to be designed carefully to avoid incorrect mappings.
3. Run Small Boundary Tests with the Real Model After Changes and Compare Differences
After any prompt or Schema change, you should use a micro test set covering every boundary, call the real model, and compare output differences. This can capture model behavior changes in time and prevent regressions. The developer emphasized: "Only a real call can tell you which word the model actually chose."
Community Resonance and Lessons
The post sparked considerable discussion, with many developers saying they had encountered similar problems, especially when using smaller models for structured output. Some suggested using explicit format examples in the prompt, while others emphasized choosing stronger models or using mechanisms such as function calling to enforce format.
This case reminds us that when relying on small models for structured output, we cannot assume they will strictly follow the Schema. Robust pipelines must be built through real-call testing, prompt optimization, and parser fault tolerance. For cost-sensitive scenarios, small models still have value, but extra engineering effort is needed to compensate for their limitations.
Have you encountered similar problems when using small models? Feel free to share your experience and solutions.
Function Calling is a native mechanism that lets models output structured parameters, where the model directly generates JSON that conforms to the function signature rather than free text. Compared with prompt constraints, function calling is usually specifically optimized by model providers during training, resulting in higher format compliance. However, small models may have incomplete support or poor performance for function calling, and enum value deviations can still occur. Another approach is to use an Output Parser combined with a retry mechanism: when parsing fails, automatically feed the error information back to the model and request regeneration, but this increases latency and cost.
One-line Summary
Small models in structured output tend to copy prompt labels instead of enum values, requiring real-call testing and fault-tolerant design.
Paragraph Summary
The article describes a typical problem a developer encountered when using cheap small models (such as Gemini Flash) for structured output: the model directly copied the natural language label "At risk" from the prompt as output instead of following the enum value risk defined in the Schema, causing the strict parser to discard the entire response. Unit tests all passed because they used manually compliant inputs, exposing a testing blind spot. The author analyzes why small models' attention mechanisms are easily drawn to prominent labels and proposes three solutions: placing enum values adjacent to labels in the prompt, normalizing synonyms in the parser, and running real-model boundary tests after changes. Community discussion further suggests using format examples or mechanisms such as function calling, emphasizing that small models require extra engineering effort to compensate for format control limitations.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.