Someone Keeps Using Public Torrent Sites to Mess With My Sonarr: A Maintenance Log for Automated TV Tracking

Sonarr gets targeted by junk releases because its automation pipeline over-trusts public indexers—tightening boundaries is the fix.
The article describes how Sonarr suffered junk release pollution after connecting to public torrent sites. Symptoms include index results not matching expected episodes, with junk releases often mimicking legitimate release group names, having abnormal file sizes, and coming from newly registered uploader accounts. Sonarr's predictable automated behavior makes it a target for junk feeding—this isn't a vulnerability but a structural risk of exposing automation to an open community. The article proposes three countermeasures: tightening indexers and configuring release group whitelists, enabling delayed downloads with manual confirmation, and relying on scoring and size validation. The core lesson is that the more effortless automation becomes, the more it needs boundaries—defaulting to complete trust on the open internet is like leaving a back door.
Sonarr is a core tool for many self-hosted media library enthusiasts. It monitors show updates, automatically matches releases, and pushes them to the download client. But once you connect its indexers to public torrent sites, the trouble often doesn't come from misconfiguration—it comes from people on the other side of the screen deliberately planting junk releases.
The problem this time wasn't that Sonarr crashed, but that it worked too well—so well that it became an attack surface.
Polluted Index Results
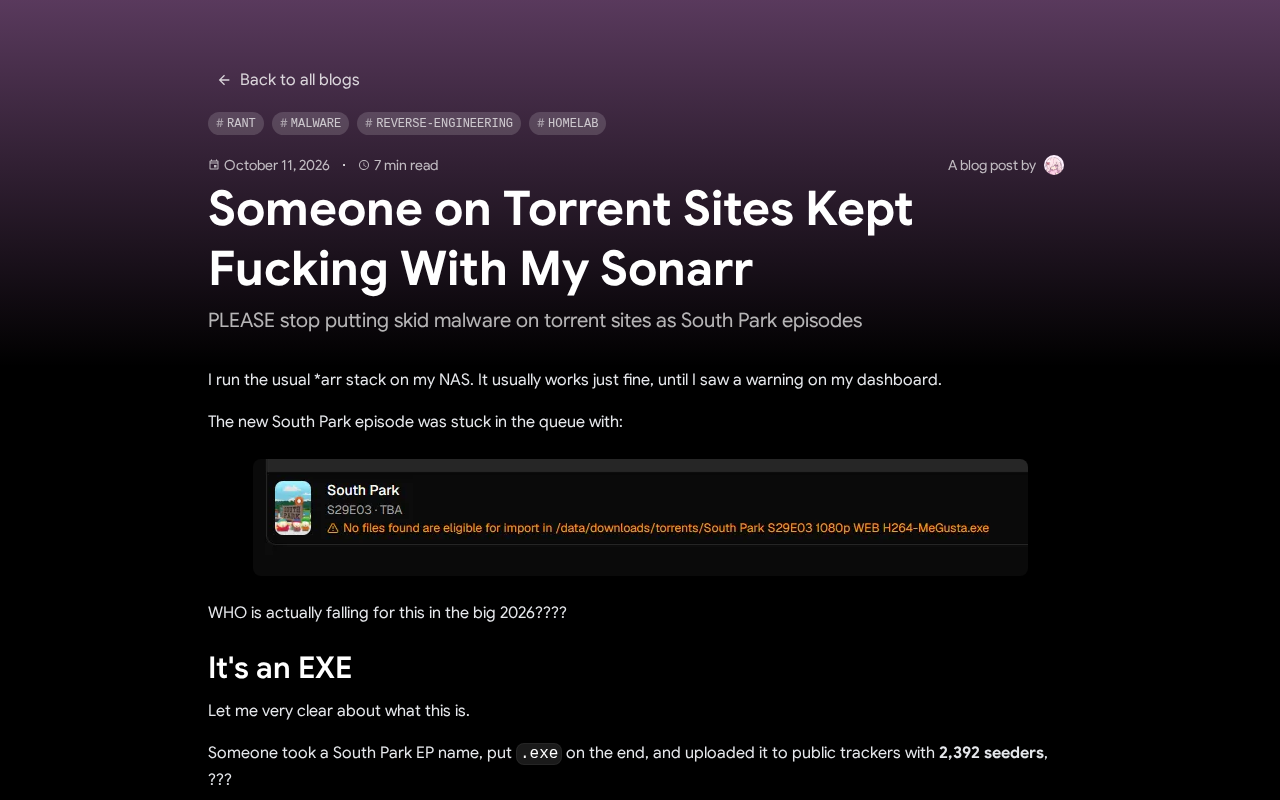
The first symptoms were mild: the episodes Sonarr grabbed didn't match expectations. The titles looked plausible, but the files were completely unrelated content, or fake torrents with abnormal sizes.
These releases usually share a few traits:
- Titles deliberately mimic the naming conventions of legitimate release groups
- File sizes are absurdly larger or smaller than normal episodes
- The uploader account is newly registered with an empty history
Their goal isn't as straightforward as getting you to download a virus. It's to waste your bandwidth, disk space, and the trust your automation pipeline places in them.
About Indexers and the RSS Mechanism
Sonarr itself doesn't store releases. It relies on "indexers" to search for episodes. An indexer is essentially a set of configurations that tells Sonarr where to look for releases and how to parse the returned results. Common indexer types include Torznab, Newznab, and custom implementations for specific sites. Public torrent sites typically provide search results via RSS or API, and Sonarr periodically pulls these results and compares them against your local episode library. Precisely because index results are external data, their quality depends entirely on how well the site is moderated. Public sites lack review, anyone can upload, so junk releases mixed into RSS results are the norm rather than the exception. Understanding this makes it clear why the root of the problem isn't Sonarr's parsing logic, but the trustworthiness of the upstream data.
Why Sonarr Becomes a Target
Sonarr's behavior pattern is highly predictable: it searches and downloads from indexers according to your configured quality preferences, resolution standards, and release time window.
Once someone figures out this pattern, they can reverse-engineer which show you might be following and roughly when downloads will be triggered. Public torrent sites have no entry barriers—anyone can upload—so automation tools become targets for junk feeding.
This isn't a vulnerability in Sonarr. It's the structural risk of exposing an automated pipeline to an open community.
What Actually Works
Tighten Indexers and Release Group Whitelists
The most direct approach is to reduce the number of indexers, keeping only the more reputable sites, and configure a release group whitelist in Sonarr to exclude known junk uploaders.
What Is a Release Group Whitelist
A release group is the signature used when a release is packaged and published, usually appearing at the end of a filename, like -GROUP. Legitimate release groups have long-standing naming conventions and reputations, while junk uploaders tend to pick random names that look legitimate. Sonarr allows you to specify "preferred" or "must contain" release group lists in settings, and you can also set a blacklist to exclude known junk groups. The purpose of a whitelist isn't to guarantee content is always correct, but to narrow the search scope to sources with track records that can be traced. Combined with indexer priority settings, you can have Sonarr query trusted sites first, reducing the odds of hitting low-quality results.
Enable Delayed Download and Manual Confirmation
For unfamiliar sources, you can enable delayed grabbing so Sonarr marks releases first without immediately pushing them to the download client. That window is enough for you to manually check whether the title and size look reasonable.
Rely on Scoring and Size Validation
Sonarr's built-in scoring mechanism can rate releases based on dimensions like resolution, codec, and release group. Combined with size range limits, it can filter out a large number of obviously abnormal entries.
How Sonarr's Scoring Mechanism Works
Sonarr's scoring system rates each search result across multiple dimensions, including resolution, source (such as WEB-DL, BluRay), codec format (H.264, H.265), release group, and whether it includes multi-language audio tracks. Users can customize the weight of each dimension and set a minimum score threshold—releases below the threshold are discarded outright. Size validation is a separate layer of filtering. By setting minimum/maximum file sizes for single episodes or full seasons, you can exclude fake torrents with obviously abnormal sizes. When used together, scoring handles "quality preference" while size handles "sanity checking," covering most low-effort junk uploads.
The Bigger Lesson
What this really exposed is this: the more effortless automation becomes, the more it needs boundaries.
Sonarr itself isn't the problem. The problem is treating "complete trust" as the default setting. Public indexers, unrestricted release groups, automatic downloads all in one go—this combo feels great in an ideal environment, but on the open internet it leaves a back door for others.
For anyone running a self-hosted media library, spending ten minutes tightening indexers and scoring rules is far more worthwhile than cleaning up junk files everywhere after the fact.
Trust Boundaries in Automated Pipelines
Any automated system implicitly carries a set of trust assumptions. Sonarr by default trusts the results returned by indexers, trusts release group naming, and trusts that file sizes match content. On closed or semi-closed private sites, these assumptions largely hold. Once you connect to a fully open public network, those assumptions become attack surfaces. Similar structural problems aren't unique to Sonarr—email filtering, web crawlers, and CI/CD pipelines all face the same challenge. The general approach is to introduce "zero trust" principles: set verification points at every stage instead of letting everything through end-to-end. For media library enthusiasts, this means leaving a manual or rule-based check at each of the three stages—indexing, filtering, and downloading—rather than handing all decision-making power to the tool.
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.