Tencent Hunyuan Hy4 Officially Released: Near Sweeping Benchmark Leads, Adds Vision and Computer Operation Capabilities

Tencent Hunyuan Hy4 official version released, adding vision and computer operation capabilities for the first time; benchmarks enter China's first tier but weaknesses remain on high-difficulty tasks.
The official version of Tencent Hunyuan Hy4 has been released, with the company claiming it ranks among the strongest open-source models for the first time. Compared with the preview version, Hy4 scaled up pre-training and post-training and added vision and computer operation capabilities for the first time, with clear improvements in instruction following, long-text understanding, long-horizon task handling, and deep research. Twelve benchmarks show it basically leads or ties DeepSeek and Kimi, falling significantly behind K3.1 Pro only on Terminal Bench Science 0.1. In research practice, Hy4 found counterexamples to multiple mathematical conjectures and completed 3D reconstruction of mouse embryos. On safety, it used defensive data training and showed no prominent cyberattack risks. Pricing is 6 yuan per million input tokens, 18 yuan per million output tokens, and 0.3 yuan for cache hits, higher than DeepSeek. Third-party evaluations have not yet been released, and actual experience remains to be tested.
The official version of Tencent Hunyuan Hy4 has finally landed. The company claims this is the first time a Hunyuan model has ranked among the strongest open-source models. Compared with the preview version, Hy4 further scaled up pre-training and post-training, and added vision capabilities for the first time, with notable improvements in instruction following, long-text understanding, long-horizon task handling, and deep research.
According to 12 benchmarks compiled by a Bilibili creator, Hy4 basically leads or ties with DeepSeekAd and Kimi, falling significantly behind K3.1 Pro only on Terminal Bench Science 0.1. Overall, its scores put it in China's first tier.
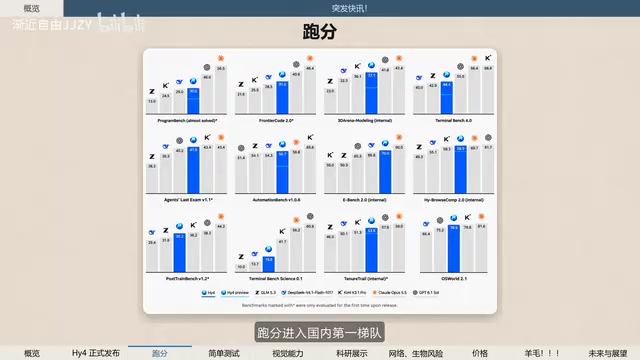
Benchmark Analysis: Agents Shine, but Hard Programming and Research Remain Weak Spots
Official benchmarks show Hy4 performs outstandingly on agent-type tasks, consistent with the industry's current emphasis on agent execution capability. However, the creator also stated bluntly that it "still has obvious shortcomings in high-difficulty programming and scientific research capabilities," and cautioned, "Let's wait and see the actual user experience—hopefully it's not just another benchmark chaser."
Currently only official benchmarks are public; third-party evaluations such as Artificial Analysis and Arena have yet to be released. A few simple test compilations shared by the creator suggest the actual experience "seems not as good as DeepSeek," but more authoritative independent evaluation is still needed for verification.
Terminal Bench Science 0.1 is a terminal-operation benchmark aimed at scientific research scenarios. It requires models to complete multi-step tasks related to scientific computing in a simulated Linux terminal environment, such as installing dependencies, running scripts, and parsing experimental data. It simultaneously tests command-line proficiency, long-horizon task planning, and error recovery, so it is often used to measure a model's agent execution level. Hy4 falls significantly behind K3.1 Pro on this item, indicating that there is still clear room for improvement in its stability and toolchain usage in long-horizon terminal tasks.
Artificial Analysis and Arena (i.e., LMArena) are two commonly cited independent evaluation sources. The former provides overall capability and price-efficiency rankings based on a standardized benchmark suite, while the latter relies on real users voting on anonymous pairwise model comparisons to form an Elo-style ranking, which is closer to subjective user experience. The two complement official benchmarks and can reduce selective reporting bias by model providers on self-selected test sets. The article emphasizes that these two third-party results have not yet been released, meaning current judgments about Hy4 are still based mainly on official data and should be viewed with caution.
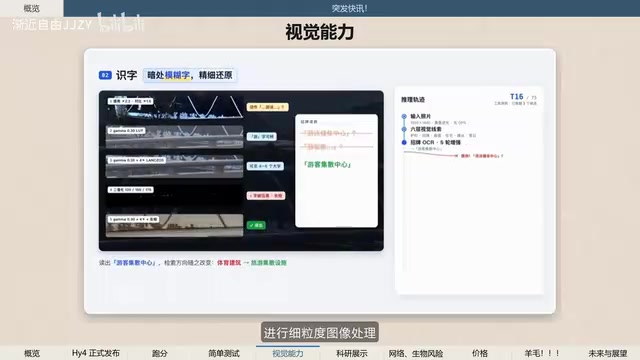
Vision Debut: Complex Chart Analysis and Mathematical Visual Reasoning
Hy4 introduces vision capabilities for the first time, enabling multimodal processing that combines perception, reasoning, and tool invocation, covering tasks such as complex chart analysis and mathematical visual reasoning. This capability also significantly benefits Hy4's front-end and game development scenarios—visual understanding can help the model more accurately parse interface layouts and design mockups.
Computer Operation Capability: Flexible Combination of Command Line and Graphical Interface
Hy4 supports computer operation for the first time, allowing it to flexibly combine command-line instructions with visual understanding of graphical interfaces to complete tasks. This means the model is no longer limited to text conversations but can operate software interfaces like a human, opening up possibilities for automated office work, testing, and other scenarios.
Research in Practice: From Mathematical Conjectures to Biological Imaging Reconstruction
In collaborative research with a mathematics team at Peking University, Hy4 successfully found counterexamples to the Mandace, Pinto, and Villa Real conjectures, further proposed new conditions to refine the conjecture, and also formalized and verified the related proofs.
In a mouse embryo 3D reconstruction task involving 84 unordered 2D slices of 6.99 million cells, with no specialized registration tools and no cell type annotations, Hy4 also completed the task. These two cases demonstrate its potential for long-horizon scientific research tasks.
Formal verification refers to translating mathematical propositions and their proofs into checkable languages for proof assistants such as Lean and Coq, with the machine verifying step by step whether each inference is valid. It can eliminate implicit assumptions and clerical errors in manual proofs, but requires that the proposition itself can be precisely formalized. Hy4's formal verification of conjecture-related proofs shows that it can not only generate natural-language arguments but also produce code acceptable to proof assistants, which is an important signal for evaluating a model's mathematical rigor.
Safety and Pricing: Defensive Data Training, Priced Higher Than DeepSeek
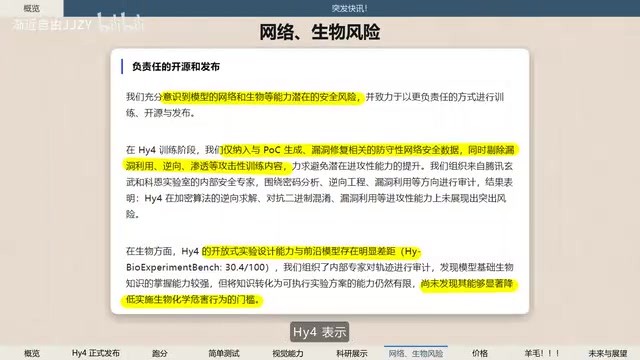
On safety, Hy4 states that only defensive cybersecurity data was used during training, excluding offensive content such as exploit and penetration material. After review by safety experts, the model did not show prominent risks in cyberattack capability. In biosecurity, although Hy4 possesses relatively strong foundational knowledge, its ability to translate knowledge into executable experimental protocols is limited, and no evidence was found that it would significantly lower the threshold for carrying out biochemical harm.
On pricing, Hy4 costs 6 yuan per million input tokens, 18 yuan per million output tokens, and 0.3 yuan for cache hits. The creator said bluntly, "This price is way more expensive than DeepSeek," but estimated that the actual experience gap would not be too large and that the value of the package is worth watching.
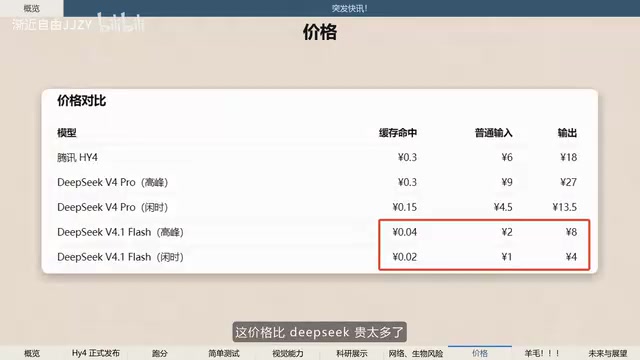
Cache-hit pricing is a discount mechanism in API billing: when the prompt prefix of a request is highly repetitive with recent requests, the server can directly reuse cached intermediate computation results, thereby billing at a price far lower than normal input. Hy4's cache-hit price is 0.3 yuan per million tokens, only one-twentieth of the normal input price, suitable for scenarios with long system prompts, multi-turn conversations, or repeated queries over fixed documents. When comparing prices, actual cache hit rates should be considered; looking only at input and output unit prices may overestimate real usage costs.
Access Channels and Awareness of Gaps
Tencent WorkBuddyAd has officially launched the Hy4 official version, with free trial access from November 4 to November 15. The creator notes that queuing may be required.
Although Hy4 is already one of the strongest open-source models currently available, there is still a large gap between it and top closed-source models, especially on high-difficulty test sets used in internal testing, such as frontier mathematics, long-horizon development, model iteration, and visual question answering. For developers, Hy4's value lies in open-source accessibility and its newly added vision and computer operation capabilities. Whether the actual experience can match the benchmarks still needs third-party evaluation and real-world testing.
Related articles

DeepSeek Harness Quick Start Guide: From Installation to 5 Real-World Cases
What is DeepSeek Harness? Based on a Bilibili tutorial, this article covers how this AI Agents software works, installation and setup, four working modes, and five real-world cases: a 3D racing game, official website, music player, science animation, and self-developed plugin—plus token money-saving tips.

Breaking Down DeepSeek's Super-agent Architecture: How Router+Worker Solves the Multi-Session Management Bottleneck
An analysis of DeepSeek's Super-agent paper: how the Router+Worker two-tier architecture uses Fast Pass, Chain of Recall, and storage-compute separation to solve multi-AI-session management bottlenecks, and how much it truly alleviates the human attention bottleneck and what engineering trade-offs it makes.

19K Stars in 5 Days: Why DeepSeek's Open-Source AI Programmer Went Viral
DeepSeek's open-source AI programmer hit 19K GitHub stars in 5 days. Why it went viral: the agent boom, AI writing its own code, and the shift from Q&A tools to AI employees.