The Best Model Race Is Over: Where AI's Real Moat Lies in 2026

Prediction markets and industry signals show the model layer has commoditized — the real moats are agent frameworks, data flywheels, and distribution.
Polymarket's "best model" year-end contract shows a rare 42-42 tie, while the betting crowd is overwhelmingly skewed toward Anthropic at 93% on agent contracts — a clear signal that the model layer is commoditizing and durable advantage lies elsewhere. Nikita Bier, Marc Andreessen, and Tom Tunguz all agree technical moats are dead; Meta Muse Wonder's commodity pricing directly undercuts frontier competitors. The article identifies three moats that still work: agent frameworks and orchestration, proprietary interaction-data flywheels, and distribution with network effects. Anthropic's annualized revenue jumping from ~$9 billion to over $44 billion, driven by agent products like Claude Code, confirms value is migrating from the model layer to the framework layer.
Prediction Markets Have Already Given the Answer
There's a prediction market on Polymarket asking a seemingly simple question: which company will have the best AI model at the end of each month? The October 2026 data tells a story the AI hype cycle doesn't want to hear. The "best model" contract crashed 56.5% this month, with Google leading Anthropic 71% to 26%, while the year-end contract is a dead heat — Google 42%, Anthropic 42%, OpenAI just 9%. The betting crowd has effectively written OpenAI out of the year-end championship race. No one can hold the lead for more than a few weeks.
The market has $1.6 million in liquidity, making it the most-watched AI leaderboard contract, swinging wildly all month. Google surged from just over 30% to 71% in early October, while Anthropic fell from above 80% to 26%.
But the number that really matters is this: the year-end contract is a perfect 42-42 tie. Not a slight lead, not a narrow advantage — a literal coin flip.
Compare that to the agent market: Anthropic at 93%, OpenAI at 4%, Google at 3%. The model market is a coin flip; the agent market is a landslide. Prediction markets have already figured out where durable advantage lives — and it's not at the model layer.
Polymarket and How Prediction Markets Work
Polymarket is a decentralized prediction market built on blockchain (the Polygon network), where users buy "shares" in an event outcome using USDC stablecoins, with prices ranging from $0 to $1 — directly corresponding to the market's implied probability. For example, if a contract is quoted at 0.71, it means the betting crowd believes the event has a 71% chance of occurring. Since these shares can be bought and sold at any time before the event resolves, prices fluctuate in real time with new information and trading activity, making prediction markets a kind of "put your real money where your mouth is" aggregator of crowd expectations.
Compared to expert interviews or analyst reports, the advantage of prediction markets is that participants bear real economic consequences, which suppresses the noise of off-the-cuff opinions; they also have a solid calibration record, long outperforming polls on elections, sports, and macro events. The "best model" contract mentioned here has liquidity as high as $1.6 million, meaning this price signal has enough depth to support it, and a single large trade can't instantly distort the market. Understanding this is essential to grasping why the author treats Polymarket data as a more credible industry signal than benchmark leaderboards.
"Technical Moats Are Basically Dead"
Nikita Bier — who just stepped down as X's head of product after launching 30 products — said it bluntly this week: "Technical moats are basically dead at this point. If you're building something meant to last, the only moats now are: proprietary data, network effects, physical components." The post racked up 22,000 likes and 2.1 million views.
He's not the only one saying this. Tom Tunguz found that 84% of tokens on OpenRouter flow to non-state-of-the-art models. Six models offering roughly 77% of frontier performance at 2.5% of Claude Fable 5's price carry the vast majority of usage. Token usage has grown about 50% since July, while prices dropped 41%.
Marc Andreessen said at a16z's LP meeting that "the technical moats that used to last a decade now last a quarter." He argues the model itself is the replaceable part. At SaaStr AI Annual 2026, practitioners from six industries reached the same conclusion: model capabilities are now accessible to any developer and no longer separate winners from losers.
Cognition (the $26 billion company behind Devon) president Russell Kaplan made the point from a different angle in a LangChain conversation: the question "which model is best?" is itself completely wrong. What matters is what you build around the model — the agent framework, the evaluation loop, the recovery paths.
Meta Muse Wonder: The Commoditization Clock Hits Zero
Meta's timing couldn't be more symbolic. Muse Wonder launched at commoditization pricing — $4 per million input tokens, $20 per million output tokens — directly undercutting OpenAI and Anthropic. By comparison, this is roughly on par with Claude Opus 5.5's input cost and 60% lower than GPT-6 Astra.
The discussion on Hacker News reads like a eulogy for model differentiation. The top-voted comment hits the same theme: "If this model isn't benchmark-gaming, I worry that Anthropic, OpenAI, etc. are done. They're not unique, and many other companies will likely ship similar models soon." Another commenter points out the pricing: "$4 input, $0.20 cached input, $20 output," noting it's on par with frontier competitors.
One commenter captured the broader dynamic: "The more companies that approach the frontier, the better. If only one company gets to call the shots after achieving recursive self-improvement, that leads to extreme concentration of power."
This is exactly the moment Benedict Evans predicted when he argued the only economic moat leading AI labs had was access to capital. The models themselves were destined to converge. The question was always how fast.
Token Pricing and What "Commoditization Pricing" Means
LLM APIs typically charge by token, and a token is the smallest unit of text a model processes, roughly corresponding to part of an English word or a Chinese character. Pricing is split into input (the prompt submitted to the model) and output (the content the model generates), with output usually more expensive because decoding is more computationally intensive. "$4 per million input tokens, $20 per million output tokens" is a commonly used industry pricing unit.
So-called "commoditization pricing" refers to the economic phenomenon where product prices converge toward marginal cost and vendors struggle to command a premium through differentiation — similar to electricity or bulk commodities. Meta Muse Wonder entering at a price on par with or even lower than frontier competitors means it's no longer trying to position itself as "I'm stronger," but directly acknowledging that model capabilities are highly homogeneous and that price war is now the main battlefield. The article specifically notes that input cost is roughly on par with Claude Opus 5.5 and 60% lower than GPT-6 Astra, which puts direct pressure on OpenAI's and Anthropic's premium pricing strategies and makes the "model as moat" narrative even harder to sustain.
Three Moats That Actually Work
If models aren't moats, what is? After reviewing more than 15 sources spanning prediction markets, VC analysis, and practitioner conferences, three categories consistently emerge. But they're not all created equal.
1. Agent Systems and Orchestration (The Framework Layer)
Microsoft calls it the "framework" — the infrastructure that wraps around any model and makes it useful in a specific enterprise environment. This includes memory, tool routing, sandboxing, permission policies, recovery paths, and the agent loop itself.
The key insight is: Swapping out a model is easy. Swapping out a framework you've spent a year training is hard. The framework accumulates customer interactions, workflow configurations, and institutional knowledge. This data flywheel creates real switching costs.
In a16z's State of AI conversation, Anish Acharya argued that traditional moats like network effects, scale, and brand still apply — but they apply to what's built around models, not the models themselves. Applications that combine different types of intelligence create more value than any single model.
The Polymarket data intuitively supports this. The model market is a coin flip. The agent market — Anthropic at 93% — is the widest gap across all AI prediction markets. The market is pricing in that Claude Code, computer use, and the agent SDK have already built an orchestration moat that no model swap can erode.
Agent Frameworks, Orchestration, and Data Flywheels
An "AI agent" refers to an AI system capable of autonomously planning, calling tools, executing multi-step tasks, and handling failures — not just one-shot Q&A. What makes it actually usable in real business is the "framework" or "orchestration layer" built around the model: including memory systems (remembering past interactions), tool routing (deciding when to call search, databases, or code execution), sandboxing (safely isolated execution environments), permission policies (controlling what the agent can access), and recovery paths (how to retry or fall back when things go wrong).
A "data flywheel" describes a self-reinforcing positive loop: usage generates interaction data, data improves the product, and improvements attract more usage. In agent scenarios, this means every customer session teaches the system how to better route tasks, understand team preferences, and handle specific failures. This accumulated context and configuration makes it hard for competitors to replicate the operating results even if they swap in an equivalent or even better model. This is exactly what the article means by "swapping out a model is easy, swapping out a framework you've trained for a year is hard" — the switching cost shifts from model quality to integration depth and institutional knowledge.
2. Proprietary Data Flywheels
Data has always been the answer, but the kind of data that matters has changed. Not training data — anyone can scrape the internet. It's interaction data: what users do with the model, which outputs they accept or reject, how they configure their workflows.
Nathan Lambert of Interconnects points out that obtaining high-quality, diverse fine-tuning prompts is something open-source projects struggle to replicate. Companies whose users interact with their models build moats through data and habits.
The community debate is fierce. On Blind, engineers at frontier labs are asking a blunt question: "Does Anthropic really have a moat, or is the IPO narrative just self-soothing?" The consensus there splits into two camps: one sees a talent moat in frontier R&D, the other believes the raw foundation models are rapidly commoditizing.
Sacra's OpenRouter analysis shows this dynamic: Chinese open-source models now account for over 50% of all tokens on OpenRouter, yet Anthropic's models — just 12% of traffic — generate 46% of revenue. Customers paying a premium are paying for what the model itself can't provide: integrated workflows, reliability guarantees, and accumulated context.
3. Distribution and Network Effects
Nikita Bier's three moats — proprietary data, network effects, and physical components — are essentially the same framework Warren Buffett applied to Coca-Cola. The AI-specific twist is that distribution now means integration depth. AI tools embedded in someone's CI/CD pipeline, code editor, or business workflow create switching costs regardless of model quality.
As Hackaday documented, technical moats are eroding from both ends — quantized open-weight models are closing the gap from below, while frontier labs converge from above.
This is why Evan Spiegel told Lenny's podcast that distribution is the most important moat in consumer tech. When every competitor has access to the same frontier models, the company with the best distribution channels wins.
The Contrarian Corner: The Revenue Paradox
The "models have commoditized" consensus has one unsettling problem: Anthropic's annualized revenue reportedly grew from about $9 billion at the end of 2025 to over $44 billion by mid-2026. Someone is paying a massive premium for the "best" models.
The resolution may be simpler than it looks. Anthropic's revenue growth is driven by Claude Code and enterprise API contracts — framework and agent products, not raw model access. The revenue data and the prediction market data are actually telling the same story: value is at the agent layer, and Anthropic happens to have won that race, while the model race is a coin flip.
But if cheaper models from Meta or open-weight competitors can plug into those same agent workflows, the revenue premium is fragile. The Polymarket crowd's 42-42 tie is a bet that model parity will eventually compress even the premium tier.
What This Means for Builders
If you're building AI-native products or integrating AI into an existing business, the "best model" race should be irrelevant to your strategy. Here's what to do instead:
Stop evaluating models. Start evaluating frameworks. The model you use will change every quarter. The orchestration layer — how you route tasks, manage context, handle failures, accumulate user data — is where compounding happens. Invest there.
Build a data flywheel, not a data lake. Static training data is a depreciating asset. Interaction data that improves your product with every use is a compounding asset. Every user session should make your agent smarter, your routing more efficient, your failure recovery more robust.
Make switching expensive (in a good way). If your customers can swap your AI tool for a competitor's in an afternoon, you don't have a moat. Deep workflow integration — connecting to their specific data sources, learning their team's preferences, encoding their business logic — creates switching costs regardless of which model you're running underneath.
Watch the Polymarket agent market. It's the best real-time signal for where durable AI advantage lives. When the model market is a coin flip and the agent market is a landslide, the market is telling you something benchmark leaderboards can't.
The litmus test: If your competitive advantage disappears when your model provider ships a cheaper version, you never had a moat. The moat is everything except the model.
The Race That Replaced the Race
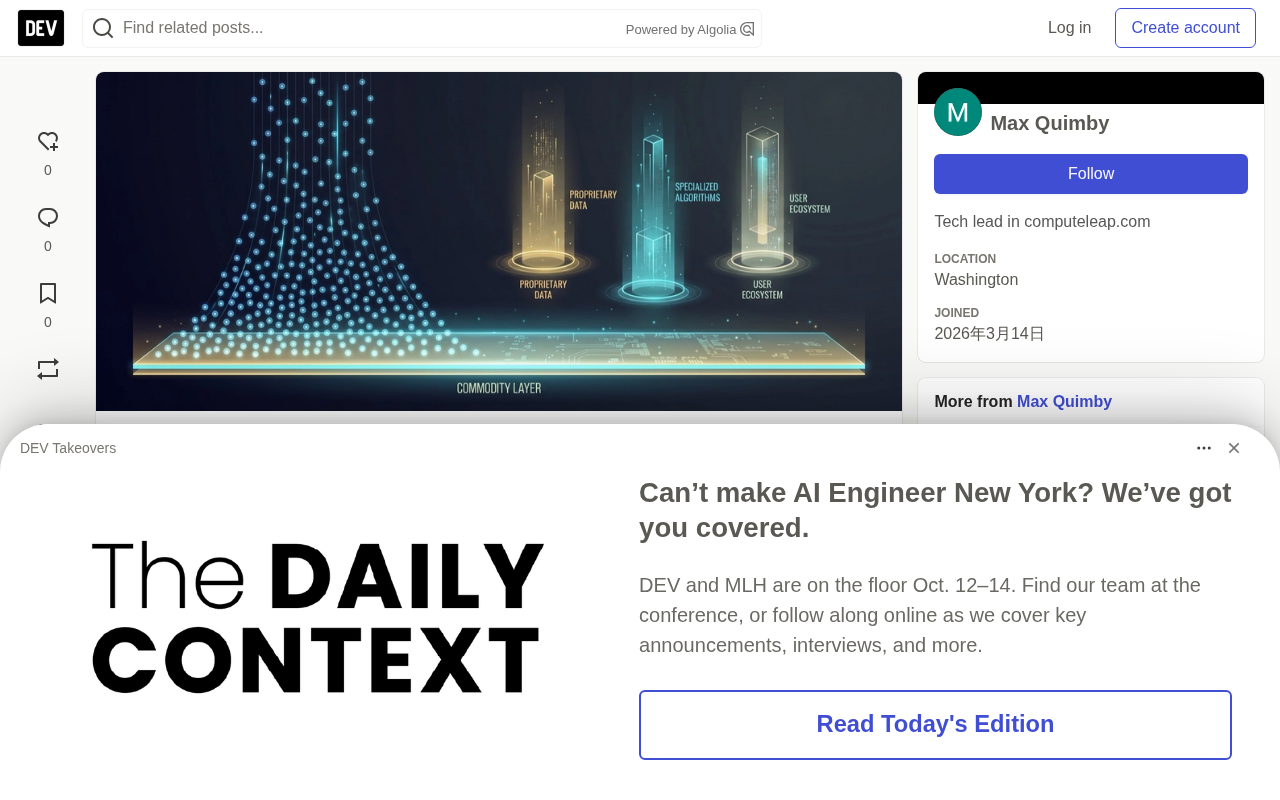
The "best model" race didn't end because models stopped improving. It ended because improvements stopped mattering at the margin. When Google, Anthropic, Meta, and OpenAI all produce frontier-class models within weeks of each other — when the Polymarket year-end contract is literally 42-42 — the model layer has become infrastructure. Important, necessary, and utterly insufficient.
The new race is frameworks, data flywheels, and distribution channels. It's less thrilling than the benchmark wars. It won't produce breathless headlines about which model is 0.3% better on some leaderboard. But it's exactly where real value — the durable, defensible, compounding kind — is being built.
The prediction markets already know this. The question is whether you do.
Background
Economic Moats and the "Non-SOTA Model" Cost-Performance Paradox
The concept of a "moat" was popularized by Warren Buffett and refers to structural advantages that let a company fend off competition and sustain excess profits over the long term — such as brand, patents, economies of scale, or high customer switching costs. When Nikita Bier says "technical moats are over," he means the window for maintaining an advantage purely through model weights or algorithmic leadership is closing.
The data Tom Tunguz observed further confirms this: 84% of tokens on OpenRouter flow to non-state-of-the-art models. OpenRouter is a gateway platform aggregating APIs from multiple model providers, letting developers call different vendors' models through a unified interface with token-based billing. The key finding is that models delivering about 77% of frontier performance at just 2.5% of the price carry the vast majority of real-world calls. This shows that in actual production scenarios, most tasks don't require top-tier reasoning; cost, latency, and reliability often matter more than leaderboard rank. When a "good enough" model is cheap enough, the room for differentiation between model providers shrinks dramatically — this is the quantitative evidence of commoditization pressure.
One-line Summary
Prediction markets and industry signals show the model layer has commoditized — the real moats are agent frameworks, data flywheels, and distribution.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.