The Embryonic Form of AGI Has Emerged: The Three Missing Puzzle Pieces Behind GPT-6 Astra's 99.9% Score

GPT-6 Astra scored 99.9% on abstract reasoning tests, but AGI still lacks three crucial puzzle pieces.
The article clarifies three commonly confused concepts: AI is a task-specific tool with clear boundaries, AGI requires human-like cross-domain learning and autonomous goal-setting, and superintelligence comprehensively surpasses humans. GPT-6 Astra's 99.9% on the AIC to AGI-3 test proves near-perfect abstract reasoning, but the author emphasizes that a high score on a single test doesn't equal achieving general intelligence. What's still missing for true AGI: physical world interaction, autonomous goal-setting, and continuous growth. For ordinary people, the conclusion isn't panic but spending two hours a week actually using AI tools to build familiarity during the embryonic period.
AI, AGI, and Superintelligence: Three Words, Three Stages
AI, AGI, superintelligence — these three terms are being used interchangeably across the internet, but most people haven't truly grasped their boundaries. Recently, GPT-6 Astra scored 99.9% on a test called AIC to AGI-3, once again making "Has AGI arrived?" a hot topic of debate. After a calm analysis, the conclusion is clear: we are indeed standing at AGI's doorstep, but the door hasn't opened yet.
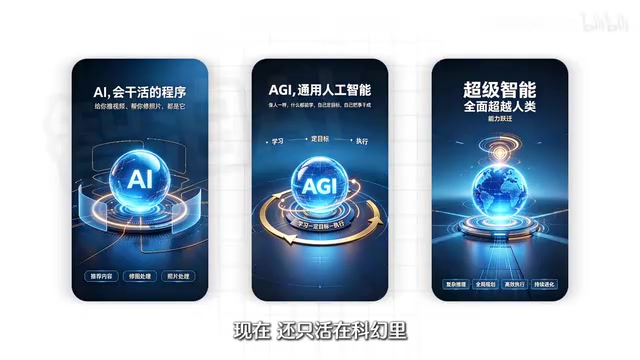
AI is the most commonly used concept today, referring to programs that do specific tasks — recommending videos, retouching photos, generating copy. Its defining feature is clear task boundaries and predictable capability ranges.
AGI (Artificial General Intelligence) requires a system to learn anything the way a human does, to set its own goals and accomplish things on its own. It's not confined to a single task but possesses cross-domain transferability.
Superintelligence is a higher-level imagination: comprehensively surpassing humans, currently existing only in science fiction. According to analysis from Bilibili tutorials, the heated discussions across the internet are actually focused on the second level — AGI.
The three are not three ways of describing the same thing, but three rungs of capability leap. Confusing them leads to misjudging where the technology truly stands.
What Does a 99.9% Test Score Mean?
What truly caused a stir was GPT-6 Astra's performance on the AIC to AGI-3 test. This test specifically examines "generalizing from one example" — presenting problems never seen before to see if the system can figure out the rules on its own. This is precisely humanity's most prized cognitive ability.
When AI approaches a perfect score, it naturally prompts the question: Has AGI arrived?
The answer needs to be examined in layers. The test score demonstrates a breakthrough in the model's abstract reasoning and pattern generalization — one of AGI's core capabilities. But a high score on one test does not equal the comprehensive achievement of general intelligence.
About tests like AIC to AGI-3: To measure whether AI possesses general intelligence, academia typically uses a series of benchmarks such as ARC (Abstraction and Reasoning Corpus), MMLU, BIG-bench, and others. The design logic of these tests is: problems don't rely on patterns seen in training data but require the system to induce rules on its own from a small number of examples — what's known as "few-shot generalization" or "out-of-distribution reasoning." Because of this, they better reflect a model's ability to "generalize from one example" than traditional exam scores. However, any single benchmark carries the risk of being "gamed": the model may have implicitly encountered similar problem types during training, or bypassed genuine reasoning through search, prompt engineering, or other means. Therefore, a 99.9% score strictly speaking only indicates that the model performs excellently within that test's problem distribution — it cannot be directly equated with general intelligence. Evaluating AGI requires a multi-dimensional combination of tests, with continuously updated question banks to prevent overfitting.
The Three Missing Puzzle Pieces from AGI
The sober conclusion is: AGI's embryonic form has appeared, but AGI itself has not yet arrived. What exactly is missing? At least three puzzle pieces remain unfilled.
Piece One: The Physical World
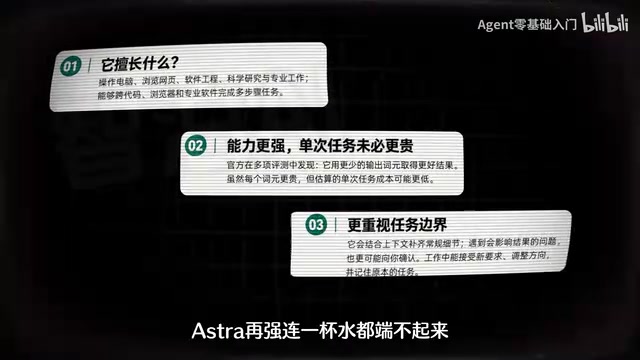
No matter how powerful Astra is, it can't even pick up a glass of water. The robotics track has only just begun, and there's a massive gap between embodied intelligence and language model capabilities. Reasoning ability in the virtual world cannot be directly transferred to physical operations.
Embodied AI refers to intelligent systems that have a physical body and can interact with the real world through sensors and actuators. Its fundamental difference from pure language models is: language models process symbols and text, while embodied intelligence must contend with gravity, friction, object shapes, real-time feedback, and other physical constraints. Moravec's paradox points out that for AI, high-level reasoning is actually easier than low-level perception and motor control — playing chess can defeat humans, but folding clothes and holding a water glass are extremely difficult. Current robot learning mainly relies on reinforcement learning and imitation learning, and remains fragile when generalizing to new objects and new environments. Therefore, even if language models approach perfect scores in abstract reasoning, embodied intelligence progress remains slow, and the capability gap between the two is one of the key obstacles on the path to AGI.
Piece Two: Autonomous Goals
Current "autonomy" means you give a goal, and it executes. It won't suddenly announce one day, "I want to do something." True AGI needs intrinsic goal-setting capability, rather than passively responding to instructions.
Intrinsic Goal Setting is an often overlooked but crucial dimension in AGI definitions. Current large language models are essentially "goal-conditioned" systems: you give them a prompt or task, and they generate output; without external instructions, they won't proactively generate intentions. True autonomous agents need to be able to independently generate, prioritize, and pursue goals based on environmental states, their own knowledge, and long-term preferences. In cognitive science, this corresponds to "agency" and "intentionality." Technically, this involves metacognition, intrinsic motivation, and the balance between exploration and exploitation. The deeper question is: once a system can set its own goals, how do we ensure those goals align with human values? This is not only a technical challenge but also a core issue in the field of AI safety.
Piece Three: Continuous Growth
It finishes a job, and its memory resets to zero. Today's genius, tomorrow's amnesiac. Lacking mechanisms for continuous learning and experience accumulation means the system cannot grow over time the way humans do.
These three puzzle pieces correspond to physical interaction, goal autonomy, and memory continuity — each striking at the core of AGI's definition.
Continual Learning, also known as lifelong learning, refers to a model continuously learning new tasks without forgetting old knowledge. Current mainstream AI adopts a "train-deploy" separated model: after training is complete, parameters are frozen, and weights are not updated during inference, so memory is lost at the end of each conversation. To achieve continuous growth, the problem of "catastrophic forgetting" must be solved — new data training overwrites old knowledge. Possible paths include: dynamic network expansion, memory replay, parameter isolation, and the combination of external memory banks with retrieval-augmented generation (RAG). But even if technically feasible, continual learning also involves safety and controllability: a system that continuously self-updates will have its behavioral boundaries drift over time, posing new challenges for alignment and regulation.
What Ordinary People Should Actually Do
Calibrating anxiety is more realistic than eliminating it. You don't need to fear being replaced tomorrow, but you should be wary of the massive changes five years from now.
Consider the trajectory of smartphone adoption: from being able to access the internet to being indispensable to everyone took five years. And AI iterates much faster than phones.
There's only one thing ordinary people should do right now: spend two hours a week actually getting hands-on with these tools. If you're not familiar with it during the embryonic period, it won't need you once it matures.
This isn't alarmist talk — it's a plain reminder from the technology adoption curve: only those familiar with the tools are qualified to talk about mastering them.
Frequently Asked Questions
Has AGI arrived now?
No. The accurate statement is that AGI's embryonic form has appeared, but the three puzzle pieces — physical world interaction, autonomous goal setting, and continuous growth — have not yet been filled in.
What does GPT-6 Astra's 99.9% score indicate?
It indicates the model approaches a perfect score on abstract reasoning tests that require generalizing from one example, which is a breakthrough in AGI's core capability — but it does not equal the comprehensive achievement of AGI.
What should ordinary people do right now?
Spend two hours a week actually getting hands-on with AI tools, building familiarity during the embryonic period to avoid being left behind when it matures.
Related articles

Understanding DeepSeek in 3 Minutes: The Rise from a Quant Hedge Fund to an Open-Source AI Leader
DeepSeek's history in 3 minutes: from High-Flyer Quant's compute build-up to V2's MLA inference cost cuts, V3's $5.576M training bill, R1's open-source global shock, and V4 with a $7B Series A.

Local Creative Writing Model Showdown: Fine-tuned Qwen3.8 27B Wins, DeepSeek v4.1 Underwhelms
Bilibili creator tests seven local creative writing models: Hemingway and HumanLike Chat based on Qwen3.8 27B perform best, DeepSeek v4.1 is plain, Dongfang Shuo ranks last with confused characters. Includes three test prompts, scores, and usage advice.

Liang Wenfeng's Three Big Bets: Why Did DeepSeek Open-Source Its 82% Gross Margin?
Why did DeepSeek open-source DeepInfer, its 82% gross margin inference framework, and then launch a hundred-billion funding round? An analysis of Liang Wenfeng's three big bets and the open-source strategy.