The Truth About AI Coding: Code Output Soars, So Why Is Delivery Still Hard to Speed Up?

AI drives a surge in code output, but delivery bottlenecks shift to review, compliance, and infrastructure as enterprises enter cost accountability.
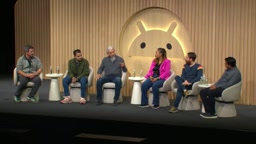
At a roundtable hosted by Android DevRel, engineering leaders from Databricks, Google Maps, Ford, Uber, and Instacart agreed that AI coding tools massively accelerate code output, but whether this translates to business value remains unproven. As coding speeds up, bottlenecks shift to code review, compliance, release, and CI/CD infrastructure—Uber even said "CI is crying every night." Participants debated whether agents can replace code review, but agreed on the need for safety nets like feature flags and observability. On costs, Ford, Uber, and Databricks have adopted token limits, approvals, and model routing for fine-grained governance. For legacy systems, they advise investing in prompt and context optimization like managing technical debt.
Code Output Soars, But the Definition of "Delivery" Is Being Reexamined
At a recent roundtable hosted by Android DevRel, engineering leaders from Databricks, Google Maps, Ford, Uber, and Instacart reached a rare consensus: AI coding tools have indeed driven a "massive acceleration" in code output, but whether this equates to faster delivery of business value is something the entire industry is still figuring out.
According to Databricks' Vinay Kumar, PR counts and lines of code have seen "massive acceleration," even putting pressure on infrastructure like code storage to scale up. He revealed that his team has shipped more code in the past six months than in a long stretch before that. But he immediately poured cold water on it: "What's not obvious is what impact this actually has on business outcomes."
This confusion is not an isolated case. Google Maps' Luis Artol pointed out that the key question is "are we delivering features faster, or just delivering code faster?" Early signals suggest the former is happening, but the way to measure it is very different from simply counting PRs.
The Bottleneck Shifts: From Writing Code to Review, Compliance, and Release
Once the coding step is massively accelerated by AI, a counterintuitive phenomenon emerges: the entire delivery chain doesn't speed up proportionally, because the bottleneck has shifted downstream.
Ford's Anise Davis used a vivid metaphor to describe this experience: "It's like you're on a highway in a major city and you hit a bottleneck. Then you start speeding up, thinking great, I'm going so fast. But then you immediately hit the next bottleneck." She noted that AI makes these friction points more visible, and many of them have nothing to do with code or technology—they're process and people problems.
Uber's Ty Smith confirmed this from the perspective of developer infrastructure. Half-jokingly, he said: "My CI is crying every night." As code volume surges, build, test, and deployment systems are under enormous pressure to scale and become more efficient, and teams are catching up with approaches like remote build execution and cache optimization.
Instacart's Kaushik Gopal offered a sharper judgment: "Engineering was never the bottleneck." He believes the real bottleneck in the past was vague business requirements and repeated back-and-forth between product and design, and that the biggest speedups from AI actually happen in compliance work and legacy system upgrades, not new feature delivery.
CI/CD (Continuous Integration/Continuous Delivery) is a core practice in modern software engineering: every time a developer commits code, the system automatically triggers a build, runs tests, performs static checks, and deploys changes to various environments through a pipeline. It compresses what used to take days of manual integration and release work into minutes, making it highly sensitive to code volume—when AI multiplies daily commit counts, build machine queues, test case execution time, and environment deployment frequency all expand proportionally. Ty Smith's remark that "CI is crying every night" is a vivid portrayal of pipeline capacity being overwhelmed by the flood of code. Common industry responses include remote build execution (distributing compilation tasks to elastic compute pools), build caching and incremental compilation (rebuilding only changed modules), and test sharding and parallelization. This also explains why, after coding speeds up, the bottleneck systematically shifts downstream to infrastructure.
The Future of Code Review: From "Everyone LGTM" to Intelligent Verification
One of the most controversial topics in the roundtable was code review. When AI can generate massive numbers of PRs, is traditional line-by-line human review still sustainable?
Kaushik was blunt: "If we're honest with ourselves, about 70% of the PRs I've looked at are 'looks good to me.' If you search PR comments across codebases worldwide, it's LGTM everywhere." His view is that since human review is often a formality, we might as well let agents do the same thing—or even do it better.
Vinay framed code review as a "verification problem": "In a world where I have full confidence in my verification capabilities, would I still review 100% of my PRs? Probably not." He noted that code review serves two functions—verification and education—and that a large portion of this work can be accelerated or even automated.
But Luis drew a distinction between "good friction" and "bad friction." He believes review still falls into the "good friction" category, and the key is to reduce its burden rather than eliminate it. A better path is to use AI to improve the quality of upstream inputs—clearer architectural understanding, more solid specifications—so that the resulting code is higher quality and review naturally goes more smoothly.
Ty added a key prerequisite: all of this depends on engineering systems having sufficient safety nets. "We already have feature flags, blue-green deployments, and observability—it's just that this data is scattered across different systems." He believes that once data on incident tracking, behavior monitoring, and more can be integrated into a complete engineering context, even if a PR is merged directly, safety can be ensured through guardrails in the pipeline.
Feature Flags are a mechanism that decouples code deployment from feature release: new code can be merged into the main branch and deployed to production first, but kept invisible to users via configuration switches, then gradually rolled out once sufficiently validated. Combined with blue-green deployment (maintaining two identical production environments, validating the new version in the "green" environment first, then switching all traffic over from "blue" once it passes) and observability (continuously observing the system's real behavior through logs, metrics, and tracing), teams gain the ability to detect and roll back problems promptly even after code is merged quickly. This is exactly the technical basis for Ty Smith's argument that "even if the PR just gets merged, it's safe": the value of a safety net is not in preventing changes, but in making the cost of failed changes controllable, reversible, and observable. Without this layer of infrastructure, loosening review is equivalent to running naked.
Token Economics: From "Use Freely" to Fine-Grained Governance
When the discussion turned to cost control, the atmosphere became noticeably more pragmatic. Several panelists confirmed that enterprise AI coding has moved from the "experimentation phase" to the "accountability phase."
Anise revealed that after a year of widespread experimentation, Ford began imposing token limits on developers starting in September of that year, along with usage dashboards to help developers understand what a "healthy session" looks like. She compared the current stage to the early days of cloud computing: "It's like when AWS first came out, we all spun up instances freely, and it ended up costing the company a lot of money. It's the same with tokens now."
Uber's approach is more flexible: after developers hit their limit, they can submit a justification with one click for manager approval. Ty emphasized that this is not just about controlling costs, but also about getting engineers to think about whether their model choice is reasonable—"You don't need the most cutting-edge model to tell you the time or switch git branches."
Databricks adopted a combination of "model routing + frontier budget." Vinay explained that the platform team doesn't want to be the decision-maker, but rather uses daily limits as a "tripwire" that developers can unlock themselves; a monthly budget cap is set for the most cutting-edge models, with overages requiring manager approval. The ultimate goal is automatic model routing, so developers don't have to worry about cost decisions at all.
Tokens are the basic unit of measurement for how large language models process text, roughly corresponding to a word or part of a word; every completion, conversation, and agent execution in an AI coding tool consumes input and output tokens and is billed by volume. Model Routing refers to the platform automatically dispatching requests to models of different tiers based on task complexity: simple tasks (like changing a time format or switching git branches) go to cheaper small models, while complex reasoning calls on expensive frontier models. This tiered strategy can significantly reduce costs without sacrificing experience, and it's the technical path Databricks is pursuing to ensure "developers don't have to worry about cost decisions." It's worth noting that quota governance isn't just about the bill—it also shapes developer behavior in reverse: when usage is visible and limits are clear, engineers will more consciously assess "does this task really need the strongest model?"
Practical Advice for Developers: Manage AI Like Technical Debt
When asked "how do you make large legacy applications AI-ready," the panelists' answers were realistic: almost no company can afford to stop for three months to do a transformation.
Kaushik suggested treating prompt and context optimization like technical debt, allocating a fixed percentage of time to continuously improve it. "Many engineers still don't understand how it works—they think it's magical and mysterious, so they don't configure or tune it."
Anise emphasized the importance of continuous learning: "If a team spends a week learning the latest tools and then doesn't keep up for a year, they'll fall seriously behind. We're building the plane while flying it."
Ty closed with an optimistic but urgent reminder: AI is making every company more ambitious, but infrastructure scaling must keep up. "We need to audit ahead of time and figure out what system will crash next. As long as things feel under control, everyone's happy; once something unexpected happens, it's bad news for everyone."
One-line Summary
AI has caused code output to soar, but the delivery bottleneck has shifted to review, compliance, and infrastructure, and enterprises have entered a phase of cost accountability.
Paragraph Summary
At a roundtable hosted by Android DevRel, engineering leaders from Databricks, Google Maps, Ford, Uber, and Instacart reached a consensus: AI coding tools have brought massive acceleration in code output, but whether this translates into business value remains to be verified. After coding speeds up, the bottleneck shifts to code review, compliance, release, and CI/CD infrastructure—Uber even described "CI crying every night." Participants debated whether code review can be replaced by agent verification, but agreed that safety nets such as feature flags and observability are needed. On costs, Ford, Uber, and Databricks have moved into fine-grained governance through token limits, approvals, and model routing. For legacy systems, panelists suggested continuously investing in prompt and context optimization the way one manages technical debt.
Related articles

AI Comic Drama with WorkBuddy from Scratch: A Step-by-Step Skill Pack Installation Guide
Learn how to create AI comic dramas with WorkBuddy from scratch. This guide covers installation, Skill pack import and invocation, plus a script generation demo with manual revision tips to get you through the first step from script to storyboard.

WorkBuddy Agent Runs the Entire GEO Database Mining Pipeline with a Single Prompt
WorkBuddy agent automates GEO database mining: from data search and curation to batch correction, differential analysis, co-expression networks, feature gene screening, and immune infiltration—a single prompt generates a complete bioinformatics report, greatly lowering the barrier to bioinformatics analysis.

PC Memory Wasted? Hacker News Debates Centralized Data Centers
Hacker News users argue that personal computer memory is wasted and should be centralized in data centers, sparking debate on centralized vs. distributed computing resource allocation. This article analyzes the logic behind the claim, the costs of centralization, and new tensions in memory resource allocation in the AI era.