TokenEconomizer: Experience-Driven Black-Box Cost Control That Makes Agents Cheaper the More They're Used
TE learns three adaptive strategies from a repository's own trajectories, cutting costs 18% to 31% without changing the model.
TokenEconomizer (TE) proposes black-box cost control that changes neither the model nor the agent code. After showing that fixed strategies like RTK, Serena, and Ader RepoMap cannot reliably save money, TE learns repository-specific policies from completed trajectories: experience micro-skills, tool depreciation, and failure-loop intervention. It cuts costs 18.4% to 30.9% on SWE-bench, with all 30 repository configurations cheaper.
Title
TokenEconomizer: Experience-Driven Black-Box Cost Control That Makes Agents Cheaper the More They're Used
Meta Description
TokenEconomizer proposes a black-box cost control method: without changing the model or agent code, it learns repository-specific policies from completed trajectories. Through micro-skills, tool depreciation, and failure-loop intervention, it reduces token costs by an average of 18.4% to 30.9% on SWE-bench.
Article Content
Agents are getting more capable, and the bills are getting thicker—every request, system prompt, tool definition, and conversation history is billed by token, and repeatedly re-read. TokenEconomizer (hereafter TE) proposes an approach: don't touch the model, don't change the agent code—just learn experience from completed trajectories and apply that experience to subsequent tasks, achieving repository-specific adaptive cost control.
Why Fixed Strategies Fail to Save Money
The research team first tried three fixed strategies: RTK command output compression, Serena semantic navigation, and Ader repository maps. None of them saved money consistently—on one repository all three saved money, while on another all three cost more; for Scikit Learn only RTK helped, and for Safex only RepoMap helped.
This shows that repository relevance is key: experience must be learned from the repository's own trajectories, and a single configuration cannot be applied to all repositories. This is also the starting point for TE's choice to "learn its own policy per repository." (Screenshot: a large number of tools loaded)
Technical Positioning of RTK, Serena, and Ader RepoMap
These three represent three common technical routes for agent cost reduction. RTK (Run-Time Kit)-style command output compression truncates, summarizes, or structures tool return results before they enter the context, reducing redundant bytes; it does not change the agent's reasoning approach and is an "exit-side" optimization. Serena is an open-source semantic code retrieval and editing toolset that provides symbol-level navigation (go-to-definition, find-references) through LSP (Language Server Protocol), allowing the agent to replace extensive text search with a small number of precise calls; it is a "retrieval-side" optimization. Ader's repository map (RepoMap) injects a repository structure summary (file tree, key symbols, dependencies) into the system prompt so the model builds a global view before acting; it is an "entry-side" optimization. What all three share is that their policies are fixed and repository-agnostic, so when a repository's code scale, tool-call distribution, or failure patterns do not match the preset assumptions, savings turn into extra overhead.
Three Sources of Reducible Cost
TE divides reducible costs into three categories, each supported by real trajectory data:
Operational Knowledge Repeatedly Rediscovered
Within the same repository, actions repeated by at least half the tasks account for 12% to 28% of tool-call bytes. This knowledge could have been remembered, yet it is rediscovered every time.
Many Tools Are Never Called
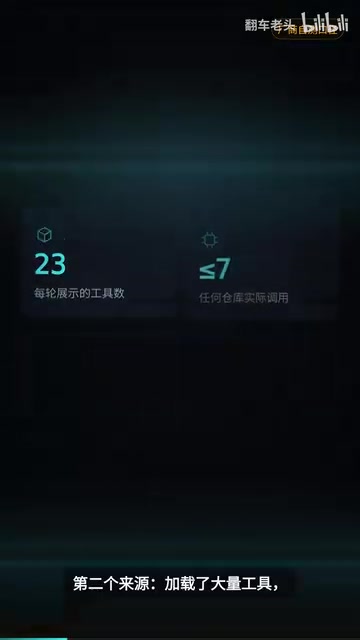
Each round exposes 23 tool schemas, but no repository ever calls more than 7. Tool definitions that are loaded but unused are sent with every request—pure waste.
The Hidden Cost of Failed Trajectories
In multi-turn tasks, 17% of tasks fail but consume 32% of total spending. Yet failure characteristics vary by repository: Matplotlib failures are much longer than successes (45 turns vs. 20 turns), while SpinX failures are only slightly longer than successes (36 turns vs. 31 turns). So a uniform turn limit cannot be used.
TE's Three Source Strategies
TE is an external controller that learns repository-specific policies from completed trajectories. It does not change model weights or the agent loop; it exerts influence only through instruction prefixes, tool loading, and event streams.
Experience Micro-Skills
Remember how this repository works. Facts are learned from two sources: failures that recur across trajectories, and a model review every three turns that examines recent trajectories and proposes facts. A fact is injected only if it satisfies two conditions simultaneously—it is confirmed on multiple tasks with non-overlapping file sets, and its error rate is below a threshold. A fact's evidence support decays over time; when contradicted, one contradiction outweighs multiple confirmations; once support falls below zero, the fact is permanently retired. (Screenshot: support threshold judgment)
Fact Lifecycle and Evidence Decay Mechanism
TE's micro-skills are essentially a repository knowledge base with confidence management, drawing on ideas from truth discovery and evidence aggregation in Byzantine fault tolerance. Each fact maintains a support score: it gains points when confirmed by independent tasks on non-overlapping file sets, and loses points when counterexamples appear, with "one contradiction outweighs multiple confirmations" corresponding to an asymmetric update—similar to how a likelihood ratio corrects a prior in probabilistic updating. Time decay prevents early conclusions from dominating permanently, allowing the knowledge base to adapt as the repository evolves. Permanent retirement once support falls below zero is a "negative evidence accumulation" strategy that avoids repeatedly injecting and repeatedly refuting the same erroneous fact, thereby controlling the cost of injection itself. The non-overlapping file set confirmation condition is especially critical: it requires a fact to hold across different code regions, ruling out pseudo-patterns that arise merely because of a particular file's style.
Tool Depreciation
Stop loading tools that are never used. Core tools (file read/write/edit, etc.) are always retained; other tools are removed if they are not called across several consecutive completed tasks. There is also an LLM judge that, based on tool descriptions and task descriptions, determines whether a never-called tool is relevant. Removed tools can be restored through re-review.
Token Overhead of Tool Schemas and Dynamic Tool Selection
In APIs that support tool calling, each tool's name, description, and JSON Schema parameter definitions are sent as input tokens with every request and billed repeatedly across multi-turn conversations. As the number of tools grows, this fixed overhead expands linearly, and it can also dilute the model's attention to relevant tools, leading to wrong or missed selections. Dynamic tool selection has therefore become a common optimization in agent engineering: mount only a subset of tools based on the task or historical usage. TE's tool depreciation adds two constraints on top of this—a core-tool whitelist ensures basic operational capability is not mistakenly removed, and an LLM judge uses semantic relevance to compensate for the blind spot that "never called does not mean not needed" (e.g., low-frequency but critical deployment or testing tools). The recoverable mechanism also lowers the cost of mistaken removal, allowing the policy to converge even if it leans conservative.
Failure-Loop Intervention
Intervene when stuck. First, compute this repository's normal turn budget from the turn distribution of successful trajectories; after each tool call, rules check for repeated failure signatures, dense error output, or exceeding the budget. When triggered, an LLM judge determines whether the agent is truly stuck or still making progress; if stuck, it first redirects by summarizing recent actions for the agent so it can try a different approach; if the pattern recurs and the judge again determines it is stuck, the rollout is terminated. There is also a hard backstop: when kappa times the budget is reached and the three conditions of marginal churn, dense errors, and repeated signatures are simultaneously met, a forced stop occurs that the judge cannot override. (Screenshot: the judge determines it is stuck)
Engineering Implications of Turn Budget and Stuck Detection
"Turn budget" refers to the maximum number of agent-tool interaction turns allowed for a task; exceeding it is considered abnormal. The problem with a fixed turn cap is that repositories differ enormously: a normal task in a complex repository may legitimately require dozens of turns, while a stuck task in a simple repository may occur within a dozen turns; a uniform threshold either kills normal tasks or lets infinite loops through. TE estimates a repository-specific budget from the turn distribution of successful trajectories (e.g., taking a high quantile), making the threshold adapt to the repository. A repeated failure signature means the same error type and location combination appears consecutively; dense error output means the error ratio per turn rises abnormally; and marginal churn characterizes actions spinning in place with stalled progress. Together with the budget multiplier, these three form a hard backstop whose significance is to add a deterministic safeguard to the LLM judge's soft judgment—when the model misjudges that the agent is "still making progress," the rules can still cut losses and prevent the failed trajectory from continuing to consume tokens.
Cost Reduction and Ablation Results
On 277 tasks across 6 repositories and 5 configurations in SWE-bench, TE reduces average cost by 18.4% to 30.9%; all 30 repository-configuration units are cheaper, with reductions from 5.2% to 40.1%. Pass@1 improves in 4 of the 5 configurations. Cost reduction accumulates over the task stream—except for xarray, all repositories are initially more expensive, but by the 6th task all turn cheaper, with final cumulative savings of 16.9% to 32%. Among the 5 agent-model configurations, Claude Sonnet 4.8 has the largest reduction at 30.9%, and Copilot Sonnet 5 the smallest at 18.4%.
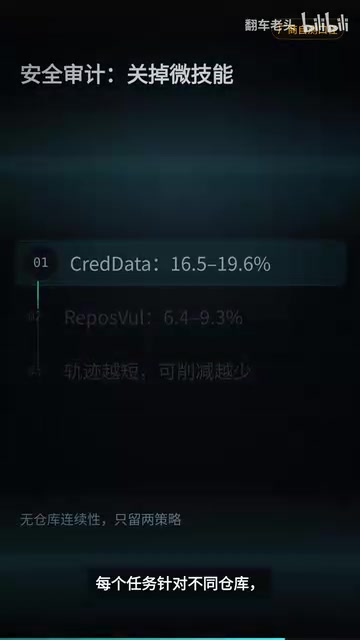
On 102 consecutive web development tasks in WebBench, cost is reduced by 16% to 21%. On the security audit benchmark ReploBench (where each task targets a different repository, with no repository continuity), turning off micro-skills and keeping only tool depreciation and failure-loop intervention yields reductions of only 6.4% to 9.3%—because trajectories are shorter and there is less room to cut. (Screenshot: a benchmark without repository continuity)
Ablation experiments show: tool depreciation contributes the most (13.2% and 17.7%), micro-skills follow closely (11.8% and 14.3%), and failure-loop intervention is in the single digits. No single strategy can reproduce all the savings; only the three complementary strategies stacked together reach 18% to 30%.
Implications of Black-Box Cost Control
TE proves one thing: in the continuous task streams of real software development, adaptive black-box cost control is more reliable than fixed strategies. The model stays the same, the agent stays the same; by learning only repository experience, it understands the repository better the more it is used, and costs keep falling. For agent applications that run long-term on a fixed codebase, this "experience-driven" cost-reduction approach is worth attention.
One-line Summary
TE learns three adaptive strategies from a repository's own trajectories, reducing costs by 18% to 31% without changing the model.
Paragraph Summary
TokenEconomizer (TE) addresses the problem of agents being repeatedly billed on every request by proposing a black-box cost control solution that changes neither the model nor the agent code. The study first demonstrates that three fixed strategies—RTK compression, Serena semantic navigation, and Ader repository maps—cannot reliably save money, and that repository relevance is key. TE learns repository-specific policies from completed trajectories, including experience micro-skills (a fact base with evidence decay), tool depreciation (removing never-called tools, restorable by a judge), and failure-loop intervention (based on turn budgets and stuck detection). On 277 tasks in SWE-bench, it reduces average cost by 18.4% to 30.9%; all 30 repository configurations are cheaper, and costs decline cumulatively over the task stream. Ablation shows tool depreciation contributes the most, and the three strategies are complementary. On ReploBench, which lacks repository continuity, the reduction is only 6.4% to 9.3%, indicating that a continuous task stream is a prerequisite for experience accumulation.
Related articles
Former OpenAI Researcher Christiano: AI Labs Should Solve Safety Before Pursuing Frontier Breakthroughs
AI safety researcher Paul Christiano said in an interview that US frontier AI labs should pause pretraining and reinforcement learning under their current security posture, describing algorithmic secrets as fragile with only a "12-hour lead over China."
Stop Writing Code and Your Code Review Skills Will Degrade Too
cekrem's article argues that stopping hands-on coding degrades code review skills. This analysis explores how writing and reviewing share the same judgment, how reviewers become the quality bottleneck in the AI era, and offers concrete ways to keep your coding feel.
Gemini 4 Neon Community in Practice: 9 Case Studies on Scenes, Games, and 3D Animation
A Bilibili community collection of Gemini 4 Neon practice cases, featuring 9 scene generation, game prototype, and 3D animation examples with model PK comparisons.