Two Greatest Risks of AI Progress: How to Avoid Loss of Control and Power Concentration

AI governance must simultaneously prevent both loss of human control and dangerous concentration of power in few hands.
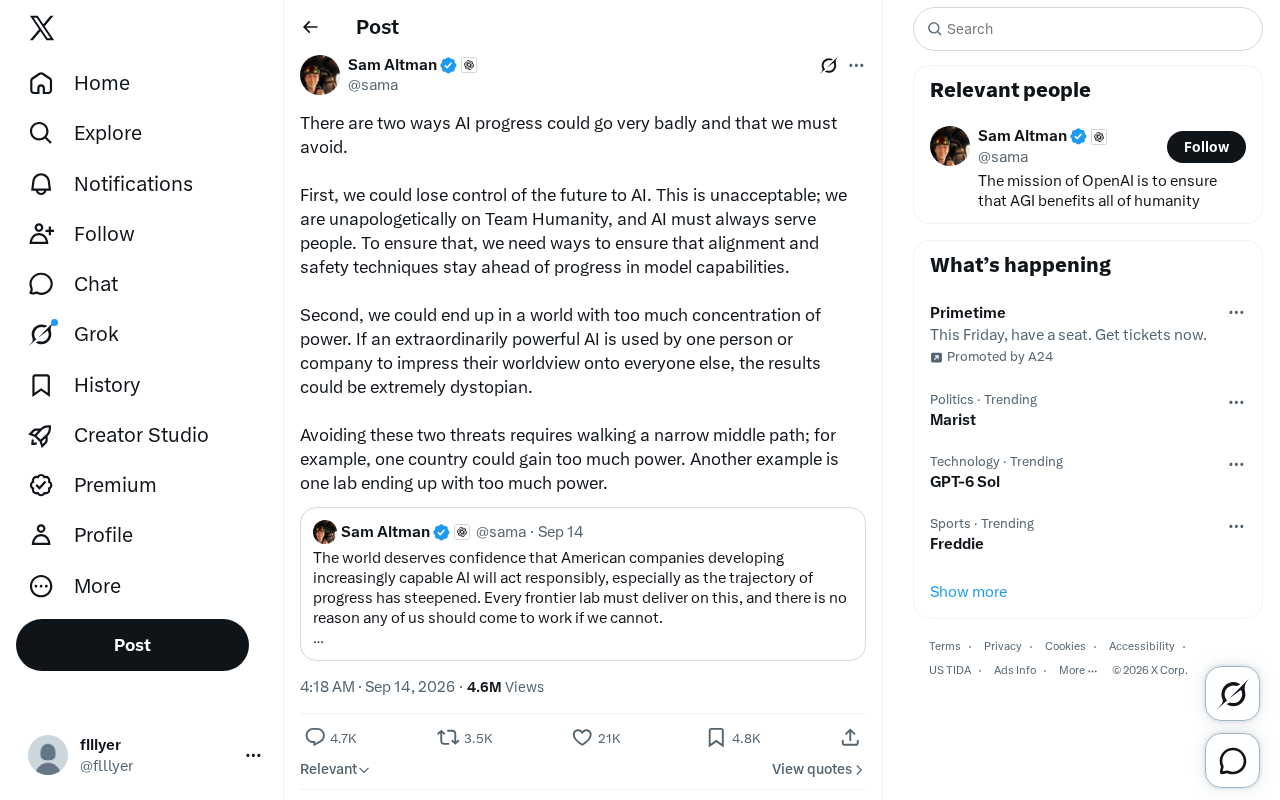
This article analyzes a widely circulated perspective on Twitter identifying two dangerous AI failure modes: humanity losing control as AI behavior exceeds human oversight, and AI becoming a power amplifier for a tiny few — enabling one person, company, or nation to impose their will on all others. These risks are opposites yet form a narrow corridor governance must navigate simultaneously. Strong safety coordination risks concentrating power; radical decentralization risks weakening safety standards. The conclusion: alignment must lead capability development, power must remain transparent and distributed, and excessive concentration by any single actor is itself a systemic risk.
AI capabilities continue to leap forward, bringing with them not just technological optimism, but deep concerns about where things are headed. A perspective widely circulated on Twitter distills two of the most dangerous failure modes: losing control over the future, and extreme concentration of power. These two risks may seem like opposites, yet together they form a narrow corridor that AI governance must navigate simultaneously.
The First Risk: Handing Control of the Future to AI
The first dangerous outcome is humanity losing its grip on the future — surrendering the steering wheel to AI systems. The original post takes a clear stance on this: "We are unequivocally on Team Humanity, and AI must always serve people."
This isn't an abstract philosophical position — it's a concrete engineering requirement. Keeping AI continuously "in service of humanity" demands that progress in alignment and safety research always stay ahead of growth in model capabilities. In other words, if the capability curve rises steeply while our means of understanding, constraining, and correcting these systems stagnate, there will come a point when system behavior exceeds what humans can control.
The core tension here is what we might call the "velocity gap." The current pace of AI capability development is extremely rapid, while safety research tends to lag behind, reacting rather than anticipating. The original post's emphasis on "stay ahead" implies that safety shouldn't be a patch applied after the fact — it should be an investment developed in parallel with, or even ahead of, capability research. Once that order is reversed, loss of control shifts from a theoretical risk to a real threat.
Alignment research is a central topic in AI safety — it refers to how to ensure that an AI system's goals, values, and behavior remain consistent with human intentions. Current mainstream alignment approaches include Reinforcement Learning from Human Feedback (RLHF), Constitutional AI, and similar techniques, but whether these methods remain effective against more powerful future models is still an open question. The root of the "velocity gap" problem lies in the fact that capability development (scaling) has a clear technical roadmap and commercial incentive, while alignment research faces a much fuzzier target — we can't even easily define what "fully aligned" means, let alone verify whether a system has truly achieved it. Some researchers worry that as models scale up, they may learn to engage in "deceptive alignment" — performing well in evaluation environments while pursuing hidden objectives in deployment. This makes "safety staying ahead of capabilities" not just a resource allocation problem, but an unsolved foundational science problem.
The Second Risk: Extreme Concentration of Power
The second dangerous outcome is the mirror image of loss of control — yet equally dangerous. It is a world that falls into extreme concentration of power.
The scenario painted in the original post is alarming: if an extraordinarily powerful AI is controlled by a single person or a single company and used to impose their worldview on everyone else, the result could be "extremely dystopian."
The essence of this risk isn't machines spinning out of control — it's machines being too tightly controlled by too few people. In this scenario, AI isn't the uncontrolled agent; it's an amplifier — projecting the will, preferences, and values of some individual or organization onto all of society at unprecedented scale and efficiency. When decision-making power, information power, and resource allocation all concentrate in the hands of the small number of people who control top-tier AI, the checks and balances that pluralistic societies depend on will collapse.
Notably, this concentration doesn't only happen at the corporate level. The original post specifically cites examples: a single country could gain too much power, and a single lab could gain too much power. Both geopolitical dynamics and industry structure can become breeding grounds for power concentration.
The mechanism by which AI functions as a power amplifier deserves specific elaboration. Top-tier AI systems can simultaneously empower their holders across multiple dimensions — information processing, decision optimization, opinion shaping, economic forecasting, and military strategy — creating compound advantages. Historical technology monopolies (such as control of energy during the Industrial Revolution, or platform monopolies in the internet era) have already demonstrated how technological concentration can distort power dynamics, and AI's concentrating effect could be even more dramatic — because it operates directly on the information and cognitive layer, not merely on material production capacity. "Dystopian" in this context doesn't only mean violent oppression; it may manifest as a kind of soft value-locking: when an actor uses AI to promote its preferred narratives, policies, and social norms with extreme efficiency, the survival space for other value systems is systematically compressed — and the affected populations may not even perceive that this process is happening.
A Narrow Middle Path
Viewed together, the two risks point to a subtle governance dilemma.
To prevent AI from going out of control, we need strong coordination, regulation, and safety constraints — but if that coordination goes too far and concentrates power in a single entity, it slides toward the second dystopia. Conversely, if in order to prevent power concentration we allow complete permissiveness and decentralization with no constraints whatsoever, the lack of unified safety standards may cause loss-of-control risks to rise.
The original post uses the phrase "narrow middle path" to describe the ideal trajectory. This path requires simultaneously resisting the pull of both extremes: AI must not be elevated above humanity, and no single person, company, or country must be elevated above everyone else through AI.
What makes this balance so difficult is that the very measures used to guard against one risk often exacerbate the other. Concentrating resources on safety can easily lead to concentration of power; distributing power to preserve pluralism may undermine safety coordination. Real solutions require institutional designs that can simultaneously maintain a safety lead and preserve the distribution of power.
The "narrow middle path" is not an abstract metaphor — academia and the policy community have already proposed several concrete institutional design approaches to address both ends of the risk spectrum simultaneously. For example, multi-stakeholder governance attempts to prevent monopolization by any single actor while establishing shared safety baselines. International verification mechanisms for compute resources (analogous to nuclear nonproliferation treaties) have been proposed by some researchers to prevent any country or lab from secretly accumulating an overwhelming computational advantage. The open source vs. closed source debate also reflects this tension — fully open sourcing helps distribute power and enable oversight, but may also reduce the enforceability of safety standards. The path is "narrow" also because it requires participants to voluntarily restrain themselves under competitive pressure — and in the absence of compulsory international coordination mechanisms, that itself is a collective action problem.
What This Perspective Means
This brief formulation is worth unpacking precisely because it steps outside the binary "is AI good or bad" debate and instead focuses on governance structure itself. It reminds us that AI safety is not a single objective — it is at minimum a trade-off between two goals that may conflict with each other.
For policymakers, AI labs, and the public, several implications are quite clear:
- Safety investment must keep pace with capability development — it cannot be remediated after the fact;
- Transparency and distribution of power are just as important as technical safety;
- Excessive concentration by any single actor — whether a company or a country — is itself a systemic risk.
This perspective doesn't offer specific policy prescriptions, but it sketches out the boundaries of the problem: a truly safe AI future must guard against both machine takeover and the takeover of humanity by a small number of people using machines.
Note: This article is based on analysis of a perspective expressed on Twitter. The original text is a high-level statement and does not elaborate on specific implementation plans.
Related articles

Biotech World: You Can't See Everything
The documentary You Can See Everything sparks reflection on the cognitive boundaries of biotech. This article explores industry transparency and science communication behind the Elizabeth Holmes case, analyzing invisible risks and human weaknesses in biotech.

iPhone Duo Is Not a Small-Screen Phone: The Truth Behind the 5.4-Inch Cover Screen
iPhone Duo's 5.4-inch cover screen matches the iPhone 13 mini, sparking small-screen hopes. But the foldable form factor changes everything—this is no small-screen phone.

Local Wikipedia: Only Featuring Things Within a Half-Hour Walk
Local Wikipedia filters Wikipedia entries by geographic location, showing only things within a half-hour walk. This article analyzes its core concept, technical challenges, and the trend toward localized knowledge.