Two Years Into Learning AI and Losing Motivation: Should You Keep Learning in the Age of AI Coding?

After AI replaces coding, the value of learning AI should shift from implementation to judgment and orchestration.
A Reddit user systematically studied ML/DL, shifted to NLP and LLMs, and then lost motivation as AI took over coding; a friend advised a career change. The article argues the frustration stems from treating "writing code" as the end goal of learning, whereas the true core capabilities of machine learning are judgment skills such as problem definition, experimental design, and result interpretation, which cannot be replaced by autocomplete. The friend's judgment about industry impact holds for repetitive development, but the software engineer role is bifurcating, with demand rising for system design and AI integration. The article offers three paths: shift to model evaluation and reliability, embed AI into vertical businesses, and become a user and orchestrator of AI tools; it also recommends switching from "learn then do" to project-driven learning—two years of accumulation leaves model intuition, not code volume.
A Reddit user posted for help: over the past two years they systematically studied machine learning and deep learning algorithms, then shifted to NLP and LLMs, but now that AI handles almost all coding work, their motivation has plummeted. A friend who works as a software engineer advised them to stop wasting time, find an ordinary job, and said AI is a major hazard for the entire software industry. They've already invested a lot of time and don't want that accumulation to go to waste, so they asked: if they keep learning, which path should they take? How can they progress faster?
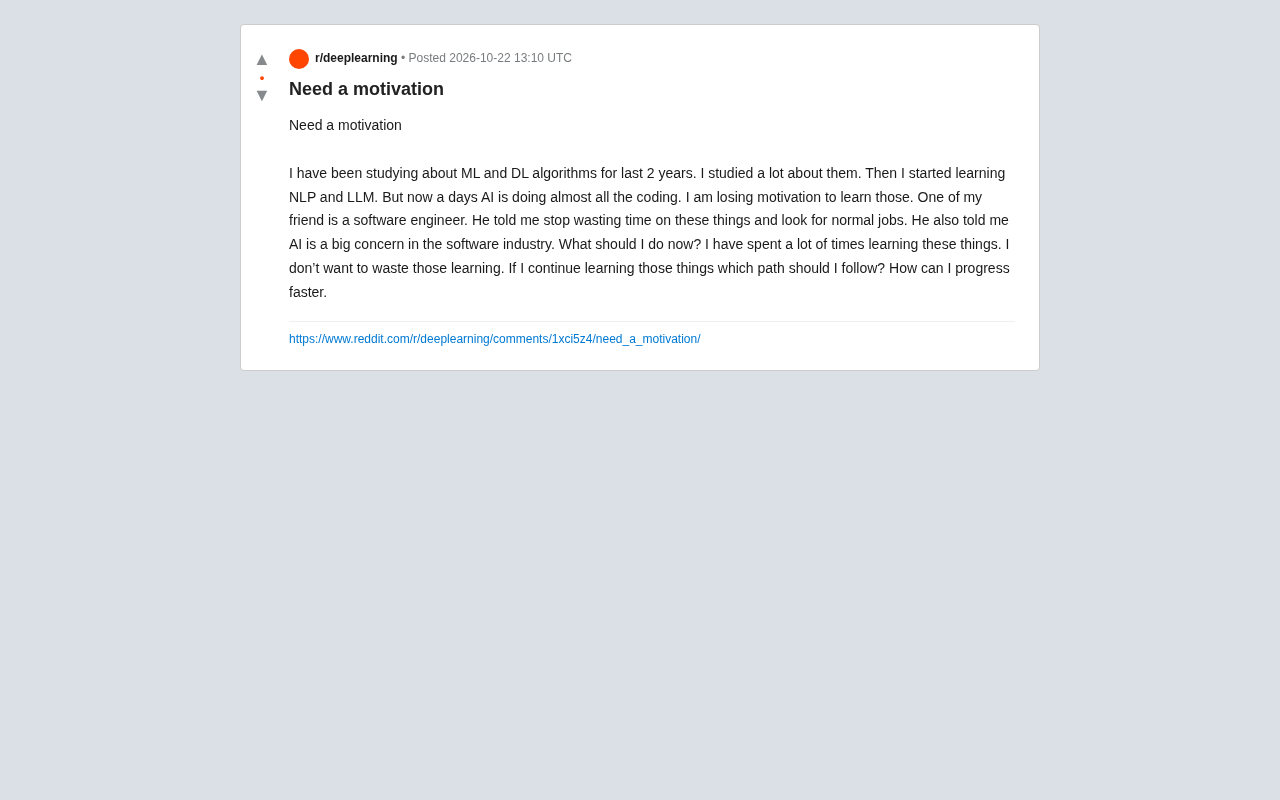
This post resonated because it hits on many people's real situation—it's not that they don't want to learn, but that they can't see the return on their investment. Below, we break this down across three dimensions: motivation, paths, and efficiency.
The Root of Lost Motivation: Treating "Writing Code" as the End Goal of Learning
The user's frustration comes from an implicit assumption: the value of learning AI equals writing code by hand. When AI can automatically generate code, that equation collapses.
But the core capability of machine learning training was never the speed of typing code. Understanding the bias-variance tradeoff, judging whether a loss function is reasonable, identifying data leakage, evaluating model performance on out-of-distribution data—these judgments cannot be replaced by autocomplete tools. AI can write a PyTorch training loop that runs, but it's hard for it to judge whether this experimental design answers the question you actually want to ask.
In other words, coding is depreciating, but problem definition, experimental design, and result interpretation are appreciating. Shift the learning focus from "implementation" to "judgment," and motivation finds a new anchor.
The bias-variance tradeoff is the core framework for understanding model generalization. Bias refers to a model systematically deviating from the true pattern because its assumptions are too simple (underfitting), while variance refers to a model being overly sensitive to fluctuations in training data, causing performance to plummet when the data changes (overfitting). In practice, regularization, increasing data volume, and adjusting model complexity are all tradeoffs between the two. Being able to write training code with autocomplete tools does not mean you can judge whether the current model is underfitting or overfitting, or whether to add data or reduce features—this kind of diagnosis is precisely what AI struggles to replace.
Data leakage refers to information that would be unavailable at prediction time being mixed into training, such as using future data to predict the past, performing global standardization before splitting the training set, or using derived features of the target variable as input. It inflates offline metrics and causes a cliff-like drop after deployment. Identifying leakage requires a clear understanding of data pipelines and business timing, and is a fundamental skill for assessing model credibility.
Is the Friend's Advice Right? Let's Break It Down
The friend says "AI is a major hazard for the software industry." This judgment holds in some scenarios: repetitive CRUD development, templated front-end pages, and simple scripting tasks are indeed being rapidly compressed. If a person's skill stack consists only of these, anxiety is reasonable.
But the conclusion "go find an ordinary job" skips the middle options. The role of software engineer itself is bifurcating: on one end is execution-oriented coding, on the other is system design, AI integration, and effectiveness evaluation. The latter is not weakened but rather in greater demand due to the spread of AI tools—companies need people who can judge whether AI output is correct and integrate models into business processes.
According to the friend's statement in the post, AI's impact on the software industry is real, but interpreting it as "the entire industry is doomed" misreads structural change as across-the-board decline.
Three Realistic Paths to Keep Learning
Path 1: Shift from Calling Libraries to Evaluation and Reliability
The biggest pain point of LLM applications is not whether they run, but whether the output is trustworthy. Learning how to design evaluation sets, how to do hallucination detection, and how to build regression tests to monitor changes in model behavior—these skills are extremely scarce in engineering teams. The direction is specific and directly connects to existing NLP foundations.
Hallucination detection refers to identifying parts of LLM-generated content that appear fluent but are inconsistent with facts or the given context. Common methods include: attribution verification based on retrieved evidence (checking whether each conclusion is supported by source documents), consistency voting with another model, and fact-checking combining rules and classifiers.
Regression testing to monitor model behavior draws on traditional software testing: establish a fixed evaluation set with expected outputs for the model, rerun it each time prompts, model versions, or retrieval configurations change, and observe whether the pass rate drops. The difference from traditional unit tests is that outputs are probabilistic, so scoring thresholds, semantic similarity, or LLM-as-judge are typically used for judgment, with statistical comparison across multiple samples.
Path 2: Embed AI Capabilities into Specific Businesses
Pure algorithm positions are highly competitive, but people who understand both AI and a vertical domain are rare. Financial risk control, medical text, legal contract review, industrial quality inspection—these scenarios need people to align model capabilities with business constraints. Existing ML/DL accumulation is a moat here, not a sunk cost.
Path 3: Become a User and Orchestrator of AI Tools
Shift the learning focus from training models to orchestrating them: multi-model routing, RAG system design, Agent workflows, cost and latency optimization. This kind of work has a fast start, direct feedback, and makes it easier to see results in the short term, which helps restore motivation.
RAG (Retrieval-Augmented Generation) refers to retrieving relevant snippets from an external knowledge base and injecting them into the context before the model generates an answer, thereby mitigating outdated knowledge and hallucination. A RAG system typically includes document chunking, vector embedding, similarity retrieval, reranking, and prompt assembly; the tradeoffs at each step affect the final result.
Agent workflows refer to letting a model autonomously decide which tools to call, in what order, for multi-step tasks, and adjust subsequent actions based on intermediate results. Compared with single-turn Q&A, it needs to handle tool-call formats, state passing, failure retries, and termination conditions, making cost and latency control a design priority. Multi-model routing distributes requests to models of different scales or vendors based on task difficulty or cost budget.
How to Progress Faster: Switch from "Learn Then Do" to "Learn by Doing"
The user mentioned studying "algorithms" for two years, which may itself be one cause of lost motivation—long-term input without output leaves no way to build a sense of achievement.
A faster path is to pick a specific small project, such as using an existing LLM to build a tool that solves your own daily problems, and then go back to fill in theory when you hit obstacles. The feedback cycle of project-driven learning is days rather than months, so motivation naturally sustains itself.
Another accelerator is benchmarking outputs. Publicly write up your experiment records and evaluation results and accept external feedback—this is much faster than grinding through courses alone, and it builds verifiable evidence of your abilities.
Project-driven learning is effective because it creates real constraints and feedback: specific goals, verifiable success or failure, and learning with a clear purpose when problems arise, making memory and understanding more solid. By contrast, finishing courses systematically before starting hands-on work easily leads to a state of "knowing a lot but unable to apply it," and long-term lack of positive feedback drains motivation. For those with theoretical foundations, a more reasonable approach is to first set a minimum viable version deliverable within a few days, then fill in theory around the weaknesses exposed.
The Right Way to Calculate Sunk Costs
"Not wanting past investment to go to waste" is the most genuine line in the post. But what two years of studying ML/DL leaves behind is not lines of code, but a basic intuition for model behavior—an intuition that can be reused in any AI-related work.
The real thing to guard against is not AI replacing coding, but defining learning too narrowly. Adjust the direction, and two years of accumulation becomes a starting point, not a burden.
One-line Summary
After AI replaces coding, the value of learning AI should shift from implementation to judgment and orchestration.
Paragraph Summary
A Reddit user systematically studied ML/DL, shifted to NLP and LLMs, and then lost motivation as AI took over coding; a friend advised a career change. The article argues the frustration stems from treating "writing code" as the end goal of learning, whereas the true core capabilities of machine learning are judgment skills such as problem definition, experimental design, and result interpretation, which cannot be replaced by autocomplete. The friend's judgment about industry impact holds for repetitive development, but the software engineer role is bifurcating, with demand rising for system design and AI integration. The article offers three paths: shift to model evaluation and reliability, embed AI into vertical businesses, and become a user and orchestrator of AI tools; it also recommends switching from "learn then do" to project-driven learning—two years of accumulation leaves model intuition, not code volume.
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.