vLLM v0.30.0 Released: Major Upgrades to Hybrid Attention and Speculative Decoding

vLLM v0.30.0 brings hybrid attention, HiSparse caching, and speculative decoding upgrades for faster inference.
vLLM v0.30.0 is a broad, technically deep release with 762 commits from 315 contributors. Core performance improvements span three areas: hybrid attention hot-path optimizations using operator fusion and sparse GQA reduction; HiSparse hierarchical caching that backfills only top-k data on demand to ease GPU memory pressure; and Model Runner V2, which brings EAGLE3-style draft generation and adaptive verification to pipeline parallelism. New features include dual-key Gumbel-max watermarking, CUDA IPC-based Fast Start for rapid cold restarts, and support for new models including GLM-5.3-Flash, rounding out vLLM's production-grade deployment capabilities.
vLLM v0.30.0 Released: Major Upgrades to Hybrid Attention and Speculative Decoding
The open-source LLM inference engine vLLM has officially released version 0.30.0. According to the announcement posted on Twitter, this release includes 762 commits from 315 contributors — 104 of whom are first-time contributors. These numbers reflect the growing activity of the vLLM community and the project's continued centrality in the large model inference ecosystem.
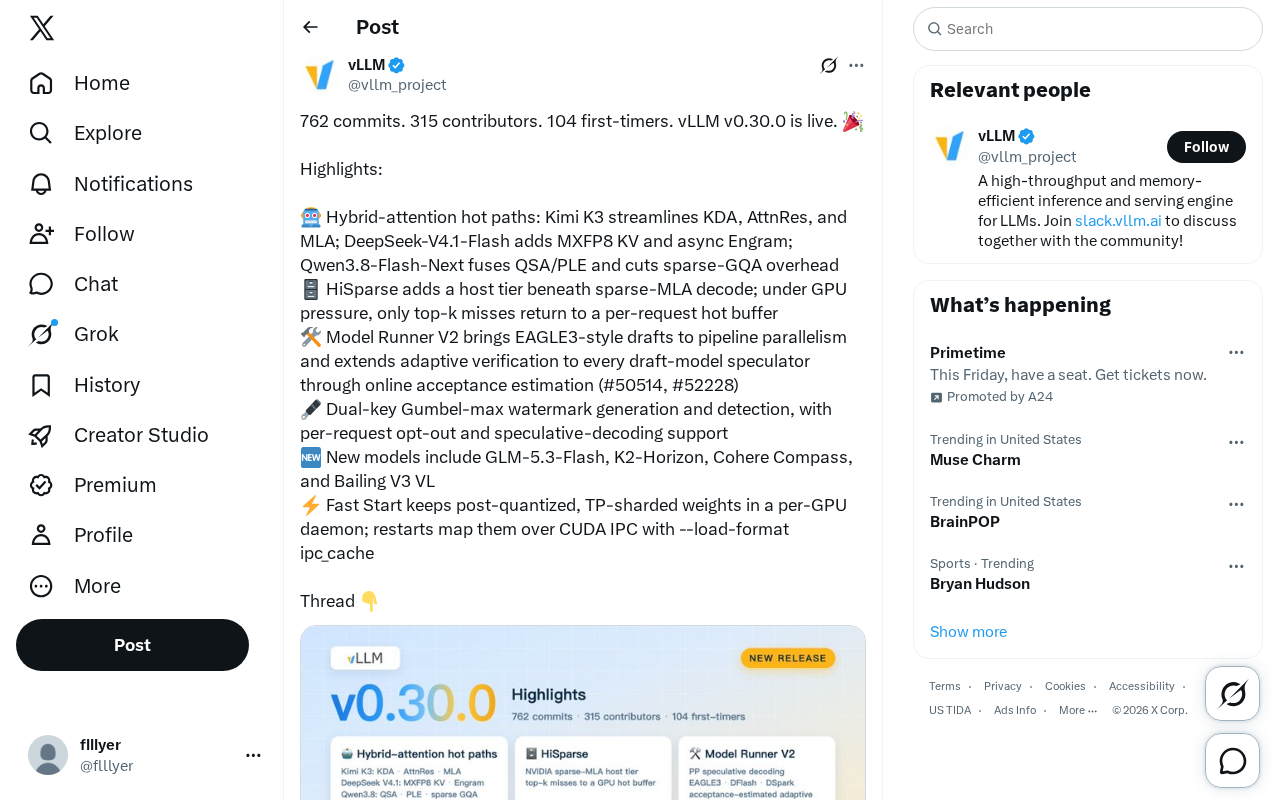
Hot-Path Optimizations for Hybrid Attention
One of the major focuses of this release is deep optimization of the "hybrid attention" hot paths, with targeted improvements for several mainstream models.
According to the release notes, vLLM introduces differentiated acceleration strategies for different models: simplifying execution flows related to KDA, AttnRes, and MLA; adding MXFP8 KV cache and async Engram support for select models; and fusing QSA/PLE operators while reducing overhead from sparse GQA (Grouped Query Attention).
The shared goal of these changes is to lower memory usage and latency in attention computation and KV cache management without sacrificing accuracy. For long-context and high-concurrency scenarios, hot-path optimizations for hybrid attention can yield substantial throughput gains — making this a key battleground in the inference engine space.
HiSparse: Hierarchical Sparse Decoding
Memory pressure has always been one of the toughest challenges in large model inference. The HiSparse feature introduced in v0.30.0 adds a "host tier" beneath sparse MLA decoding, creating a more granular hierarchical cache structure.
The mechanism is clever: when GPU memory is under pressure, the system only backfills top-k missing data into each request's hot buffer on demand, rather than indiscriminately consuming precious GPU memory. This on-demand backfill approach is essentially a dynamic trade-off between GPU memory and host memory, ensuring limited VRAM is dedicated to the most critical decoding paths.
For teams deploying under resource constraints, this kind of hierarchical mechanism means they can serve larger models or handle higher concurrency on lower-spec hardware.
Model Runner V2 and Speculative Decoding Enhancements
Speculative decoding is another highlight of this release. The new Model Runner V2 brings EAGLE3-style draft generation into pipeline parallelism, and through online acceptance rate estimation, extends adaptive verification to every draft model speculator (see PRs #50514 and #52228).
In brief, speculative decoding accelerates generation by having a small model "pre-write" candidate tokens that a larger model then verifies in batch. vLLM's improvement here makes the verification process more adaptive — the system can dynamically adjust its verification strategy based on real-time acceptance rates, reducing wasted computation. Extending this capability to pipeline parallelism means large-scale distributed deployments can also benefit from speculative decoding speedups.
The core idea behind speculative decoding is to exploit the asymmetric cost between a lightweight draft model and a large target model. The draft model generates several candidate tokens in sequence; the main model verifies all of them in a single forward pass, accepting those that match its distribution and regenerating from the first rejected token. As long as the acceptance rate is high enough, the number of valid tokens produced per unit of time significantly exceeds pure autoregressive decoding. EAGLE (Extrapolation Algorithm for Greater Language-model Efficiency) is a family of feature-layer-based drafting methods, and EAGLE3 is its latest iteration, achieving better draft quality through more precise hidden-state reuse. Online acceptance rate estimation allows the system to dynamically determine how many tokens to speculate at each step based on actual request traffic — without manual tuning — maintaining near-optimal speedup across varying workloads.
Watermarking, Fast Start, and New Model Support
Beyond performance, v0.30.0 also delivers several noteworthy functional additions.
Content Watermarking: New support for dual-key Gumbel-max watermark generation and detection, with per-request opt-out support and compatibility with speculative decoding. This feature aligns with the growing industry trend toward content traceability and compliance for AI-generated text.
Fast Start: Saves quantized, tensor-parallel (TP)-sharded weights in a per-GPU resident daemon process. On restart, weights are directly mapped via CUDA IPC — simply enable it with --load-format ipc_cache. This is highly practical for production environments that require frequent service restarts or high availability, dramatically reducing cold-start times.
New Model Support: This release adds support for GLM-5.3-Flash, K2-Horizon, Cohere Compass, and Bailing V3 VL, further expanding vLLM's model ecosystem coverage.
Dual-key Gumbel-max watermarking is a statistical watermarking scheme based on random seeds: when generating each token, a key is used to randomly permute the vocabulary, causing watermarked text to statistically favor certain tokens in ways imperceptible to ordinary readers. The "dual-key" design separates the generation key from the detection key — organizations can make detection public while keeping the private generation key safe from forgery, balancing auditability with security. Per-request opt-out means specific scenarios (such as code completion or highly creative writing) can be exempt from watermarking, avoiding any impact on output quality. Fast Start leverages CUDA IPC (Inter-Process Communication) to keep quantized, TP-sharded weights resident in daemon process memory, so restarts simply remap the weights rather than reload and reshard them — reducing cold-start time from minutes to seconds, which is highly significant for rolling upgrades or rapid failure recovery in production.
Summary
vLLM v0.30.0 continues the project's characteristic high-cadence iteration. From hybrid attention optimization and hierarchical sparse caching to speculative decoding enhancements, nearly every change targets the same goal: squeezing more inference efficiency out of available hardware. Combined with engineering-grade capabilities like watermarking and fast startup, along with an ever-growing roster of supported models, vLLM continues to solidify its position as the go-to open-source inference engine. For developers focused on large model deployment and inference optimization, this release is well worth evaluating for an upgrade.
Related articles

MCP Protocol in 60 Seconds: A Real Session, Message by Message
Dissecting a real MCP session message by message: how an Agent dynamically discovers tools, forwards call requests, and has an MCP server execute them — all in just 9 JSON messages, with the model and reasoning loop untouched.

n8n 40-Minute Masterclass: Build Your First AI Automation Workflow from Scratch
Distilled from a 40-minute n8n masterclass: the core differences between automation, AI, and AI Agents, a comparison of n8n's four deployment methods, and a complete guide from dashboard to your first workflow.

Why Does a 35GB Quantized Model Blow Up an 80GB GPU? The Truth About KV Cache VRAM
Why does a 35GB 4-bit quantized LLM still blow up an 80GB GPU? This article breaks down the four components of inference VRAM, provides precise KV Cache formulas, compares GQA vs DeepSeek MLA memory, and offers production-grade OOM prevention like FP8 KV Cache.