What Goal Is Reasoning Actually Solving? A Hacker News Discussion

Reasoning is a means, not an end; without clear goals, capability gains may miss real needs.
Starting from a low-traffic Hacker News thread, the article asks what goal large-model reasoning actually solves. It argues that research assumes stronger reasoning is always better, equating long chains of thought and high benchmark scores with reasoning capability, confusing means with ends. Without a clear objective function, reasoning evaluation degenerates into pattern matching, causing benchmark scores to diverge from real-world performance. It outlines two views—reasoning as serving decision quality, or as a compression and generalization tool for data efficiency—and offers practical lessons: redesign evaluation to include decision-process soundness, define scenario goals before pursuing capability, and avoid a blind reasoning arms race.
What Is the Goal of Reasoning? A Neglected Fundamental Question
In the AI field, reasoning capability is regarded as a key milestone in the evolution of large models. But a discussion thread on Hacker News raises a more fundamental question: what goal is reasoning actually solving? This seemingly simple question touches on a blind spot in current AI research—we invest massive resources in improving models' reasoning performance, yet rarely ask what reasoning is ultimately for.
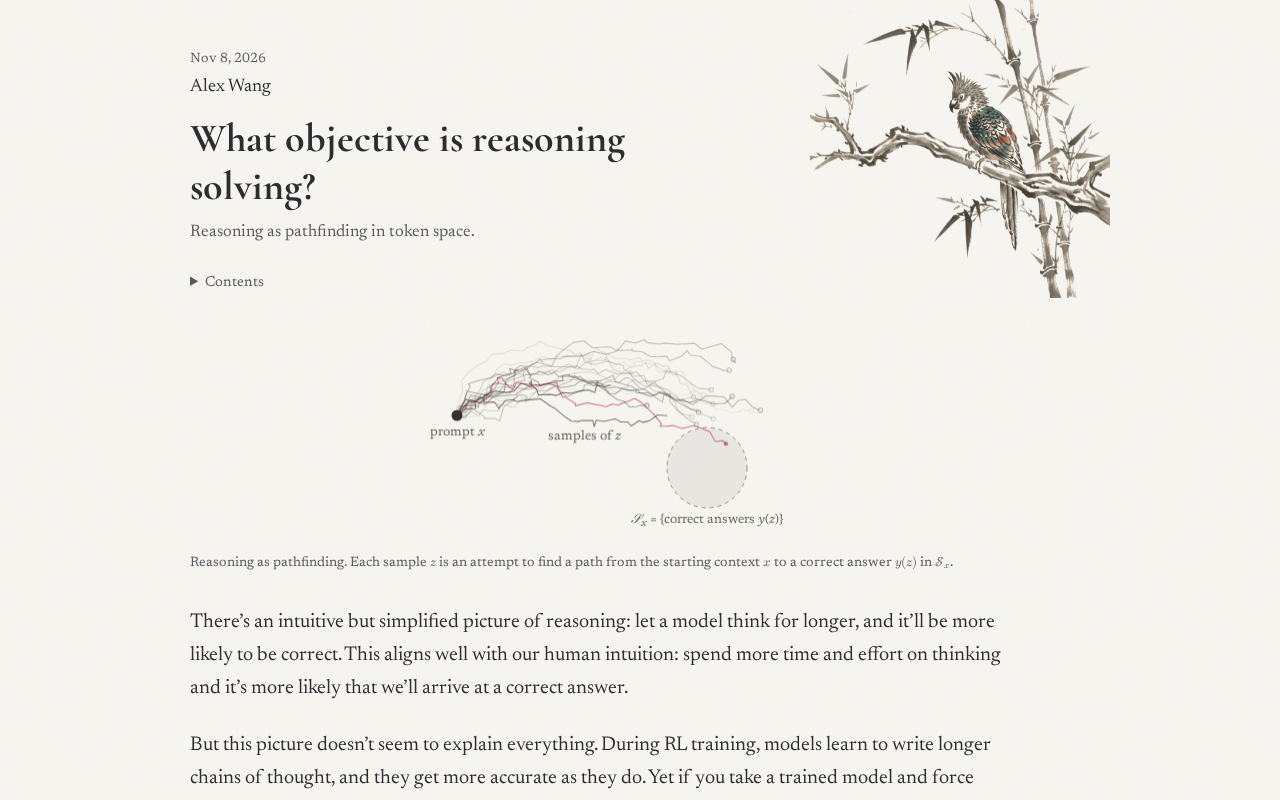
The post itself has only 13 upvotes and 2 comments, but the depth of the topic is worth exploring. When the industry equates reasoning with "longer chains of thought" or "higher benchmark scores," we may be overlooking the true value of reasoning: it should help models make better decisions in uncertain environments, rather than merely generating text that looks more rigorous.
Reasoning and Goals: Confusing Means with Ends
Reasoning Treated as an End in Itself
Much current reasoning research assumes a premise: the stronger the reasoning capability, the better. As a result, training data is filled with examples of step-by-step derivation, and evaluation benchmarks lean toward multi-step logic problems. But reasoning is not an end in itself—it is a means to achieving a goal. If the goal is not clearly defined, improving reasoning capability may simply let the model go further in the wrong direction.
Evaluation Bias Caused by Missing Goals
The Hacker News discussion implies a point: without a clear objective function, reasoning evaluation easily degenerates into pattern matching. Models may learn the output format of "looking like reasoning" without actually solving problems that require reasoning. This explains why some models perform excellently on benchmarks yet frequently fail in real-world scenarios.
Chain-of-Thought (CoT) is a prompting or training method that has large models generate a series of intermediate reasoning steps before outputting the final answer. Its representative work comes from Wei et al.'s 2022 paper, whose core finding is that when models are guided to "think step by step," accuracy on arithmetic, commonsense, and symbolic reasoning tasks improves significantly. Since then, CoT has gradually evolved from a prompting trick into a training paradigm, giving rise to "reasoning models" fine-tuned on large amounts of step-annotated solution data. But CoT's effectiveness comes with a side effect: models may generate reasoning chains that are well-formatted and look logically sound yet are disconnected from the final answer—so-called "unfaithful reasoning." This is precisely the technical root of the "equating long chains of thought with reasoning capability" criticized in the article—the length and form of steps do not guarantee that reasoning actually participates in generating the answer.
Benchmarks and data contamination are key background for understanding the phenomenon of "high benchmark scores, poor real-world performance." The questions and reference answers of reasoning benchmarks such as GSM8K, MATH, and BBH are mostly publicly available on the internet, and the pretraining corpora of large models are precisely large-scale web text, so test questions may well have been "seen" by models during training. In this case, high scores reflect memorization and pattern matching rather than reasoning capability. Researchers typically mitigate contamination by rephrasing questions, holding out private test sets, or dynamically generating questions, but it is hard to eliminate entirely. In addition, benchmarks usually only evaluate whether the final answer is correct and do not examine the soundness of the reasoning process, further amplifying the incentive bias of "score as long as the format looks like reasoning."
Multiple Perspectives: Two Understandings of the Goal of Reasoning
Although the original post has limited comments, combined with past related discussions in the Hacker News community, two mainstream views can be identified.
View 1: Reasoning Should Serve Decision Quality
According to analyses by several researchers on Hacker News, the core goal of reasoning should be making better decisions when information is incomplete. This means reasoning evaluation should not only look at whether the final answer is right or wrong, but also at whether the decision process is reasonable under limited information. This view connects reasoning with decision problems in reinforcement learning and emphasizes the practicality of reasoning.
View 2: Reasoning Is a Tool for Compression and Generalization
Another camp (from the Hacker News comment section and public discussions among AI researchers) holds that the goal of reasoning is achieving better generalization with fewer samples. Reasoning enables models to apply combinations of patterns seen in training to new situations, essentially a mechanism of compression and abstraction. Under this understanding, the "goal" of reasoning is to improve data efficiency rather than directly optimize decisions.
The two views are not mutually exclusive, but they differ in emphasis: the former focuses on the output of reasoning (decisions), while the latter focuses on the mechanism of reasoning (generalization). The root of the divergence lies in the understanding of the word "goal"—is it an external task goal or an internal learning goal?
Minimum Description Length (MDL) and "compression is intelligence" provide theoretical support for the view that "reasoning is a compression tool." The MDL principle holds that the best model is the one that can encode data with the shortest description, so learning is equivalent to finding regularity-based compression in data. From this perspective, reasoning steps are the process of inducing a large number of concrete examples into reusable abstract rules, and a model's generalization capability depends on whether it can cover a wide range of situations with a small number of rules. Solomonoff's inductive inference and Hutter's AIXI theory follow a similar line, characterizing intelligence as optimal compression and prediction of observation sequences. This explains why "achieving better generalization with fewer samples" can be regarded as an internal goal of reasoning—it corresponds to the learning mechanism and external utility levels, respectively, alongside the decision-quality perspective mentioned in the article.
Implications for AI Practice
Redesigning Reasoning Evaluation
If we accept that reasoning serves decision quality, then the existing evaluation system needs adjustment. In addition to answer accuracy, indicators of decision process soundness should be introduced, such as whether the model proactively clarifies when information is missing and whether it provides alternatives with reasonable confidence. This is more meaningful than simply increasing the number of reasoning steps.
Goal Definition Before Capability Improvement
For developers, before pursuing stronger reasoning capabilities, the objective function of the application scenario should be clearly defined. Is high accuracy required, or acceptable decisions under low latency? Is an interpretable reasoning chain required, or is only the final result of interest? Different goals imply vastly different requirements for reasoning capability.
Avoiding a Reasoning Arms Race
The Hacker News discussion reminds us that the industry easily falls into an arms race over reasoning capability. But if goals are unclear, stronger reasoning may bring higher computational costs and longer latency without necessarily improving the actual experience. The rational approach is to choose reasoning depth based on the scenario rather than blindly pursuing models that "think better."
Conclusion
The question "what goal is reasoning solving" has no standard answer, but it forces researchers to step back from the capability race and return to the problem itself. Whether it is decision quality or generalization efficiency, only clear goals can turn progress in reasoning capability into real value. For AI practitioners, this may be more important than chasing a few more benchmark points.
One-line Summary
Reasoning is a means, not an end; without clear goals, capability improvements may deviate from real needs.
Paragraph Summary
Starting from a low-traffic Hacker News discussion thread, the article asks a neglected fundamental question: what goal is large-model reasoning actually solving? The author points out that current research assumes stronger reasoning is always better, equating long chains of thought and high benchmark scores with reasoning capability, which confuses means with ends. Without a clear objective function, reasoning evaluation easily degenerates into pattern matching, leading to a disconnect between high benchmark scores and real-world performance. The article outlines two understandings: reasoning should serve decision quality in uncertain environments, or act as a tool for compression and generalization to improve data efficiency. Practical implications include redesigning evaluation systems to incorporate decision-process soundness, defining scenario goals before pursuing capability, and avoiding a blind reasoning arms race.
Related articles
Why Rockets Don't Land Horizontally Like Airplanes: A Physics and Engineering Trade-off
Why don't rockets land horizontally like airplanes with wings? This article explains the engineering trade-offs behind Shuttle-style landings and Falcon 9 vertical landings from three angles: wing lift conditions, orbital velocity costs, and reusable booster structural reuse.

Can AI Governance Tools Block Agent and API Calls?
A Reddit developer questions whether AI governance tools only flag Agent calls rather than block them. We analyze the flagging vs. real-time blocking capability gap, vendor demo mismatches, and key questions to ask when buying.
Perplexity's New Default Setting: The Experience and the Logic Behind It
Exploring the significance and impact of Perplexity's default setting change, analyzing how defaults guide user experience and speculating on model, search scope, or answer style adjustments.