Which ML Projects Will Actually Help You Land a Job Offer?

Build ML projects with real problems, end-to-end engineering, and quantifiable results to stand out to hiring managers.
This article analyzes what ML projects actually impress hiring managers: not tutorial reproductions, but work demonstrating real problem-solving, complete engineering pipelines, and measurable outcomes. Key directions include LLM/Agent applications, full MLOps workflows, and domain-specific solutions addressing genuine industry pain points.
Introduction: Escape the "Tutorial Project" Trap
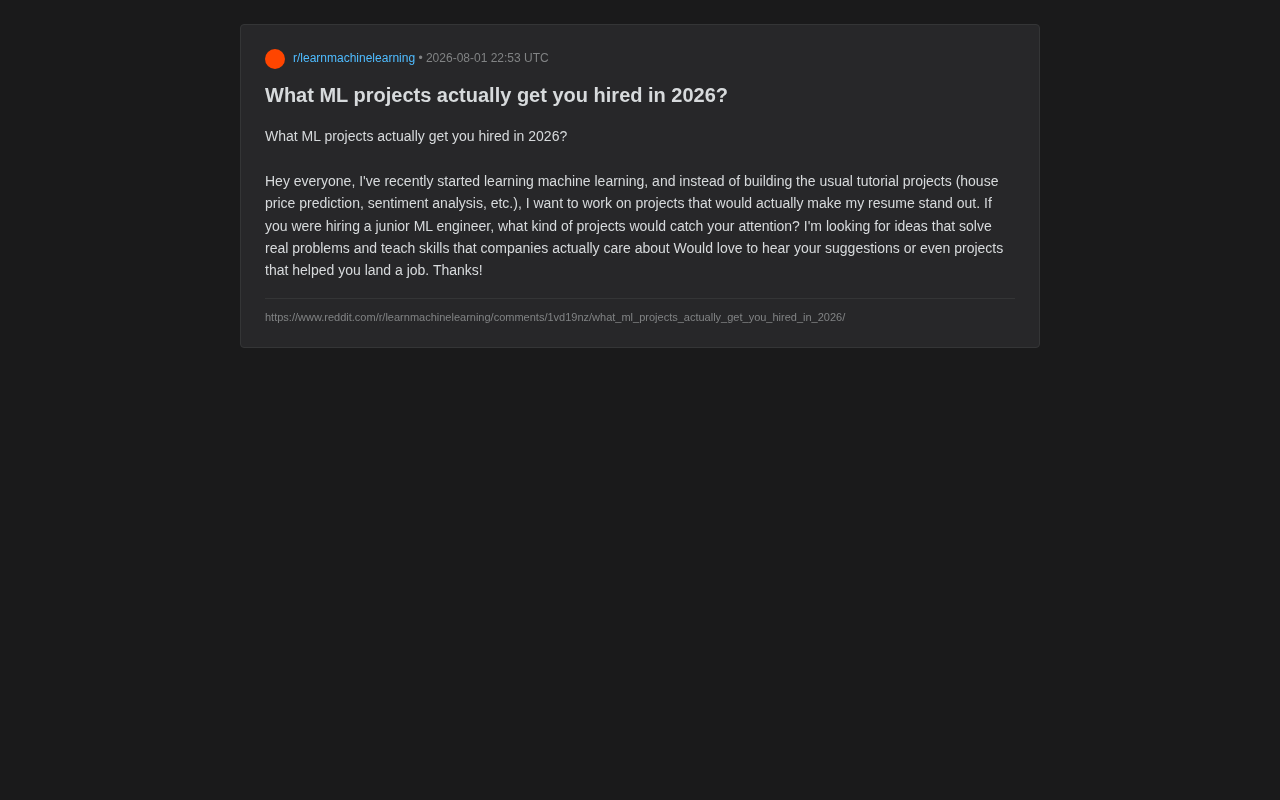
On Reddit's machine learning community, a newcomer posed a question that hits right at the heart of the issue: instead of repeating those overused tutorial projects—house price prediction, sentiment analysis—why not build something that actually makes your resume stand out? If you were a hiring manager, what kind of ML project would catch your eye?
Behind this question lies a harsh reality of today's ML job market: with the proliferation of large model tools and the explosion of AI educational resources, those "portfolio projects" that simply follow along with a YouTube tutorial can no longer prove anything. Hiring managers see hundreds or thousands of resumes every day featuring "Titanic survival prediction" or "MNIST handwriting recognition." These projects don't earn bonus points—they might actually signal a "lack of independent thinking."
What Hiring Managers Actually Care About
From "Knowing How to Call Libraries" to "Solving Real Problems"
Competition for ML positions today is fundamentally a competition of engineering capability and problem-definition ability. With the maturation of platforms like Hugging Face, OpenAI API, and Google Vertex AI, the barrier to calling a high-performance pre-trained model has dropped to just a few lines of Python code. A pre-trained model is one that has been trained in advance on a large-scale dataset, allowing users to simply fine-tune it or call it directly to accomplish specific tasks. This "democratization" trend means that when calling a pre-trained model requires just a few lines of code, being able to write model.fit() is no longer a differentiator. What hiring managers actually want to see is:
- Whether you can define a machine-learning-solvable problem from a vague business requirement;
- Whether you've handled real-world data that's messy, imbalanced, and full of missing values;
- Whether you understand the complete lifecycle of a model after deployment, rather than just getting an accuracy score in a Jupyter Notebook.
In other words, ML projects that land offers are often not about how complex the model is, but about how real the problem is and how complete the engineering is.
End-to-End Capability Beats Showing Off
A single complete end-to-end project—from data collection, cleaning, training, and evaluation to deployment and monitoring—is far more convincing than ten Kaggle notebooks that stop at the modeling stage. In actual work, modeling might account for only 20% of an ML engineer's workload, with the remaining 80% going to data pipelines, feature engineering, deployment operations, and iterative optimization. This ratio is by no means exaggerated—Google pointed out in its famous paper Hidden Technical Debt in Machine Learning Systems that the actual "ML code" in a real ML system represents only a tiny fraction of the entire system, surrounded by vast amounts of data collection, feature extraction, configuration management, serving infrastructure, and monitoring code.
ML Project Directions That Actually Earn Bonus Points
Direction 1: LLM Applications and Agent Systems
As large language models enter production environments, practical applications built around LLMs have become the hottest project type. The key here isn't training a large model (nearly impossible for individuals), but building valuable systems around existing models:
- Domain-specific Q&A systems based on RAG (Retrieval-Augmented Generation), such as connecting to a specialized document library. RAG is an architectural paradigm that combines information retrieval with generative large models—before the model generates an answer, it first retrieves the most relevant document fragments from an external knowledge base based on the user's query, then injects these fragments as context into the large model's prompt, enabling the model to generate answers based on the most current and accurate factual information. A complete RAG system involves document chunking strategies, vector embedding model selection, retrieval optimization for vector databases (such as Pinecone, Weaviate, Milvus), and Prompt engineering, among other engineering components—its complexity far exceeds simple API calls;
- Multi-step Agent workflows capable of calling tools, decomposing tasks, and self-correcting. An AI Agent is an LLM application system with capabilities for autonomous planning, tool calling, and task execution. Unlike traditional single-turn Q&A, Agents can decompose complex tasks into multiple sub-steps, deciding at each step which external tool to call (such as search engines, code executors, database queries), and dynamically adjusting subsequent strategies based on intermediate results. Representative frameworks include LangChain's Agent module, AutoGPT, CrewAI, and others. The core challenge of Agent systems lies in reliability—how to keep the model logically consistent during multi-step reasoning, how to handle fallback mechanisms when tool calls fail, and how to balance cost and latency;
- Engineering practices for evaluating LLM outputs and preventing hallucinations. Hallucination refers to when large models generate content that appears fluent but is actually incorrect or unsupported—this is one of the biggest obstacles to deploying LLM applications in production. Anti-hallucination engineering practices include citation-based fact-checking, output consistency verification, confidence calibration, and human feedback loops.
These types of projects directly correspond to capabilities that enterprises urgently need today and are most likely to spark in-depth discussion during interviews.
Direction 2: Complete MLOps Practice
If you're applying for engineering-focused ML positions, a project demonstrating the full MLOps workflow is extremely powerful. MLOps (Machine Learning Operations) is an engineering practice system that brings DevOps principles into machine learning lifecycle management. It emerged because a large number of ML models perform excellently in the lab but struggle to run stably in production environments—according to Gartner, over 85% of ML projects never make it to production. The core goal of MLOps is to bridge this gap between research and production. A convincing MLOps project should include:
- Containerizing model services with Docker, ensuring consistency across development, testing, and production environments, eliminating the classic "it works on my machine" problem;
- Exposing inference endpoints through FastAPI or similar frameworks, wrapping trained models into RESTful API services that other systems can call;
- Automated training and deployment via CI/CD, building pipelines through tools like GitHub Actions or GitLab CI that automatically trigger model retraining, evaluation, and deployment when data updates or code changes;
- Introducing model monitoring to detect data drift and performance degradation. Data Drift refers to when the statistical distribution of actual input data received by a model after deployment significantly deviates from the data used during training. For example, a consumer behavior prediction model trained on pre-pandemic data might see prediction accuracy plummet during the pandemic. Data drift is primarily categorized into covariate drift (changes in input feature distributions), prior probability drift (changes in target variable distributions), and concept drift (changes in the relationship between inputs and targets). Common tools for detecting data drift include Evidently AI and WhyLabs, and common statistical methods include KL divergence, PSI (Population Stability Index), and KS tests. Production systems typically need automated monitoring and alerting mechanisms that trigger model retraining workflows when drift reaches a threshold.
Such projects prove that you understand "the model is only part of the product" and can transform research results into reliably running production systems. The broader MLOps tool ecosystem also includes MLflow and Weights & Biases (experiment tracking), DVC (data version management), Kubeflow and Airflow (workflow orchestration), and appropriately leveraging these tools in your projects will further demonstrate your engineering maturity.
Direction 3: Solving Real Pain Points in Specific Industries
What most impresses hiring managers are often projects that originate from real needs. For example:
- Custom models built for niche domains (agricultural pest identification, used car pricing, local logistics optimization);
- Combining public datasets with self-scraped data to solve a problem no one else has tackled;
- Clear business metric improvements, such as "reduced customer service response time by 40%."
Even if these projects aren't technically cutting-edge, because they have real scenarios, quantifiable results, and independent thinking, they better demonstrate your engineering value. It's worth noting that the biggest highlight of such projects is the "problem discovery" itself—you need to demonstrate the complete chain of thinking from observing real-world pain points, collecting and cleaning non-standardized data, selecting appropriate modeling strategies, to finally delivering usable results. Hiring managers can judge from this whether you have the ability to independently drive projects after joining, rather than merely executing technical solutions defined by others.
How to Make ML Projects "Speak" on Your Resume
Explain the "Why," Not Just the "What"
Many job seekers list their tech stacks on resumes but overlook the most critical part: why did you choose this approach? What difficulties did you encounter? How did you weigh trade-offs? Hiring managers use these details to assess your engineering maturity. A candidate who can clearly articulate "I tried approach A but found the latency was too high, then switched to approach B which improved performance by 3x" is far superior to one who can only say "I used Transformer." This "decision narrative" ability is known in the industry as Technical Judgment—it reflects whether a candidate can make sound trade-offs based on constraints (latency, cost, data volume, team capabilities) when facing multiple technical options.
Let Data and Results Do the Talking
Every project should have quantifiable outcomes. Not "built a recommendation system," but "the recommendation system I built increased click-through rate by 15%"; not "trained a classification model," but "on extremely imbalanced data, improved F1 from 0.6 to 0.82 through resampling and Focal Loss."
It's worth elaborating on Focal Loss and class imbalance handling here. Focal Loss is a loss function proposed by Facebook AI Research in 2017, originally designed to address the extreme positive-negative sample imbalance in object detection. Its core idea is to introduce a modulating factor on top of standard cross-entropy loss that reduces the loss weight for easily classified samples, making model training focus more on hard-to-classify minority class samples. In practical ML projects, strategies for handling class imbalance also include oversampling (such as SMOTE), undersampling, class weight adjustment, and ensemble learning methods. If a candidate can demonstrate systematic experimental comparisons for imbalance problems in their project—for example, comparing the effects of different strategies and explaining the rationale for their choice—it will significantly enhance their technical credibility and engineering maturity.
Make Your Code and Thought Process Public
Put your projects on GitHub, write a high-quality README, or even publish a technical blog post reviewing the entire process. This not only demonstrates your communication skills but also gives hiring managers confidence that this is truly your independent work, not a simple copy. An excellent README should include project motivation, architecture diagrams, installation and running instructions, core experimental results, and known limitations with future improvement directions. Technical blog posts can adopt a "problem-exploration-solution-reflection" structure to fully present your thinking process. In the open-source community, code quality (clear naming, reasonable modular design, thorough comments, and test coverage) is itself a direct demonstration of engineering capability.
Conclusion: What's Scarce Is Never Technical Skills, But Problem-Solving Ability
Returning to that Reddit learner's original question: ML projects that truly help you land an offer have only three core characteristics—a real problem, a complete engineering loop, and quantifiable results.
In an era where everyone can call large model APIs, technical barriers have been dramatically lowered, but the ability to "discover problems worth solving and thoroughly execute solutions" has become increasingly scarce. Rather than chasing the flashiest model architectures, settle down and find a real problem you genuinely care about, then take it from data to deployment with excellence. One such project outweighs ten tutorial reproductions.
Key Takeaways
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.