Why Does KV Cache Blow Up Your GPU Memory? A Deep Dive into LLM Inference Optimization
KV Cache is the hidden culprit behind GPU memory explosions in LLM inference — here's how it works and how to tame it.
This article explains why GPU memory spikes during LLM inference: KV Cache stores historical Key and Value matrices to avoid redundant computation, trading space for speed. But its memory footprint scales multiplicatively with model layers, sequence length, KV heads, and data precision, making it the top memory consumer in long-context, high-concurrency deployments. The article also clarifies two common misconceptions — why only K and V (not Q) are cached, and how PagedAttention (reducing fragmentation) and FlashAttention (optimizing compute bandwidth) solve fundamentally different problems.
The Real Culprit Behind Skyrocketing GPU Memory Usage
Many developers building LLM applications have run into this puzzling situation: loading model weights only takes up a dozen or so gigabytes of GPU memory, but the moment you run a long conversation, memory usage shoots up like a rocket — jumping from 20GB straight to hundreds of GB. A beginner's first instinct is usually "did the model get bigger?" But that's not the answer.
The invisible monster silently devouring your GPU memory is KV Cache (Key-Value Cache). It's also a favorite topic in technical interviews at top tech companies — if an interviewer asks why KV Cache speeds up inference and why it can blow up memory, and your only answer is "it's a cache," you can kiss that offer goodbye.
The Essence of KV Cache: Trading Space for Time
At its core, KV Cache is a "scratch pad" that Transformer models use during autoregressive generation to store the results of past attention computations. The underlying principle is trading space for time.
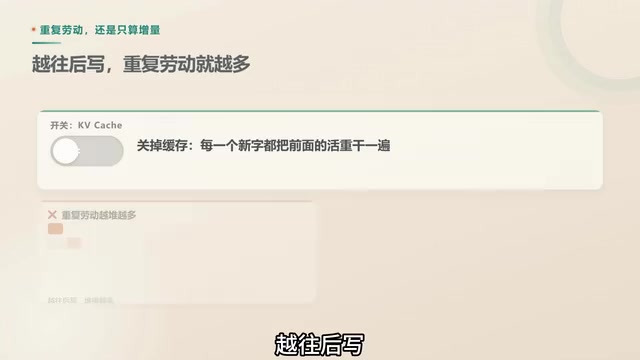
Without it, the model would need to recompute everything from the beginning every time it generates a new token. The longer the sequence, the more computation explodes quadratically — making it completely impractical for real-world use. With KV Cache, past computation results can be reused, and new tokens only need to interact with the cached values during attention. This delivers a qualitative leap in inference speed.
Here's an intuitive example: when a model is generating the sentence "Artificial intelligence reshapes the future," by the time it writes the second word, without caching it would have to redo all the computations for the first word — and the further along it gets, the more redundant work piles up. With KV Cache enabled, past computation results are stored, and only the incremental portion needs to be computed for each new token. The efficiency difference is enormous.
Why Is It Called KV Cache and Not QKV Cache?
There's an important technical nuance here. The Query (Q) vector only represents the current token's query intent — it's used once and discarded with no reuse value. Key (K) and Value (V) vectors, on the other hand, represent the semantic information of historical tokens, and every future token needs to look them up. That's why caching only K and V is the most cost-effective design.
Looking at the Transformer attention mechanism's computation flow: each token at each layer generates three vectors — Query (Q), Key (K), and Value (V). Q represents "what I want to look up," K represents "what label I carry," and V represents "the actual content I hold." The essence of attention computation is using the current token's Q to compute dot products with all historical tokens' K vectors, obtaining weights, and then computing a weighted sum of all tokens' V vectors.
In autoregressive generation, a newly generated token's Q only participates in that single step and is never referenced again. But the K and V of every past token need to be accessed again each time a new token is generated. Without caching, every generation step requires recomputing K and V across the entire context — a time complexity of O(n²). The design of caching only K and V is therefore a precise "pruning" of the critical path in the computation graph, not a naive approach of storing all intermediate results.
Why KV Cache Overwhelms GPU Memory
The crux of the problem is this: every Transformer layer has its own independent cache, and every concurrent request and every sequence must occupy a separate copy of that cache.
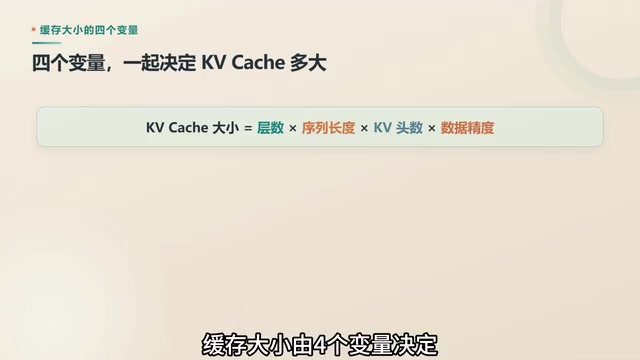
The size of KV Cache is primarily determined by four variables:
- Number of model layers
- Sequence length
- Number of KV heads
- Data precision
One trap worth watching out for: even if you quantize the model weights down to Int4, the KV Cache may still be running in FP16 or even BF16. The result is that your weights take up very little space, but the moment you hit long-context, high-concurrency scenarios, the cache becomes the single largest consumer of GPU memory.
When planning your deployment, never just look at the model file size. You must estimate weight memory, KV memory, and activation memory separately to arrive at a reliable resource budget.
A Survey of Industry Optimization Approaches
To tame this memory-hungry beast, the industry has developed a range of optimization solutions.
PagedAttention: Borrowing from OS Paging
PagedAttention borrows the virtual memory paging concept from operating systems, slicing the cache into small blocks and allocating them on demand — dramatically reducing memory fragmentation. This is one of the key technologies that enables inference frameworks like vLLM to achieve significantly higher throughput.
Traditional inference frameworks, when allocating KV Cache for a request, typically pre-allocate a single large contiguous block of GPU memory based on the maximum sequence length. This causes two problems: internal fragmentation (a short sequence is given space reserved for a long sequence, wasting large amounts of memory that can't be used by other requests) and external fragmentation (free memory is scattered across many locations, and while there's enough total space, no single contiguous chunk is large enough).
PagedAttention splits each request's KV Cache into fixed-size "blocks," each capable of storing the K and V vectors for a certain number of tokens, and uses a block table to record the mapping from logical blocks to physical blocks — analogous to how an operating system uses a page table to manage virtual memory. Physical blocks don't need to be contiguous, they're dynamically allocated on demand and freed when done, reducing memory fragmentation to a minimum. Going further, physical blocks with the same prefix (such as system prompts) can be shared across multiple requests through copy-on-write semantics, saving substantial GPU memory in high-concurrency scenarios.
FlashAttention: Optimizing Computation, Not Storage
FlashAttention reduces the number of HBM (High Bandwidth Memory) accesses through operator fusion. It's important to note that it optimizes computational efficiency — it does not equate to saving storage space. The two address entirely different dimensions of the problem and are commonly confused.
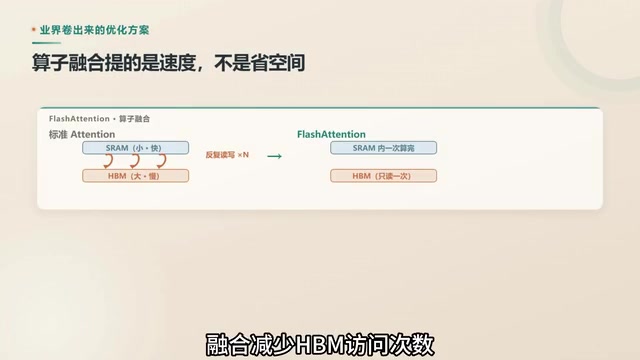
FlashAttention's optimization target is the bandwidth bottleneck in GPU memory hierarchy. GPUs have extremely fast but small SRAM (on-chip cache), and large but relatively bandwidth-limited HBM (what we commonly call "GPU memory"). Standard attention implementations must write the intermediate attention matrix (of size sequence-length-squared) to HBM and read it back with every computation step. For long sequences, this repeated HBM read/write becomes a serious performance bottleneck.
FlashAttention uses a "tiled computation + operator fusion" strategy: it loads Q, K, V matrices into SRAM in tiles, completes the full attention computation on-chip, and only writes the final result back to HBM — reducing HBM accesses from O(n²) to O(n). A side benefit is that it saves the GPU memory needed to store intermediate attention matrices, but the KV Cache itself remains unchanged in size. This means that when estimating long-context GPU memory usage, FlashAttention cannot substitute for PagedAttention or KV quantization, which are specifically designed to reduce cache volume.
Other Strategies
Additional strategies include KV Cache quantization, latent dimension sharing, and sliding window attention — all aimed at fitting more effective context into limited GPU memory. These methods can be combined and used together to support long-context deployment scenarios.
Interview Answer Template
If this topic comes up in a technical interview, here's a solid answer framework:
KV Cache reduces inference latency by caching historical KV matrices to avoid redundant computation. However, its memory footprint grows linearly with the number of layers, sequence length, and concurrency — making it the primary bottleneck in long-context scenarios. Production deployments require a combination of PagedAttention, KV quantization, and context management strategies for comprehensive optimization.
Remember this key insight: KV Cache is not model parameters — it's the short-term working memory used during inference. The longer the conversation and the higher the concurrency, the more likely it is to become your system's bottleneck. Once you truly understand this, you've cleared the first hurdle of understanding LLM inference.
Related articles
Prompt → MCP → Agent → Skill: The AI Terminology Evolution Chain Explained in 5 Minutes
A clear guide to five core AI concepts — Prompt, MCP, Agent, Skill, and Cowork — and how they connect in a layered evolution chain from simple instructions to multi-agent teamwork.
OpenAI Discloses Model Anomalies, DeepMind Launches AGI Forum, NVIDIA Partners on Grid Power Management
Sept 17 AI roundup: OpenAI publishes model anomaly disclosure framework with 6 reports, Google DeepMind launches AGI public forum, NVIDIA leads AI energy management alliance with 18 partners.
Build a Local AI Agent with Python in 10 Minutes: Ollama + PydanticAI in Action
A hands-on guide to building a fully local AI agent with Python, Ollama, and PydanticAI in 10 minutes — covering model selection, tool functions, and conversation loops.