Why Is Qwen3 27B So Slow on a 4090? A Hands-On Guide to Local Inference Performance Optimization

Why the RTX 4090 struggles with Qwen3 27B: VRAM overflow, CPU offloading, and how to fix it.
An RTX 4090 taking over 400 seconds per Qwen3 27B inference request stems from VRAM overflow triggering CPU offloading, where DDR5 and PCIe bandwidth become bottlenecks. This article explains VRAM requirements, quantization, KV cache, and offers targeted fixes for local LLM deployment.
A Classic Local Deployment Dilemma
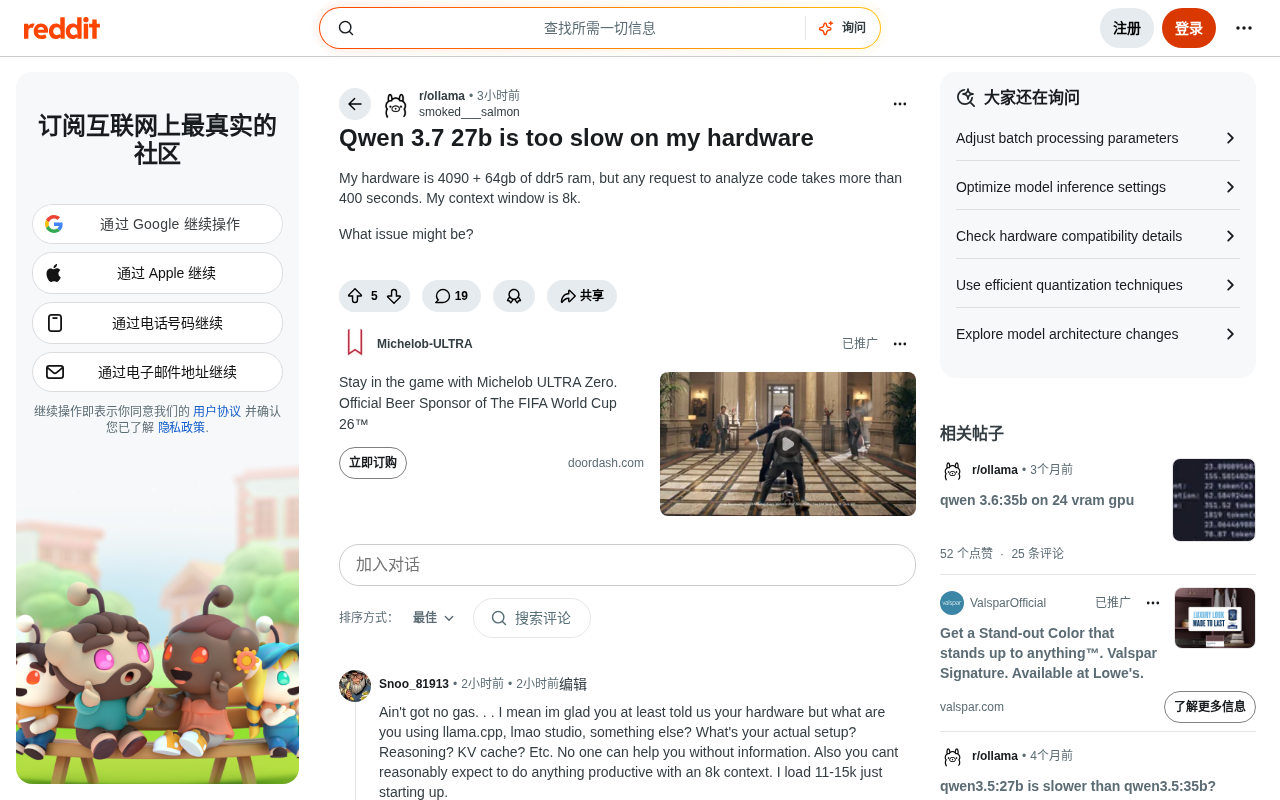
Recently, a Reddit user posted asking for help: he was running a Qwen3 27B-class large model on an RTX 4090 paired with 64GB of DDR5 memory, yet every code analysis request took over 400 seconds to complete—and this was with the context window set to just 8K.
This case is quite representative. As a consumer flagship GPU, the 4090 boasts 24GB of VRAM and formidable compute power. In theory, running a 27B model should be no problem. Yet in practice, each inference took nearly 7 minutes—a speed that simply cannot support day-to-day development work. So where exactly does the problem lie? This article will break it down across three dimensions: hardware resources, model loading strategy, and inference framework configuration.
VRAM Overflow: The Core Cause of Performance Collapse
Just How Much VRAM Does a 27B Model Need?
To understand why the 4090 slows down, we first need to calculate the model's VRAM requirements. A 27B-parameter model, if loaded in FP16 precision, requires roughly 54GB of VRAM for the weights alone (27B × 2 bytes)—far exceeding the 4090's 24GB ceiling.
Even with common 4-bit quantization (such as Q4_K_M), the model weights still require about 16–17GB of VRAM. Add in the KV cache, activations, and runtime overhead, and 24GB of VRAM quickly becomes stretched thin when handling even moderately long contexts.
Background on RTX 4090 VRAM technology: The GDDR6X memory in the RTX 4090 is the highest-spec memory technology among current consumer GPUs, developed by Micron. Compared to GDDR6, GDDR6X introduces PAM4 (Pulse Amplitude Modulation, 4-level) signal encoding, which doubles data throughput at the same physical frequency, ultimately achieving an astonishing bandwidth of over 1000 GB/s. However, increased bandwidth cannot break through the physical limits of memory capacity—the 24GB ceiling is determined by a combination of manufacturing process, chip cost, and power consumption, and is hard to dramatically exceed in the short term. This is also one of the key dividing lines between consumer and professional GPUs: data center cards like the A100/H100 use HBM (High Bandwidth Memory) technology, which achieves 80GB or even larger VRAM capacities within a smaller package footprint via 3D stacking. This is precisely the hardware gap between enterprise-grade inference services and consumer-grade local deployments.
Quantization Explained: Model quantization is a technique that compresses neural network weights from high-precision floating-point numbers into low-bit integers—essentially trading an acceptable loss of precision for lower VRAM usage and faster computation. Mathematically, FP16 (16-bit floating point) can represent about 65,536 distinct values, whereas INT4 (4-bit integer) can only represent 16; quantization "compresses and maps" the former's distribution into the range the latter can express. Naive uniform quantization treats all weights equally, but neural network weight distributions are not uniform—compressing sensitive layers such as the projection matrices in attention layers can significantly amplify errors. The "K" in Q4_K_M stands for the k-quants scheme, and the "M" stands for medium quality level. This is a mixed quantization strategy introduced by llama.cpp: through the concept of "superblocks," each group of weights shares a set of scaling factors, while more sensitive layers (such as the output projections in attention layers) retain relatively higher precision, and other layers use more aggressive compression—striking a balance between compression ratio and model quality. Compared to naive uniform 4-bit quantization, Q4_K_M typically preserves better inference quality at nearly the same VRAM footprint.
The VRAM Cost of the KV Cache: The KV cache (Key-Value Cache) is a core mechanism in the Transformer architecture used to accelerate inference. To understand it, one must first grasp the Transformer's autoregressive generation approach: the model generates only one token at a time, then appends it to the end of the input before generating the next. The attention mechanism requires each new token to be cross-computed against all historical tokens—meaning that without any caching, the longer the sequence, the greater the redundant computation. More specifically, the attention computation in each Transformer layer requires taking the dot product of the current token's Query vector with the Key vectors of all historical tokens, then performing a weighted sum over the Value vectors. At each step of autoregressive decoding, the Key and Value vectors of historical tokens have actually already been computed. The KV cache stores these intermediate results in VRAM, so that each time a new token is generated, there's no need to recompute the attention over the entire sequence from scratch—only the interaction between the current new token and the cached history needs to be computed. However, the KV cache's VRAM usage is proportional to context length, the number of model layers, and the number of attention heads. Taking an 8K context as an example, a typical 27B model might consume an additional 2–4GB of VRAM—not negligible within an already tight 24GB VRAM budget.
The Serial Nature of Autoregressive Generation: Large language models perform inference in an autoregressive manner: each time, only one token is predicted and output, then that token is appended to the input sequence before the next round of prediction, looping until generation is complete. This mechanism makes the inference process inherently serial—generating each token depends on the result of the previous token, and it cannot be parallelized over the entire sequence the way training can. For this reason, the core metric for measuring inference speed is "tokens generated per second" (tokens/s). When VRAM is sufficient and the model fully resides on the GPU, the RTX 4090 running a Q4-quantized 27B model can typically reach 15–30 tokens/s, enough to support a smooth interactive experience. But once CPU offloading is triggered, this speed can plummet to 1–2 tokens/s or even lower—this is precisely the underlying cause of the 400-second response time.
The Key Signal: The CPU and Memory Are Being Forced Into Play
This user happened to have 64GB of DDR5 memory, which is precisely the key clue to the problem. When VRAM runs out, mainstream inference frameworks (such as llama.cpp and Ollama) automatically "offload" a portion of the model layers to system memory, delegating computation to the CPU.
The Relationship Between llama.cpp and Ollama: llama.cpp is an open-source project launched by Georgi Gerganov in early 2023, initially aimed at enabling LLaMA models to run on the CPU of a MacBook. It subsequently evolved rapidly into a general-purpose inference engine supporting GPU acceleration, multiple platforms, and multiple backends, becoming the infrastructure of the local AI inference ecosystem. The GGUF (GPT-Generated Unified Format) model format used by llama.cpp deserves special mention: as the successor to the GGML format, it packages model weights, quantization schemes, the tokenizer, and necessary metadata into a single file, allowing model distribution without additional configuration files—achieving "download and run" simplicity. GGUF also supports embedding model descriptions, recommended parameters, and other information in the file header, making it easy for toolchains to automatically read and configure. It is precisely because of this self-contained, cross-platform nature that GGUF has become the de facto standard for local model distribution—the vast majority of locally deployable versions on platforms like Hugging Face are provided in this format. Ollama, on the other hand, is a higher-level wrapper built on top of llama.cpp, providing a Docker-like model management experience (
ollama pull,ollama run) and an OpenAI-API-compatible HTTP interface, dramatically lowering the barrier to local deployment. The relationship between the two is analogous to that between the Linux kernel and the Ubuntu distribution: llama.cpp provides the underlying inference capabilities, while Ollama handles usability and engineering packaging. Understanding this relationship helps determine which layer's parameters to adjust when encountering performance issues.
The problem is that DDR5 memory bandwidth (about 50–80 GB/s) is more than ten times lower than the 4090's VRAM bandwidth (over 1000 GB/s). More critically, data transfer between the CPU and GPU must also pass through the PCIe bus bottleneck—even the latest PCIe 4.0 x16 specification has a theoretical bidirectional bandwidth ceiling of only about 64 GB/s, roughly 16 times lower than local GPU VRAM bandwidth.
Background on the PCIe Bus: PCIe (Peripheral Component Interconnect Express) is the standard bus protocol connecting the CPU to high-speed peripherals like GPUs and NVMe SSDs in modern PCs. Its bandwidth is determined jointly by "generation" and "lane count": PCIe 4.0 offers about 2 GB/s of unidirectional bandwidth per lane, and an x16 slot (16 lanes) has a unidirectional theoretical peak of about 32 GB/s, or about 64 GB/s bidirectional. In comparison, the RTX 4090's GDDR6X memory interface bandwidth reaches as high as 1008 GB/s—meaning that even if the PCIe bus is fully saturated, its throughput is less than 7% of the GPU's VRAM bandwidth. In actual inference, generating each token requires reading the complete model weights once from the storage tier (VRAM or memory) for computation. If the weights are scattered between CPU memory and GPU VRAM, each inference step triggers cross-PCIe data movement, leaving the GPU idle much of the time waiting for data rather than actually performing matrix operations. This is precisely why "whether the model can fit entirely in VRAM" has a decisive impact on inference speed, rather than depending solely on the GPU's TFLOPS compute figure. As long as large amounts of computation require data to be shuttled across the PCIe bus between the CPU and GPU, inference speed will plummet off a cliff. A 400-second response time can almost certainly be diagnosed as the classic symptom of heavy model layer offloading to the CPU.
How to Diagnose Your Deployment Problem
Step 1: Confirm GPU Utilization
While inference is running, use the nvidia-smi command to observe VRAM usage and compute utilization. If VRAM is fully saturated (close to 24GB) but GPU utilization fluctuates wildly or stays low for extended periods, you can basically conclude that CPU offloading is dragging things down.
nvidia-smi is the official command-line tool provided by NVIDIA that displays GPU temperature, power consumption, VRAM usage, and compute utilization in real time. Continuously monitoring these metrics during inference can quickly pinpoint where the bottleneck lies. If you want to track changes second-by-second more precisely, you can use the watch -n 1 nvidia-smi command to refresh the output every second. Advanced users can also leverage nvtop (a GPU monitoring tool similar to htop) for a more intuitive real-time visualization interface, monitoring multiple GPUs simultaneously.
Step 2: Check the Quantization Level
Confirm which quantization scheme the currently loaded model uses. If you've mistakenly used an FP16 or 8-bit version, a 27B model simply won't fit into 24GB of VRAM. For 4090 users, Q4_K_M or Q5_K_M is usually the best balance point between precision and speed.
Compared to Q4_K_M, Q5_K_M uses about 1 more bit of storage per parameter, increasing the 27B model's weight size by about 3–4GB, but it typically offers a perceptible quality improvement on precision-sensitive tasks such as code analysis and mathematical reasoning. Users can flexibly choose between the two based on their available VRAM headroom. Additionally, the GGUF filename itself usually contains the quantization level information (such as Qwen3-27B-Q4_K_M.gguf), so you can determine the quantization scheme directly from the filename before downloading.
Step 3: Review the GPU Layer Configuration
In llama.cpp or Ollama, the n_gpu_layers parameter determines how many model layers are loaded onto the GPU. If this value is set too low, or if the framework's automatic allocation is unreasonable, a large amount of computation will remain stuck on the CPU side.
llama.cpp and Ollama (built on top of it) adopt a layer-granularity GPU offloading strategy: each Transformer layer of the model can independently be assigned to run on either the GPU or the CPU. Setting n_gpu_layers to -1 means loading all layers (including the embedding and output layers) onto the GPU—this is the optimal configuration when VRAM is sufficient. If VRAM cannot hold all layers, you can gradually lower this value to find the maximum number of layers that just fits into VRAM, ensuring at least that most of the computation is completed on the GPU.
Targeted Optimization Solutions
Solution 1: Choose a More Aggressive Quantization Level
For running a 27B model on a 4090, Q4_K_M quantization is recommended—the weights take up about 16–17GB, leaving sufficient headroom for the KV cache and runtime overhead of an 8K context, ensuring all layers can fit into VRAM. If it's still tight, you can try Q3_K_M, trading a small amount of precision for full GPU operation.
Q3_K_M compresses each weight to about 3 bits, reducing the 27B model's weight size to about 12–13GB and greatly easing VRAM pressure. The cost is that the model's performance on complex reasoning tasks may decline somewhat, but for relatively straightforward tasks such as code completion and Q&A, the actual impact is usually within an acceptable range. It's advisable to do simple benchmarking on your target task before deciding.
Solution 2: Maximize GPU Layer Loading
Manually set n_gpu_layers to a large value (-1 means loading everything onto the GPU). The goal is to have the entire model running in VRAM, completely avoiding data movement between the CPU and GPU. Only when the model fully resides in VRAM can the 4090's compute power truly be unleashed.
In Ollama, this can be configured via PARAMETER num_gpu -1 in the Modelfile. When using llama.cpp's llama-server or llama-cli directly, specify it via the command-line argument --n-gpu-layers -1. After configuring, run nvidia-smi again to confirm that VRAM usage meets expectations, verifying whether the configuration has taken effect.
Solution 3: Reevaluate the Model Scale
If the 27B model still doesn't run smoothly after quantization, consider switching to a 14B or smaller model. For tasks like code analysis, a 14B model running at full speed in VRAM often delivers a better actual experience than a 27B model forced to offload to the CPU. The value of response speed to a development workflow is sometimes more important than a model's absolute capability.
Research in recent years has shown that model capability is not linearly correlated with parameter count. An important theoretical source of this understanding is DeepMind's "Chinchilla" research published in 2022: through systematic experiments, the study found that the industry at the time commonly suffered from the problem of "models being too large and training data insufficient"—under a fixed compute budget, appropriately shrinking the model size and substantially increasing the number of training tokens often yields better final performance. Chinchilla (70B parameters, trained on 1.4 trillion tokens) outperformed Gopher (280B), which had several times its parameter count, on numerous benchmarks—powerfully demonstrating that the sufficiency of training data is just as important as model scale. This finding drove the subsequent rise of the "data quality first" training paradigm and is one of the important reasons why smaller-parameter models (in the 7B–14B range) have in recent years dramatically caught up with, and even surpassed, earlier larger models. A 14B model trained on high-quality data and instruction-tuned can be entirely on par with, or even better than, an inefficiently running 27B model on specific tasks such as code generation and debugging. Taking the Qwen series as an example, Qwen3-14B scores comparably to the previous generation's larger models on code-related benchmarks, yet requires only about 8GB of VRAM (Q4 quantization), providing ample headroom for the 4090.
Solution 4: Optimize Context and Batch Settings
An 8K context isn't large in itself, but if a high batch parameter is also set, it will further crowd out VRAM. While still meeting task requirements, appropriately narrowing the context length can free up more VRAM space for model weights.
The batch size (--batch-size or n_batch) controls the number of tokens the model processes in parallel during the prompt processing phase. A larger batch value speeds up the initial processing of the prompt but temporarily consumes additional VRAM. For interactive, single-user local deployment scenarios, lowering n_batch to 256 or 512 usually won't noticeably affect the experience, yet it can provide some buffer space when VRAM is tight. Additionally, the --ctx-size (or n_ctx) parameter directly controls the maximum context length; the KV cache pre-allocates VRAM according to this value—if your actual tasks rarely use contexts beyond 8K, lowering this value to 4096 or even 2048 can immediately free up VRAM space.
General Lessons for Local Large Model Deployment
This case exposes a common misconception when deploying large models locally: having a powerful GPU does not equal being able to run large models smoothly. The real bottleneck often lies in whether the model can fit entirely into VRAM.
Once the CPU offloading mechanism is triggered, even the most powerful graphics card will be dragged down by memory bandwidth and the PCIe bus. Therefore, when choosing a model, one should follow a basic principle: prioritize ensuring the model can reside entirely in VRAM for operation, and let quantization level and parameter scale serve this goal.
This logic applies equally in multi-GPU scenarios. Two RTX 3090s (24GB each, 48GB total VRAM) connected via NVLink can run a 27B model in full FP16 precision; whereas without NVLink, the two cards can only communicate via PCIe, likewise encountering the bandwidth bottleneck.
The Fundamental Difference Between NVLink and PCIe: NVLink is NVIDIA's proprietary interconnect technology designed specifically for high-speed communication between GPUs, with bandwidth far exceeding standard PCIe. Taking NVLink 3.0 as an example, its unidirectional bandwidth can reach 600 GB/s, with a bidirectional total of 1200 GB/s—about 18 times the 64 GB/s bidirectional of PCIe 4.0 x16. The design philosophy of NVLink is to eliminate the bottleneck of inter-GPU communication, allowing multiple GPUs to directly access each other's VRAM, approximating from the software perspective a single larger unified VRAM pool. NVSwitch, on the other hand, is a switching chip aimed at data centers that allows up to 8 GPUs to form a fully interconnected topology, where each GPU can access the VRAM of all other GPUs at NVLink speed—this is precisely the technical foundation for "VRAM pooling" in A100/H100 server nodes. It's worth noting that consumer GPUs (including the entire RTX 3090/4090 series) do not support NVLink interconnect—NVIDIA restricts this feature to professional-grade product lines such as Quadro/Tesla, so multi-card collaboration is inevitably constrained by PCIe bandwidth. What can truly break through the single-card limit is professional-grade hardware configurations equipped with high-bandwidth interconnects (such as NVLink and NVSwitch), which is also the core gap in hardware architecture between data-center-grade inference services and consumer-grade local deployments.
For users with 24GB VRAM cards like the RTX 4090, a Q4-quantized 27B model is the feasible upper limit, while a 14B-class model provides more comfortable operating room. Understanding the matching relationship between hardware and models is the first lesson in mastering local AI inference.
Key Takeaways
- VRAM is the hard ceiling: Whether the model can fit entirely into VRAM determines the performance ceiling—not the GPU's compute power itself.
- CPU offloading is a performance killer: The dual bottlenecks of DDR5 memory bandwidth and the PCIe bus leave even the most powerful GPU unable to perform.
- Quantization selection requires careful calculation: Q4_K_M is the recommended baseline for running a 27B model on a 4090; drop to Q3_K_M when VRAM is tight.
- Full GPU layer loading is the goal:
n_gpu_layers -1is the top priority in configuration; verify VRAM usage withnvidia-smi. - Small and fast beats large and slow: A 14B model running at full speed often delivers a better actual development experience than a 27B model forced to slow down.
Related articles

Apple HomeView Hands-On Review: Is the $300 Smart Home Hub Worth It?
Apple HomeView hands-on: a $300 smart home hub with facial recognition for quick account switching, but no App Store or voice recognition. Is the wall-mounted version worth it? Should you buy the first generation?

Meta Muse Wonder Launch: What It Means for Meta's Return to the Frontier AI Race
Meta releases Muse Wonder and WonderFull, benchmarks reach the frontier, community feedback is polarized. An in-depth look at Meta's return to the frontier AI race, its personal agent strategy, and Zuckerberg's different path.

Apple Home Smart Home Lineup Leaked: LG and Schneider Team Up, UWB Door Lock on Board
Apple Home ecosystem gains new LG and Schneider devices: UWB smart lock with proximity unlock, 2.5K dual-camera doorbell, privacy indoor camera, and AirPods-like seamless pairing.