Wity-1 Reasoning Decision Model: A New Approach Between Full Reasoning and Zero Reasoning

Wity-1 claims to balance intelligence and speed by stopping reasoning the moment an answer is reached — but performance data is unverified.
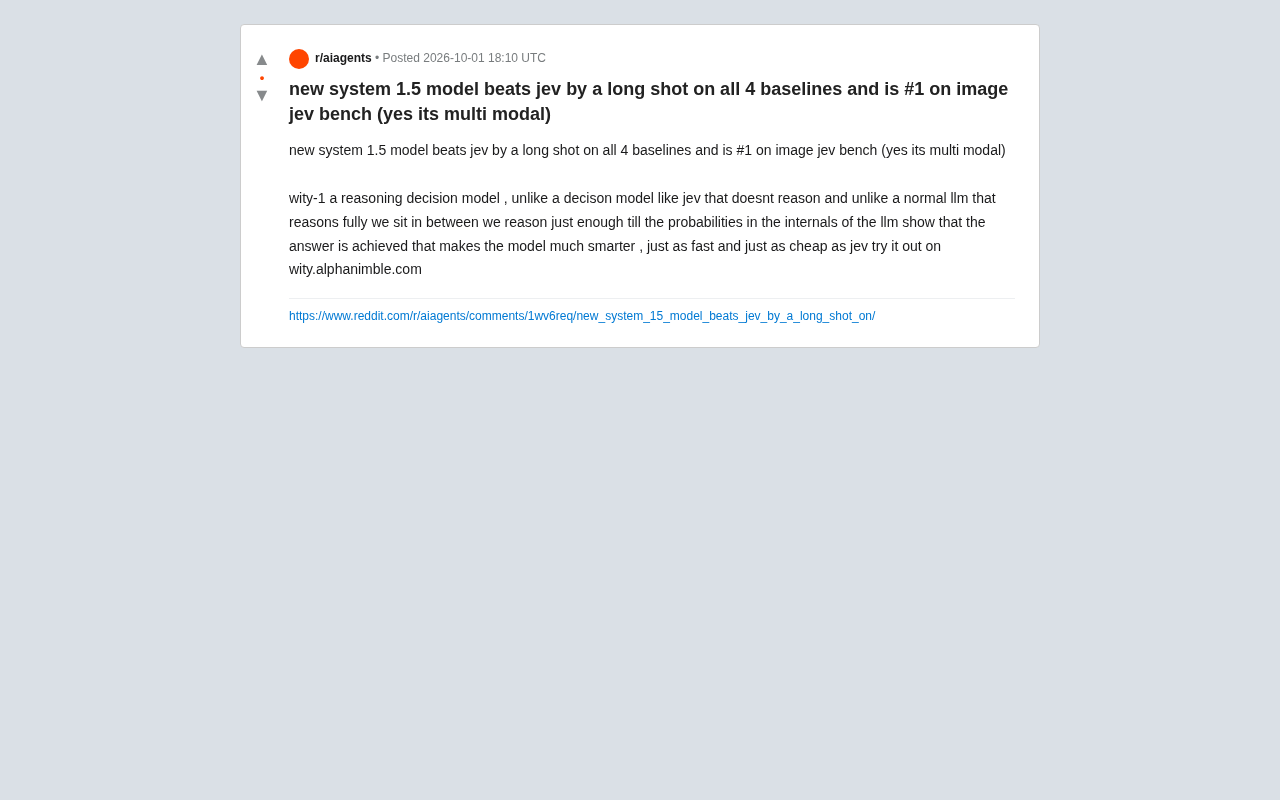
Wity-1, a self-described "reasoning decision model," has attracted attention on Reddit after its team claimed it outperforms decision model JEV across four baselines and ranks #1 on Image JEV Bench, with multimodal support. Its core idea is to sit between pure decision models (fast but shallow) and full reasoning LLMs (smart but slow) by monitoring internal probability distributions and stopping reasoning adaptively once an answer is reached. While this targets the real "overthinking" problem in modern reasoning models, all performance claims are currently self-reported with no third-party evaluation or reproducible details — treat them as unverified until independently confirmed.
A New Species: The Reasoning Decision Model
A new model called Wity-1 has been gaining attention on Reddit. Its development team claims it significantly outperforms a comparison model called JEV across all four baseline tests, and achieves first place on the Image JEV Bench. Notably, the model also supports multimodal capabilities, enabling it to handle image-related tasks.
A word of caution: these figures currently come solely from the developers' own social media announcements, with no third-party independent evaluations or complete technical papers to back them up. Readers should approach these claims with appropriate skepticism.
Core Positioning: Between Two Extremes
Wity-1 is defined as a "reasoning decision model." To understand what makes it distinctive, it helps to first look at the two existing model paradigms it sits between.
Decision Models vs. Reasoning LLMs
On one end are decision models like JEV, which directly output decisions without explicit reasoning. These models are fast and cost-efficient, but may lack depth when handling complex problems.
On the other end are fully reasoning large language models (LLMs), which engage in thorough chain-of-thought processing. These models tend to be "smarter," but at the cost of lengthy reasoning chains, higher latency, and greater computational overhead.
Wity-1's "Just Enough" Strategy
According to the development team, Wity-1 positions itself in the middle: it only reasons to the point where it's "just enough" — stopping when the LLM's internal probability distribution indicates that an answer has been reached.
The core logic of this mechanism is: not every question needs a full reasoning chain. Instead, the model dynamically determines when it has "thought things through." The team claims this allows the model to remain intelligent while matching the speed and cost of the pure decision model JEV.
The "dynamic early exit" mechanism has a reasonable research foundation in academia. The core idea is that neural networks, when processing simple inputs, can arrive at high-confidence answers without passing through every layer or every reasoning step. Researchers typically insert "confidence probes" at intermediate layers of the network — when the entropy of a layer's output probability distribution is sufficiently low (meaning the model is highly confident about a particular answer), computation is terminated early. For language models, this mechanism can be applied at the token level (whether each token requires a full forward pass) or at the reasoning-chain level (when to stop generating thinking steps). Wity-1 claims to monitor the "LLM's internal probability distribution" to determine when an answer has been reached — this theoretically falls into the latter category. However, the specific method for training the model to learn this self-stopping signal is the critical technical challenge, and also the part that remains most opaque based on currently available information.
Why This Direction Is Worth Watching
"Reason just enough" actually addresses a genuine pain point in today's AI reasoning landscape: overthinking.
Many reasoning models generate large amounts of redundant thinking tokens even for simple questions, wasting compute and slowing response times. If it's possible to adaptively control reasoning length by monitoring the model's internal state (such as probability convergence), the theory is that you can achieve a better balance between accuracy, speed, and cost.
This type of "adaptive reasoning depth" or "dynamic early exit" thinking has already been explored in academic research, and Wity-1's attempt to productize it is what makes it worth keeping an eye on.
The "overthinking" problem is especially pronounced in chain-of-thought (CoT) reasoning models like o1 and DeepSeekAd-R1. These models, trained extensively with reinforcement learning, have learned to generate lengthy internal reasoning processes before answering — producing impressive results on complex tasks like math and coding, but also introducing clear side effects: even for trivially simple questions like "what is 1+1," the model may generate hundreds or even thousands of thinking tokens, causing latency spikes and dramatically increased inference costs. Researchers have found that this redundant reasoning doesn't always correlate with higher accuracy — in some cases, excessively long reasoning chains actually cause the model to "circle back to the wrong answer." As a result, getting models to think deeply on complex problems while responding quickly on simple ones has become one of the central challenges in reasoning model efficiency optimization.
Staying Rational
Based on the information publicly available, this post reads more like a product teaser than a verified technical release. Several key questions remain unanswered:
- What exactly JEV refers to and how its baselines are defined is not explained;
- Claims like "outperforms across all four baselines" and "#1 on Image JEV Bench" lack reproducible evaluation details;
- The specific implementation of "monitoring LLM internal probability distributions to determine when an answer is reached" has not been disclosed.
The team has provided a demo link (wity.alphanimble.com), so interested readers can try it out and form their own impressions. Until independent verification is available, it's advisable to treat these claims as unconfirmed assertions rather than established facts.
Summary
Wity-1's proposal of "reasoning just enough" is an appealing direction — it targets the real challenge of balancing efficiency and intelligence in reasoning models. But the performance advantages it claims currently remain at the level of developer self-reporting. Its true value will need to be verified through more transparent evaluations and broader real-world use.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.