#LLM训练
9 related articles

The Full LLM Building Pipeline: Why Most Explanations Stop at the Transformer
Most LLM explainers stop at the Transformer, but data pipelines, post-training recipes, evaluation, and systems engineering really determine model quality. Based on a Stanford CS229 lecture.
What Does LLM Training Actually Do? The Underlying Logic from Random Noise to Intelligence
An in-depth look at the essence of LLM training: from random noise to intelligence. Covers backpropagation, gradient descent, GPT-3 and Llama training data, and how models learn to predict through billions of updates.
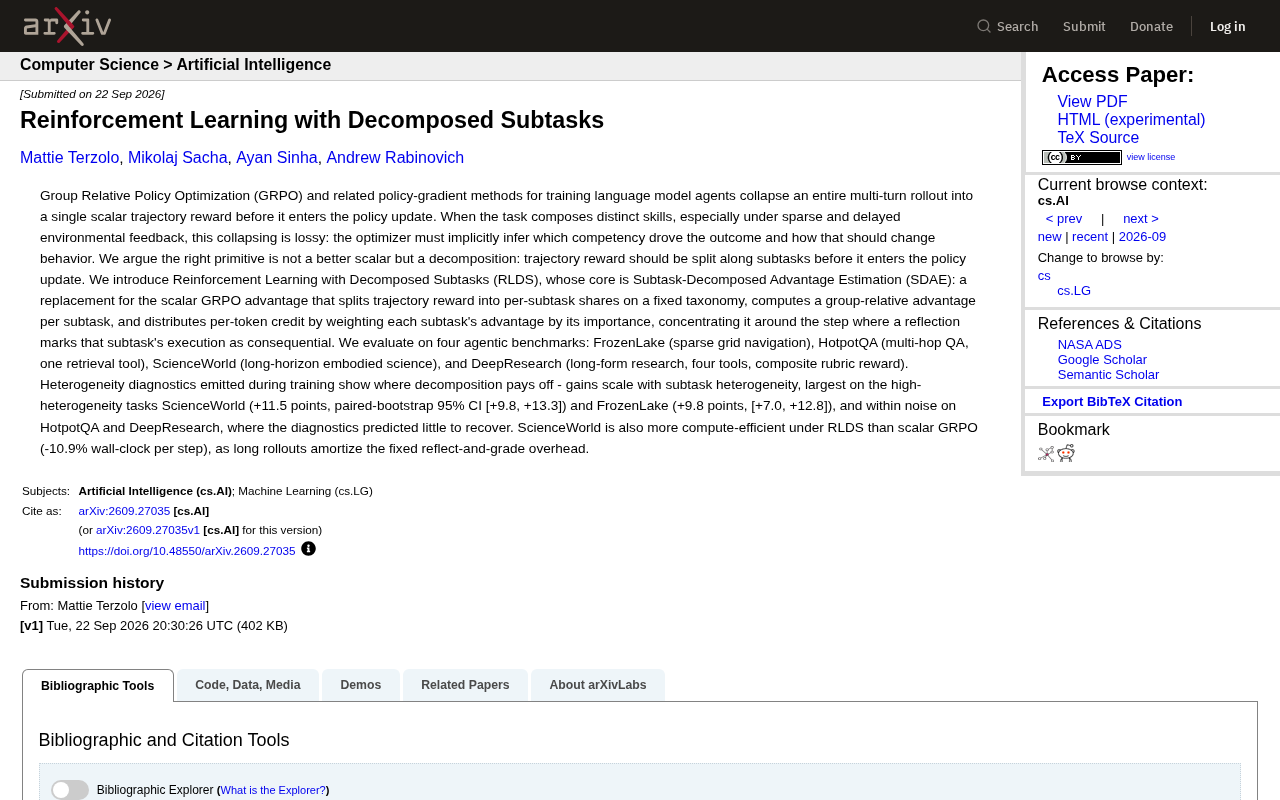
RLDS: Rethinking Credit Assignment in Reinforcement Learning via Subtask Decomposition
RLDS proposes Subtask-Decomposed Advantage Estimation (SDAE) to replace GRPO's scalar rewards, achieving up to +11.5 points on ScienceWorld and FrozenLake benchmarks while reducing compute overhead.

Score Centering: A Numerical Solution for Stabilizing Off-Policy Reinforcement Learning
Together.ai researchers Marek and Ryabinin propose Score Centering, reducing gradient variance to stabilize off-policy RL training for LLMs and address numerical sensitivity.
 Tech Frontiers
Karpathy Open-Sources autoresearch: A Deep Dive into the AI-Powered Automated Research Tool with 80K Stars
Andrej Karpathy open-sources autoresearch, an AI Agent tool that automates nanochat training experiments on a single GPU. With 80K+ GitHub Stars, we break down its architecture and impact.
 Product Reviews
Unsloth: An Efficient Open-Source Tool for Local LLM Fine-Tuning
Unsloth is a 63,000+ star open-source project on GitHub with a Web UI for locally training and fine-tuning LLMs like Gemma 4, Qwen3, and DeepSeek on consumer GPUs.
 Product Reviews
Unsloth: A Powerful Tool for Training Open-Source LLMs Locally
Unsloth is an open-source tool with 63K+ GitHub stars that provides a Web UI for locally training and running LLMs like Gemma 4, Qwen3.6, and DeepSeek.
 Product Reviews
Unsloth: The Open-Source Tool That Makes Local LLM Fine-Tuning 5x Faster
Unsloth is an open-source LLM fine-tuning tool with 63K+ GitHub stars. Supporting Gemma 4, Qwen 3, and DeepSeek, it boosts training speed 2-5x and cuts VRAM by 80% via LoRA/QLoRA, with a Web UI for easy local fine-tuning.
 Product Reviews
Unsloth: The Best Open-Source Tool for Local LLM Fine-Tuning (2025 Guide)
Unsloth is an open-source LLM training tool with 63K GitHub stars. Fine-tune Gemma 4, Qwen3, DeepSeek locally with 50% less VRAM and 2-5x faster training speed via Web UI.