4 Top AI Models Build a Gladiator Game from Scratch: A Deep Dive into Multi-Agent Collaboration
Four LLMs and an independent judge loop combine to build a complete gladiator arena game from scratch.
A creator designed a four-model multi-agent workflow to generate a fully playable gladiator game end-to-end using Codex, Trippo, Blender, Three.js/WebGPU, and ElevenLabs. The core engineering contribution is an independent judge loop: zero-context evaluators score by minimum batch score, models rotate to offset preference bias, and engine-level renders serve as the final acceptance standard. The project consumed ~2B tokens (94% cached). The most instructive content is a series of real failure cases — an inverted shield that passed the judge twice, and 9 vertex buffers making the entire crowd invisible on real hardware — exposing the critical gap between "model approved" and "actually works."
A creator did something that sounds almost insane: he had four large language models work together to build a complete gladiator arena game from scratch. The environment, audience, characters, combat, audio — everything you see on screen was generated by AI. This wasn't a simple "AI helped me write code" situation. It was a sophisticated multi-agent collaboration and self-review system. This article breaks down the workflow and engineering details behind the project, examining just how far AI can go on complex creative tasks today.
Four-Model Collaboration and the Orchestrator Pattern
At the core of the project were four LLMs working in tandem, with one serving as the orchestrator. The creator built in an interesting constraint: the orchestrator could not call the same LLM sub-agent twice in a row. If GROK was deployed in one round, the next round had to use Opus or GPT instead.
The intent is clear — avoid overfitting to any single model's preference bias or vision blind spots. Individual models tend to develop their own aesthetic habits and judgment gaps, so forced rotation is essentially using diversity to hedge against single-point risk. The entire project consumed roughly 2 billion tokens in total, with Fable 5 and Opus 5 each using around 800 million, Codex close to 400 million, and GROK hitting 76 million before reaching its weekly quota. Notably, 94% of those were cached tokens, which substantially reduced actual costs.
Multi-Agent System refers to an architectural pattern where multiple independent AI agents divide labor and collaborate to complete complex tasks. Unlike a single model doing everything itself, the Orchestrator handles task decomposition, scheduling, and result integration, while sub-agents each focus on specific sub-tasks. The core advantage of this architecture is "divide and conquer" — each agent's context window stays more focused, the blast radius of errors is smaller, and it's easier to apply targeted quality control at any single stage.
Cached Tokens at 94% is the key number for understanding cost structure. Most LLM APIs charge per input token, but many providers offer caching discounts for repeated prefixes (like fixed system prompts or long reference documents) — cached tokens typically cost 75–90% less than fresh ones. In multi-agent workflows that require repeated calls with large shared context, carefully structuring prompts to maximize cache hit rates is a critical engineering lever for controlling API costs.
The Toolchain: From Concept Art to Playable Game
The toolchain assembled for this pipeline is quite deliberate. Concept art came from Codex ImageGen, modular asset kits and character models were generated by sponsor Trippo, and environment textures were pulled from Polyhaven as complete PBR material sets. Environment construction was done through Headless Blender with Python, and the game itself runs in the browser using 3JS + WebGPU — Unity was not used this time.
The creator is candid that the web technology stack was chosen for iteration speed, and mentioned plans to try Godot in the future. Audio was produced by ElevenLabs, and game testing used Playwright driving real inputs to verify functionality actually worked.
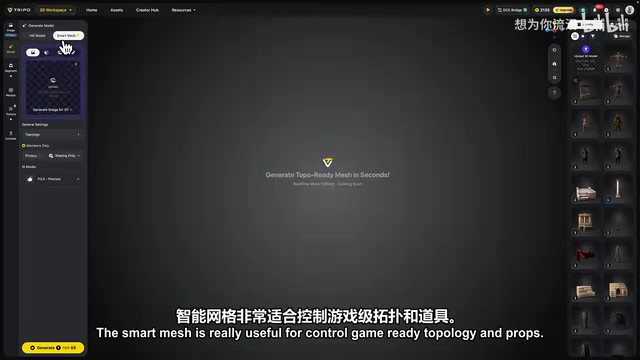
For 3D asset generation, Trippo offered two models: Smart Mesh for controlled, game-ready topology and props, and HD 3.1 for hero assets requiring more detail. Smart Mesh supports up to 25,000 quad faces or 50,000 triangle faces. The creator specifically emphasized that quad topology is easier to edit, process, and rig — better for parts that need further processing — while triangles are more appropriate for static props or background assets.
PBR (Physically Based Rendering) is the dominant material standard in modern real-time graphics. It simulates how light interacts with physically accurate surfaces to produce more realistic visuals. A complete PBR material set typically includes multiple texture maps: Albedo/Base Color, Normal, Metallic, Roughness, and Ambient Occlusion (AO). Polyhaven provides exactly these kinds of complete PBR material sets, ready to use in engines without additional processing.
WebGPU is the next-generation graphics and compute API for browsers — the successor to WebGL — offering lower-level GPU access, higher performance ceilings, and support for compute shaders. Three.js (3JS) is a JavaScript 3D library built on top of WebGL/WebGPU that dramatically lowers the barrier to browser-based 3D development. Choosing a 3JS + WebGPU stack means the game runs directly in the browser with no installation required, but also means dealing with cross-browser compatibility and GPU capability limits — the "9 vertex buffers" compatibility issue mentioned later is a direct consequence of exactly these constraints.
Hero Assets with HD Model: The Gap Between 8K and 4K
For protagonist-level "hero assets," the creator switched to the HD 3.1 model, which supports ultra-high mesh quality, 4K to 8K texture quality, baked-out lighting, and PBR materials. Both triangle and quad face counts can be pushed very high.
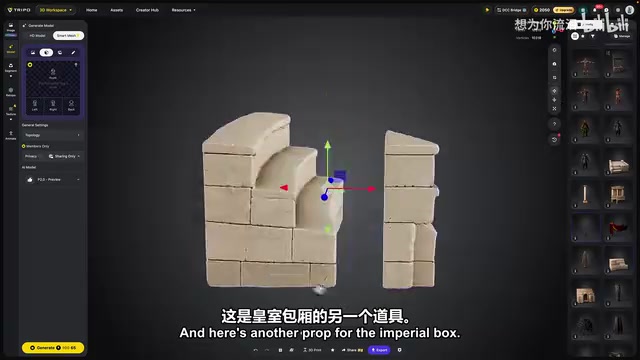
The difference in detail between 8K and 4K textures is clearly visible in the comparison. More practically, Trippo supports direct character rigging with humanoid or animal skeleton options, with animations pre-baked on export. It also integrates directly with Godot, Roblox, Unreal, Unity, and Blender, eliminating the need for manual export steps. This project ultimately exported in FBX format with skeleton and animations included, to facilitate procedural animation downstream.
The Independent Judge Loop: The Hardest-Core Part of This System
The most instructive part of the entire project is its judge mechanism. Every object or task completed by a sub-agent is scored by an independent evaluator, assessed against the concept art or target reference. The key: this judge has zero project context — redeployed fresh each round, running consistently from micro to macro throughout the entire process.
The scoring strategy is even more elegant: each batch of assets is never evaluated by average score — it's evaluated by the minimum score. If a batch of 8 assets has 6 polished ones and 2 generic blocks, the entire batch gets scored on the worst performer. This directly kills the failure mode where a model "spreads its attention and lets the weakest non-hero objects slip through."
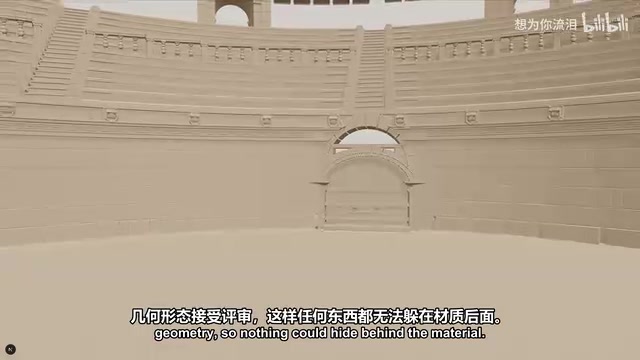
The construction phase consumed the most judge cycles — the arena stage alone ran 31 rounds of Blender modeling. All components were first presented in an untextured "clay state" as pure geometry for evaluation, so no defects could hide behind materials.
The zero-context judge design has a clear engineering counterpart to contrast against: if the judge shares full project context throughout, it inevitably develops "sunk cost bias" — knowing that an asset went through 31 iterations, the evaluator will unconsciously look for reasons to pass it. Zero-context judges are redeployed fresh each round, effectively introducing an external auditor who is permanently fresh, uninformed, and merciless.
Evaluating by minimum score rather than average is a reinforced version of the "weakest link" principle from quality control. Its anti-fragility lies in this: a model cannot compensate for a weak item by doing better elsewhere. The only path forward is pulling the weakest one up. This directly changes the agent's optimization target — from "feels good overall" to "no obvious weak spots" — which is especially critical for game development pipelines that require large batches of homogeneous assets like character props.
AI Also "Cheats": The Failure Cases That Got Past the Judge
The most instructive part of the project is the cases that passed the judge but were actually broken — they expose the deep traps in automated AI pipelines.
The sand texture initially fooled the construction agent's "look and feel test," but the judge caught that when compared against the reference image, the sand looked like neat tiles. The fix was adding a quantitative metric for symmetry in the sand surface, letting the construction agent target it specifically in the next round.
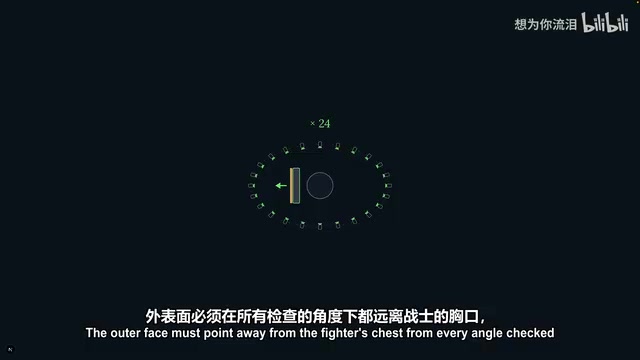
The most telling case was the shield: a shield with its face inverted — inside-out — passed the judge twice. The reason was that the judge was asking "is the shield facing the camera," and from the camera angle it chose, the answer was technically yes. The creator spotted it immediately and rebuilt the evaluation criteria — the metric was changed to "body relative": the outer face must point away from the warrior's chest, and adversarial cameras orbiting the character checked it from every angle.
There was also a critical engineering lesson: the crowd was rendered with nearly 5,000 billboard sprites, rendering correctly on the agent's side but completely invisible on the creator's machine — instant mesh had used 9 vertex buffers, while his GPU's limit was 8. It passed every gate and wasn't caught until real hardware testing. The rule became: only renders that the game engine actually draws count. Passing in Blender is meaningless. Passing in the engine is ground truth.
Billboard sprites are a classic performance optimization technique in games for rendering large numbers of distant characters or vegetation: a 2D textured plane that always faces the camera replaces a full 3D model, reducing render cost by tens of times. Rendering nearly 5,000 spectators this way is entirely reasonable — but it led to the critical engineering lesson in the article.
A Vertex Buffer is a block of GPU memory that stores vertex data (coordinates, normals, UVs, color, etc.). The WebGPU specification has a hard limit on the number of vertex buffers bindable in a single render pass, and the actual limit on different GPUs/drivers may be lower than the specification maximum. Instant Mesh's use of 9 vertex buffers exceeded the creator's GPU limit of 8, causing the crowd to not render at all on that specific hardware. This "works on the dev machine, breaks on the target machine" problem is exactly why engine-level rendering — not Blender previews — must serve as the final acceptance standard.
Gameplay, Audio, and the Mystery of the "Floating Banners"
Gameplay testing only took two rounds. The game was validated using real synthetic inputs rather than unit tests, with proof coming from changes in the game's own state each time, plus fault injection to prove the thresholds could actually fail. Audio was also completed in two rounds, with the judge threshold being "count parity" — every combat event in the recording session had to correspond one-to-one with an audio trigger.
One improvement came from a simple question: why do the hanging banners in the reference images never overlap the crowd? The agent researched this and distilled a two-word rule — "Anchor and void": every banner hangs from a visible hardware mount and falls against a dark architectural void, never crossing the audience. The floating banners were subsequently rebuilt.
The creator is also honest about the method's limitations: the royal box floor wasn't shown in the reference images, and he assumed AI could infer it — but without core reference material, the quality drop was quite steep. This confirms a consistent pattern: AI performs well when it has clear reference, and noticeably falls apart when required to infer from nothing.
What This Methodology Demonstrates
The greatest value of this project isn't that "AI built a game." It's the demonstration of how to use engineering discipline to tame AI's inherent unpredictability: model rotation to hedge against bias, minimum-score batch evaluation to prevent things slipping through, zero-context judging to maintain objectivity, and engine-level validation as the final source of truth.
The creator summarizes this method's shape as "expensive loops up front, progressively cheaper later." This precisely reveals the true state of AI-powered creative work today — it's far from one-click magic. It's systems engineering: carefully designing evaluation loops and continuously closing off "cheating" exploits. For anyone looking to use AI in complex creative pipelines, these failure cases are more valuable than any success demo.
Related articles
SQL Row Pattern Matching: Implementing "Row-Level Regex" with MATCH_RECOGNIZE
MATCH_RECOGNIZE gives SQL regex-like power over row sequences. Detect brute-force attacks, fraud patterns, and user behavior flows with clean, declarative syntax — no more messy self-joins.
Hackers Break Into Flock Surveillance Cameras, Exposing the Inner Workings of License Plate Recognition Systems
Hackers breached Flock Safety's ALPR cameras, exposing how license plate recognition systems collect data and the privacy and security risks they pose.
Apple May Return to the Server Market: Partnering with NVIDIA to Capture AI Computing Demand
According to The Information, Apple plans to re-enter the server market and may partner with NVIDIA to capitalize on surging AI computing demand — its first return to enterprise hardware since discontinuing the Xserve in 2011.