66 Problems Beat a Nature Paper? TerminalBench Becomes the New Yardstick for Frontier Labs

TerminalBench has only 66 problems yet is tracked by every frontier lab; problem-design influence may surpass top-journal papers.
The article starts from a social media observation: TerminalBench v4.1 has only 66 problems, yet is tracked by virtually every frontier lab, and the poster argues that designing a benchmark problem may have more influence than publishing in Nature or Science. The underlying logic is that scarcity determines value—fewer problems mean greater signal weight per problem and implicit agenda-setting power for designers. TerminalBench evaluates agents' multi-step task execution in real terminal environments, closely mirroring AI coding deployment, making it a more discriminative battlefield after traditional benchmarks saturate. The article also notes concerns about small-sample benchmarks: large statistical noise and susceptibility to training data contamination, with influence and fragility coexisting.
When Benchmark Problems Become a Scarce Resource
An observation from social media has sparked discussion in AI research circles: TerminalBench v4.1 currently has only 66 problems, yet virtually every frontier lab is tracking performance on this benchmark. The poster used this to make a slightly provocative claim—at some point, the prestige and influence of leading the design of a single TerminalBench problem may exceed publishing a paper in Nature or Science.
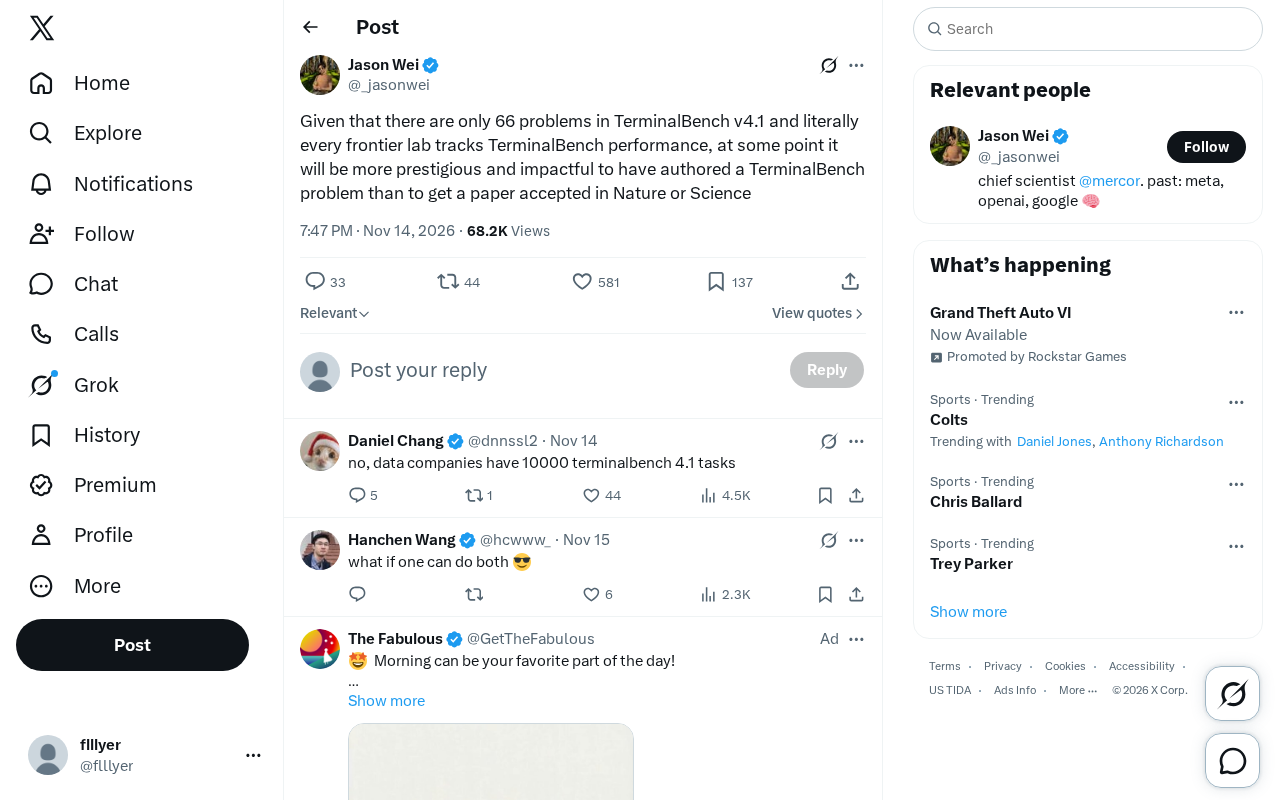
The underlying logic of this judgment isn't complicated: scarcity determines value. 66 problems is an extremely small set, meaning each individual problem carries enormous signal weight. When the model iterations of the world's top labs cannot avoid these few dozen problems, the problem designers effectively hold a kind of implicit agenda-setting power.
Why Frontier Labs Keep a Close Eye on TerminalBench
TerminalBench is positioned to evaluate an agent's ability to execute tasks in real terminal environments. Unlike static question-answering benchmarks, it requires models to complete multi-step operations in a command-line environment, involving composite skills such as file systems, script writing, and error troubleshooting. These capabilities map directly onto core scenarios for AI coding and automation deployment, so labs have strong incentives to track changes in its scores.
According to the poster's statement in the original post, "literally every frontier lab" is paying attention to this benchmark. Although this claim is a qualitative judgment, it reflects the state of the industry: when model capabilities approach saturation on traditional evaluations, terminal task benchmarks that closely mirror real workflows become a battlefield with greater discriminative power. The scale of 66 problems makes leaderboard fluctuations more sensitive—changes in performance on a single problem can affect overall rankings, further amplifying the influence of problem-design behavior.
Benchmark refers to a standardized set of tasks used in AI to quantitatively evaluate model capabilities, typically including fixed problems, scoring scripts, and a unified runtime environment. Its role is similar to "reproducible experiments" in academia: different labs run scores under identical conditions, and results can be directly compared across them. A benchmark's "discriminative power" refers to whether it can separate models of different capability levels—when models generally approach full marks on an old benchmark (i.e., "saturation"), that benchmark loses its ability to discriminate, and the community shifts to new benchmarks that are harder and closer to real-world scenarios. TerminalBench belongs to the "agent benchmark" subcategory; unlike static question-answering benchmarks such as MMLU and GSM8K, it evaluates a model's comprehensive ability to call tools, operate environments, and plan over multiple steps, and is therefore closer to real-world performance at product deployment.
The Value Mismatch Between Problem-Design Influence and Paper Publication
Comparing "designing a benchmark problem" with "publishing a Nature/Science paper" in the same coordinate system touches on the tension between the academic evaluation system and the engineering practice evaluation system. Top-journal papers represent theoretical contributions that have undergone peer review, and their prestige is built on long-term consensus within the academic community; benchmark problems influence the immediate direction of frontline R&D, with short feedback cycles and direct dissemination paths.
This comparison may not be rigorous, but it points to a real trend: in AI, the builders of evaluation infrastructure are gaining a voice that exceeds that of traditional academic channels. A well-designed, highly discriminative problem will be repeatedly cited and repeatedly tested, and its frequency of "being used" may far exceed the frequency of "being cited" of a high-impact-factor paper.
Nature and Science are comprehensive top-tier academic journals, and acceptance of their papers depends on strict peer review, with review cycles often lasting months or even a year, emphasizing theoretical novelty and broad scientific significance. In contrast, the "publication" threshold for AI benchmark problems is extremely low—they are usually released as open-source repositories or datasets without peer review, but they will be actually used by labs worldwide within weeks. The prestige mechanisms of the two channels differ: top-journal prestige comes from long-term consensus and accumulated citations within the academic community, while benchmark prestige comes from the immediate frequency of "being used" and leaderboard exposure. This also explains why, in the rapidly iterating field of AI, builders of evaluation infrastructure can gain visibility far beyond that of traditional academic paths in a short time—their contributions are directly embedded in others' R&D processes rather than remaining at the literature level.
Concerns About Small-Sample Benchmarks
The scale of 66 problems also brings obvious risks. A small sample size means large statistical noise, and a model's incidental performance on individual problems may significantly distort the total score; at the same time, once benchmark problems are made public, there is a possibility of contamination by training data, and problem designers need to continuously maintain the validity of the problems. The poster's view is more an expression of admiration for the influence than an endorsement of the benchmark's quality.
From industry practice, small-scale high-quality benchmarks and large-scale diverse benchmarks each have their uses. TerminalBench's value lies in anchoring the capability boundaries of terminal agents, and its scarcity is precisely the source of its influence as well as the vulnerability that warrants vigilance. For researchers, participating in the construction of such benchmarks is indeed becoming a highly visible way to contribute.
Data contamination refers to benchmark problems or their near variants being accidentally or deliberately included in model training data, causing the model to "memorize the questions" rather than genuinely reason, thereby inflating scores and rendering the benchmark ineffective. Small-sample benchmarks are especially fragile: once 66 problems are made public, they can easily be crawled into pretraining corpora. Common mitigation measures in the industry include: regularly rotating problems, retaining private test sets, dynamically parameterizing and rewriting problems, and filtering by "training data cutoff time." Statistical noise refers to the wide confidence intervals under small samples, where gains or losses on a single problem can cause the total score to fluctuate by several percentage points; therefore, rigorous benchmark reports should provide the variance or confidence intervals of multiple runs rather than only a single-run mean.
Frequently Asked Questions
What is TerminalBench? A benchmark for evaluating an AI agent's ability to execute tasks in a terminal environment; the current version, v4.1, contains 66 problems.
Why does a smaller number of problems mean greater influence? Because frontier labs generally track this benchmark, the scarcity of problems means each problem carries higher signal weight, and problem designers thereby gain influence at the agenda-setting level.
One-line Summary
TerminalBench has only 66 problems yet is tracked by every frontier lab; problem-design influence may surpass top-journal papers.
Paragraph Summary
The article starts from an observation on social media: TerminalBench v4.1 has only 66 problems, yet is tracked by virtually every frontier lab, and the poster therefore argues that designing a single benchmark problem may have more influence than publishing a paper in Nature or Science. The article analyzes the underlying logic as scarcity determining value—the fewer the problems, the greater the signal weight of each problem, and the more implicit agenda-setting power problem designers gain. TerminalBench evaluates an agent's ability to execute multi-step tasks in real terminal environments, closely mirroring AI coding deployment scenarios, and thus becomes a battlefield with greater discriminative power after traditional benchmarks saturate. The article also points out concerns about small-sample benchmarks: large statistical noise and susceptibility to training data contamination, with influence and fragility coexisting, and participation in benchmark construction is becoming a highly visible way to contribute.
Related articles
DevWorkflow 5.0: From Idea to Launch with the AI Five-Step Method
DevWorkflow 5.0 is a Claude Code plugin that uses a five-step process to take AI-assisted development from idea to launch. It asks you before every decision, preventing AI from adding tables and fields on its own, keeping docs and code consistent, and stopping merges before tests are written. Supports multiple platforms and languages, for individual developers and small teams.
How Do Hermes Agent's .md Files Work? A Breakdown of the Core Mechanism
Explaining Hermes Agent's .hermes directory mechanism: user.md stores personal info, memory.md records details worth remembering, soul.md defines the Agent's personality. Learn how these pure Markdown files keep the Agent consistent across sessions.

UN "Killer Robot" Talks Stall Again: Why Autonomous Weapons Regulation Is Hard to Break Through
UN Geneva talks on autonomous weapons ("killer robots") ended a week of consultations with little progress; delegates only agreed to "begin discussing options." This article analyzes the definitional disputes, conflicting security demands, and limits of multilateral mechanisms behind the stalemate.